The software creates an Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam-like scenario for you which helps to kill anxiety about the Databricks Databricks-Certified-Professional-Data-Engineer Certification Exams Questions. Customizable Databricks-Certified-Professional-Data-Engineer practice test software enables you to change settings of practice exam time and questions. Since the Actualtests4sure software tracks your progress, you can know mistakes and overcome them before the Databricks Databricks-Certified-Professional-Data-Engineer final test.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Exam Duration: | 120 minutes |
| Available Languages: | Japanese, Korean, English, Portuguese (Brazil) |
| Exam Price: | USD 200 |
| Real Exam Qty: | 59 |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Choice |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Passing Score: | 70% |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Databricks-Certified-Professional-Data-Engineer Exam Experience <<
If you are sure you have learnt all the Databricks-Certified-Professional-Data-Engineer exam questions, you have every reason to believe it. Actualtests4sure's Databricks-Certified-Professional-Data-Engineer exam dumps have the best track record of awarding exam success and a number of candidates have already obtained their targeted Databricks-Certified-Professional-Data-Engineer Certification relying on them. They provide you the real exam scenario and by doing them repeatedly you enhance your confidence to Databricks-Certified-Professional-Data-Engineer questions answers without any hesitation.
Databricks Certified Professional Data Engineer exam is a rigorous test that measures a candidate's knowledge and skills in various areas of Databricks, including data engineering, data modeling, data integration, data processing, and data storage. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to solve real-world problems using Databricks. Databricks-Certified-Professional-Data-Engineer Exam is designed to assess the candidate's ability to design and implement scalable, reliable, and efficient data solutions that meet business requirements.
NEW QUESTION # 104
Review the following error traceback: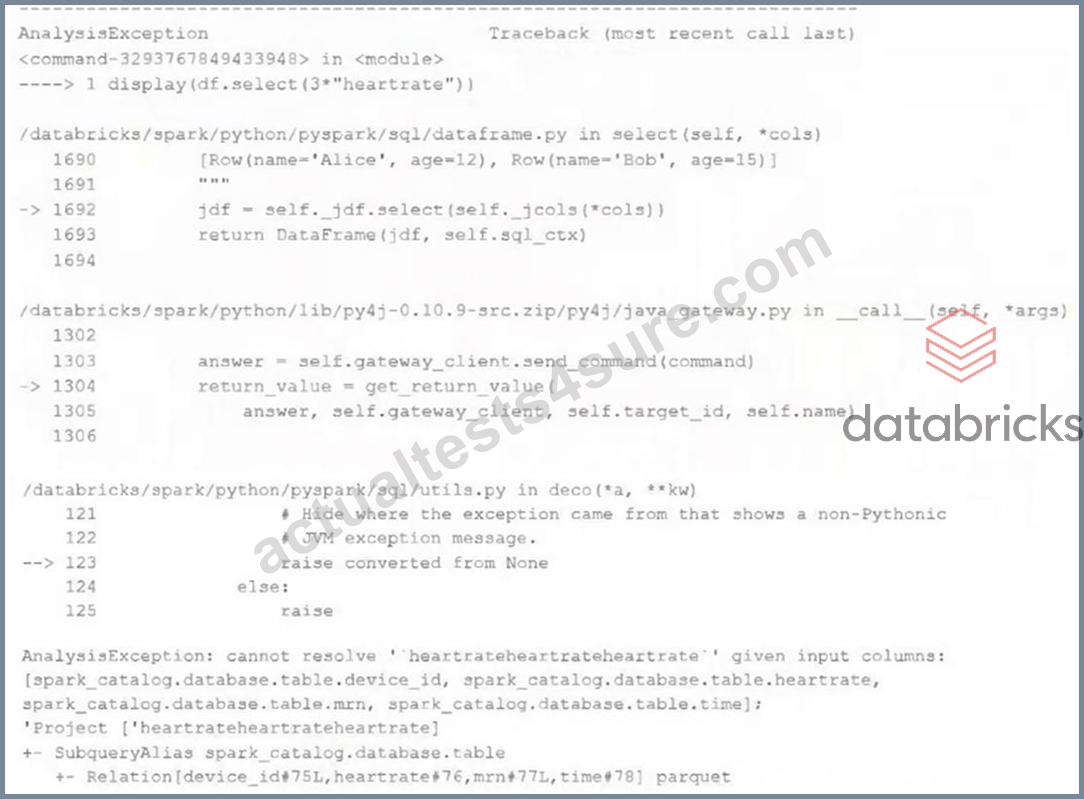
Which statement describes the error being raised?
Answer: C
Explanation:
Explanation
The error is a Py4JJavaError, which means that an exception was thrown in Java code called by Python code using Py4J. Py4J is a library that enables Python programs to dynamically access Java objects in a Java Virtual Machine (JVM). PySpark uses Py4J to communicate with Spark's JVM-based engine. The error message shows that the exception was thrown by org.apache.spark.sql.AnalysisException, which means that an error occurred during the analysis phase of Spark SQL query processing. The error message also shows that the cause of the exception was "cannot resolve 'heartrateheartrateheartrate' given input columns". This means that Spark could not find a column named heartrateheartrateheartrate in the input DataFrame or Dataset. The reason for this error is that there is a syntax error in the code that caused this exception. The code is:
df.withColumn("heartrate", heartrate * 3)
The code tries to create a new column called heartrate by multiplying an existing column called heartrate by 3.
However, the code does not correctly identify the heartrate column as a column object, but rather as a plain Python variable. This causes PySpark to concatenate the variable name with itself three times, resulting in heartrateheartrateheartrate, which is not a valid column name. To fix this error, the code should use one of the following ways to identify the heartrate column as a column object:
df.withColumn("heartrate", df["heartrate"] * 3) df.withColumn("heartrate", df.heartrate * 3) df.withColumn("heartrate", col("heartrate") * 3) Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Py4J Documentation, under "What is Py4J?"; Databricks Documentation, under "Query plans - Analysis phase"; Databricks Documentation, under "Accessing columns".
NEW QUESTION # 105
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in thegeo_lookuptable.
Before executing the code, runningSHOWTABLESon the current database indicates the database contains only two tables:geo_lookupandsales.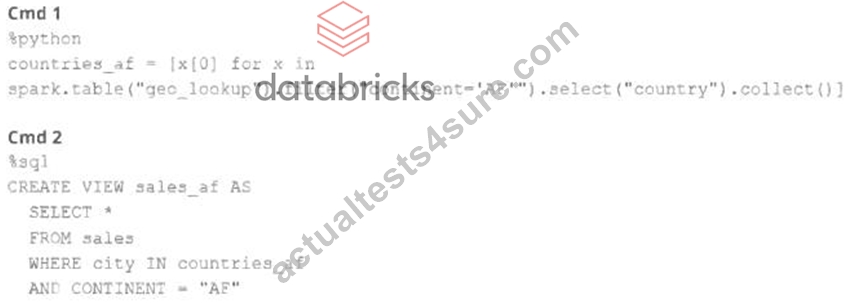
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Answer: E
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified References: [Databricks Certified Data Engineer Professional], under
"Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
NEW QUESTION # 106
Which of the following statements describes Delta Lake?
Answer: A
Explanation:
Explanation
Delta Lake
NEW QUESTION # 107
The following table consists of items found in user carts within an e-commerce website.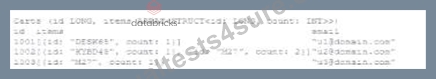
The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.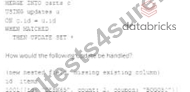
How would the following update be handled?
Answer: D
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGEoperation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
References:
* Databricks documentation on schema evolution in Delta Lake: https://docs.databricks.com/delta/delta- batch.html#schema-evolution
NEW QUESTION # 108
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
Answer: E
Explanation:
Explanation
This is the correct answer because it is the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data. Notebook permissions are used to control access to notebooks in Databricks workspaces. There are four types of notebook permissions: Can Manage, Can Edit, Can Run, and Can Read. Can Manage allows full control over the notebook, including editing, running, deleting, exporting, and changing permissions. Can Edit allows modifying and running the notebook, but not changing permissions or deleting it. Can Run allows executing commands in an existing cluster attached to the notebook, but not modifying or exporting it. Can Read allows viewing the notebook content, but not running or modifying it. In this case, granting Can Read permission to the user will allow them to review the production logic in the notebook without allowing them to makeany changes to it or run any commands that may affect production data. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "Notebook permissions" section.
NEW QUESTION # 109
......
Databricks-Certified-Professional-Data-Engineer Valid Exam Voucher: https://www.actualtests4sure.com/Databricks-Certified-Professional-Data-Engineer-test-questions.html