P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PassTestking: https://drive.google.com/open?id=1rUIYL2Qc5irXKd6rpUBAi7vaYs_FStjT
This is similar to the Databricks-Generative-AI-Engineer-Associate desktop format but this is browser-based. It requires an active internet connection to run and is compatible with all browsers such as Google Chrome, Mozilla Firefox, Opera, MS Edge, Safari, Internet Explorer, and others. The Databricks Databricks-Generative-AI-Engineer-Associate Mock Exam helps you self-evaluate your Databricks Databricks-Generative-AI-Engineer-Associate exam preparation and mistakes. This way you improve consistently and attempt the Databricks-Generative-AI-Engineer-Associate certification exam in an optimal way for excellent results in the exam.
| Section | Objectives |
|---|---|
| Topic 1: Prompt Engineering | - Prompt design techniques
|
| Topic 2: Foundations of Generative AI | - Generative AI Concepts
|
| Topic 3: Databricks Mosaic AI Platform | - MLflow for GenAI
|
| Topic 4: Responsible AI and Governance | - AI safety and ethics
|
| Topic 5: Retrieval-Augmented Generation (RAG) | - Vector databases and embeddings
|
>> Study Databricks-Generative-AI-Engineer-Associate Material <<
Computer brings more convenience, online access to information, published an article, watch movies, online remote virtual learning and other benefits. IT workers are becoming high-salary field in all over the world. PassTestking releases latest and valid Databricks-Generative-AI-Engineer-Associate Exam preparations to help candidates clear exams certainly as Databricks certifications are outstanding and attractive. If you determine to take part in exams, our Databricks-Generative-AI-Engineer-Associate exam preparations will be a good helper.
NEW QUESTION # 23
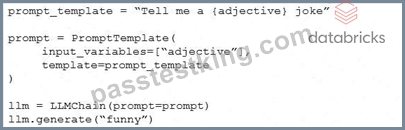
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.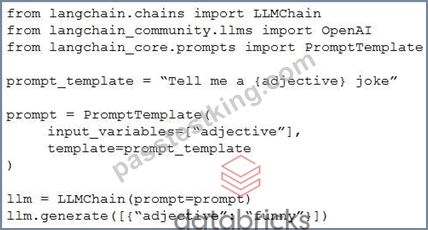
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
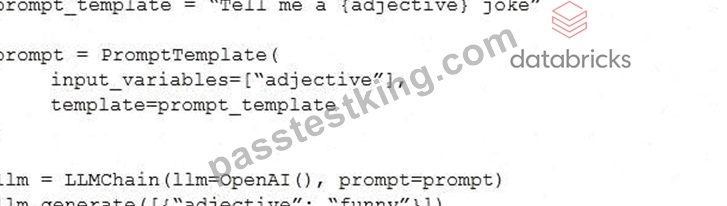
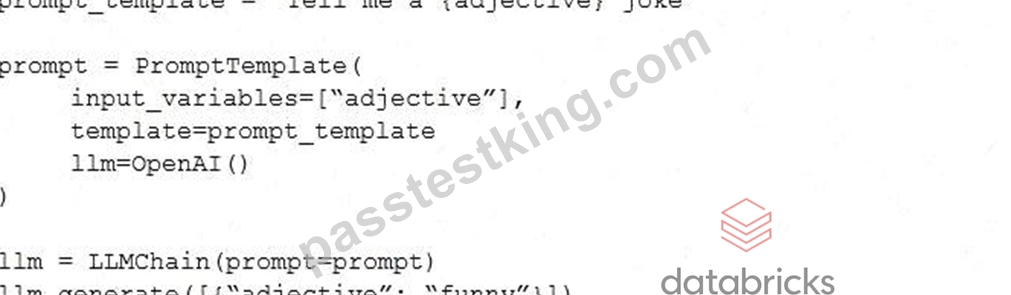
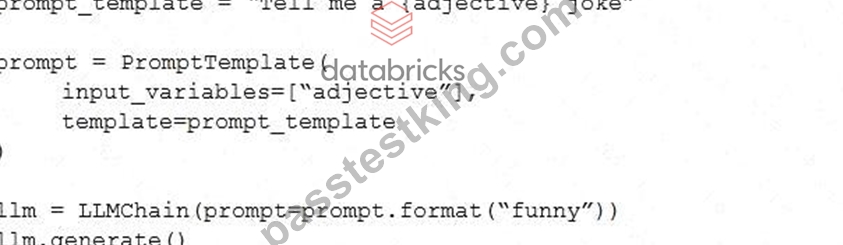
Answer: B
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here ' s a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization : In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods :
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A : Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B : Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D : Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain ' s architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 24
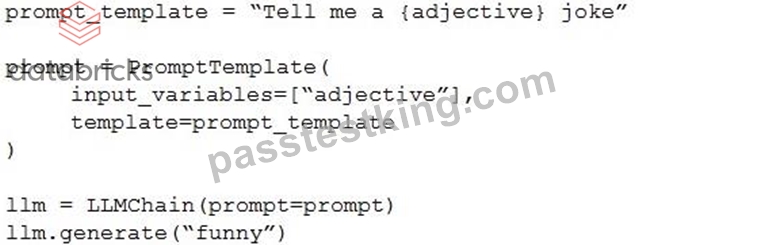
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.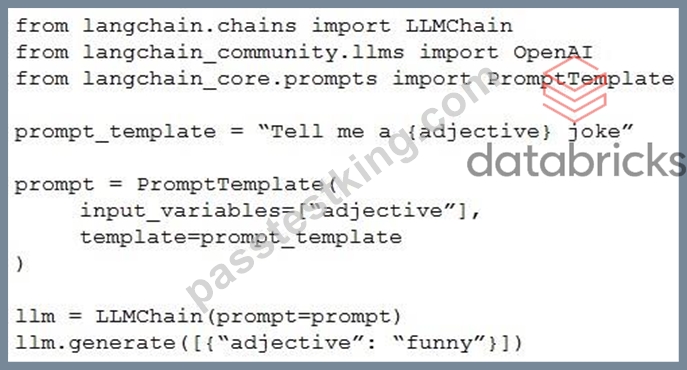
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
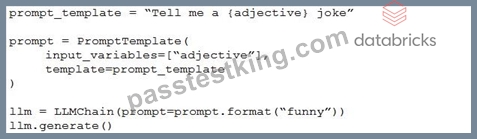
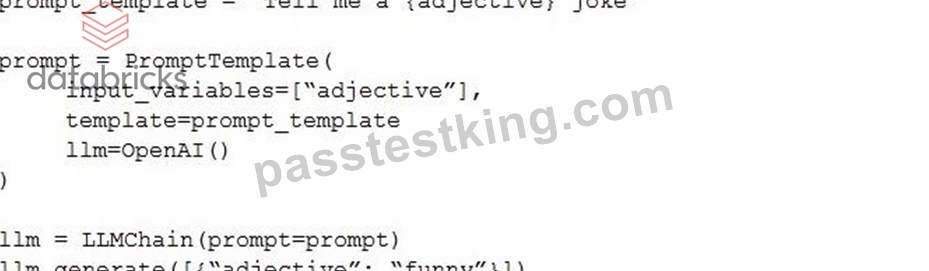
Answer: B
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 25
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
Answer: D
Explanation:
* Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
* Explanation of Options:
* Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
* Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON.
This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
* Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
* Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs,Option Bis the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
NEW QUESTION # 26
A Generative AI Engineer is building a RAG application that will rely on context retrieved from source documents that are currently in PDF format. These PDFs can contain both text and images. They want to develop a solution using the least amount of lines of code.
Which Python package should be used to extract the text from the source documents?
Answer: B
Explanation:
* Problem Context: The engineer needs to extract text from PDF documents, which may contain both text and images. The goal is to find a Python package that simplifies this task using the least amount of code.
* Explanation of Options:
* Option A: flask: Flask is a web framework for Python, not suitable for processing or extracting content from PDFs.
* Option B: beautifulsoup: Beautiful Soup is designed for parsing HTML and XML documents, not PDFs.
* Option C: unstructured: This Python package is specifically designed to work with unstructured data, including extracting text from PDFs. It provides functionalities to handle various types of content in documents with minimal coding, making it ideal for the task.
* Option D: numpy: Numpy is a powerful library for numerical computing in Python and does not provide any tools for text extraction from PDFs.
Given the requirement,Option C(unstructured) is the most appropriate as it directly addresses the need to efficiently extract text from PDF documents with minimal code.
NEW QUESTION # 27
A Generative AI Engineer has been asked to design an LLM-based application that accomplishes the following business objective: answer employee HR questions using HR PDF documentation.
Which set of high level tasks should the Generative AI Engineer's system perform?
Answer: A
Explanation:
To design an LLM-based application that can answer employee HR questions using HR PDF documentation, the most effective approach is option D. Here's why:
* Chunking and Vector Store Embedding:HR documentation tends to be lengthy, so splitting it into smaller, manageable chunks helps optimize retrieval. These chunks are then embedded into avector store(a database that stores vector representations of text). Each chunk of text is transformed into an embeddingusing a transformer-based model, which allows for efficient similarity-based retrieval.
* Using Vector Search for Retrieval:When an employee asks a question, the system converts their query into an embedding as well. This embedding is then compared with the embeddings of the document chunks in the vector store. The most semantically similar chunks are retrieved, which ensures that the answer is based on the most relevant parts of the documentation.
* LLM to Generate a Response:Once the relevant chunks are retrieved, these chunks are passed into the LLM, which uses them as context to generate a coherent and accurate response to the employee's question.
* Why Other Options Are Less Suitable:
* A (Calculate Averaged Embeddings): Averaging embeddings might dilute important information. It doesn't provide enough granularity to focus on specific sections of documents.
* B (Summarize HR Documentation): Summarization loses the detail necessary for HR-related queries, which are often specific. It would likely miss the mark for more detailed inquiries.
* C (Interaction Matrix and ALS): This approach is better suited for recommendation systems and not for HR queries, as it's focused on collaborative filtering rather than text-based retrieval.
Thus, option D is the most effective solution for providing precise and contextual answers based on HR documentation.
NEW QUESTION # 28
......
We can guarantee that our study materials will be suitable for all people and meet the demands of all people, including students, workers and housewives and so on. If you decide to buy and use the Databricks-Generative-AI-Engineer-Associate study materials from our company with dedication on and enthusiasm step and step, it will be very easy for you to pass the exam without doubt. We sincerely hope that you can achieve your dream in the near future by the Databricks-Generative-AI-Engineer-Associate Study Materials of our company.
Databricks-Generative-AI-Engineer-Associate Latest Test Online: https://www.passtestking.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PassTestking: https://drive.google.com/open?id=1rUIYL2Qc5irXKd6rpUBAi7vaYs_FStjT