Doubtlessly, clearing the Databricks-Certified-Professional-Data-Engineer certification exam is a challenging task. You can make this task considerably easier by studying with actual Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) Questions of TroytecDumps. We provide you with a triple-formatted Databricks-Certified-Professional-Data-Engineer Practice Test material, made under the supervision of experts. This product has everything you need to clear the challenging Databricks-Certified-Professional-Data-Engineer exam in one go.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Topic 2: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Topic 3: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 4: Data Ingestion | 15-20% | - Streaming ingestion
|
| Topic 5: Delta Lake | 20-25% | - Delta Lake operations
|
>> Databricks Databricks-Certified-Professional-Data-Engineer Interactive Practice Exam <<
The TroytecDumps is committed to providing the best possible study material to succeed in the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam. With actual PDF questions, customizable practice exams, and 24/7 support, customers can be confident that they are getting the best possible prep material. The TroytecDumps Databricks-Certified-Professional-Data-Engineer is an excellent choice for anyone looking to advance their career with the certification. Buy Now.
NEW QUESTION # 211
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
Answer: A
Explanation:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
NEW QUESTION # 212
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table namedusers.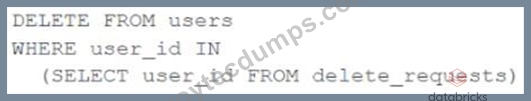
Assuming thatuser_idis a unique identifying key and thatdelete_requestscontains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: E
Explanation:
Explanation
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion.
The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 213
The marketing team is launching a new campaign to monitor the performance of the new campaign for the first two weeks, they would like to set up a dashboard with a refresh schedule to run every 5 minutes, which of the below steps can be taken to reduce of the cost of this refresh over time?
Answer: B
Explanation:
Explanation
The answer is Setup the dashboard refresh schedule to end in two weeks
NEW QUESTION # 214
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.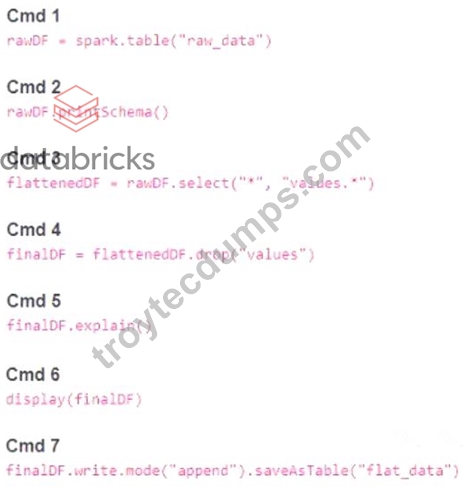
Which command should be removed from the notebook before scheduling it as a job?
Answer: E
Explanation:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 215
A table customerLocations exists with the following schema:
1. id STRING,
2. date STRING,
3. city STRING,
4. country STRING
A senior data engineer wants to create a new table from this table using the following command:
1. CREATE TABLE customersPerCountry AS
2. SELECT country,
3. COUNT(*) AS customers
4. FROM customerLocations
5. GROUP BY country;
A junior data engineer asks why the schema is not being declared for the new table. Which of the following
responses explains why declaring the schema is not necessary?
Answer: A
NEW QUESTION # 216
......
As is known to all, Databricks-Certified-Professional-Data-Engineer practice test simulation plays an important part in the success of exams. By simulation, you can get the hang of the situation of the real exam with the help of our free demo. You can fight a hundred battles with no danger of defeat. Simulation of our Databricks-Certified-Professional-Data-Engineer Training Materials make it possible to have a clear understanding of what your strong points and weak points are and at the same time, you can learn comprehensively about the exam. By combining the two aspects, you are more likely to achieve high grades in the real exam.
Certification Databricks-Certified-Professional-Data-Engineer Cost: https://www.troytecdumps.com/Databricks-Certified-Professional-Data-Engineer-troytec-exam-dumps.html