P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by BraindumpsVCE: https://drive.google.com/open?id=1b_6CpSM5KQdic45RL8OZuB5XLfbY4rdb
Do you want to pass your exam buying using the least time? If you do, you can choose us, we have confidence help you pass your exam just one time. DP-600 training materials are edited by skilled professionals, they are familiar with the dynamics for the exam center, therefore you can know the dynamics of the exam timely. Besides, we offer you free demo for you to have a try before buying DP-600 Test Dumps, so that you can have a deeper understanding of what you are going to buy. Free update for one year is available, and you can obtain the latest version if you choose us, and the update version for DP-600 exam materials will be sent to your email address automatically.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Latest DP-600 Exam Question <<
Microsoft is obliged to give you 12 months of free update checks to ensure the validity and accuracy of the Microsoft DP-600 exam dumps. We also offer you a 100% money-back guarantee, in the very rare case of failure or unsatisfactory results. This puts your mind at ease when you are Microsoft DP-600 Exam preparing with us.
NEW QUESTION # 73
You have a Fabric tenant that contains a data warehouse named DW1. DW1 contains a table named DimCustomer. DimCustomer contains the fields shown in the following table.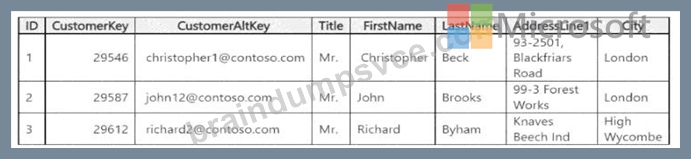
You need to identify duplicate email addresses in DimCustomer. The solution must return a maximum of
1,000 records.
Which four T-SQL statements should you run in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.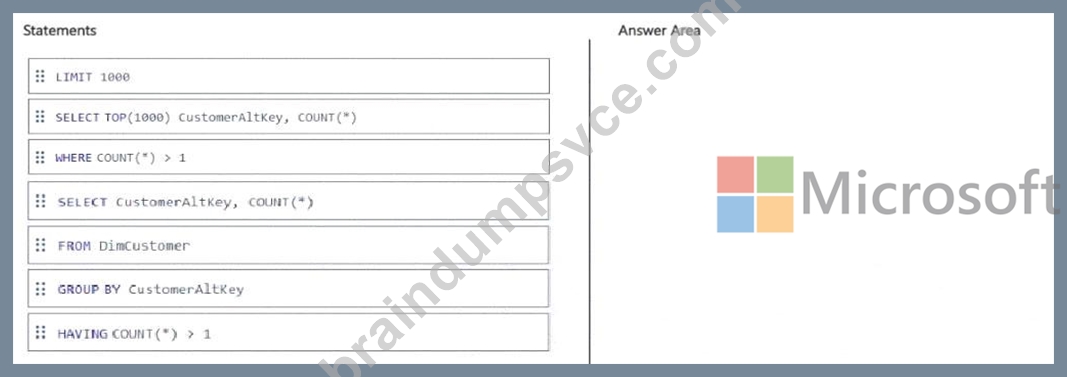
Answer:
Explanation: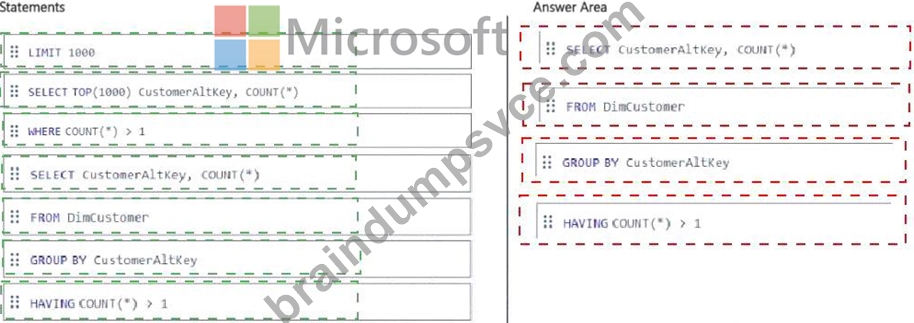
Explanation: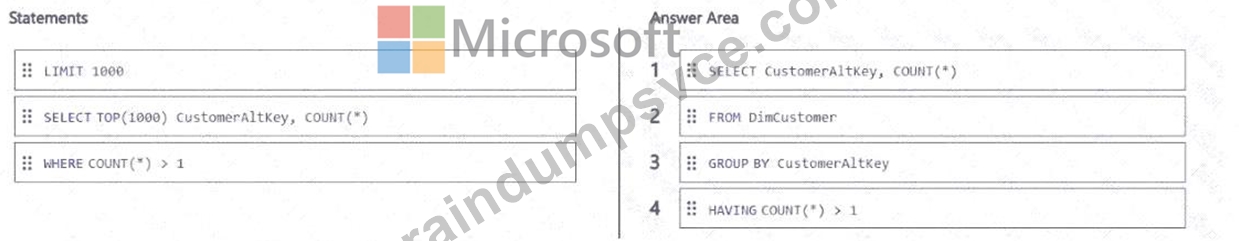
Step 1 - Select the required fields and count
We want to group by CustomerAltKey and count occurrences.
SELECT CustomerAltKey, COUNT(*)
Step 2 - From the table
FROM DimCustomer
Step 3 - Grouping by email
GROUP BY CustomerAltKey
Step 4 - Filtering duplicates (only values with count > 1)
HAVING COUNT(*) > 1
Step 5 - Limiting the result to 1,000 rows
LIMIT 1000
(or in T-SQL, SELECT TOP(1000) ...). Since both options are shown, we use LIMIT 1000 because Fabric Warehouse supports Synapse SQL T-SQL + ANSI SQL style.
Correct Sequence:
SELECT CustomerAltKey, COUNT(*)
FROM DimCustomer
GROUP BY CustomerAltKey
HAVING COUNT(*) > 1
LIMIT 1000
NEW QUESTION # 74
You have a Fabric tenant that contains JSON files in OneLake. The files have one billion items.
You plan to perform time series analysis of the items.
You need to transform the data, visualize the data to find insights, perform anomaly detection, and share the insights with other business users. The solution must meet the following requirements:
# Use parallel processing.
# Minimize the duplication of data.
# Minimize how long it takes to load the data.
What should you use to transform and visualize the data?
Answer: C
Explanation:
Requirements:
Parallel processing # PySpark runs distributed across Spark clusters.
Minimize duplication of data # OneLake shortcut + Spark queries avoid unnecessary copies.
Time series analysis, anomaly detection, visualization # can be done in PySpark within Fabric Notebooks.
pandas (C) is single-threaded and not efficient for billions of items.
Power BI visuals (A) are good for visualization but not for transformation or large-scale anomaly detection.
Correct: B.
Reference: Use PySpark in Fabric notebooks
NEW QUESTION # 75
You have a Microsoft Power B1 Premium Per User (PPU) workspace that contains a semantic model.
You have an Azure App Service app named App1 that modifies row-level security (RLS) for the model by using the XMLA endpoint. App1 requires users to sign in by using their Microsoft Entra credentials to access the XMLA endpoint. You need to configure App1 to use a service account to access the model. What should you do first?
Answer: B
Explanation:
Topic 1, Contoso, ltd.
Overview
Contoso, ltd. is a US-based health supplements company, Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroupi and ReseachReviewefsGfoup2.
Data Environment
Contoso has the following data environment
* The Sales division uses a Microsoft Power B1 Premium capacity.
* The semantic model of the Online Sales department includes a fact table named Orders that uses import mode. In the system of origin, the OrderlD value represents the sequence in which orders are created.
* The Research department uses an on-premises. third-party data warehousing product.
* Fabric is enabled for contoso.com.
* An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Producthne1. The data is in the delta format.
* A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Planned Changes
Contoso plans to make the following changes:
* Enable support for Fabric in the Power Bl Premium capacity used by the Sales division.
* Make all the data for the Sales division and the Research division available in Fabric.
* For the Research division, create two Fabric workspaces named Producttmelws and Productline2ws.
* in Productlinelws. create a lakehouse named LakehouseV
* In Lakehouse1. create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
* All the workspaces for the Sales division and the Research division must support all Fabric experiences.
* The Research division workspaces must use a dedicated, on-demand capacity that has per-minute billing.
* The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
* For the Research division workspaces, the members of ResearchRevtewersGroupl must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
* For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
* All the semantic models and reports for the Research division must use version control that supports branching Data Preparation Requirements Contoso identifies the following data preparation requirements:
* The Research division data for Producthne2 must be retrieved from Lakehouset by using Fabric notebooks.
* All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models;
* The number of rows added to the Orders table during refreshes must be minimized.
* The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
* Follow the principle of least privilege when applicable
* Minimize implementation and maintenance effort when possible.
NEW QUESTION # 76
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.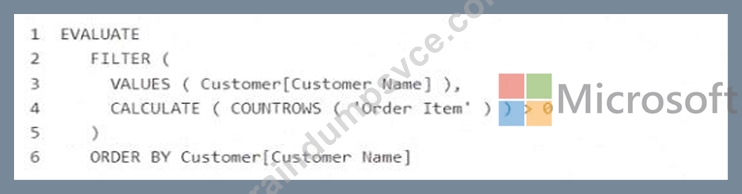
You need to reduce the execution time of the query.
Solution: following code:
Does this meet the goal?
Answer: B
Explanation:
ISEMPTY(CALCULATETABLE( ' Order Item ' )) checks if there are no related rows in ' Order Item ' for a customer. Wrapping this in NOT returns true if the customer has at least one order. This avoids calculating row counts and instead just checks existence, which is more efficient for performance. This reduces execution time and meets the goal.
NEW QUESTION # 77
You have a Fabric tenant that contains a warehouse named WH1. You run the following T-SQL query against WH1.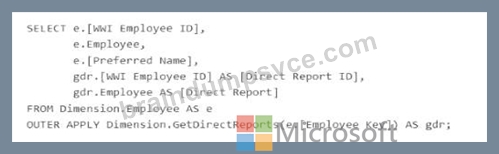
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.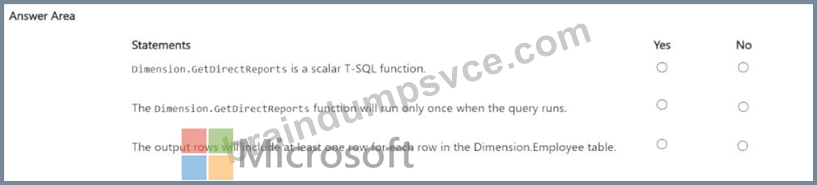
Answer:
Explanation: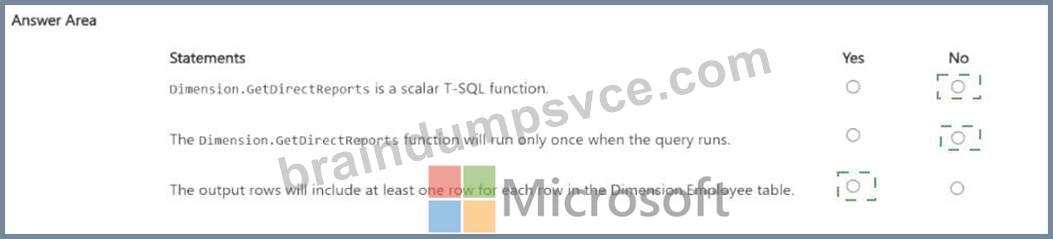
Explanation: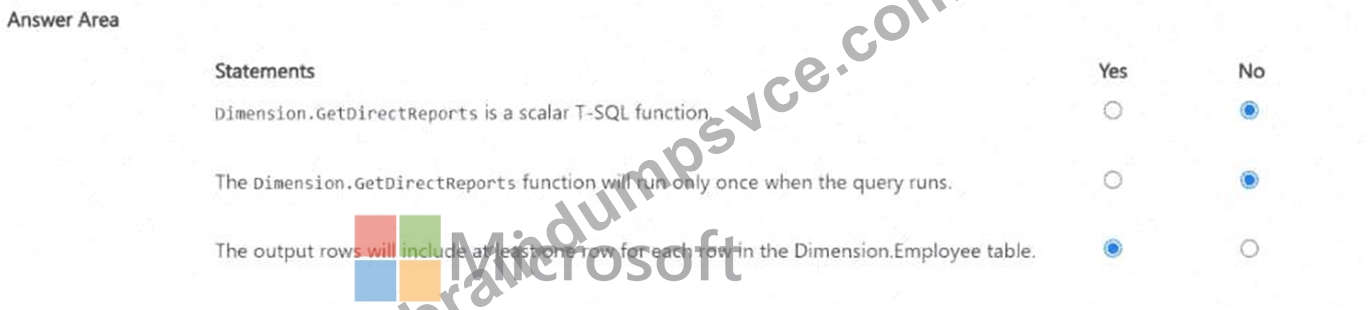
We are analyzing the query:
SELECT e.[WWI Employee ID],
e.Employee,
e.[Preferred Name],
gdr.[WWI Employee ID] AS [Direct Report ID] ,
gdr.Employee AS [Direct Report]
FROM Dimension.Employee AS e
OUTER APPLY Dimension.GetDirectReports(e.[Employee Key]) AS gdr;
Key concepts:
APPLY operator: Used to join a table with a table-valued function.
OUTER APPLY ensures all rows from the left (Employee) are returned, even if the function returns no rows (similar to LEFT JOIN).
Table-valued function (TVF): Returns a set of rows (unlike scalar functions, which return a single value).
The function executes once per row from the left table, not once for the whole query.
Evaluating each statement:
" Dimension.GetDirectReports is a scalar T-SQL function. "
No # It must be a table-valued function, because OUTER APPLY requires a table expression.
" The Dimension.GetDirectReports function will run only once when the query runs. " No # With APPLY, the function runs for each row of Dimension.Employee.
" The output rows will include at least one row for each row in the Dimension.Employee table. " Yes # Because of OUTER APPLY, every employee row is included, even if there are no direct reports (in that case, the columns from gdr will be NULL).
Final Answer:
Scalar function # No
Runs once per query # No
At least one row per Employee # Yes
References:
APPLY operator in T-SQL
Table-valued functions
NEW QUESTION # 78
......
The Microsoft DP-600 dumps PDF format of BraindumpsVCE is portable and printable. It means you can print Microsoft DP-600 real questions for off-screen preparation. You can also access Microsoft DP-600 dumps PDF from smartphones, laptops, and tablets anywhere anytime to prepare for the DP-600 Exam. This version of our DP-600 questions PDF is beneficial for busy applicants because they can easily use DP-600 dumps PDF and prepare for the Microsoft DP-600 test in their homes, offices, libraries, and even while traveling.
Valid DP-600 Exam Questions: https://www.braindumpsvce.com/DP-600_exam-dumps-torrent.html
BONUS!!! Download part of BraindumpsVCE DP-600 dumps for free: https://drive.google.com/open?id=1b_6CpSM5KQdic45RL8OZuB5XLfbY4rdb