2026 Latest Pass4SureQuiz NCP-AII PDF Dumps and NCP-AII Exam Engine Free Share: https://drive.google.com/open?id=17E_ajVIrOFL6G4kWJqr1Y9jOcOJtHitl
Our NCP-AII exam materials are formally designed for the exam. With its help, you don't have to worry about the exam any more for it almost guarantees you get what you want. If you think i'm exaggerating, you might as well take a look at our NCP-AII Actual Exam. With a high pass rate as 98% to 100%, you will be bound to pass the exam. And our NCP-AII training questions are popular in the market. We believe you will make the right choice.
| Section | Weight | Objectives |
|---|---|---|
| System and Server Bring-up | 31% | - Hardware initialization and configuration
|
| Troubleshoot and Optimize | 12% | - Fault detection and remediation
|
| Cluster Test and Verification | 33% | - Cluster diagnostics
|
| Physical Layer Management | 5% | - Networking and GPU partitioning
|
| Control Plane Installation and Configuration | 19% | - GPU utilization in containers
|
NVIDIA NCP-AII practice test questions of Pass4SureQuiz is the perfect choice for you. With our comprehensive NCP-AII study material, you will be able to pass your NCP-AII certification exam with ease. The basic motive of Pass4SureQuiz is to help students pass the NCP-AII Exam on the first attempt. This also offers up to 365 days of free NVIDIA NCP-AII updates. And also helps you evaluate the product with a free NCP-AII demo. Try a free NCP-AII demo now and satisfy yourself.
NEW QUESTION # 58
A user reports that their GPU-accelerated application is crashing with a CUDA error related to 'out of memory'. You have confirmed that the GPU has sufficient physical memory What are the likely causes and troubleshooting steps?
Answer: C,D
Explanation:
Memory leaks and single-allocation limits are common causes of 'out of memory' errors, even when sufficient physical memory exists. 'cuda-memcheck' is specifically designed to find memory errors in CUDA applications. While driver incompatibility is possible, leaks and allocation size limits are more frequent occurrences.
NEW QUESTION # 59
Consider the following Dockerfile snippet: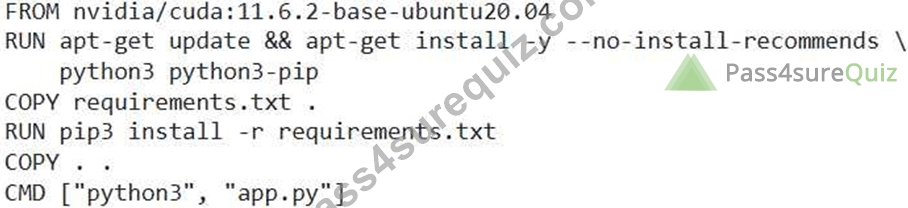
This Dockerfile is used to build a deep learning application. After building and running a container from this image, you observe that the application is not detecting the GPU. You have verified that the NVIDIA Container Toolkit is installed and configured correctly on the host. What is the most likely reason for this issue?
Answer: C
Explanation:
The 'docker run' command must include the =gpus all' (or equivalent) flag to explicitly request GPU resources for the container (C). The base image 'nvidia/cuda:ll .6.2-base-ubuntu20.04' provides the CUDA runtime, but the NVIDIA Container Toolkit on the host handles the GPU device mapping. The application code (B) doesn't need to explicitly request GPUs; the CUDA runtime will handle that. 'nvidia-pyindex' (D) is related to package management, not GPU detection. The Dockerfile includes a specific CUDA version that mitigates version differences (E). The base image does not include the Container Toolkit, which is installed on the HOST.
NEW QUESTION # 60
During a 72-hour HPL burn-in test on a DGX H100 cluster, one node shows a 15% performance drop after 48 hours. What are the two most likely causes and diagnostic steps? (Choose two.)
Answer: B,D
Explanation:
A delayed performance drop during a long HPL burn-in is commonly caused by thermal throttling as cooling conditions degrade under sustained load, so GPU temperature, clocks, power, and throttling behavior should be checked with nvidia-smi dmon. Network packet loss or fabric errors can also reduce multi-node HPL performance over time, so ibdiagnet reports should be analyzed for link errors, packet loss, retries, or degraded InfiniBand paths.
NEW QUESTION # 61
You have a dataset with many small files (e.g., images). Directly reading these files can result in high metadata access overhead. What are the MOST effective strategies to mitigate this problem?
Answer: A,B,D
Explanation:
Combining small files reduces the number of metadata operations. A key-value store can provide efficient access to small data items. Increasing metadata servers reduces the load on individual metadata servers. Smaller block sizes exacerbate the problem. Replicating data doesn't address metadata overhead.
NEW QUESTION # 62
A System Administrator needs to change the scheduling behavior of a single GPU to use a fixed share scheduler. What command achieves this?
Answer: B
Explanation:
NVIDIA Multi-Instance GPU (MIG) technology, introduced with the Ampere architecture (A100) and enhanced in Hopper (H100), allows a single physical GPU to be partitioned into multiple isolated instances.
To manage these instances and their scheduling behavior (such as moving from a default time-sliced scheduler to a fixed-share or "MIG" partitioned mode), the nvidia-smi utility is used. The command nvidia- smi -i 0 -mig 1 enables MIG mode on the first GPU (index 0). Once MIG is enabled, the administrator can create specific GPU instances with dedicated compute and memory resources. This "Fixed Share" approach ensures that one tenant's workload does not impact the performance or latency of another, which is critical for deterministic AI inference and multi-tenant cloud environments. Option A and B refer to VMware ESXi specific commands which are not the primary method for raw hardware configuration in standard AI infrastructure, and Option D is for network adapter configuration.
NEW QUESTION # 63
......
Don't mind what others say, trust you and make a right choice. We hope that you understand our honesty and cares, so we provide free demo of NCP-AII exam software for you to download before you purchase our dump so that you are rest assured of our dumps. After your payment of our dumps, we will provide more considerate after-sales service to you. Once the update of NCP-AII Exam Dump releases, we will inform you the first time. You will share the free update service of NCP-AII exam software for one year after you purchased it.
NCP-AII Cheap Dumps: https://www.pass4surequiz.com/NCP-AII-exam-quiz.html
BTW, DOWNLOAD part of Pass4SureQuiz NCP-AII dumps from Cloud Storage: https://drive.google.com/open?id=17E_ajVIrOFL6G4kWJqr1Y9jOcOJtHitl