BONUS!!! Download part of TrainingDumps DP-600 dumps for free: https://drive.google.com/open?id=1BZdwy3ngWAXpDxKh9yQz0XuA3HNvsvb6
Are you still worried about your coming DP-600 exam and have no idea what to do? Are you too busy to study with all the books and other broad exam materials which will take you a long time to prapare for your exam? You can just choose to buy our DP-600 Exam Questions which have settle all these problems for you. And our pass rate of the DP-600 study materials is high as 98% to 100%. Hence they are your real ally for establishing your career pathway and get your potential attested.
| Section | Weight | Objectives |
|---|---|---|
| Secure and monitor data solutions | 15-20% | - Monitor data solutions
|
| Design and manage the data model | 20-25% | - Design a data model
|
| Deploy and maintain a data solution | 10-15% | - Deploy data assets
|
| Load and prepare data | 20-25% | - Create and configure items
|
| Clean, transform, and enrich data | 25-30% | - Clean data
|
>> Valid DP-600 Exam Pattern <<
Do you want to find a job that really fulfills your ambitions? That's because you haven't found an opportunity to improve your ability to lay a solid foundation for a good career. Our DP-600 learning materials are carefully compiled by industry experts based on the examination questions and industry trends in the past few years. The knowledge points are comprehensive and focused. You don't have to worry about our learning from DP-600 Exam Question. We assure you that our DP-600 learning materials are easy to understand and use the fewest questions to convey the most important information.
NEW QUESTION # 206
Hotspot Question
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData that stores the following data.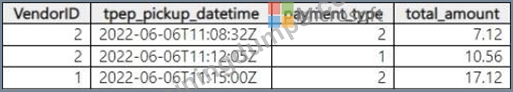
You need to create a column named FirstPickupDateTime that will contain the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.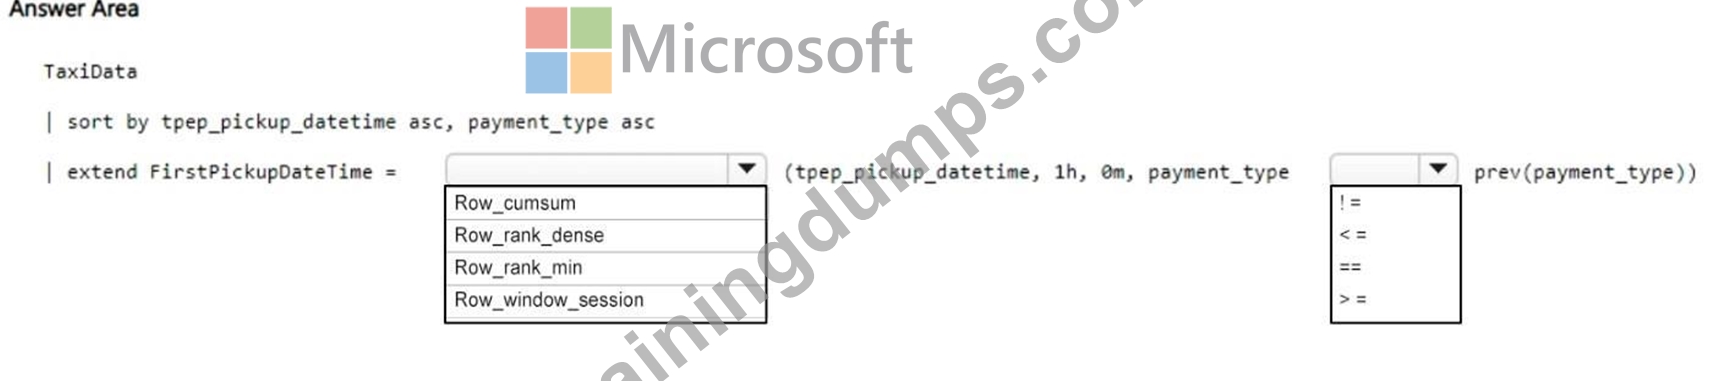
Answer:
Explanation: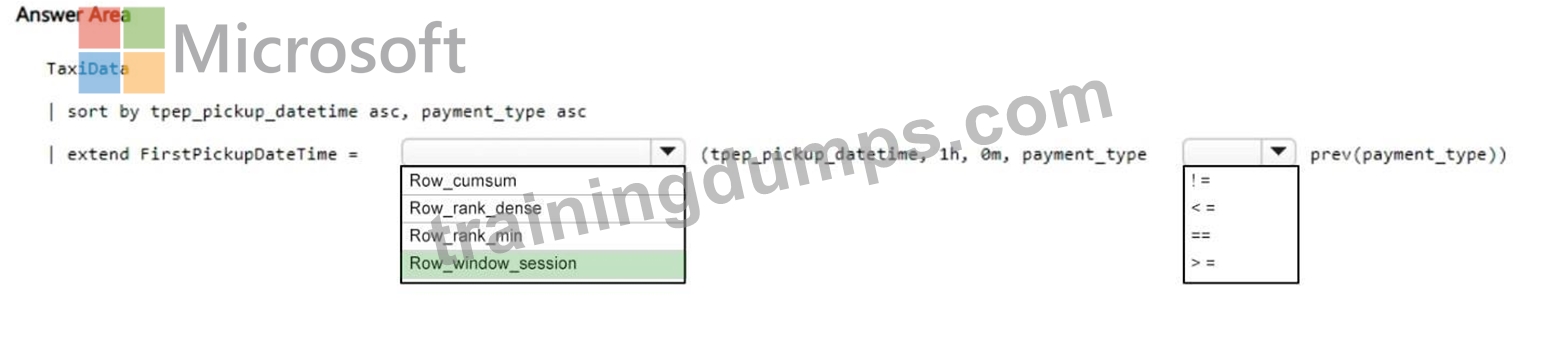
Explanation:
Box 1: Row_Window_Session
Kusto, KQL Windowing Functions - Row_Window_Session
The row_window_session function can be used to group rows of data in a time range, and will return the starting time for that range of data in each row.
Box 2: !=
Here we are using an equation, which will compare the payment_type for the current row to the one of the previous row using the prev Windowing Function. If they are not equal, the comparison will return true and trigger Row_Window_Session to begin a Row_Window_Session grouping.
NEW QUESTION # 207
You have a Fabric tenant that contains a semantic model. The model contains data about retail stores.
You need to write a DAX query that will be executed by using the XMLA endpoint. The query must return the total amount of sales from the same period last year.
How should you complete the DAX expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.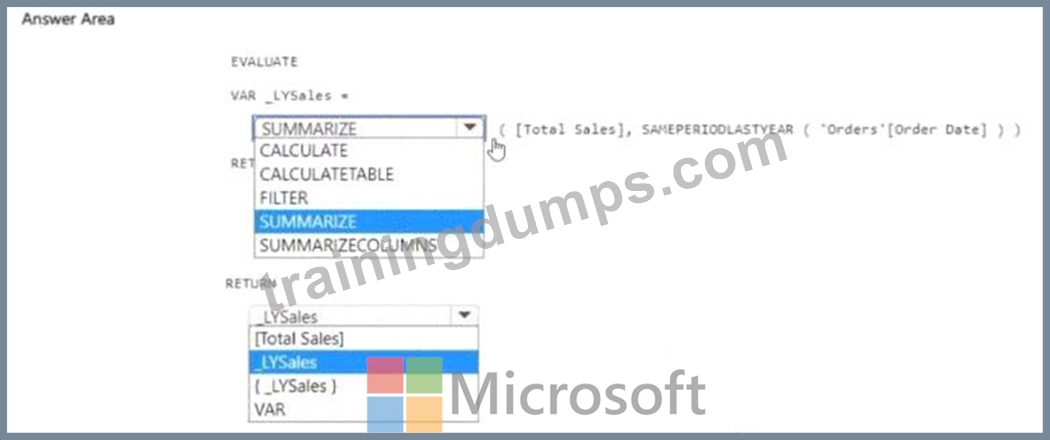
Answer:
Explanation: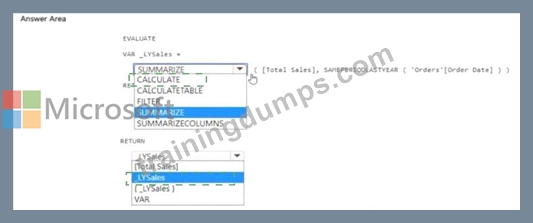
Explanation:
First blank: CALCULATE
Second blank: _LYSales
Step 1 - Defining the variable
We want to calculate sales for the same period in the prior year. The correct function here is CALCULATE, because it allows applying a filter context modification (with SAMEPERIODLASTYEAR).
So:
VAR _LYSales =
CALCULATE ( [Total Sales], SAMEPERIODLASTYEAR ( ' Orders ' [Order Date] ) ) Step 2 - Returning the value We then need to RETURN the value of the variable. From the dropdown options, we select _LYSales.
So:
EVALUATE
VAR _LYSales =
CALCULATE ( [Total Sales], SAMEPERIODLASTYEAR ( ' Orders ' [Order Date] ) ) RETURN ROW ( " LastYearSales " , _LYSales ) Note: In XMLA DAX queries, you usually need a table expression, so wrapping with ROW or SELECTCOLUMNS is common, but based on the provided answer box, just returning _LYSales is sufficient here.
Final Answer:
First blank: CALCULATE
Second blank: _LYSales
NEW QUESTION # 208
You have a Fabric tenant that contains the workspaces shown in the following table.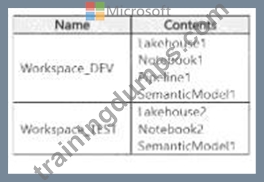
You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
Answer: A
Explanation:
Workspace_DEV contents:
Lakehouse1, Notebook1, Pipeline1, SemanticModel1
Workspace_TEST contents (before deployment):
Lakehouse2, Notebook2, SemanticModel1
After deployment:
SemanticModel1 # same name, so it will be paired and overwritten with the DEV version.
Lakehouse1 and Notebook1 # new items, so they will be added to TEST.
Lakehouse2 and Notebook2 # remain because they don't conflict in name.
Pipeline1 # new item, so it will also be added .
So the final content is:
Lakehouse1, Lakehouse2, Notebook1, Notebook2, Pipeline1, SemanticModel1
NEW QUESTION # 209
You have a Fabric tenant that contains JSON files in OneLake. The files have one billion items.
You plan to perform time series analysis of the items.
You need to transform the data, visualize the data to find insights, perform anomaly detection, and share the insights with other business users. The solution must meet the following requirements:
# Use parallel processing.
# Minimize the duplication of data.
# Minimize how long it takes to load the data.
What should you use to transform and visualize the data?
Answer: B
Explanation:
Requirements:
Parallel processing # PySpark runs distributed across Spark clusters.
Minimize duplication of data # OneLake shortcut + Spark queries avoid unnecessary copies.
Time series analysis, anomaly detection, visualization # can be done in PySpark within Fabric Notebooks.
pandas (C) is single-threaded and not efficient for billions of items.
Power BI visuals (A) are good for visualization but not for transformation or large-scale anomaly detection.
Correct: B.
Reference: Use PySpark in Fabric notebooks
NEW QUESTION # 210
You have a Fabric workspace named Workspace1 that contains a data flow named Dataflow1 contains a query that returns the data shown in the following exhibit.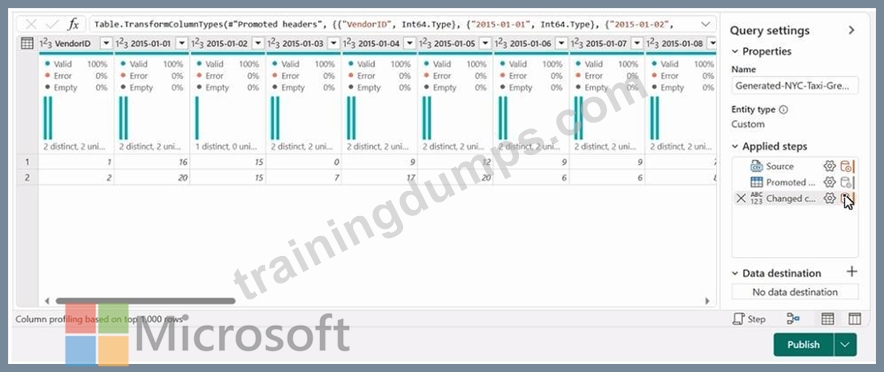
You need to transform the data columns into attribute-value pairs, where columns become rows.
You select the VendorID column.
Which transformation should you select from the context menu of the VendorID column?
Answer: A
NEW QUESTION # 211
......
By using the TrainingDumps DP-600 valid exam lab questions, there is no need to purchase anything else or attend expensive training. We promise that you can pass the DP-600 certification at the first try. We will update our questions and answers in time after thoroughly analysis of latest real exams, so the DP-600 Exam Dumps shown front of you is the latest and valid. Besides, we offer you one year free update Microsoft study dumps after your purchase.
DP-600 Reliable Dumps Sheet: https://www.trainingdumps.com/DP-600_exam-valid-dumps.html
2026 Latest TrainingDumps DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1BZdwy3ngWAXpDxKh9yQz0XuA3HNvsvb6