Learning knowledge is not only to increase the knowledge reserve, but also to understand how to apply it, and to carry out the theories and principles that have been learned into the specific answer environment. The Databricks Certified Data Engineer Professional exam dumps are designed efficiently and pointedly, so that users can check their learning effects in a timely manner after completing a section. Our Certified-Data-Engineer-Professional test material is updating according to the precise of the real exam. Our Databricks Certified Data Engineer Professional exam dumps will help you to conquer all difficulties you may encounter.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Topic 2: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 3: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 4: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Topic 5: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
| Topic 6: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 7: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 8: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 9: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
>> Certified-Data-Engineer-Professional Reliable Source <<
Just look at the text version of the introduction, you may still be unable to determine whether this product is suitable for you, or whether it is worth your purchase. We are very fond of preparing trial versions of our Certified-Data-Engineer-Professional study materials for you so that you can have a clearly check on not only the content of the Certified-Data-Engineer-Professional Exam Braindumps, but also the displays. The content of the tiral version is a small part of our Certified-Data-Engineer-Professional practice questions, and it is easy and convenient to free download.
NEW QUESTION # 69
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.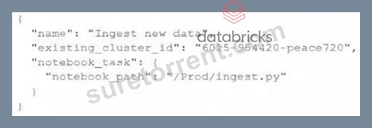
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: C
Explanation:
Databricks jobs create will create a new job with the same name each time it is run.
In order to overwrite the extsting job you need to run databricks jobs reset
NEW QUESTION # 70
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
Answer: A
Explanation:
This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade- off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job.
NEW QUESTION # 71
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
Answer: C
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 72
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.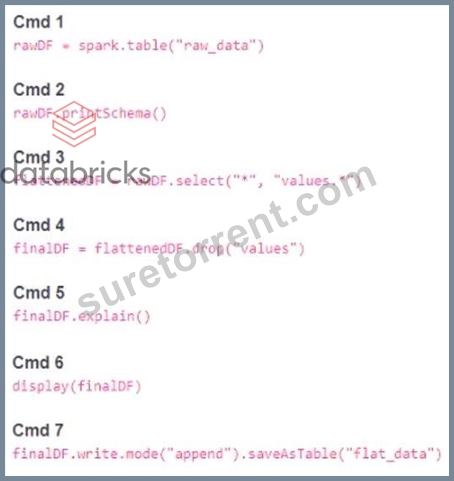
Which command should be removed from the notebook before scheduling it as a job?
Answer: D
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 73
A table is registered with the following code: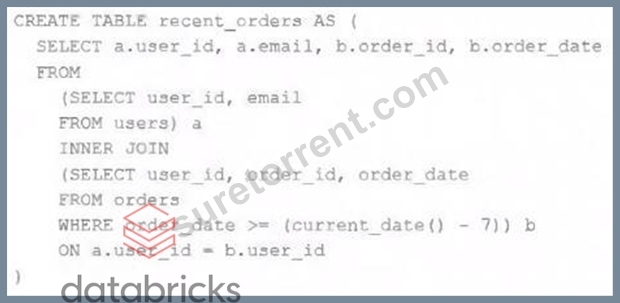
Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
Answer: A
Explanation:
Table is created and data of join will be stored on DBFS and it will be returned on query time.
NEW QUESTION # 74
......
So we can say that the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test questions are real, valid, and updated and these will greatly help you in Certified-Data-Engineer-Professional exam preparation. The availability of Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions in three different formats, free demo download facility, affordable price, free three months updated Certified-Data-Engineer-Professional Exam Questions download facility, and verified and real Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions are the top features of SureTorrent Certified-Data-Engineer-Professional exam questions.
Certified-Data-Engineer-Professional Reliable Torrent: https://www.suretorrent.com/Certified-Data-Engineer-Professional-exam-guide-torrent.html