You can change the time and type of questions of the Microsoft DP-800 exam dumps. Developing AI-Enabled Database Solutions practice questions improve your confidence and ability to complete the exam timely. The Microsoft DP-800 real questions are an advanced strategy to prepare you according to the test service. The Microsoft DP-800 Practice Exam software keeps track of previous attempts and shows the changes in each attempt. Knowing your weaknesses and overcoming them before the Microsoft DP-800 exam is easy.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-800 Study Notes <<
Our DP-800 training quiz is the top selling products in the market. You will save a lot of preparation troubles if you purchase our DP-800 study materials. Our DP-800 exam braindumps are highly similar to the real test. Almost all questions of the real exam will be predicated accurately in our DP-800 Practice Questions, which can add you passing rate of the exam. And you will find that our prices for the exam products are quite favorable.
NEW QUESTION # 48
You need to create a table in the database to store the telemetry data. You have the following Transact-SQL code.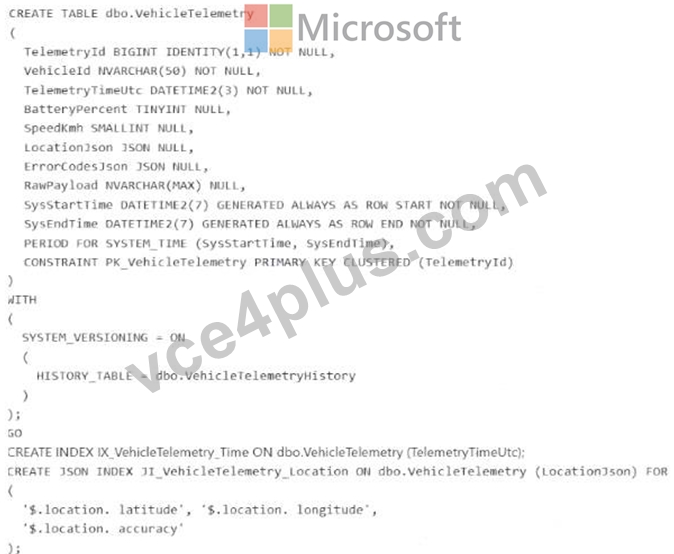
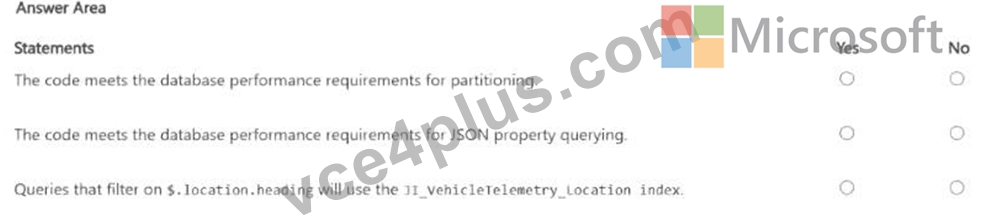
Answer:
Explanation: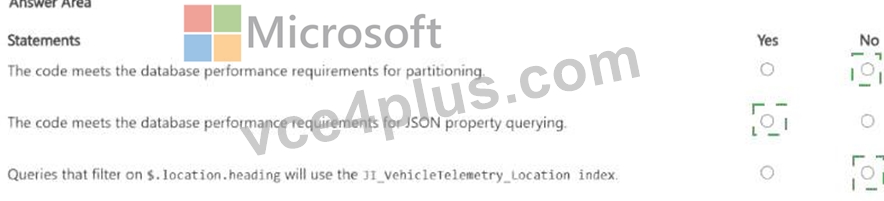
Explanation: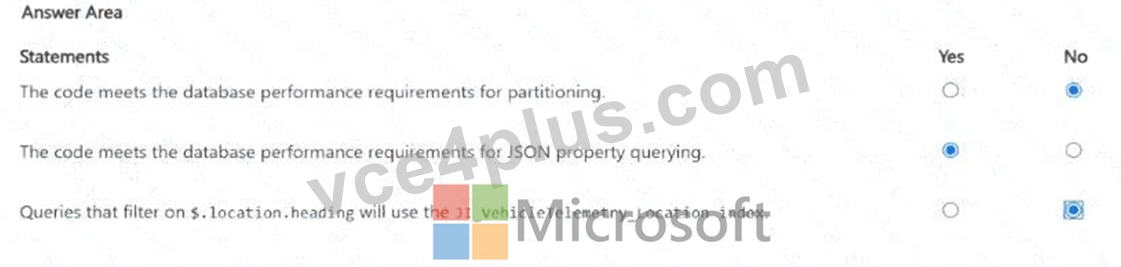
The first statement is No . The requirement says telemetry data must be stored in a partitioned table to provide predictable performance for ingestion and retention operations. However, the shown CREATE TABLE statement does not define a partition function or partition scheme, and the table is created with a regular clustered primary key on TelemetryId. Microsoft's partitioning guidance states that creating a partitioned table requires a partition function , a partition scheme , and creating the table or index on that partition scheme using a partitioning column. None of that appears in the code, so the table is not partitioned.
The second statement is Yes . The code creates a JSON index named JI_VehicleTelemetry_Location on LocationJson for these specific JSON paths: $.location.latitude, $.location.longitude, and $.location.accuracy.
That matches the requirement that those JSON properties must be filterable by using an index seek .
Microsoft documents that JSON indexing is used to optimize filtering and sorting on JSON properties, and the index only helps for the properties included in the index definition.
The third statement is No . The JSON index is defined only for latitude, longitude, and accuracy. A query filtering on $.location.heading references a different path that is not included in the index definition, so that query would not use JI_VehicleTelemetry_Location for that predicate. JSON indexes are path-specific; they do not automatically cover unrelated properties in the same JSON document.
NEW QUESTION # 49
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.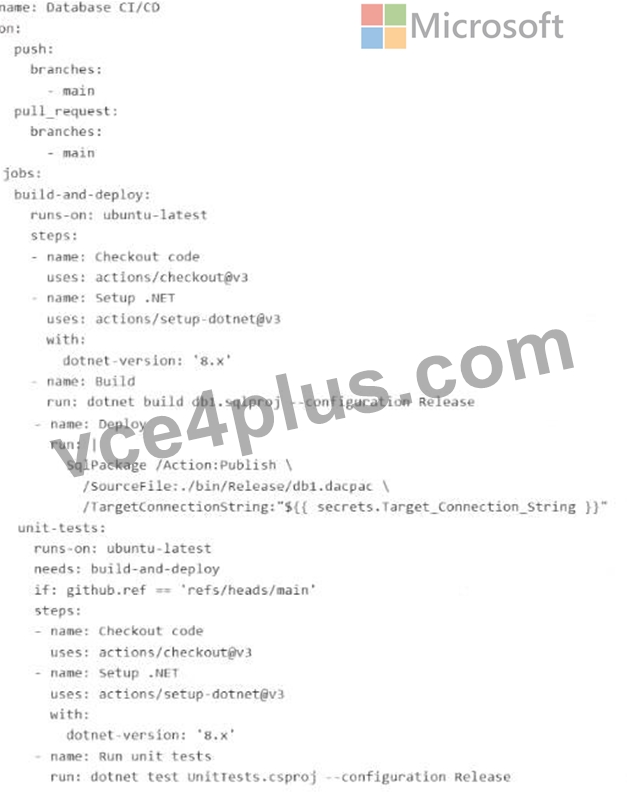
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.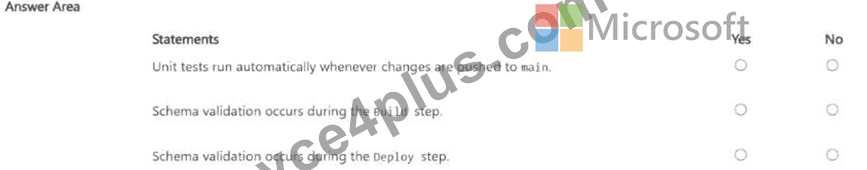
Answer:
Explanation: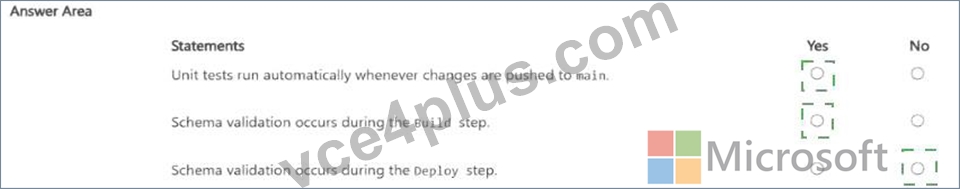
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
NEW QUESTION # 50
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.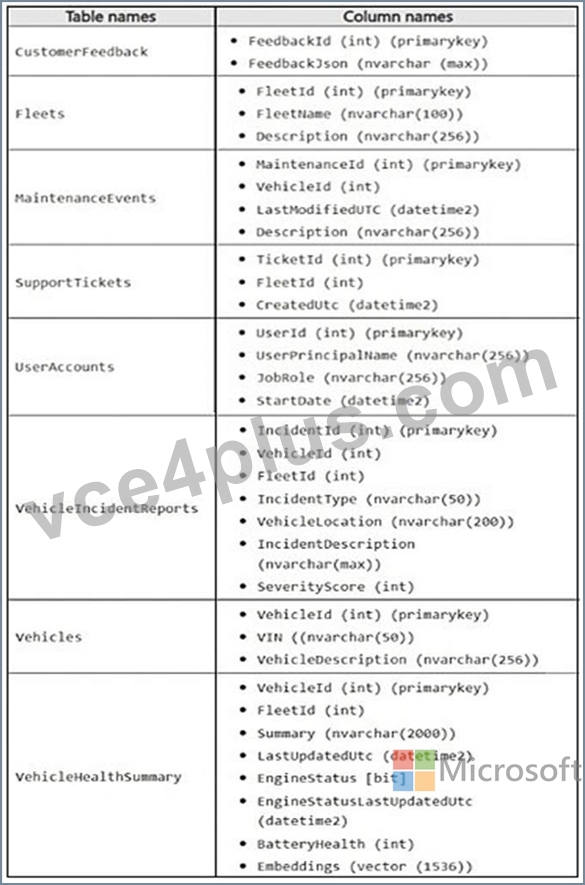
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.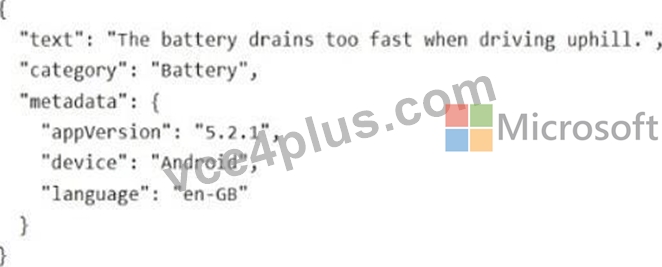
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.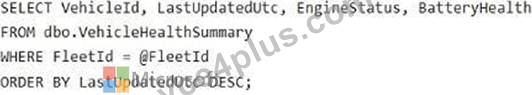
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You need to create a table in the database to store the telemetry data.
You have the following Transact-SQL code.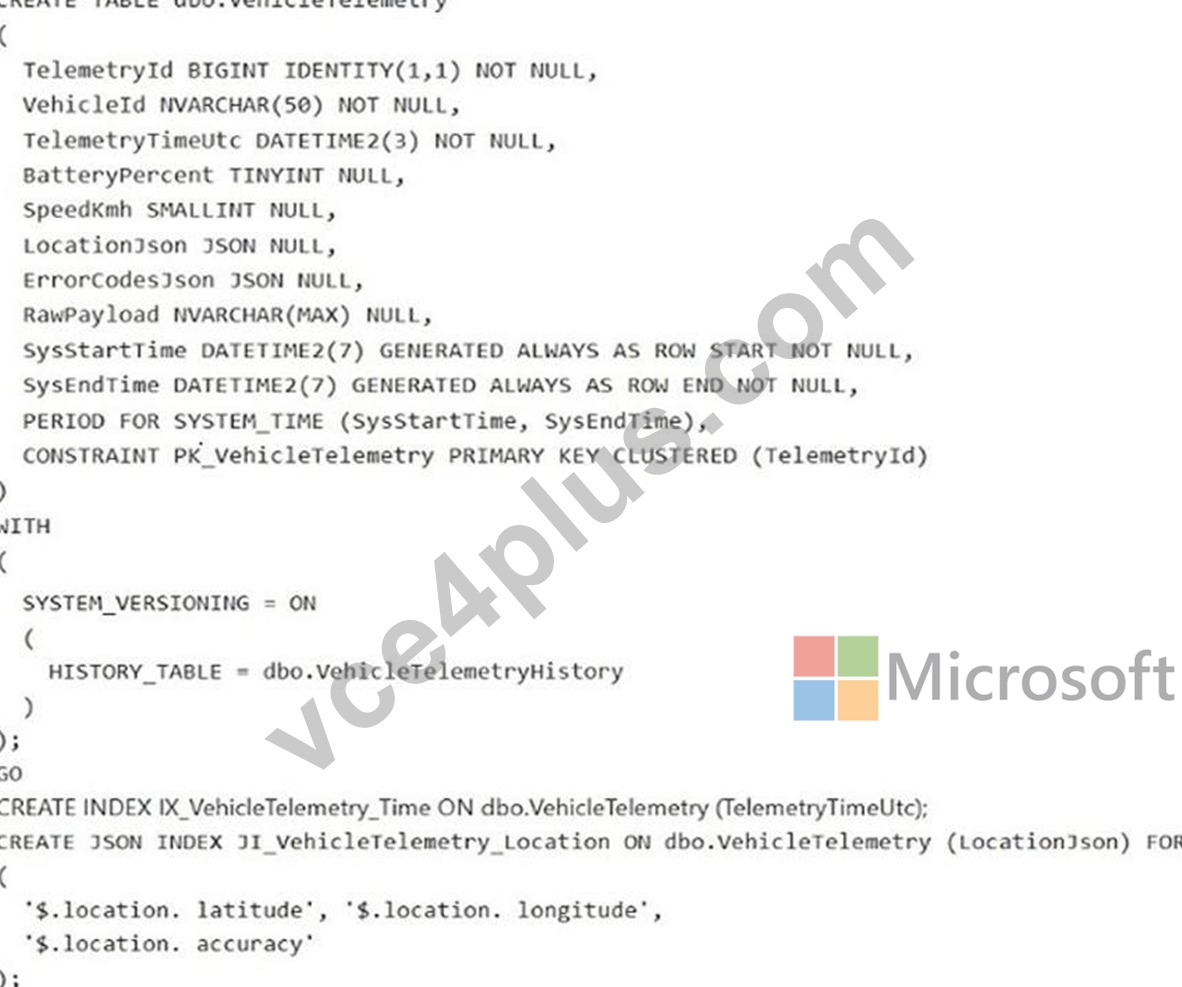
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.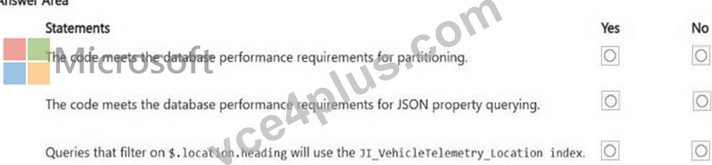
Answer:
Explanation: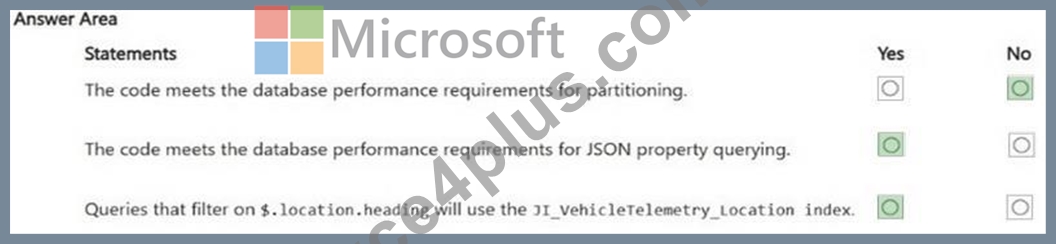
NEW QUESTION # 51
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution; Identify the partition scheme (or the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
Does this meet the goal?
Answer: A
Explanation:
This also does not meet the goal. DROP PARTITION SCHEME removes the partition scheme object from the database; it is not the command used to remove just the rows for the oldest month from a partitioned table.
Microsoft's DROP PARTITION SCHEME documentation is explicit that the statement removes the partition scheme itself.
For removing only the oldest month's rows with minimal impact, Microsoft points to partition-level maintenance operations such as truncating a single partition on a partitioned table. That targets only the needed data subset and is more efficient for retention workloads.
NEW QUESTION # 52
You have a SQL database in Microsoft Fabric that contains a column named Payload. pay load stores customer data in JSON documents that have the following format.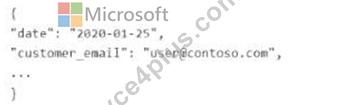
Data analysis shows that some customers have subaddressing in their email address, for example, user1+promo@contoso.com.
You need to return a normalized email value that removes the subaddressing, for example, user! + promo@contoso.com must be normalized to userl@contoso.com.
Which Transact SQL expression should you use?