P.S. Xhs1991がGoogle Driveで共有している無料かつ新しいNCM-MCI-6.10ダンプ:https://drive.google.com/open?id=1BXUF6WtJScfJe9Dz0dFcw0DL66DlpuIP
Xhs1991は君の試験に合格させるだけでなく本当の知識を学ばれます。Xhs1991はあなたが100% でNCM-MCI-6.10試験に合格させるの保証することができてまたあなたのために一年の無料の試験の練習問題と解答の更新サービス提供して、もし試験に失敗したら、弊社はすぐ全額で返金を保証いたします。
| Section | Objectives |
|---|---|
| Analyze and Optimize VM Performance | - Cluster and node metrics analysis - VM resource optimization |
| Advanced Configuration and Troubleshooting | - Troubleshooting Nutanix services - Risk mitigation configuration - Third-party integrations - CLI and API execution - Security posture analysis |
| Analyze and Optimize Network Performance | - Overlay networking optimization - Advanced network configuration - Flow policies analysis and optimization - Physical and virtual network evaluation |
| Business Continuity | - BCDR compliance analysis - Workload resilience evaluation |
| Analyze and Optimize Storage Performance | - Workload performance evaluation - Storage configuration optimization - Storage internals and I/O analysis |
当社Xhs1991のNCM-MCI-6.10学習準備は、自己学習、自己評価、統計レポート、タイミング、およびテスト刺激機能を強化し、各機能はクライアントが包括的に学習するのに役立つ独自の役割を果たします。 NCM-MCI-6.10ガイド資料の自己学習および自己評価機能は、クライアントがNCM-MCI-6.10学習資料の学習結果を確認するのに役立ちます。 NCM-MCI-6.10トレーニングクイズのタイミング機能は、学習者が速度を調整して質問に答え、Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI)アラートを維持するのに役立ちます。学習教材はタイマーを設定します。
質問 # 26
Task 10
An administrator will be deploying Flow Networking and needs to validate that the environment, specifically switch vs1, is appropriately configured. Only VPC traffic should be carried by the switch.
Four versions each of two possible commands have been placed in Desktop\Files\Network\flow.txt. Remove the hash mark (#) from the front of correct First command and correct Second command and save the file.
Only one hash mark should be removed from each section. Do not delete or copy lines, do not add additional lines. Any changes other than removing two hash marks (#) will result in no credit.
Also, SSH directly to any AHV node (not a CVM) in the cluster and from the command line display an overview of the Open vSwitch configuration. Copy and paste this to a new text file named Desktop\Files\Network\AHVswitch.txt.
Note: You will not be able to use the 192.168.5.0 network in this environment.
First command
#net.update_vpc_traffic_config virtual_switch=vs0
net.update_vpc_traffic_config virtual_switch=vs1
#net.update_vpc_east_west_traffic_config virtual_switch=vs0
#net.update_vpc_east_west_traffic_config virtual_switch=vs1
Second command
#net.update_vpc_east_west_traffic_config permit_all_traffic=true
net.update_vpc_east_west_traffic_config permit_vpc_traffic=true
#net.update_vpc_east_west_traffic_config permit_all_traffic=false
#net.update_vpc_east_west_traffic_config permit_vpc_traffic=false
正解:
解説:
First, you need to open the Prism Central CLI from the Windows Server 2019 workstation. You can do this by clicking on the Start menu and typing "Prism Central CLI". Then, you need to log in with the credentials provided to you.
Second, you need to run the two commands that I have already given you in Desktop\Files\Network\flow.txt.
These commands are:
net.update_vpc_traffic_config virtual_switch=vs1 net.update_vpc_east_west_traffic_config permit_vpc_traffic=true These commands will update the virtual switch that carries the VPC traffic to vs1, and update the VPC east- west traffic configuration to allow only VPC traffic. You can verify that these commands have been executed successfully by running the command:
net.get_vpc_traffic_config
This command will show you the current settings of the virtual switch and the VPC east-west traffic configuration.
Third, you need to SSH directly to any AHV node (not a CVM) in the cluster and run the command:
ovs-vsctl show
This command will display an overview of the Open vSwitch configuration on the AHV node. You can copy and paste the output of this command to a new text file named Desktop\Files\Network\AHVswitch.txt.
You can use any SSH client such as PuTTY or Windows PowerShell to connect to the AHV node. You will need the IP address and the credentials of the AHV node, which you can find in Prism Element or Prism Central.
remove # from greens
On AHV execute:
sudo ovs-vsctl show
CVM access AHV access command
nutanix@NTNX-A-CVM:192.168.10.5:~$ ssh root@192.168.10.2 "ovs-vsctl show" Open AHVswitch.txt and copy paste output
質問 # 27
TASK 1
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to
"SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named MonitorSQL02 and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitovm2 in the name.
Finally, correct the issue within "SQL02".
Notes:
* Do not power on the VMs.
* While you will be creating a session, you will need to examine the VM configurations to determine the issue.
* Do not delete the VM to resolve the issue, any other destructive change is acceptable.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to all three tasks, performed within the Nutanix Prism interface.
Task 1: Create Monitoring Session & Save Metrics
* From the Prism Central dashboard, navigate to Operations > Analysis.
* Click the + New Session button.
* Name the session Monitor SQL02.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart.
* Title: Storage IOPS
* Metric: Storage Controller IOPS
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Latency
* Metric: Storage Controller Latency
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Bandwidth
* Metric: Storage Controller Bandwidth
* Click Add.
* Click Save Session.
* With the "Monitor SQL02" session open, right-click anywhere on the page and click Select All.
* Right-click again and select Copy.
* Open Notepad, paste the content, and save the file to the desktop as Task 1.txt.
(The content pasted into Task 1.txt would be the session's chart configurations, showing metrics for SQL01 and SQL02.)
Task 2: Create and Schedule the Report
* While still in the "Monitor SQL02" analysis session, click the Save as Report button (it looks like a bookmark icon).
* Name the report MonitorSQL02 and click Save.
* Navigate to Operations > Reports.
* Find the MonitorSQL02 report in the list. Select its checkbox.
* Click the Actions dropdown and select Schedule.
* Configure the schedule with the following settings:
* Schedule Name: monitovm2_daily_report
* Recurrence: Daily
* Start Time: (Set to a time, e.g., 8:00 AM)
* Repeat every: 1 day(s)
* Retention Policy: Uncheck the "Retain a copy of the report" box. (This ensures reports are not retained).
* Email Report: Check this box.
* Format: PDF
* Recipients: perf_group@ACME.org
* Click Save.
Task 3: Identify and Correct the Performance Issue
This task is performed without powering on the VMs, indicating a configuration error.
Investigation
* Navigate to VMs > Table view.
* Click on the SQL01 (the good VM) and select the Configuration tab.
* Expand the Disks section. Observe that the primary disk is attached to a SCSI bus (e.g., scsi.0). This is the high-performance standard.
* Return to the VM list and click on SQL02 (the problem VM).
* Expand the Disks section.
Root Cause
You discover that the primary disk for SQL02 is attached to an IDE bus. The IDE bus has significant performance limitations and is not suitable for a database server, causing the poor storage performance.
Correction
* With the SQL02 VM selected, click the Update button.
* In the "Update VM" dialog, scroll down to the Disks section.
* Find the disk attached to the IDE bus. Click the Edit (pencil) icon for that disk.
* Change the Bus Type dropdown from IDE to SCSI.
* The Device Index will automatically populate (e.g., scsi.0).
* Click Save in the "Update Disk" dialog.
* (Note: A "VirtIO SCSI Controller" will be automatically added to the VM configuration if one was not already present.)
* Click Save in the "Update VM" dialog.
The VM SQL02 is now configured to use the high-performance VirtIO-SCSI controller, which will resolve the storage performance discrepancy once the VM is powered on.
質問 # 28
Task 14
An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the data.
You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type.
Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster.
The datastore will provide low cost per GB and high performance for your distributed application.
質問 # 29
Task 2
Part1
An administrator logs into Prism Element and sees an alert stating the following:
Cluster services down on Controller VM (35.197.75.196)
Correct this issue in the least disruptive manner.
Part2
In a separate request, the security team has noticed a newly created cluster is reporting.
CVM [35.197.75.196] is using the default password.
They have provided some new security requirements for cluster level security.
Security requirements:
Update the default password for the root user on the node to match the admin user password: Note: 192.168.x.
x is not available. To access a node use the Host IP (172.30.0.x) from a CVM or the supplied external IP address.
Update the default password for the nutanix user on the CVM to match the admin user password.
Resolve the alert that is being reported.
Output the cluster-wide configuration of the SCMA policy to Desktop\Files\output.txt before changes are made.
Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
Enable high-strength password policies for the cluster.
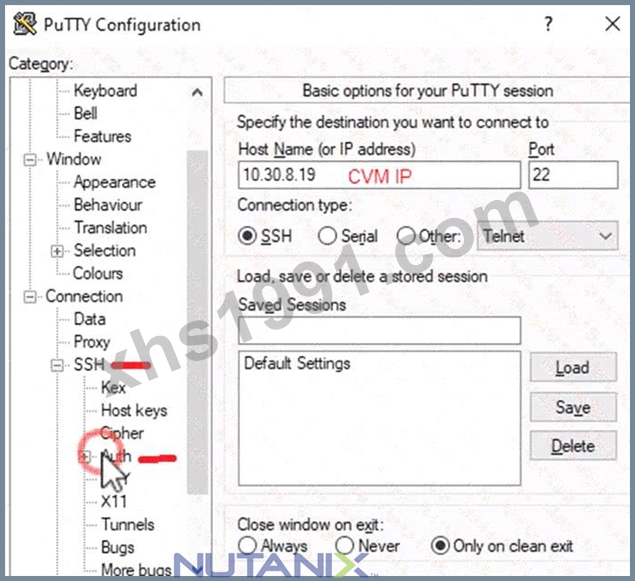
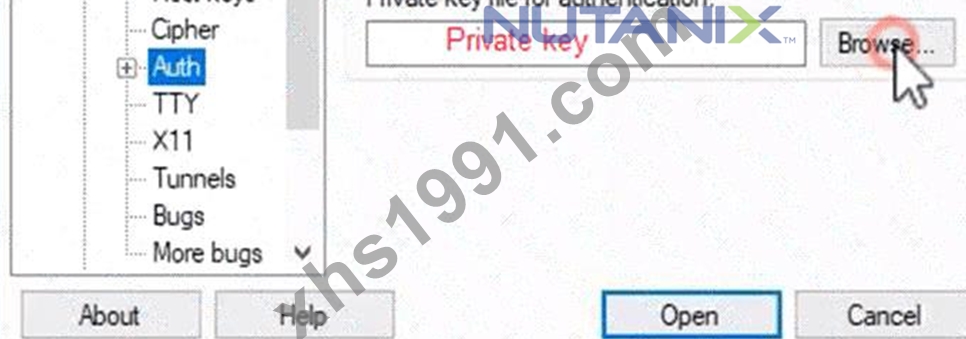
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the Desktop\Files\SSH folder).
Ensure the clusters meets these requirements. Do not reboot any cluster components.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To correct the issue of cluster services down on Controller VM (35.197.75.196) in the least disruptive manner, you need to do the following steps:
Log in to Prism Element using the admin user credentials.
Go to the Alerts page and click on the alert to see more details.
You will see which cluster services are down on the Controller VM. For example, it could be cassandra, curator, stargate, etc.
To start the cluster services, you need to SSH to the Controller VM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the Controller VM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.
txt.
Once you are logged in to the Controller VM, run the command:
cluster status | grep -v UP
This will show you which services are down on the Controller VM.
To start the cluster services, run the command:
cluster start
This will start all the cluster services on the Controller VM.
To verify that the cluster services are running, run the command:
cluster status | grep -v UP
This should show no output, indicating that all services are up.
To clear the alert, go back to Prism Element and click on Resolve in the Alerts page.
To meet the security requirements for cluster level security, you need to do the following steps:
To update the default password for the root user on the node to match the admin user password, you need to SSH to the node using the root user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the node. You will need the IP address and the password of the root user, which you can find in Desktop\Files\SSH\root.txt.
Once you are logged in to the node, run the command:
passwd
This will prompt you to enter a new password for the root user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To update the default password for the nutanix user on the CVM to match the admin user password, you need to SSH to the CVM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the CVM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the CVM, run the command:
passwd
This will prompt you to enter a new password for the nutanix user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To resolve the alert that is being reported, go back to Prism Element and click on Resolve in the Alerts page.
To output the cluster-wide configuration of SCMA policy to Desktop\Files\output.txt before changes are made, you need to log in to Prism Element using the admin user credentials.
Go to Security > SCMA Policy and click on View Policy Details. This will show you the current settings of SCMA policy for each entity type.
Copy and paste these settings into a new text file named Desktop\Files\output.txt.
To enable AIDE (Advanced Intrusion Detection Environment) to run on a weekly basis for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > AIDE Configuration and click on Enable AIDE. This will enable AIDE to monitor file system changes on all CVMs and nodes in the cluster.
Select Weekly as the frequency of AIDE scans and click Save.
To enable high-strength password policies for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > Password Policy and click on Edit Policy. This will allow you to modify the password policy settings for each entity type.
For each entity type (Admin User, Console User, CVM User, and Host User), select High Strength as the password policy level and click Save.
To ensure CVMs require SSH keys for login instead of passwords, you need to log in to Prism Element using the admin user credentials.
Go to Security > Cluster Lockdown and click on Configure Lockdown. This will allow you to manage SSH access settings for the cluster.
Uncheck Enable Remote Login with Password. This will disable password-based SSH access to the cluster.
Click New Public Key and enter a name for the key and paste the public key value from Desktop\Files\SSH\id_rsa.pub. This will add a public key for key-based SSH access to the cluster.
Click Save and Apply Lockdown. This will apply the changes and ensure CVMs require SSH keys for login instead of passwords.
Part1
Enter CVM ssh and execute:
cluster status | grep -v UP
cluster start
If there are issues starting some services, check the following:
Check if the node is in maintenance mode by running the ncli host ls command on the CVM. Verify if the parameter Under Maintenance Mode is set to False for the node where the services are down. If the parameter Under Maintenance Mode is set to True, remove the node from maintenance mode by running the following command:
nutanix@cvm$ ncli host edit id=<host id> enable-maintenance-mode=false
You can determine the host ID by using ncli host ls.
See the troubleshooting topics related to failed cluster services in the Advanced Administration Guide available from the Nutanix Portal's Software Documentation page. (Use the filters to search for the guide for your AOS version). These topics have information about common and AOS-specific logs, such as Stargate, Cassandra, and other modules.
Check for any latest FATALs for the service that is down. The following command prints all the FATALs for a CVM. Run this command on all CVMs.
nutanix@cvm$ for i in `svmips`; do echo "CVM: $i"; ssh $i "ls -ltr /home/nutanix/data/logs/*.FATAL"; done NCC Health Check: cluster_services_down_check (nutanix.com) Part2 Vlad Drac2023-06-05T13:22:00.86I'll update this one with a smaller, if possible, command Update the default password for the root user on the node to match the admin user password echo -e "CHANGING ALL AHV HOST ROOT PASSWORDS.\nPlease input new password: "; read -rs password1; echo "Confirm new password: "; read -rs password2; if [ "$password1" == "$password2" ]; then for host in $(hostips); do echo Host $host; echo $password1 | ssh root@$host "passwd --stdin root"; done; else echo "The passwords do not match"; fi Update the default password for the nutanix user on the CVM sudo passwd nutanix Output the cluster-wide configuration of the SCMA policy ncli cluster get-hypervisor-security-config Output Example:
nutanix@NTNX-372a19a3-A-CVM:10.35.150.184:~$ ncli cluster get-hypervisor-security-config Enable Aide : false Enable Core : false Enable High Strength P... : false Enable Banner : false Schedule : DAILY Enable iTLB Multihit M... : false Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
ncli cluster edit-hypervisor-security-params enable-aide=true
ncli cluster edit-hypervisor-security-params schedule=weekly
Enable high-strength password policies for the cluster.
ncli cluster edit-hypervisor-security-params enable-high-strength-password=true Ensure CVMs require SSH keys for login instead of passwords
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA0600000008gb3CAA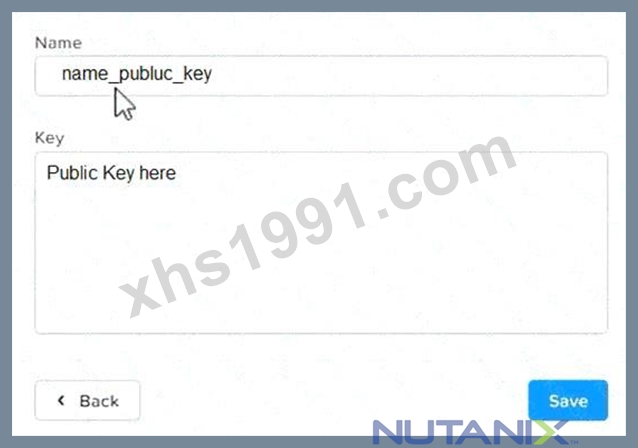
質問 # 30
An administrator needs to perform AOS and AHV upgrades on a Nutanix cluster and wants to ensure that VM data is replicated as quickly as possible when hosts and CVMs are rebooted.
Configure Cluster 1 so that after planned host and CVM reboots, the rebuild scan starts immediately.
Note:
You will need to use SSH for this task. Ignore the fact that this is a 1-node cluster.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure the immediate rebuild scan on Cluster 1.
This task must be performed from an SSH session connected to a CVM (Controller VM) on Cluster 1.
1. Access the Cluster 1 CVM
* From the Prism Central dashboard, navigate to Hardware > Clusters and click on Cluster 1 to open its Prism Element (PE) interface.
* In the Cluster 1 PE, navigate to Hardware > CVMs to find the IP address of any CVM in the cluster.
* Use an SSH client (like PuTTY) to connect to the CVM's IP address.
* Log in with the admin user and password.
2. Modify the Rebuild Delay Setting
By default, the cluster waits 15 minutes (900 seconds) before starting a rebuild scan after a CVM reboot. You will change this setting to 0.
* Once logged into the CVM, run the following command to set the delay to 0 seconds:
gflag --set --gflags=stargate_delayed_rebuild_scan_secs=0
* (Optional but recommended) You can verify the change took effect by running the "get" command:
gflag --get --gflags=stargate_delayed_rebuild_scan_secs
The output should now show stargate_delayed_rebuild_scan_secs=0.
質問 # 31
......
弊社Xhs1991のNCM-MCI-6.10テストブレインダンプを習得するのに20〜30時間しかかからず、試験に参加すれば、NCM-MCI-6.10試験に合格する可能性が非常に高くなります。多くの人々にとって、彼らは現役のスタッフであろうと学生であろうと、仕事や家族生活などで忙しいのです。ただし、NCM-MCI-6.10準備トレントを購入すると、主に仕事、学習、または家族の生活に時間とエネルギーを費やすことができ、毎日Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI)試験トレントを学ぶことができます。また、NCM-MCI-6.10試験の質問で簡単にNCM-MCI-6.10試験に合格できます。
NCM-MCI-6.10資格難易度: https://www.xhs1991.com/NCM-MCI-6.10.html
さらに、Xhs1991 NCM-MCI-6.10ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1BXUF6WtJScfJe9Dz0dFcw0DL66DlpuIP