P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Pass4guide: https://drive.google.com/open?id=1wy6nnErqm0Sn_lcvMqS_s_YciyePJJw4
Would you like to distinguish yourself in IT industry? And would you like to get much more professional recognition? Come on and sign up for Snowflake SPS-C01 Certification Exam to further improve your skills. Pass4guide can help you achieve your wishes. Here has professional knowledge, powerful exam dumps and quality service, which can let you master knowledge and skill with high speed and high efficiency. What's more, it can help you are easy to cross the border and help you access to success.
| Section | Objectives |
|---|---|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
>> SPS-C01 Reliable Exam Bootcamp <<
Our company Pass4guide is glad to provide customers with authoritative study platform. Our SPS-C01 quiz torrent was designed by a lot of experts and professors in different area in the rapid development world. At the same time, if you have any question on our SPS-C01 exam questions, we can be sure that your question will be answered by our professional personal in a short time. In a word, if you choose to buy our SPS-C01 Quiz torrent, you will have the chance to enjoy the authoritative study platform provided by our company.
NEW QUESTION # 28
You are tasked with optimizing the performance of a Snowpark application that uses a UDF to perform complex image processing. The UDF is currently registered using 'session.udf.registeff. You observe that the UDF execution is slow, particularly when processing large batches of images. What steps could you take to potentially improve the performance of this UDF execution? Select all that apply.
Answer: A,D,E
Explanation:
The correct answers are B, C, and E. Locating the stage in the same region minimizes latency (B). Smaller dependency files deploy faster (C). Larger warehouses provide more resources (E). Converting to a UDTF might not always improve performance, it depends on the nature of the image processing (A)' is not directly related to UDF performance optimization, it is used for session management and cleanup (D).
NEW QUESTION # 29
You are developing a Snowpark application to ingest a large dataset into Snowflake. You have a DataFrame with a schema that matches the target table 'TARGET TABLE. Due to network constraints, you need to optimize the insertion process to minimize the number of API calls. Which of the following approaches would provide the MOST efficient way to insert the data?
Answer: C
Explanation:
The most efficient approach is option C: 'data_df.insert_into('TARGET_TABLE')'. This method leverages Snowpark's optimized data transfer mechanisms and performs bulk insertion using the underlying Snowflake engine which minimizes api calls and faster to insert the data. Option A is highly inefficient due to the overhead of constructing and executing individual SQL statements. Option B introduces Pandas, which is slower. Option D involves additional staging steps. Option E is manual chunking which is also slower.
NEW QUESTION # 30
You are developing a Snowpark application to analyze website traffic data'. You have a DataFrame named 'website_logs' with columns 'user_id', 'page_url', and 'timestamp'. You need to create a new DataFrame that contains the count of distinct users who visited each page within a specific time window Consider the following (incomplete) Snowpark Python code: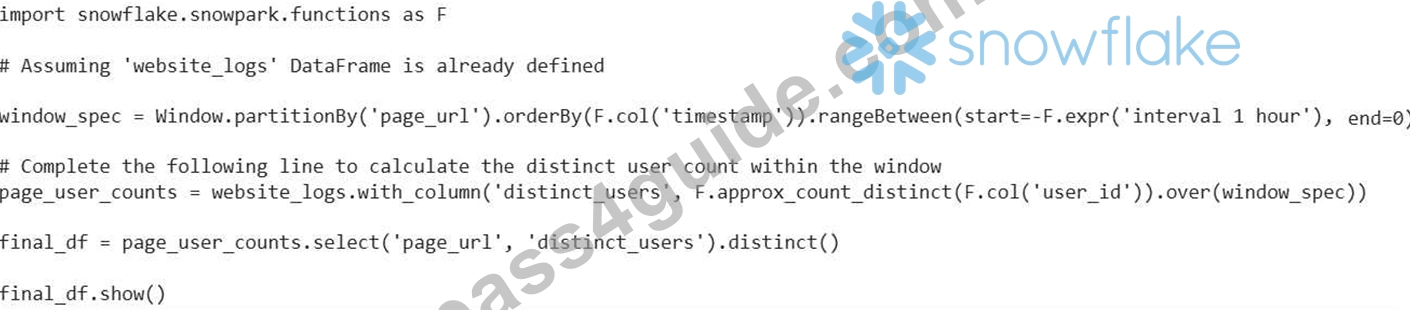
Which of the following code lines, when inserted into the Complete the following line...' comment, will correctly calculate the approximate distinct user count for each page within the specified time window?
Answer: E
Explanation:
The correct code line is 'website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))'. This uses the function to calculate the approximate distinct count of user IDs within the window defined by 'window_spec' . Option B uses exact count which is less performant. Option A performs an aggregation, which will give a different type of result. Option D uses F.window' which is used for tumbling windows, not sliding windows as requested by the problem.
NEW QUESTION # 31
You have a Snowpark DataFrame named with the following schema: 'product_id' (INTEGER), (STRING), 'category' (STRING), 'price' (FLOAT), and 'description' (STRING). You want to perform several data cleaning and transformation steps. Which of the following operations can be efficiently chained together using Snowpark DataFrames to clean null values in 'description', replace special characters in 'product_name' and standardize 'category' values? Select all that apply:
Answer: A,B,C
Explanation:
Options A, B, and D can be efficiently chained using Snowpark DataFrame operations. Option A Cna.fill()') is a built-in method for handling null values. Option B is a SQL function available in Snowpark for string manipulation. Option D ('coalesce()') effectively fills null values from another column if present. Option C, using a UDF for string standardization, is viable but potentially less efficient than using built-in functions if possible. Option E is extremely inefficient as it forces data transfer to the client and row-by-row processing instead of leveraging Snowflake's parallel processing capabilities. Chaining operations allows Snowpark to optimize the execution plan and potentially perform these transformations in a single pass over the data. UDF execution might introduce overhead.
NEW QUESTION # 32
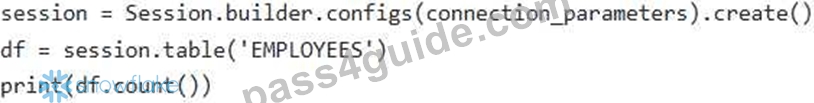
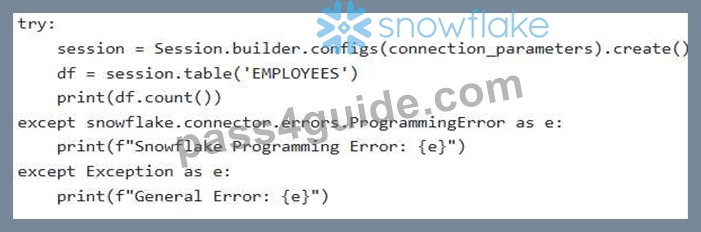
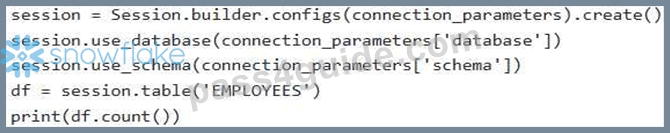
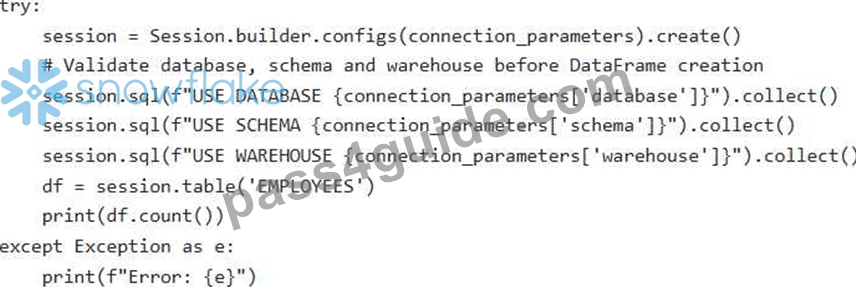
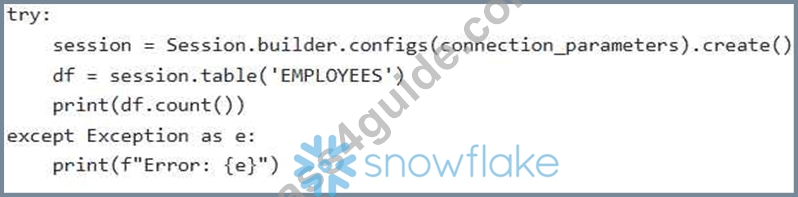
You are developing a Snowpark application that needs to access data from a Snowflake table called 'EMPLOYEES. You want to create a Snowpark DataFrame representing this table. However, you are facing issues with the connection and believe that the database, schema, or warehouse attributes may not be set up correctly for the session. Which of the following code snippets, used in conjunction, BEST demonstrates how to create a Snowpark session with robust error handling to identify and address potential connection issues before attempting to create the DataFrame?
Answer: B,D
Explanation:
The combination of option C and E provides the most robust solution. Option C validates the critical database, schema, and warehouse parameters before attempting to create the DataFrame. If any of these parameters are incorrect, the 'USE statements will fail, and the 'try...except' block will catch the exception. Then Option E specifically catches 'snowflake.connector.errors.ProgrammingError' which would be raised if database/schema/warehouse is not set up correctly. This allows targeted debugging. A and B only catch general errors after the fact, and D is uses deprecated use_database and use_schema calls.
NEW QUESTION # 33
......
As for buying SPS-C01 exam materials online, some candidates may have the concern that if the personal information is safe or not. If you do have the same concern, you can try us. If you buy SPS-C01 exam materials from us, we can ensure you that your personal information will be protected well. We respect the privacy of our customers, once the deal having finished, your personal information will be concealed. Furthermore, the SPS-C01 Exam Materials have the questions and answers, and they will be enough for you to pass the exam. Pass guarantee and money back guarantee if you fail to pass the exam.
SPS-C01 Free Practice Exams: https://www.pass4guide.com/SPS-C01-exam-guide-torrent.html
BONUS!!! Download part of Pass4guide SPS-C01 dumps for free: https://drive.google.com/open?id=1wy6nnErqm0Sn_lcvMqS_s_YciyePJJw4