順便提一下,可以從雲存儲中下載VCESoft Databricks-Certified-Data-Engineer-Professional考試題庫的完整版:https://drive.google.com/open?id=1c26rPzJelBX-JMttmqcYn_Pq0J7vds62
與 VCESoft考古題的超低價格相反,VCESoft提供的Databricks-Certified-Data-Engineer-Professional考試考古題擁有最好的品質。而且更重要的是,VCESoft為你提供優質的服務。只要你支付了你想要的考古題,那麼你馬上就可以得到它。VCESoft網站有你最需要的,也是最適合你的考試資料。你購買了Databricks-Certified-Data-Engineer-Professional考古題以後還可以得到一年的免費更新服務,一年之內,只要你想更新你擁有的資料,那麼你就可以得到最新版。VCESoft盡最大努力給你提供最大的方便。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Monitoring and Alerting | 10% | - Track data lineage and metrics - Set up alerts and notifications - Monitor pipeline performance and health |
| Topic 2: Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic - Use Databricks-specific libraries and APIs - Write efficient and maintainable code |
| Topic 3: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices |
| Topic 4: Data Modelling | 6% | - Optimize table design and partitioning - Design Medallion Architecture - Implement dimensional and relational models |
| Topic 5: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Apply cost management best practices - Optimize compute and storage resources |
| Topic 6: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources - Handle incremental and batch data loads - Use Auto Loader and structured streaming |
| Topic 7: Data Sharing and Federation | 5% | - Manage cross-platform data access - Implement Lakehouse Federation - Use Delta Sharing for secure data sharing |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards - Apply data cleansing and validation rules - Implement schema evolution and management |
| Topic 9: Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit - Implement access control and permissions - Ensure data privacy and compliance |
| Topic 10: Data Governance | 7% | - Enforce data policies and standards - Manage data assets and metadata - Use Unity Catalog for governance |
>> Databricks-Certified-Data-Engineer-Professional考試心得 <<
如果你選擇了VCESoft的幫助,我們一定不遺餘力地幫助你通過考試。而且我們還會為你提供一年的免費的更新考試練習題和答案的售後服務。不用再猶豫了!請選擇VCESoft,它將會是你通過Databricks-Certified-Data-Engineer-Professional認證考試的最好保證。快將VCESoft加入你的購物車吧!
問題 #65
A data engineer is optimizing a MERGE operation on an 800GB UC-managed table that experiences frequent updates and deletions. Which two actions should the engineer prioritize to improve MERGE performance? (Choose two.)
答案:B,E
解題說明:
Liquid clustering on the merge join keys improves data locality and reduces the amount of data scanned during MERGE operations, which is especially effective for large, frequently updated tables. Enabling deletion vectors avoids rewriting entire Parquet files for updates and deletes, significantly reducing I/O and improving MERGE performance on Unity Catalog-managed tables.
問題 #66
Which statement describes integration testing?
答案:B
解題說明:
Integration testing is a type of software testing where components of the software are gradually integrated and then tested as a unified group.
問題 #67
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
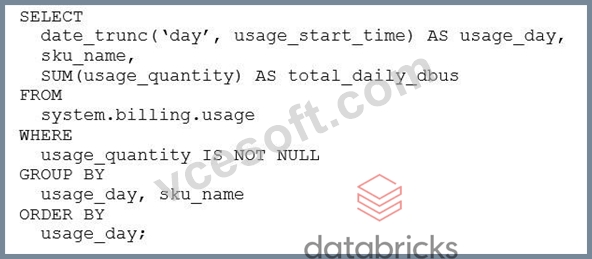
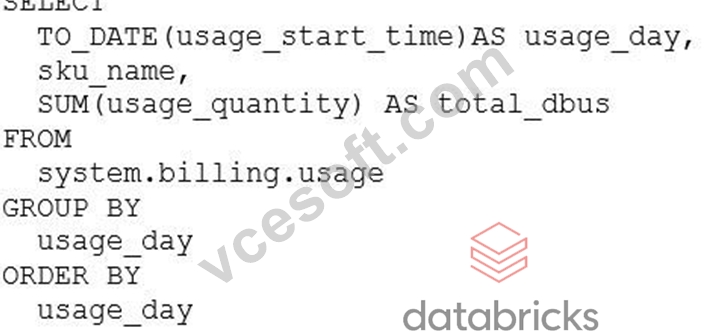
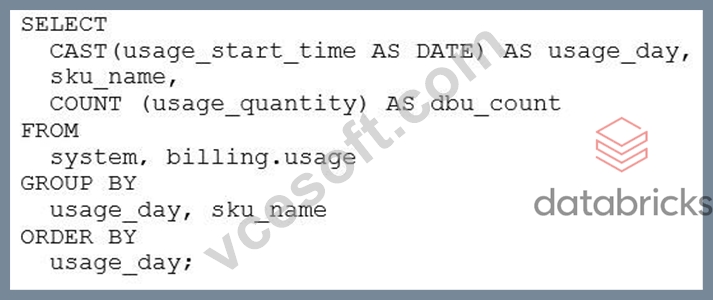
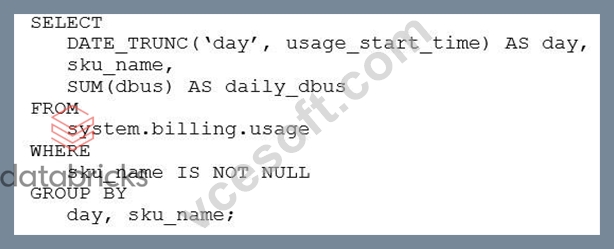
答案:A
解題說明:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
問題 #68
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
答案:A
解題說明:
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
問題 #69
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
答案:A
解題說明:
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver.
問題 #70
......
所有的Databricks職員都知道,Databricks-Certified-Data-Engineer-Professional認證考試的資格是不容易拿到的。但是,參加Databricks-Certified-Data-Engineer-Professional認證考試獲得資格又是提升自己能力以及更好地證明自己的價值的途徑,所以不得不選擇。那麼,難道沒有一個簡單的方法可以讓大家更容易地通過Databricks認證考試嗎?當然有了。VCESoft的考古題就是一個最好的方法。VCESoft有你需要的所有資料,絕對可以滿足你的要求。你可以到VCESoft的网站了解更多的信息,找到你想要的考试资料。
Databricks-Certified-Data-Engineer-Professional考試大綱: https://www.vcesoft.com/Databricks-Certified-Data-Engineer-Professional-pdf.html
此外,這些VCESoft Databricks-Certified-Data-Engineer-Professional考試題庫的部分內容現在是免費的:https://drive.google.com/open?id=1c26rPzJelBX-JMttmqcYn_Pq0J7vds62