BTW, DOWNLOAD part of Exam4Labs DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1VHoqBlLL2mPr0KwCLIySQDZB0SWSdSpR
These DP-100 exam questions braindumps are designed in a way that makes it very simple for the candidates. Each and every DP-100 topic is elaborated with examples clearly. Use Exam4Labs top rate Microsoft DP-100 Exam Testing Tool for making your success possible. DP-100 exam preparation is a hard subject. Plenty of concepts get mixed up together due to which student feel difficult to identify them. There is no similar misconception in DP-100 Dumps because we have made it more interactive for you. The candidates who are less skilled may feel difficult to understand the DP-100 questions can take help from these braindumps. The tough topics of DP-100 certification have been further made easy with examples, simulations and graphs. Candidates can avail the opportunity of demo of free DP-100 dumps.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
| Exam Number: | DP-100 |
| Exam Format: | Multiple choice, Drag and drop, Multiple select, Case studies, Yes/No |
| Certificate Validity Period: | 1 year |
| Available Languages: | Korean, Japanese, French, Portuguese (Brazil), Indonesian (Indonesia), Italian, German, Chinese (Traditional), Spanish, Russian, English, Chinese (Simplified), Arabic (Saudi Arabia) |
| Real Exam Qty: | 40-60 |
| Exam Price: | $165 USD |
| Exam Duration: | 100 minutes |
| Passing Score: | 700 |
| Related Certifications: | Microsoft Certified: Azure AI Engineer Associate Microsoft Certified: Azure Data Engineer Associate |
| Recommended Training: | Microsoft Learn Learning Path Course DP-100T01-A: Designing and Implementing a Data Science Solution on Azure |
| Exam Registration: | Microsoft Learn Registration Pearson VUE Scheduling |
| Sample Questions: | Microsoft DP-100 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended knowledge: Azure fundamentals, Python programming, data science concepts, machine learning frameworks (Scikit-learn, PyTorch, Tensorflow) |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-100 |
We has a long history of 10 years in designing the DP-100 exam guide and enjoys a good reputation across the globe. There are so many features to show that our DP-100 study engine surpasses others. We can confirm that the high quality is the guarantee to your success. At the same time, the prices of our DP-100 practice materials are quite reasonable for no matter the staffs or the students to afford. What is more, usually we will give some discounts to our worthy customers.
The DP-100 Exam is intended for data scientists who have experience working with data and developing machine learning models. It focuses on the practical application of data science techniques using Azure tools and services. Candidates will need to demonstrate their ability to use Azure Machine Learning to prepare data, train models, and deploy solutions. They will also need to know how to work with other Azure services such as Azure Databricks, Azure Stream Analytics, and Azure Synapse Analytics.
NEW QUESTION # 366
You use the Azure Machine Learning SDK to run a training experiment that trains a classification model and calculates its accuracy metric.
The model will be retrained each month as new data is available.
You must register the model for use in a batch inference pipeline.
You need to register the model and ensure that the models created by subsequent retraining experiments are registered only if their accuracy is higher than the currently registered model.
What are two possible ways to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: D,E
Explanation:
Explanation
E: Using tags, you can track useful information such as the name and version of the machine learning library used to train the model. Note that tags must be alphanumeric.
Reference:
https://notebooks.azure.com/xavierheriat/projects/azureml-getting-started/html/how-to-use-azureml/deployment/
NEW QUESTION # 367
You need to set up the Permutation Feature Importance module according to the model training requirements.
Which properties should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.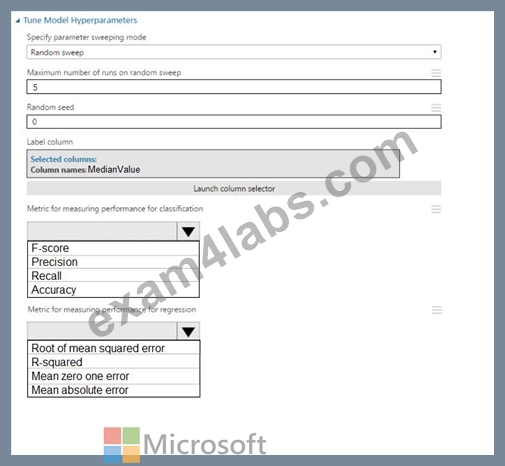
Answer:
Explanation: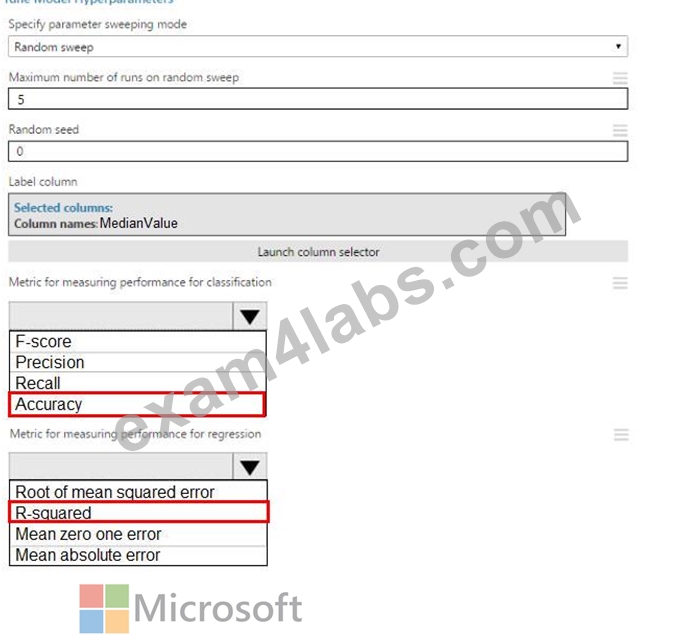
Explanation:
Box 1: Accuracy
Scenario: You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
Box 2: R-Squared
NEW QUESTION # 368
You need to identify the methods for dividing the data according to the testing requirements.
Which properties should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.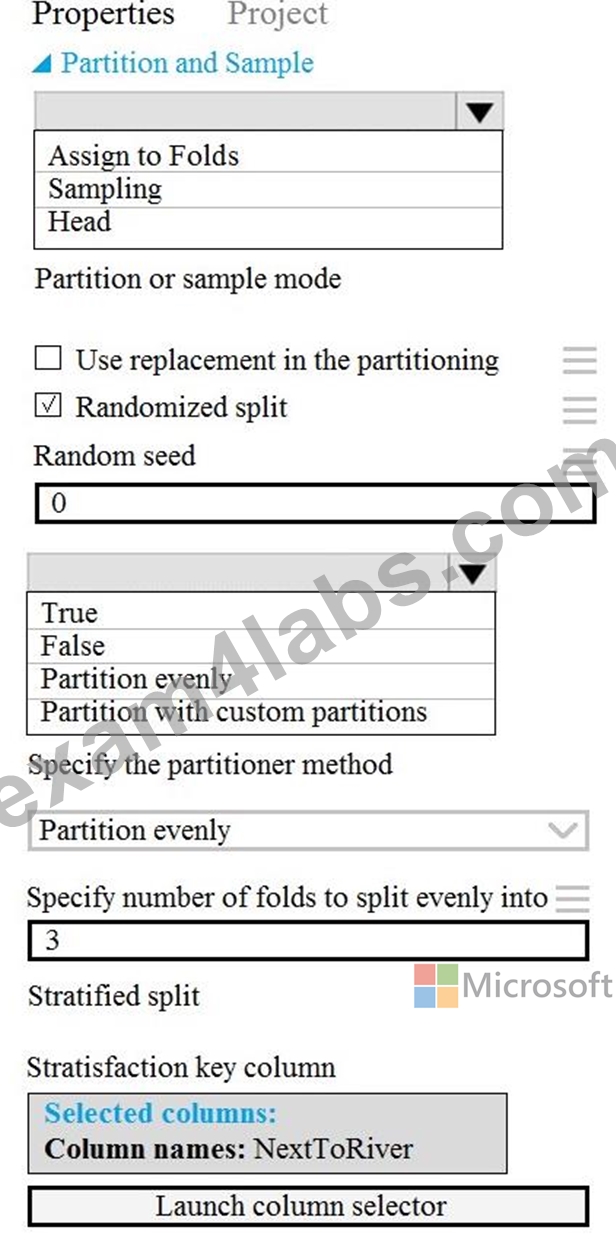
Answer:
Explanation: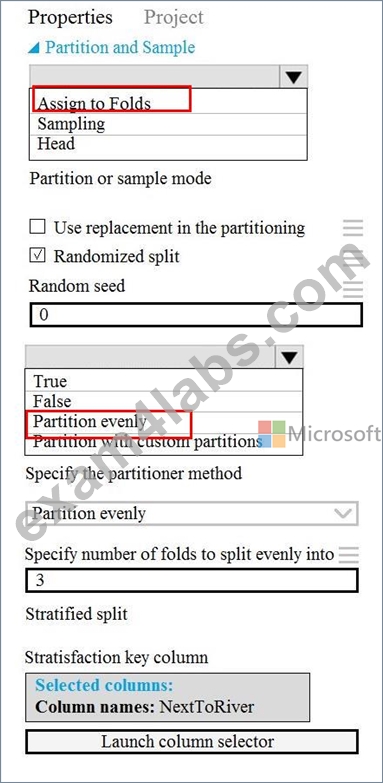
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/algorithm-module-reference/partition-and-sample
NEW QUESTION # 369
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.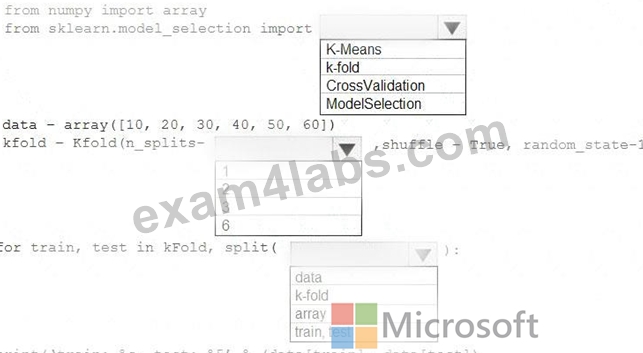
Answer:
Explanation: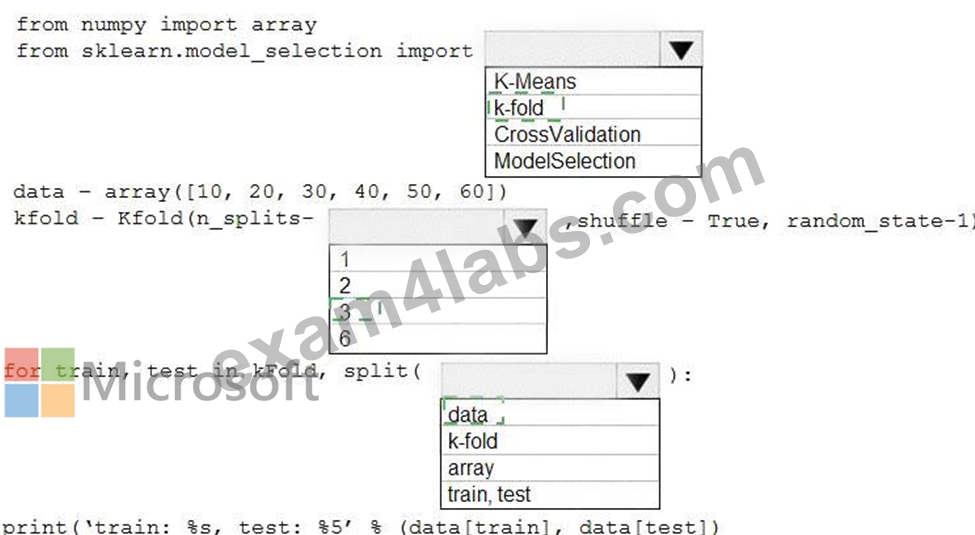
Explanation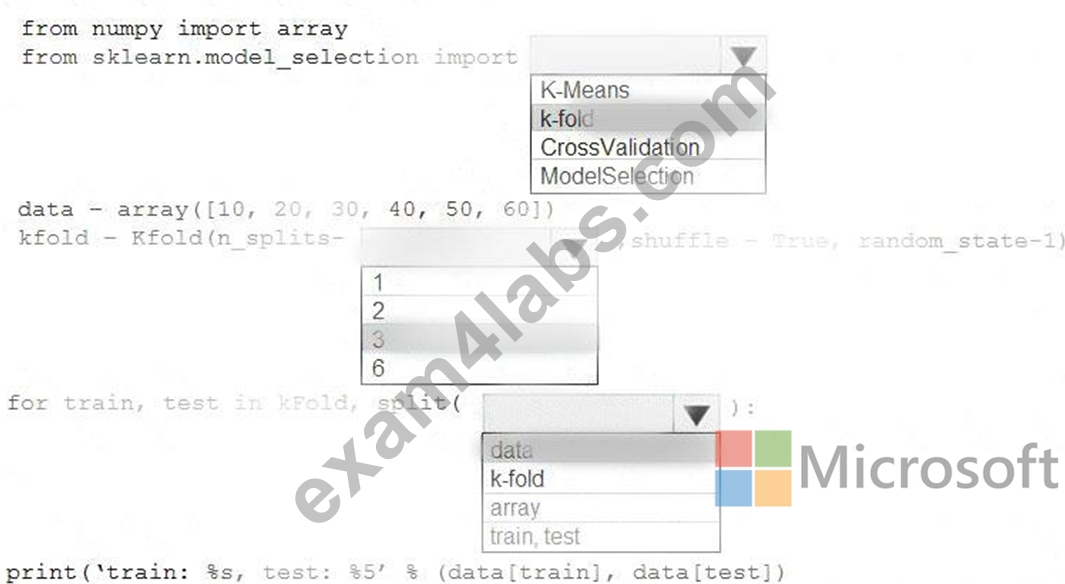
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default).
The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
>>>
>>> from sklearn.model_selection import KFold
>>> X = np.array([[1, 2], [3, 4], [1, 2], [3, 4]])
>>> y = np.array([1, 2, 3, 4])
>>> kf = KFold(n_splits=2)
>>> kf.get_n_splits(X)
2
>>> print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
>>> for train_index, test_index in kf.split(X):
print("TRAIN:", train_index, "TEST:", test_index)
X_train, X_test = X[train_index], X[test_index]
y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
NEW QUESTION # 370
You use the Azure Machine Learning Python SDK to define a pipeline to train a model.
The data used to train the model is read from a folder in a datastore.
You need to ensure the pipeline runs automatically whenever the data in the folder changes.
What should you do?
Answer: B
Explanation:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-trigger-published-pipeline
NEW QUESTION # 371
......
DP-100 Actual Test Pdf: https://www.exam4labs.com/DP-100-practice-torrent.html
BTW, DOWNLOAD part of Exam4Labs DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1VHoqBlLL2mPr0KwCLIySQDZB0SWSdSpR