참고: Itexamdump에서 Google Drive로 공유하는 무료 2026 Nutanix NCM-MCI-6.10 시험 문제집이 있습니다: https://drive.google.com/open?id=1L41imOb3JBcPsjzncXZIglnL4qf7_seO
Nutanix NCM-MCI-6.10덤프의 유효성을 보장해드릴수 있도록 저희 기술팀은 오랜시간동안Nutanix NCM-MCI-6.10시험에 대하여 분석하고 연구해 왔습니다. Nutanix NCM-MCI-6.10 덤프를 한번 믿고Nutanix NCM-MCI-6.10시험에 두려움없이 맞서보세요. 만족할수 있는 좋은 성적을 얻게 될것입니다.
| Section | Objectives |
|---|---|
| Deploy and Upgrade Nutanix Environments | - Cluster installation and configuration - Software and firmware upgrades - Foundation processes |
| Implement and Manage Security and Compliance | - Compliance frameworks - Security hardening - Access control and authentication |
| Troubleshoot and Resolve Complex Issues | - Cluster health management - Log analysis and diagnostics - Failure recovery procedures |
| Configure and Manage Nutanix Networking | - Advanced networking scenarios - AHV networking configuration - Network segmentation and microsegmentation |
| Manage and Optimize Nutanix Storage | - Storage optimization and efficiency - Storage container and VDisk management - Data protection and disaster recovery |
| Analyze and Remediate Performance Issues | - Troubleshooting storage performance - Troubleshooting network performance - Performance monitoring and metrics |
| Manage and Configure Nutanix Virtual Infrastructure | - VM management and operations - Resource scheduling and optimization - AHV cluster configuration |
Nutanix인증 NCM-MCI-6.10시험은 IT업종종사분들에게 널리 알려진 유명한 자격증을 취득할수 있는 시험과목입니다. Nutanix인증 NCM-MCI-6.10시험은 영어로 출제되는만큼 시험난이도가 많이 높습니다.하지만 Itexamdump의Nutanix인증 NCM-MCI-6.10덤프만 있다면 아무리 어려운 시험도 쉬워집니다. 오르지 못할 산도 정복할수 있는게Itexamdump제품의 우점입니다. Itexamdump의Nutanix인증 NCM-MCI-6.10덤프로 시험을 패스하여 자격증을 취득하면 정상에 오를수 있습니다.
질문 # 16
Use Prism Element for this question.
The Application team has a 3 tier application (App Server, Web Server, and Database Server) that is mission critical and requires as close to 0 RPO and RTO as possible with their current license level.
The organization has 2 clusters, with one cluster (Cluster 1) being production and the other cluster (Cluster 2) being remote/DR. Cluster 2 should be able to fail back to Cluster 1.
The connectivity between the two sites is >5ms and replication traffic should not use more than 10Mbps of bandwidth. The Application team requests a plan that includes the ability to go back 2 days locally, and 2 days remotely.
The team also requests that all 3 VMs be treated as a single group and backed up collectively in a snapshot.
The three VMs are:
* Web-Prod
* App-Prod
* DB-Prod
Use Task3 as part of the name for any objects created for this task.
Note: VMs do NOT need to be powered on. You will need to use the 172.30.0.x IP addresses when configuring DR.
정답:
설명:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Disaster Recovery from the Cluster 1 Prism Element interface.
1. Add Cluster 2 as a Remote Site
First, you must register Cluster 2 as a DR target for Cluster 1.
* From the Cluster 1 Prism Element dashboard, navigate to Data Protection from the main dropdown menu.
* Click the Remote Site tab.
* Click the + Remote Site button and select Physical Cluster.
* In the "Name" field, enter Cluster2_DR_Task3.
* In the "Address" field, enter the 172.30.0.x Virtual IP address of Cluster 2.
* Click Save. The clusters will exchange credentials and connect.
2. Throttle Replication Bandwidth
Next, apply the 10 Mbps bandwidth limit for traffic going to Cluster 2.
* On the same Remote Site tab, select the newly created Cluster2_DR_Task3.
* Click the Update button.
* In the dialog, set the Bandwidth Limit to 10 Mbps.
* Click Save.
3. Create the Protection Domain
A Protection Domain (PD) is the top-level object that will manage the VMs and replication schedules.
* In the Data Protection dashboard, click the Table tab.
* Click the + Protection Domain button and select Async DR.
* For the Name, enter App_PD_Task3.
* Click Create.
4. Protect VMs in a Consistency Group
Now you will add the three application VMs to the new Protection Domain as a single Consistency Group (CG).
* You will be taken to the dashboard for the new App_PD_Task3. In the Entities panel, click the Protect Entities button.
* In the "Protect Entities" dialog, search for and select the three VMs:
* Web-Prod
* App-Prod
* DB-Prod
* Click Next.
* Select Create new consistency group and name it App_CG_Task3.
* Click Protect.
5. Create the Replication Schedule
Finally, configure the schedule to meet the RPO and retention requirements.
* In the App_PD_Task3 dashboard, click the Schedules tab.
* Click the + New Schedule button.
* Remote Site: Select Cluster2_DR_Task3.
* RPO (Repeat every): Select NearSync. Set the RPO to 1 minute.
* Note: This is the lowest possible RPO for an Async (>5ms latency) connection, fulfilling the "as close to 0" requirement.
* Local Retention: Set to 2 Days.
* Remote Retention: Set to 2 Days.
* Ensure the "Store snapshots for 2-way replication" checkbox is enabled to allow failback from Cluster 2.
* Click Create Schedule.
질문 # 17
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
정답:
설명:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
질문 # 18
Task 12
The application team is reporting performance degradation for a business-critical application that runs processes all day on Saturdays.
The team is requesting monitoring or processor, memory and storage utilization for the three VMs that make up the database cluster for the application: ORA01, ORA02 and ORA03.
The report should contain tables for the following:
At the cluster level, only for the current cluster:
The maximum percentage of CPU used
At the VM level, including any future VM with the prefix ORA:
The maximum time taken to process I/O Read requests
The Maximum percentage of time a VM waits to use physical CPU, out of the local CPU time allotted to the VM.
The report should run on Sundays at 12:00 AM for the previous 24 hours. The report should be emailed to appdev@cyberdyne.net when competed.
Create a report named Weekends that meets these requirements
Note: You must name the report Weekends to receive any credit. Any other objects needed can be named as you see fit. SMTP is not configured.
정답:
설명:
See the Explanation for step by step solution.
Explanation:
To create a report named Weekends that meets the requirements, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter Weekends as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select Cluster. Click Next.
Under the Custom Columns option, add the following variable: CPU Usage (%). Click Next.
Under the Aggregation option for CPU Usage (%), select Max. Click Next.
Under the Filter option, select Current Cluster from the drop-down menu. Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Custom Views section, select Data Table again. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, I/O Read Latency (ms), VM Ready Time (%). Click Next.
Under the Aggregation option for I/O Read Latency (ms) and VM Ready Time (%), select Max. Click Next.
Under the Filter option, enter ORA* in the Name field. This will include any future VM with the prefix ORA.
Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Report Settings option, select Weekly from the Schedule drop-down menu and choose Sunday as the day of week. Enter 12:00 AM as the time of day. Enter appdev@cyberdyne.net as the Email Recipient.
Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
질문 # 19
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
정답:
설명:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
질문 # 20
Task 2
Part1
An administrator logs into Prism Element and sees an alert stating the following:
Cluster services down on Controller VM (35.197.75.196)
Correct this issue in the least disruptive manner.
Part2
In a separate request, the security team has noticed a newly created cluster is reporting.
CVM [35.197.75.196] is using the default password.
They have provided some new security requirements for cluster level security.
Security requirements:
Update the default password for the root user on the node to match the admin user password: Note: 192.168.x.
x is not available. To access a node use the Host IP (172.30.0.x) from a CVM or the supplied external IP address.
Update the default password for the nutanix user on the CVM to match the admin user password.
Resolve the alert that is being reported.
Output the cluster-wide configuration of the SCMA policy to Desktop\Files\output.txt before changes are made.
Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
Enable high-strength password policies for the cluster.
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the Desktop\Files\SSH folder).
Ensure the clusters meets these requirements. Do not reboot any cluster components.
정답:
설명:
See the Explanation for step by step solution.
Explanation:
To correct the issue of cluster services down on Controller VM (35.197.75.196) in the least disruptive manner, you need to do the following steps:
Log in to Prism Element using the admin user credentials.
Go to the Alerts page and click on the alert to see more details.
You will see which cluster services are down on the Controller VM. For example, it could be cassandra, curator, stargate, etc.
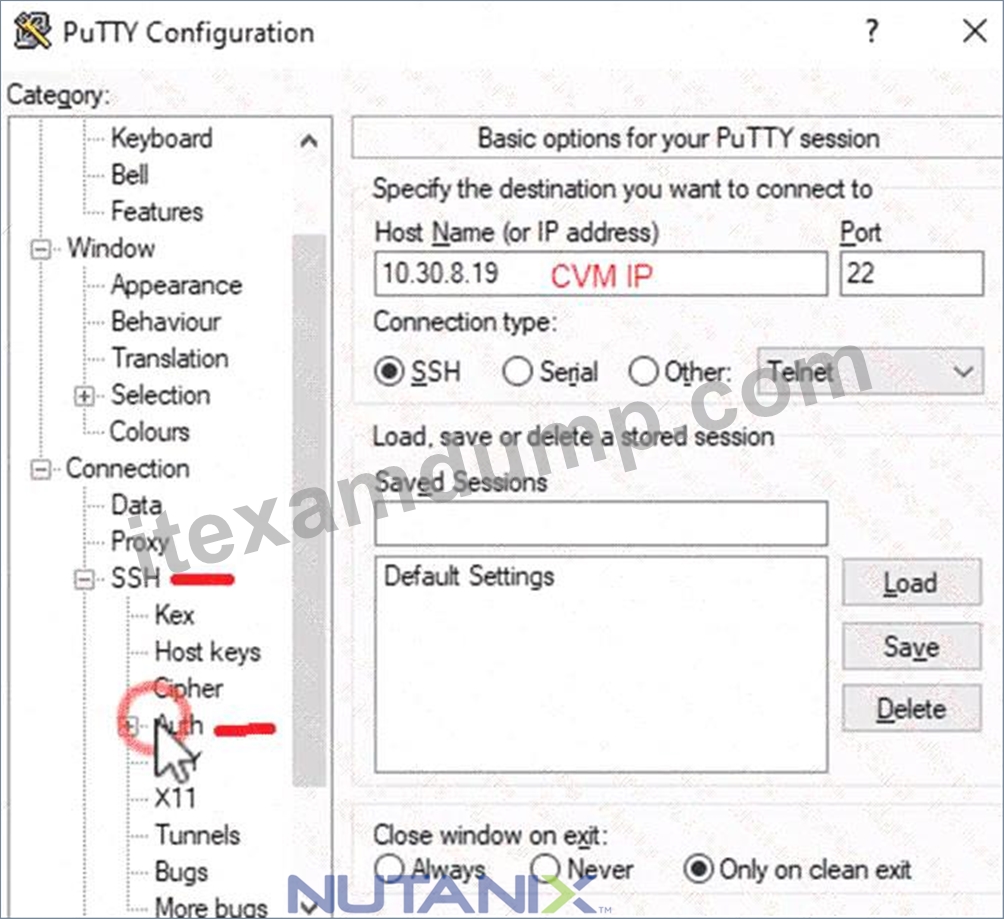
To start the cluster services, you need to SSH to the Controller VM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the Controller VM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.
txt.
Once you are logged in to the Controller VM, run the command:
cluster status | grep -v UP
This will show you which services are down on the Controller VM.
To start the cluster services, run the command:
cluster start
This will start all the cluster services on the Controller VM.
To verify that the cluster services are running, run the command:
cluster status | grep -v UP
This should show no output, indicating that all services are up.
To clear the alert, go back to Prism Element and click on Resolve in the Alerts page.
To meet the security requirements for cluster level security, you need to do the following steps:
To update the default password for the root user on the node to match the admin user password, you need to SSH to the node using the root user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the node. You will need the IP address and the password of the root user, which you can find in Desktop\Files\SSH\root.txt.
Once you are logged in to the node, run the command:
passwd
This will prompt you to enter a new password for the root user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To update the default password for the nutanix user on the CVM to match the admin user password, you need to SSH to the CVM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the CVM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the CVM, run the command:
passwd
This will prompt you to enter a new password for the nutanix user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To resolve the alert that is being reported, go back to Prism Element and click on Resolve in the Alerts page.
To output the cluster-wide configuration of SCMA policy to Desktop\Files\output.txt before changes are made, you need to log in to Prism Element using the admin user credentials.
Go to Security > SCMA Policy and click on View Policy Details. This will show you the current settings of SCMA policy for each entity type.
Copy and paste these settings into a new text file named Desktop\Files\output.txt.
To enable AIDE (Advanced Intrusion Detection Environment) to run on a weekly basis for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > AIDE Configuration and click on Enable AIDE. This will enable AIDE to monitor file system changes on all CVMs and nodes in the cluster.
Select Weekly as the frequency of AIDE scans and click Save.
To enable high-strength password policies for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > Password Policy and click on Edit Policy. This will allow you to modify the password policy settings for each entity type.
For each entity type (Admin User, Console User, CVM User, and Host User), select High Strength as the password policy level and click Save.
To ensure CVMs require SSH keys for login instead of passwords, you need to log in to Prism Element using the admin user credentials.
Go to Security > Cluster Lockdown and click on Configure Lockdown. This will allow you to manage SSH access settings for the cluster.
Uncheck Enable Remote Login with Password. This will disable password-based SSH access to the cluster.
Click New Public Key and enter a name for the key and paste the public key value from Desktop\Files\SSH\id_rsa.pub. This will add a public key for key-based SSH access to the cluster.
Click Save and Apply Lockdown. This will apply the changes and ensure CVMs require SSH keys for login instead of passwords.
Part1
Enter CVM ssh and execute:
cluster status | grep -v UP
cluster start
If there are issues starting some services, check the following:
Check if the node is in maintenance mode by running the ncli host ls command on the CVM. Verify if the parameter Under Maintenance Mode is set to False for the node where the services are down. If the parameter Under Maintenance Mode is set to True, remove the node from maintenance mode by running the following command:
nutanix@cvm$ ncli host edit id=<host id> enable-maintenance-mode=false
You can determine the host ID by using ncli host ls.
See the troubleshooting topics related to failed cluster services in the Advanced Administration Guide available from the Nutanix Portal's Software Documentation page. (Use the filters to search for the guide for your AOS version). These topics have information about common and AOS-specific logs, such as Stargate, Cassandra, and other modules.
Check for any latest FATALs for the service that is down. The following command prints all the FATALs for a CVM. Run this command on all CVMs.
nutanix@cvm$ for i in `svmips`; do echo "CVM: $i"; ssh $i "ls -ltr /home/nutanix/data/logs/*.FATAL"; done NCC Health Check: cluster_services_down_check (nutanix.com) Part2 Vlad Drac2023-06-05T13:22:00.86I'll update this one with a smaller, if possible, command Update the default password for the root user on the node to match the admin user password echo -e "CHANGING ALL AHV HOST ROOT PASSWORDS.\nPlease input new password: "; read -rs password1; echo "Confirm new password: "; read -rs password2; if [ "$password1" == "$password2" ]; then for host in $(hostips); do echo Host $host; echo $password1 | ssh root@$host "passwd --stdin root"; done; else echo "The passwords do not match"; fi Update the default password for the nutanix user on the CVM sudo passwd nutanix Output the cluster-wide configuration of the SCMA policy ncli cluster get-hypervisor-security-config Output Example:
nutanix@NTNX-372a19a3-A-CVM:10.35.150.184:~$ ncli cluster get-hypervisor-security-config Enable Aide : false Enable Core : false Enable High Strength P... : false Enable Banner : false Schedule : DAILY Enable iTLB Multihit M... : false Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
ncli cluster edit-hypervisor-security-params enable-aide=true
ncli cluster edit-hypervisor-security-params schedule=weekly
Enable high-strength password policies for the cluster.
ncli cluster edit-hypervisor-security-params enable-high-strength-password=true Ensure CVMs require SSH keys for login instead of passwords
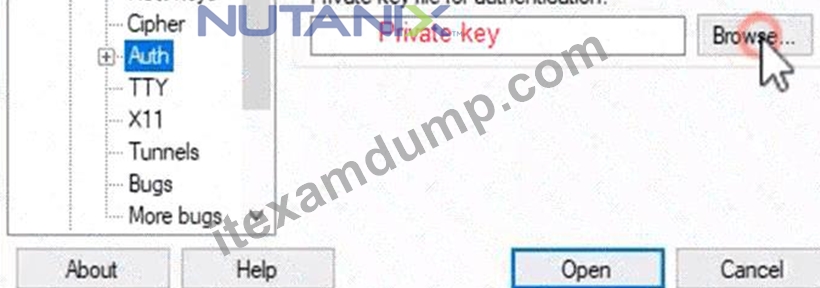
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA0600000008gb3CAA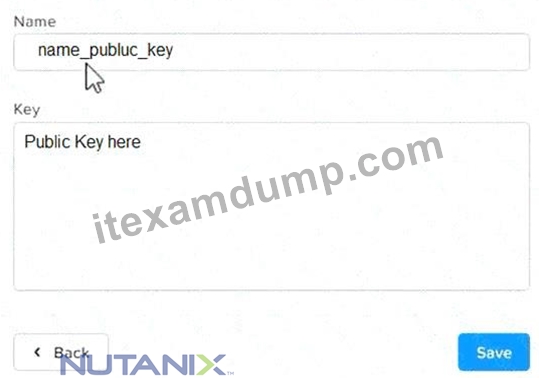
질문 # 21
......
Itexamdump는 아주 믿을만하고 서비스 또한 만족스러운 사이트입니다. 만약 NCM-MCI-6.10시험실패 시 우리는 100% 덤프비용 전액환불 해드립니다.그리고 시험을 패스하여도 우리는 일 년 동안 무료업뎃을 제공합니다.
NCM-MCI-6.10덤프데모문제 다운: https://www.itexamdump.com/NCM-MCI-6.10.html
참고: Itexamdump에서 Google Drive로 공유하는 무료, 최신 NCM-MCI-6.10 시험 문제집이 있습니다: https://drive.google.com/open?id=1L41imOb3JBcPsjzncXZIglnL4qf7_seO