Now we can say that Developing AI Cloud Solutions on Azure (AI-200) exam questions are real and top-notch Microsoft AI-200 exam questions that you can expect in the upcoming Developing AI Cloud Solutions on Azure (AI-200) exam. In this way, you can easily pass the AI-200 exam with good scores. The countless AI-200 Exam candidates have passed their dream AI-200 certification exam and they all got help from real, valid, and updated AI-200 practice questions, You can also trust on Exams-boost and start preparation with confidence.
| Section | Objectives |
|---|---|
| Topic 1: Plan and manage Azure AI solutions | - Plan security and compliance requirements - Monitor and optimize AI solutions - Select appropriate Azure AI services |
| Topic 2: Implement Azure AI solutions | - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI - Implement knowledge mining with Azure AI Search - Implement computer vision solutions |
| Topic 3: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
>> AI-200 Valid Practice Questions <<
There is a high demand for Developing AI Cloud Solutions on Azure certification, therefore there is an increase in the number of Microsoft AI-200 exam candidates. Many resources are available on the internet to prepare for the Developing AI Cloud Solutions on Azure exam. Exams-boost is one of the best certification exam preparation material providers where you can find newly released Microsoft AI-200 Dumps for your exam preparation.
NEW QUESTION # 132
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
Answer: C
Explanation:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
NEW QUESTION # 133
Drag and Drop Question
You have an existing AKS cluster and a container image stored in Azure Container Registry.
You must deploy a new version without interrupting traffic.
You need to perform a rolling update by using a manifest file.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.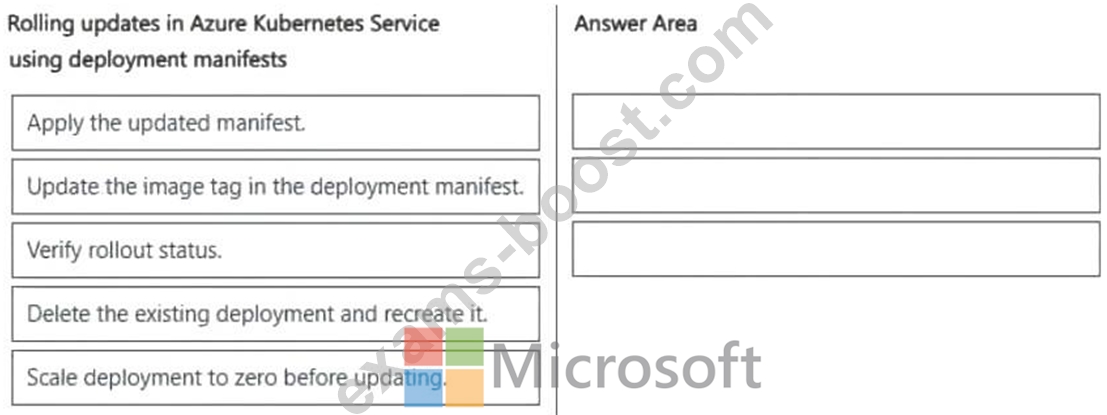
Answer:
Explanation: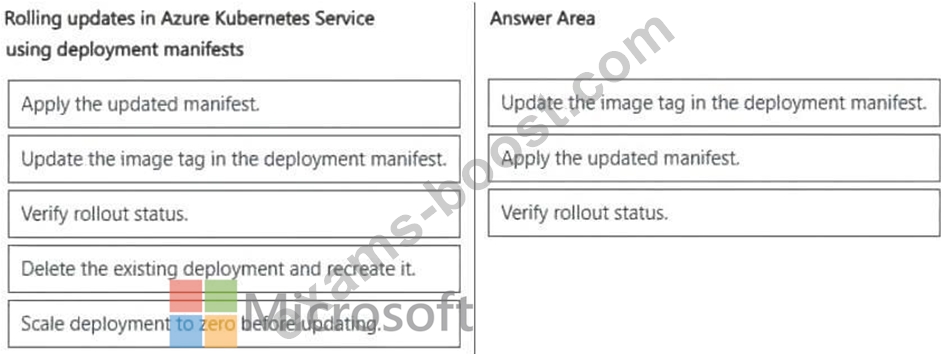
Explanation:
Step 1: Update the image tag in the deployment manifest
This changes the definition file to point to your new version image stored in the Azure Container Registry.
Step 2: Apply the updated manifest
Running kubectl apply -f <manifest.yaml> triggers Kubernetes to natively initiate a zero-downtime rolling update strategy, incrementally replacing old pods with new ones.
Step 3: Verify rollout status
Running kubectl rollout status deployment/<deployment-name> allows you to track and ensure the new version deploys successfully without failure.
Reference:
https://learn.microsoft.com/en-us/azure/aks/tutorial-kubernetes-deploy-application
NEW QUESTION # 134
Drag and Drop Question
You are developing several microservices to run on Azure Container Apps.
The microservices must allow HTTPS access by using a custom domain.
You need to configure the custom domain in Azure Container Apps.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.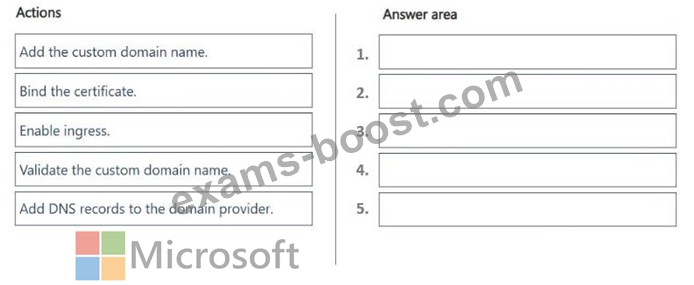
Answer:
Explanation: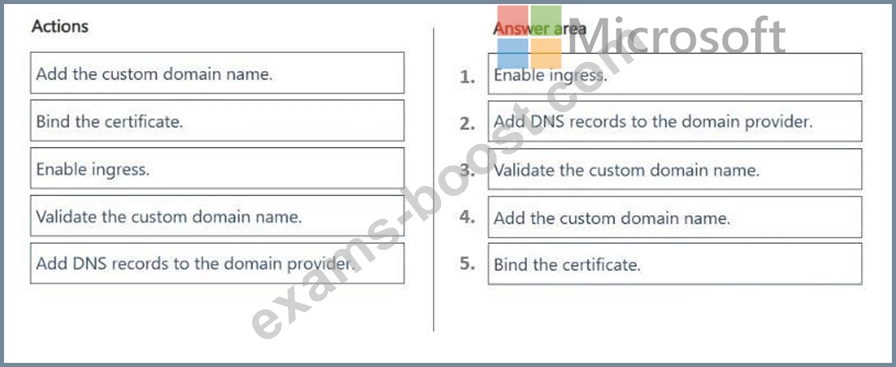
Explanation:
Step 1: Enable ingress
You must first expose your container app to external traffic to generate the default fully qualified domain name (FQDN) needed for DNS mapping.
Step 2: Add DNS records to the domain provider
Log into your domain registrar to create the required TXT (for verification) and CNAME/A records pointing to your container app.
Step 3: Validate the custom domain name
Azure checks your DNS records to confirm that you actually own the domain before allowing it to be linked.
Step 4: Add the custom domain name
Once validation passes, you officially add and register the custom domain name within the Azure Container App configuration.
Step 5: Bind the certificate
Finally, bind an SSL/TLS certificate to the custom domain to secure the connection and enable HTTPS access.
Reference:
https://learn.microsoft.com/en-us/azure/container-apps/ingress-overview
NEW QUESTION # 135
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.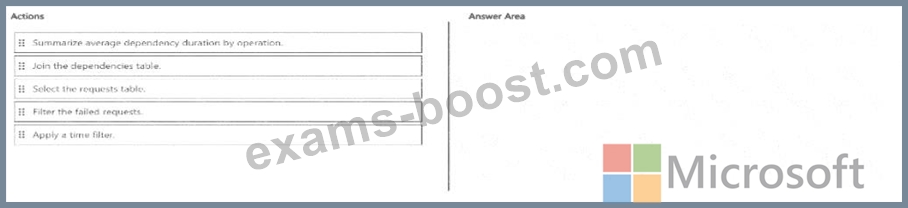
Answer:
Explanation: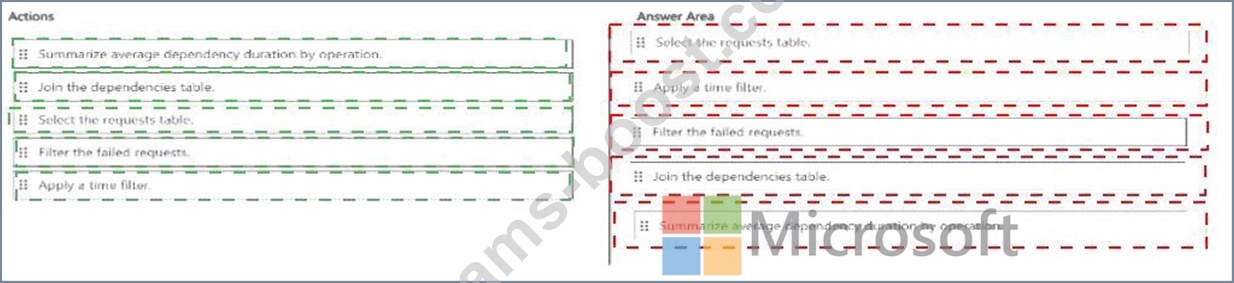
Explanation: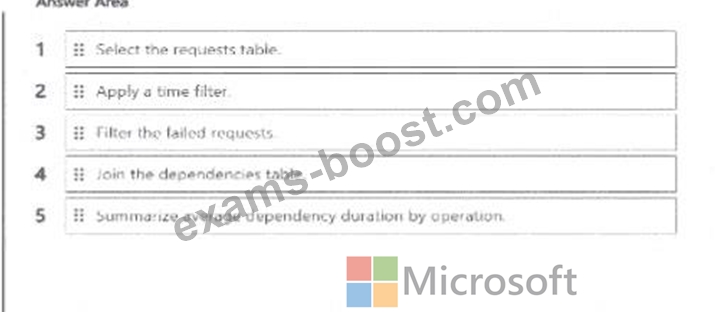
Verified Answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 136
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: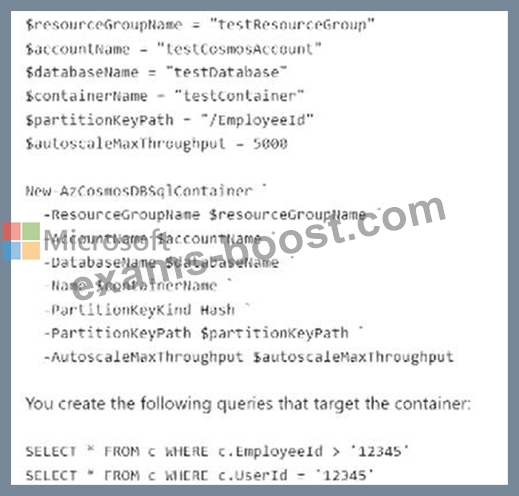
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.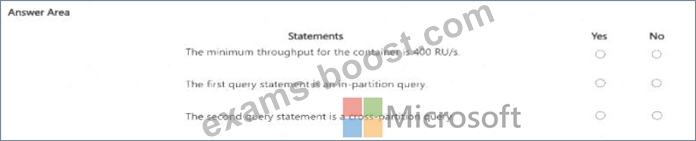
Answer:
Explanation: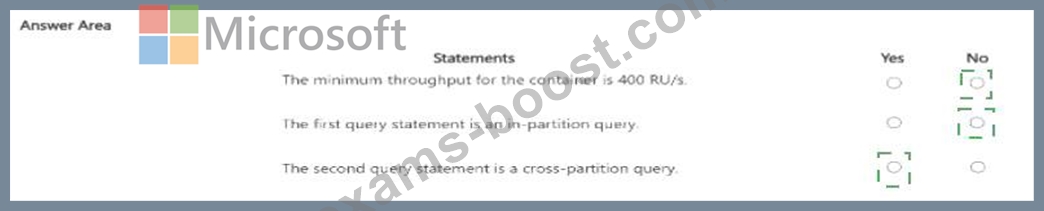
Explanation: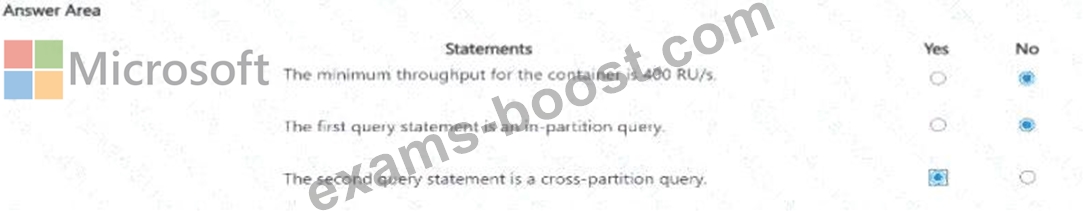
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
NEW QUESTION # 137
......
Our AI-200 exam questions can assure you that you will pass the AI-200 exam as well as getting the related certification under the guidance of our AI-200 study materials as easy as pie. Firstly, the pass rate among our customers has reached as high as 98% to 100%, which marks the highest pass rate in the field. Secondly, you can get our AI-200 Practice Test only in 5 to 10 minutes after payment, which enables you to devote yourself to study as soon as possible.
AI-200 Study Guide: https://www.exams-boost.com/AI-200-valid-materials.html