素晴らしいCertified-Data-Engineer-Professional必殺問題集一回合格-実用的なCertified-Data-Engineer-Professional合格受験記

それでも、インターネットでプロのCertified-Data-Engineer-Professionalテストガイドを購入することについて心配しすぎている場合、それは非常に正常なことです。 有用な認定Certified-Data-Engineer-Professionalガイド資料は、半分の作業で2つの結果が得られるよう準備するのに役立ちます。 Certified-Data-Engineer-Professional試験の品質について検討する場合は、Certified-Data-Engineer-Professional試験問題のデモを無料でダウンロードできます。 Certified-Data-Engineer-Professionalスタディガイドで、お客様のニーズと疑問を慎重に考えました。 当社の認定Certified-Data-Engineer-Professionalガイド資料は、このラインで10年以上働いた経験のある専門家によって収集および編集されています。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Develop unit and integration tests for data processing code
- 3. Compare streaming tables and materialized views
- 4. Use control flow operators in pipeline components
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
>> Certified-Data-Engineer-Professional必殺問題集 <<
Certified-Data-Engineer-Professional合格受験記、Certified-Data-Engineer-Professional日本語講座
弊社のCertified-Data-Engineer-Professional問題集は大好評を博しました。専門家たちの整理と分析を通して、問題集の質量はよくなりました。だから、お客様は我々のCertified-Data-Engineer-Professional問題集を安心で利用することができます。弊社の商品の質量に疑問がありましたら、我々のサイトで無料のCertified-Data-Engineer-Professionalデモをダウンロードして見ることができます。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q180-Q185):
質問 # 180
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
- A. "Can Restart" privileges on the required cluster
- B. Cluster creation allowed. "Can Restart" privileges on the required cluster
- C. Workspace Admin privileges, cluster creation allowed. "Can Attach To" privileges on the required cluster
- D. "Can Manage" privileges on the required cluster
- E. Cluster creation allowed. "Can Attach To" privileges on the required cluster
正解:A
解説:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
質問 # 181
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
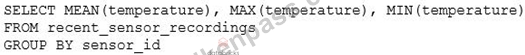
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
- A. The recent_sensor_recordingstable was unresponsive for three consecutive runs of the query
- B. The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query
- C. The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query
- D. The total average temperature across all sensors exceeded 120 on three consecutive executions of the query
- E. The source query failed to update properly for three consecutive minutes and then restarted
正解:C
解説:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120.
質問 # 182
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- B. Instruct the marketing team to download results as a CSV and email them to the sales organization.
- C. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- D. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- E. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
正解:A
解説:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
質問 # 183
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
- A. Ingest both batch and streaming data using Lakeflow Declarative Pipelines, and apply masking via Unity Catalog column masks at read time to avoid modifying the data during ingestion.
- B. Load batch data with notebooks and ingest streaming data with SQL Warehouses; use Unity Catalog column masks on Silver tables to redact fields after storage.
- C. Use Lakeflow Declarative Pipelines for batch and streaming ingestion, define a PII masking function, and apply it during Bronze ingestion before writing to Delta Lake.
- D. Allow PII to be stored unmasked in Bronze for lineage tracking, then apply masking logic in Gold tables used for reporting.
正解:C
解説:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
質問 # 184
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM, 160 total cores and only one Executor per VM.
Given a job with at least one wide transformation, which of the following cluster configurations will result in maximum performance?
- A. Total VMs: 2
200 GB per Executor
80 Cores / Executor - B. Total VMs: 4
100 GB per Executor
40 Cores/Executor - C. Total VMs: 1
400 GB per Executor
160 Cores / Executor - D. Total VMs: 8
50 GB per Executor
20 Cores / Executor
正解:C
解説:
https://docs.databricks.com/en/clusters/cluster-config-best-practices.html
質問 # 185
......
すべての人が当社ShikenPASSのCertified-Data-Engineer-Professional学習教材を使用することは非常に便利です。私たちの学習教材は、多くの人々が私たちの製品を購入した場合、多くの問題を解決するのに役立ちます。当社のCertified-Data-Engineer-Professional学習教材のオンライン版は機器に限定されません。つまり、学習教材を電話、コンピューターなどを含むすべての電子機器に適用できます。そのため、当社のオンライン版Certified-Data-Engineer-Professional学習教材は、試験の準備に非常に役立ちます。私たちは、Certified-Data-Engineer-Professional学習教材が良い選択になると信じています。
Certified-Data-Engineer-Professional合格受験記: https://www.shikenpass.com/Certified-Data-Engineer-Professional-shiken.html
- 一番優秀なCertified-Data-Engineer-Professional必殺問題集 - 合格スムーズCertified-Data-Engineer-Professional合格受験記 | 有効的なCertified-Data-Engineer-Professional日本語講座 Databricks Certified Data Engineer Professional ✡ ➽ www.xhs1991.com 🢪から簡単に✔ Certified-Data-Engineer-Professional ️✔️を無料でダウンロードできますCertified-Data-Engineer-Professional無料ダウンロード
- Certified-Data-Engineer-Professional最新資料 🔙 Certified-Data-Engineer-Professional勉強資料 ☮ Certified-Data-Engineer-Professional関連資格知識 😿 最新➥ Certified-Data-Engineer-Professional 🡄問題集ファイルは{ www.goshiken.com }にて検索Certified-Data-Engineer-Professional無料ダウンロード
- 一番優秀なCertified-Data-Engineer-Professional必殺問題集 - 合格スムーズCertified-Data-Engineer-Professional合格受験記 | 高品質なCertified-Data-Engineer-Professional日本語講座 Databricks Certified Data Engineer Professional 🕊 ➡ jp.fast2test.com ️⬅️を入力して[ Certified-Data-Engineer-Professional ]を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professionalウェブトレーニング
- Certified-Data-Engineer-Professional関連復習問題集 🍃 Certified-Data-Engineer-Professional合格記 🕣 Certified-Data-Engineer-Professional復習対策書 🕡 ➡ Certified-Data-Engineer-Professional ️⬅️を無料でダウンロード《 www.goshiken.com 》ウェブサイトを入力するだけCertified-Data-Engineer-Professional受験対策書
- 試験の準備方法-最新のCertified-Data-Engineer-Professional必殺問題集試験-認定するCertified-Data-Engineer-Professional合格受験記 💮 時間限定無料で使える⇛ Certified-Data-Engineer-Professional ⇚の試験問題は⏩ www.xhs1991.com ⏪サイトで検索Certified-Data-Engineer-Professional関連復習問題集
- 試験の準備方法-信頼できるCertified-Data-Engineer-Professional必殺問題集試験-権威のあるCertified-Data-Engineer-Professional合格受験記 🧊 ➠ www.goshiken.com 🠰から《 Certified-Data-Engineer-Professional 》を検索して、試験資料を無料でダウンロードしてくださいCertified-Data-Engineer-Professional問題無料
- Certified-Data-Engineer-Professional最新問題 🌏 Certified-Data-Engineer-Professionalトレーリング学習 🚎 Certified-Data-Engineer-Professional資格取得 ☝ URL ➠ www.topexam.jp 🠰をコピーして開き、{ Certified-Data-Engineer-Professional }を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional受験対策書
- 一番優秀なCertified-Data-Engineer-Professional必殺問題集 - 合格スムーズCertified-Data-Engineer-Professional合格受験記 | 有効的なCertified-Data-Engineer-Professional日本語講座 Databricks Certified Data Engineer Professional 🕗 ウェブサイト▛ www.goshiken.com ▟を開き、( Certified-Data-Engineer-Professional )を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional最新問題
- 試験の準備方法-信頼できるCertified-Data-Engineer-Professional必殺問題集試験-権威のあるCertified-Data-Engineer-Professional合格受験記 📒 検索するだけで➤ www.passtest.jp ⮘から( Certified-Data-Engineer-Professional )を無料でダウンロードCertified-Data-Engineer-Professional最新資料
- 一生懸命にCertified-Data-Engineer-Professional必殺問題集 - 合格スムーズCertified-Data-Engineer-Professional合格受験記 | 素晴らしいCertified-Data-Engineer-Professional日本語講座 😉 { www.goshiken.com }サイトで【 Certified-Data-Engineer-Professional 】の最新問題が使えるCertified-Data-Engineer-Professionalウェブトレーニング
- Certified-Data-Engineer-Professional受験体験 🛣 Certified-Data-Engineer-Professional最新試験 🌠 Certified-Data-Engineer-Professional関連資格知識 🦟 最新⇛ Certified-Data-Engineer-Professional ⇚問題集ファイルは▷ www.xhs1991.com ◁にて検索Certified-Data-Engineer-Professional技術問題
- www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, amfettkesniya.blogspot.com, telegra.ph, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes