Users of this format don't need to install excessive plugins or software to attempt the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) web-based practice exams. Another format of the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice test is the desktop-based software. This Databricks-Certified-Professional-Data-Engineer Exam simulation software needs installation only on Windows computers to operate. The third format of the PracticeVCE Databricks Databricks-Certified-Professional-Data-Engineer exam dumps is the Databricks-Certified-Professional-Data-Engineer Dumps PDF.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Batch and incremental processing logic - Integration with Databricks APIs and tools |
| Topic 2: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Topic 3: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching - Cluster configuration and scaling |
| Topic 4: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 5: Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Auto Loader and streaming ingestion - Schema inference and evolution |
| Topic 6: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Topic 7: Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
| Topic 8: Data Modelling | 6% | - Medallion Architecture implementation - Schema design and management - Delta Lake table design |
| Topic 9: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Topic 10: Monitoring and Alerting | 10% | - Pipeline observability and logging - Performance and health monitoring - Setting up alerts and notifications |
>> Databricks-Certified-Professional-Data-Engineer Exam Preview <<
As the old saying goes, practice is the only standard to testify truth. In other word, it has been a matter of common sense that pass rate of the Databricks-Certified-Professional-Data-Engineer study materials is the most important standard to testify whether it is useful and effective for people to achieve their goal. We believe that you must have paid more attention to the pass rate of the Databricks-Certified-Professional-Data-Engineer study materials. If you focus on the study materials from our company, you will find that the pass rate of our products is higher than other study materials in the market, yes, we have a 99% pass rate, which means if you take our the Databricks-Certified-Professional-Data-Engineer Study Materials into consideration, it is very possible for you to pass your exam and get the related certification.
NEW QUESTION # 192
What is the purpose of the bronze layer in a Multi-hop architecture?
Answer: C
Explanation:
Explanation
The answer is Provides efficient storage and querying of full unprocessed history of data Medallion Architecture - Databricks Bronze Layer:
1.Raw copy of ingested data
2.Replaces traditional data lake
3.Provides efficient storage and querying of full, unprocessed history of data
4.No schema is applied at this layer
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.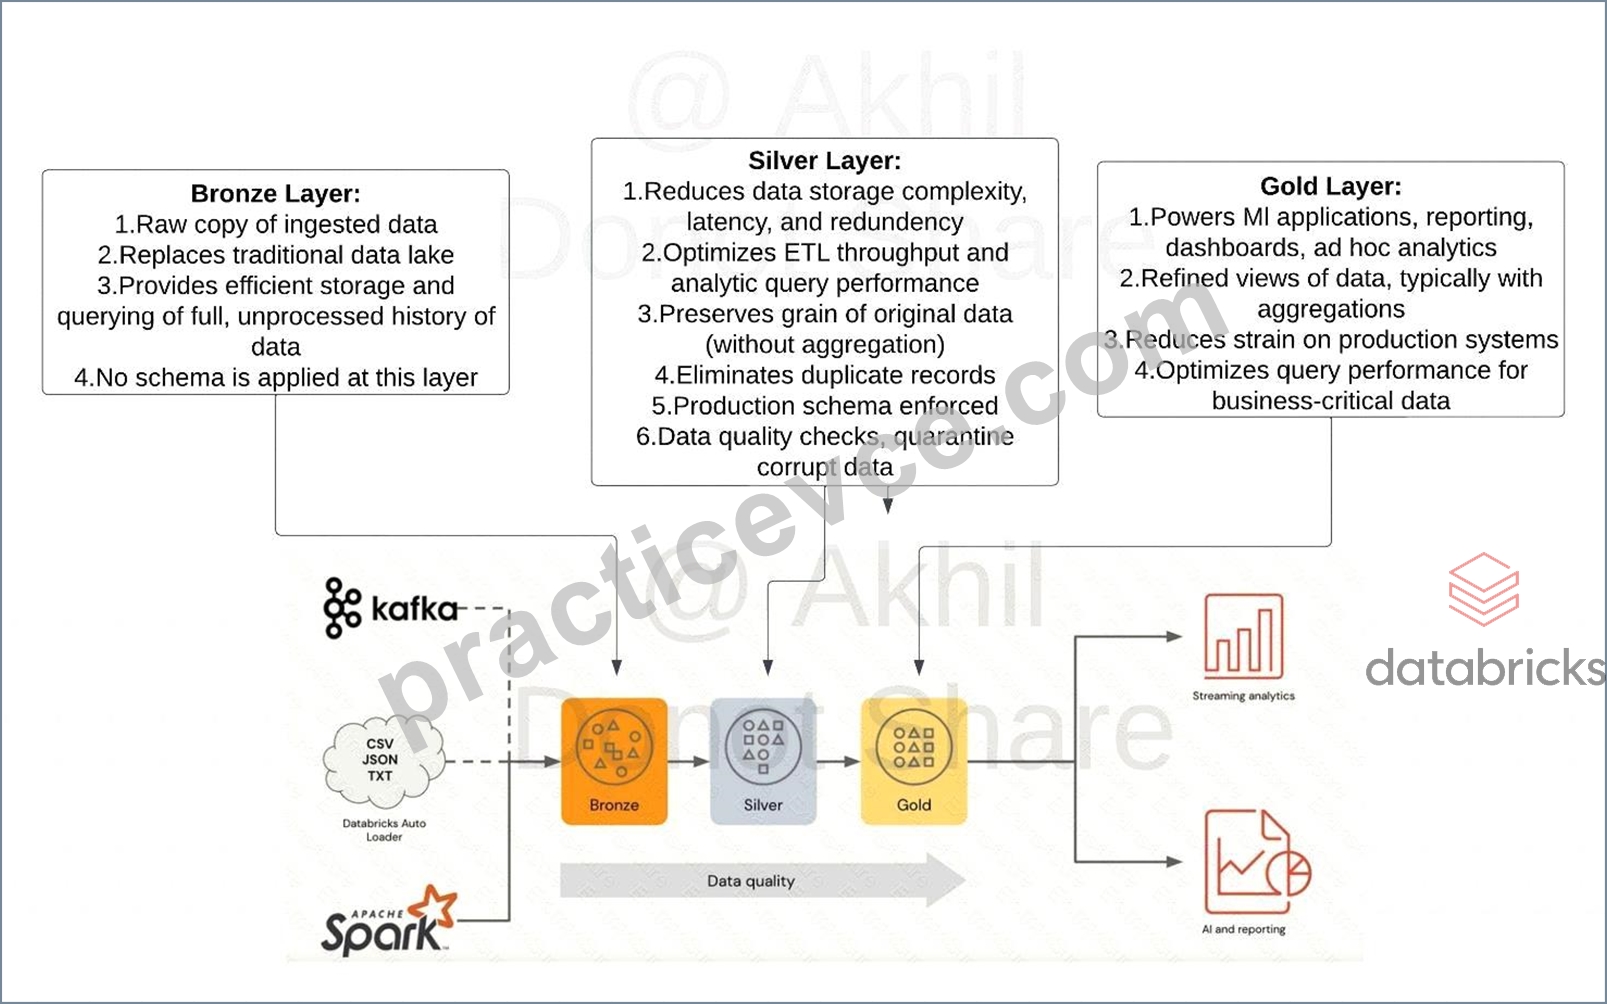
NEW QUESTION # 193
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table namedusers.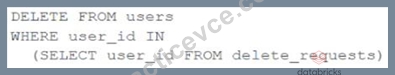
Assuming thatuser_idis a unique identifying key and that contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: A
Explanation:
Explanation
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion.
The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 194
A junior data engineer is migrating a workload from a relational database system to the Databricks Lakehouse. The source system uses a star schema, leveraging foreign key constrains and multi-table inserts to validate records on write.
Which consideration will impact the decisions made by the engineer while migrating this workload?
Answer: B
Explanation:
In Databricks and Delta Lake, transactions are indeed ACID-compliant, but this compliance is limited to single table transactions. Delta Lake does not inherently enforce foreign key constraints, which are a staple in relational database systems for maintaining referential integrity between tables. This means that when migrating workloads from a relational database system to Databricks Lakehouse, engineers need to reconsider how to maintain data integrity and relationships that were previously enforced by foreign key constraints.
Unlike traditional relational databases where foreign key constraints help in maintaining the consistency across tables, in Databricks Lakehouse, the data engineer has to manage data consistency and integrity at the application level or through careful design of ETL processes.
:
Databricks Documentation on Delta Lake: Delta Lake Guide
Databricks Documentation on ACID Transactions in Delta Lake: ACID Transactions in Delta Lake
NEW QUESTION # 195
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops." The watermark of 2 hours bounds the deduplication state. Duplicate orders within the 2-hour window are removed; duplicates arriving later than 2 hours behind the corresponding first event are considered late and are ignored, so they won't appear, but any orders that themselves arrive later than the watermark will be dropped and thus be missing.
Reference:
NEW QUESTION # 196
The data engineering team maintains the following code: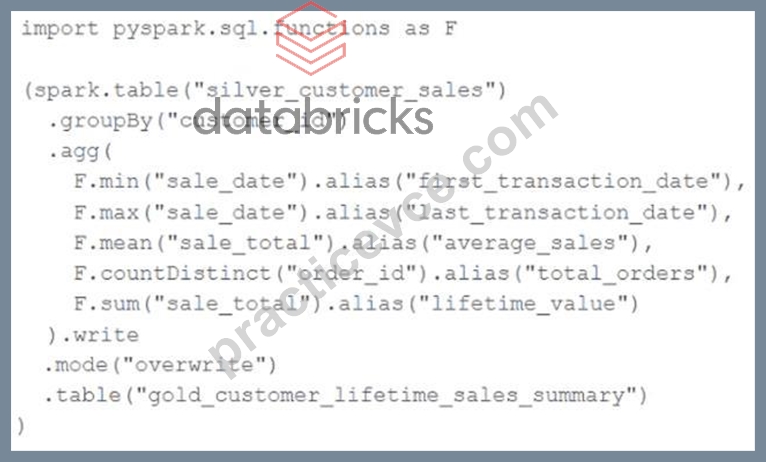
Assuming that this code produces logically correct results and the data in the source table has been de- duplicated and validated, which statement describes what will occur when this code is executed?
Answer: B
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References :
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 197
......
We pursue the best in the field of Databricks-Certified-Professional-Data-Engineer exam dumps. Databricks-Certified-Professional-Data-Engineer dumps and answers from our PracticeVCE site are all created by the IT talents with more than 10-year experience in IT certification. PracticeVCE will guarantee that you will get Databricks-Certified-Professional-Data-Engineer Certification certificate easier than others.
Dumps Databricks-Certified-Professional-Data-Engineer Vce: https://www.practicevce.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html