DOWNLOAD the newest Actual4Labs DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1KeVgixv5ytGRnnKuKVql_IopGDSebTi-
In addition to the free download of sample questions, we are also confident that candidates who use DP-100 study materials will pass the exam at one go. DP-100 study materials are revised and updated according to the latest changes in the syllabus and the latest developments in theory and practice. Regardless of your weak foundation or rich experience, DP-100 study materials can bring you unexpected results. In the past, our passing rate has remained at 99%-100%. This is the most important reason why most candidates choose DP-100 Study Materials. Failure to pass the exam will result in a full refund. But as long as you want to continue to take the DP-100 exam, we will not stop helping you until you win and pass the certification.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare a model for deployment | 20-25% | - Deploy machine learning models
|
| Topic 2: Design and prepare a machine learning solution | 20-25% | - Design an Azure Machine Learning workspace
|
| Topic 3: Explore data and train models | 35-40% | - Run experiments and train models
|
| Topic 4: Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
The memory needs clues, but also the effective information is connected to systematic study, in order to deepen the learner's impression, avoid the quick forgetting. Therefore, we can see that in the actual DP-100 exam questions, how the arrangement plays a crucial role in the teaching effect. The DP-100 Study Guide in order to allow the user to form a complete system of knowledge structure, the qualification DP-100 examination of test interpretation and supporting course practice organic reasonable arrangement together.
NEW QUESTION # 209
You are creating a machine learning model in Python. The provided dataset contains several numerical columns and one text column. The text column represents a product's category. The product category will always be one of the following:
Bikes
Cars
Vans
Boats
You are building a regression model using the scikit-learn Python package.
You need to transform the text data to be compatible with the scikit-learn Python package.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.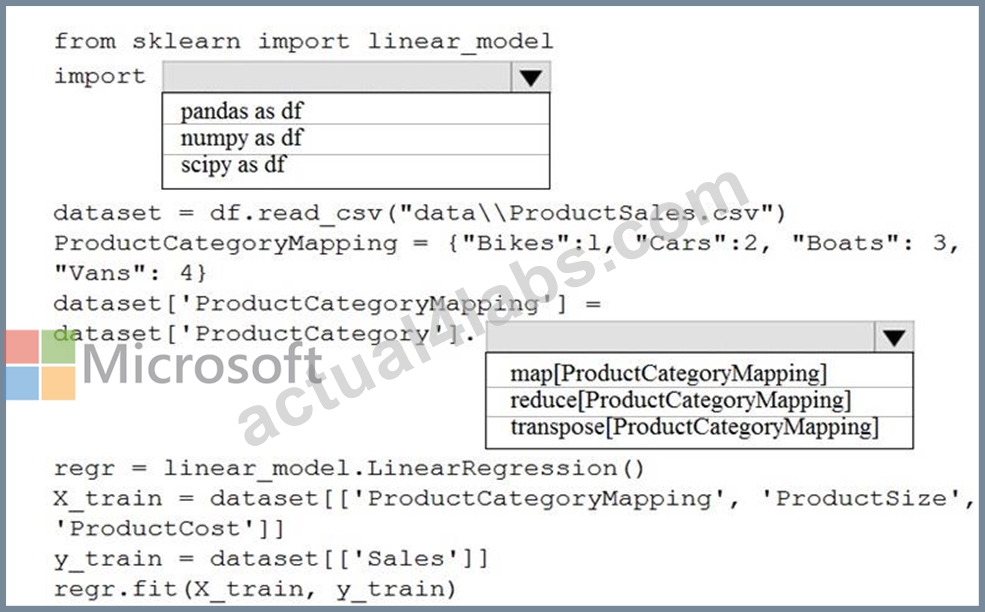
Answer:
Explanation: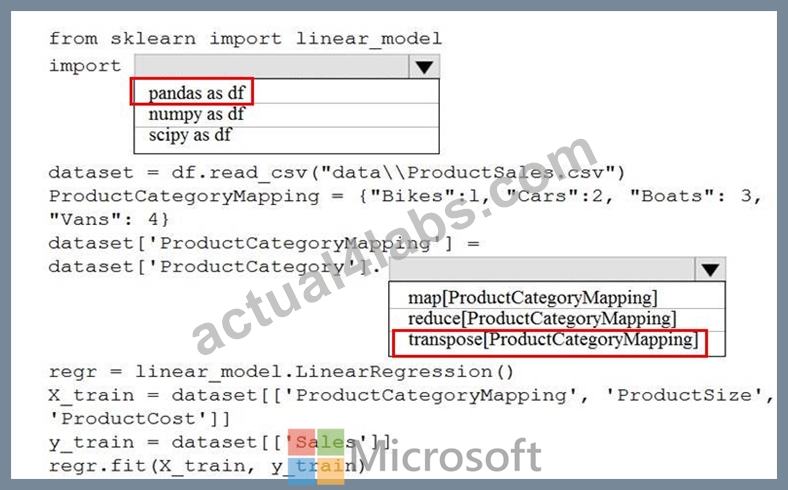
:
Reference:
https://datascienceplus.com/linear-regression-in-python/
NEW QUESTION # 210
You are building an intelligent solution using machine learning models.
The environment must support the following requirements:
Data scientists must build notebooks in a cloud environment
Data scientists must use automatic feature engineering and model building in machine learning pipelines.
Notebooks must be deployed to retrain using Spark instances with dynamic worker allocation.
Notebooks must be exportable to be version controlled locally.
You need to create the environment.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.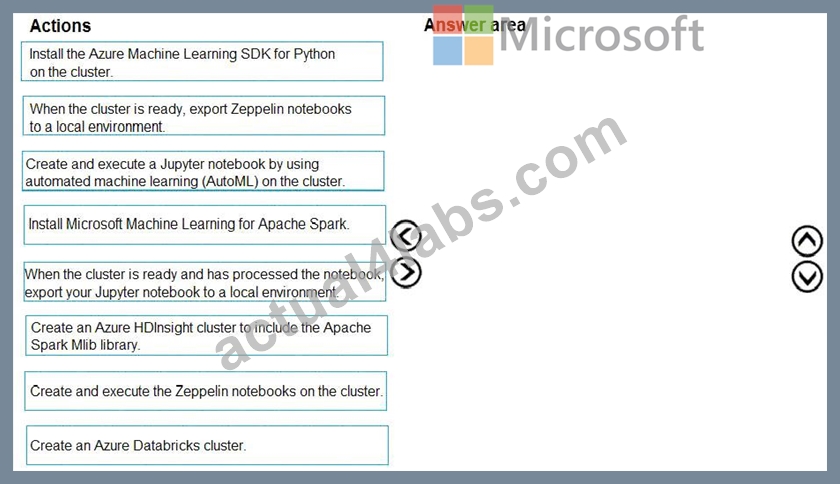
Answer:
Explanation: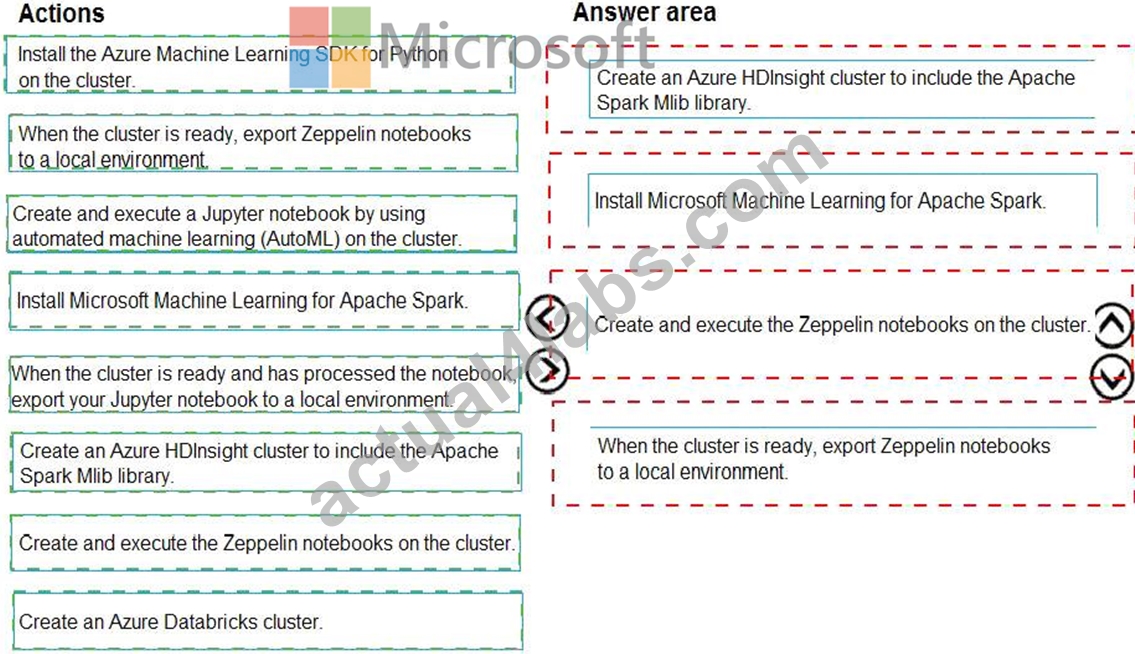
Explanation: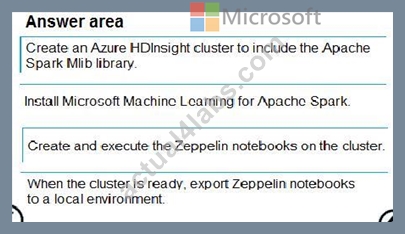
Step 1: Create an Azure HDInsight cluster to include the Apache Spark Mlib library Step 2: Install Microsot Machine Learning for Apache Spark You install AzureML on your Azure HDInsight cluster.
Microsoft Machine Learning for Apache Spark (MMLSpark) provides a number of deep learning and data science tools for Apache Spark, including seamless integration of Spark Machine Learning pipelines with Microsoft Cognitive Toolkit (CNTK) and OpenCV, enabling you to quickly create powerful, highly-scalable predictive and analytical models for large image and text datasets.
Step 3: Create and execute the Zeppelin notebooks on the cluster
Step 4: When the cluster is ready, export Zeppelin notebooks to a local environment.
Notebooks must be exportable to be version controlled locally.
References:
https://docs.microsoft.com/en-us/azure/hdinsight/spark/apache-spark-zeppelin-notebook
https://azuremlbuild.blob.core.windows.net/pysparkapi/intro.html
NEW QUESTION # 211
You monitor an Azure Machine Learning classification training experiment named train-classification on Azure Notebooks.
You must store a table named table as an artifact in Azure Machine Learning Studio during model training.
You need to collect and list the metrics by using MLfow.
how should you complete the code segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth on* point.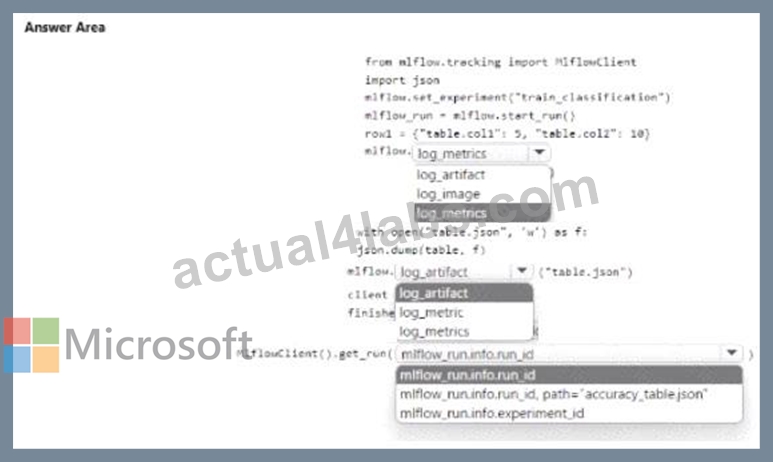
Answer:
Explanation: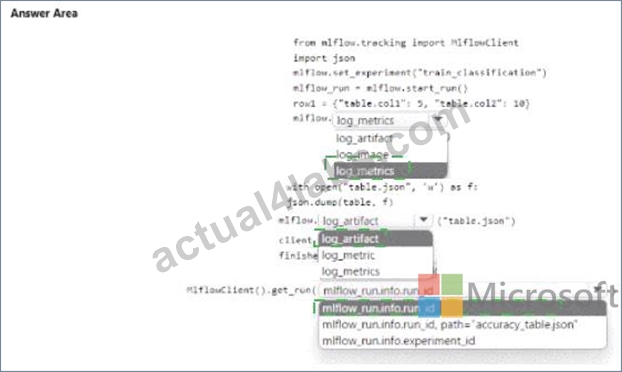
Explanation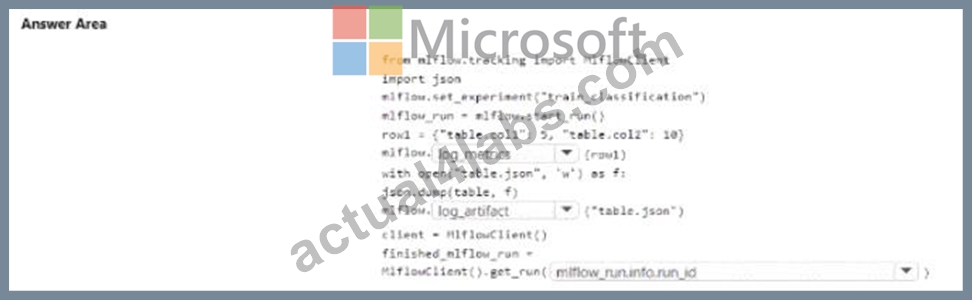
NEW QUESTION # 212
You need to implement a feature engineering strategy for the crowd sentiment local models.
What should you do?
Answer: B
Explanation:
The linear discriminant analysis method works only on continuous variables, not categorical or ordinal variables.
Linear discriminant analysis is similar to analysis of variance (ANOVA) in that it works by comparing the means of the variables.
Scenario:
Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
Experiments for local crowd sentiment models must combine local penalty detection data.
All shared features for local models are continuous variables.
Topic 2, Case Study 2
Case study
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns: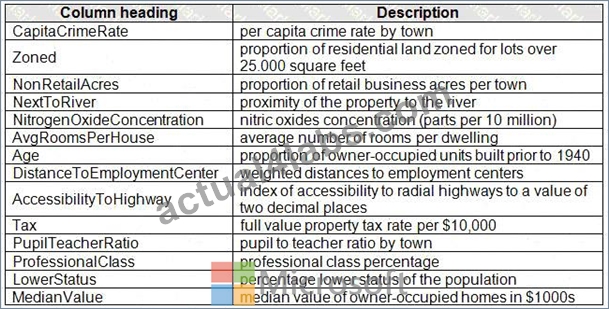
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
NEW QUESTION # 213
You create a binary classification model to predict whether a person has a disease.
You need to detect possible classification errors.
Which error type should you choose for each description? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.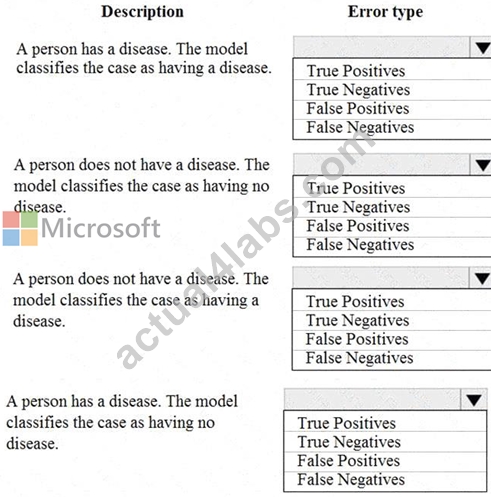
Answer:
Explanation: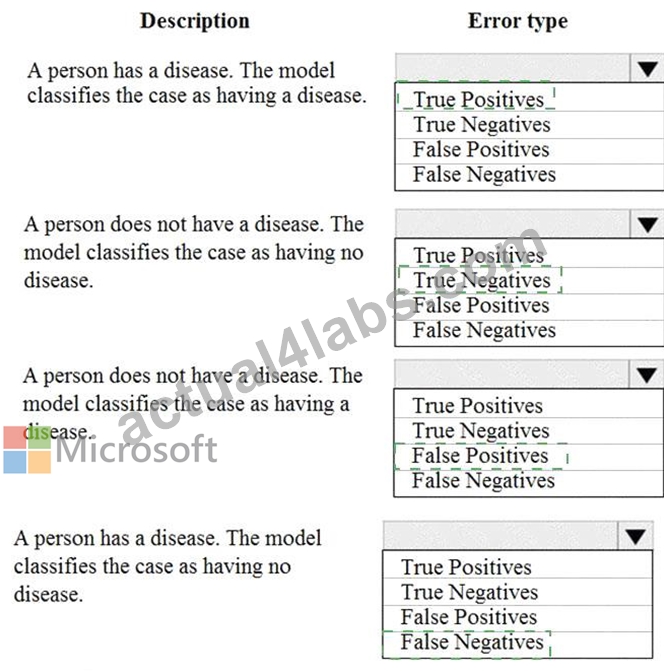
Explanation: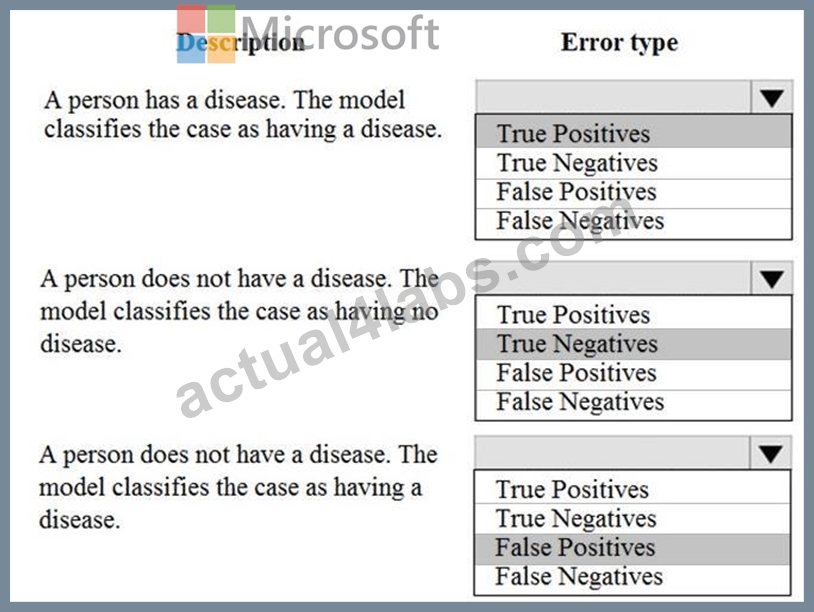
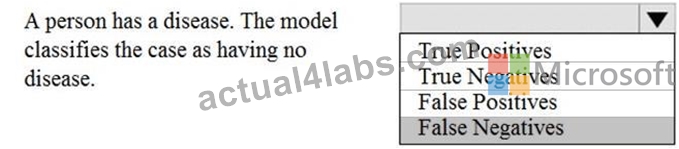
Box 1: True Positive
A true positive is an outcome where the model correctly predicts the positive class Box 2: True Negative A true negative is an outcome where the model correctly predicts the negative class.
Box 3: False Positive
A false positive is an outcome where the model incorrectly predicts the positive class.
Box 4: False Negative
A false negative is an outcome where the model incorrectly predicts the negative class.
Note: Let's make the following definitions:
"Wolf" is a positive class.
"No wolf" is a negative class.
We can summarize our "wolf-prediction" model using a 2x2 confusion matrix that depicts all four possible outcomes:
Reference:
https://developers.google.com/machine-learning/crash-course/classification/true-false-positive-negative
NEW QUESTION # 214
......
If you want to ace the Designing and Implementing a Data Science Solution on Azure (DP-100) test, the main problem you may face is not finding updated DP-100 practice questions to crack this test quickly. After examining the situation, the Actual4Labs has come with the idea to provide you with updated and actual Microsoft DP-100 Exam Dumps so you can Pass DP-100 Test on the first attempt. The product of Actual4Labs has many different premium features that help you use this product with ease. The study material has been made and updated after consulting with a lot of professionals and getting customers' reviews.
DP-100 Free Dump Download: https://www.actual4labs.com/Microsoft/DP-100-actual-exam-dumps.html
What's more, part of that Actual4Labs DP-100 dumps now are free: https://drive.google.com/open?id=1KeVgixv5ytGRnnKuKVql_IopGDSebTi-