DP-800学習教材を購入すると、DP-800テストにスムーズかつ簡単に合格します。プロの専門家チームを強化してDP-800トレーニング資料を熱心に編成および編集し、販売前後のサービス、24時間のオンラインカスタマーサービス、払い戻しサービスなどの素晴らしいサービスを提供します。 DP-800の実際のクイズでは、3つのバージョンとさまざまな機能が強化され、包括的かつ効率的に学習できます。学習教材の学習は時間と労力をほとんど必要とせず、頻繁に更新されます。質問:Developing AI-Enabled Database Solutionsの詳細については、次のように製品の紹介をご覧ください。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Exam Format: | Multiple choice, Case studies |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Available Languages: | English |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
当社Microsoftのソフトウェアバージョンには、実際のDP-800試験環境をシミュレートするという利点があります。 多くの受験者は、練習をするときにパフォーマンスが正しくなりすぎて緊張するため、CertShiken実際のDP-800試験に合格できません。 DP-800練習資料のこのソフトウェアバージョンは、心理的な恐怖を克服するのに役立ちます。 その上、練習を終えると得点が表示されるので、数回後には間違いなくどんどん良くなります。 DP-800試験の受験を完了したため、Developing AI-Enabled Database Solutions試験に合格する必要があります。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 70
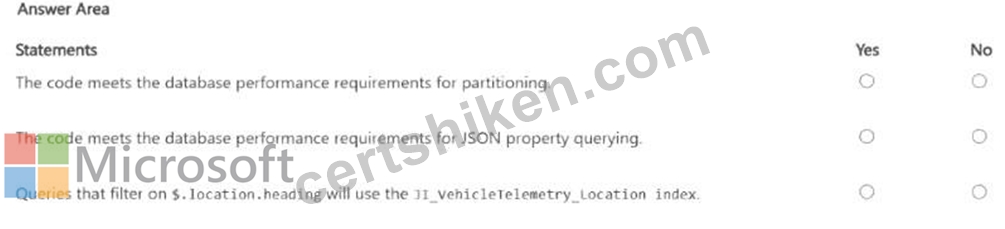
You need to create a table in the database to store the telemetry data. You have the following Transact-SQL code.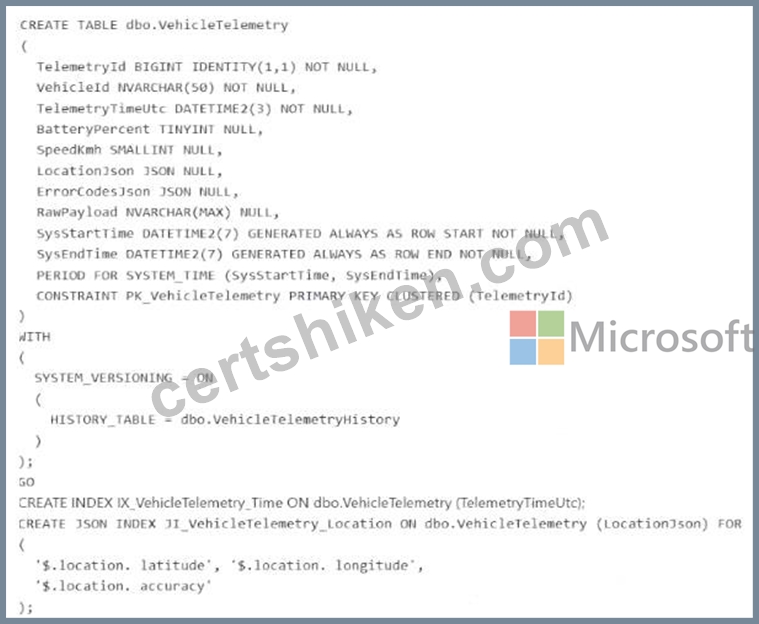
正解:
解説: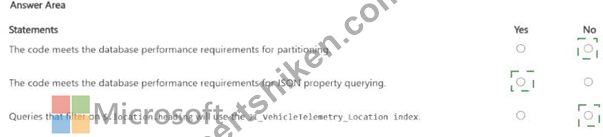
Explanation: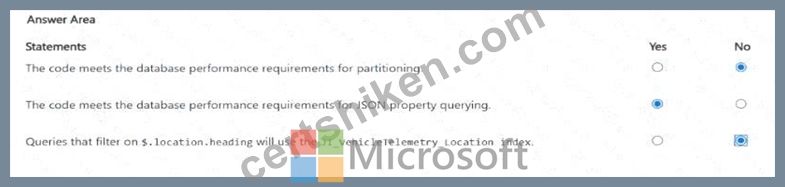
The first statement is No . The requirement says telemetry data must be stored in a partitioned table to provide predictable performance for ingestion and retention operations. However, the shown CREATE TABLE statement does not define a partition function or partition scheme, and the table is created with a regular clustered primary key on TelemetryId. Microsoft's partitioning guidance states that creating a partitioned table requires a partition function , a partition scheme , and creating the table or index on that partition scheme using a partitioning column. None of that appears in the code, so the table is not partitioned.
The second statement is Yes . The code creates a JSON index named JI_VehicleTelemetry_Location on LocationJson for these specific JSON paths: $.location.latitude, $.location.longitude, and $.location.accuracy.
That matches the requirement that those JSON properties must be filterable by using an index seek .
Microsoft documents that JSON indexing is used to optimize filtering and sorting on JSON properties, and the index only helps for the properties included in the index definition.
The third statement is No . The JSON index is defined only for latitude, longitude, and accuracy. A query filtering on $.location.heading references a different path that is not included in the index definition, so that query would not use JI_VehicleTelemetry_Location for that predicate. JSON indexes are path-specific; they do not automatically cover unrelated properties in the same JSON document.
質問 # 71
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.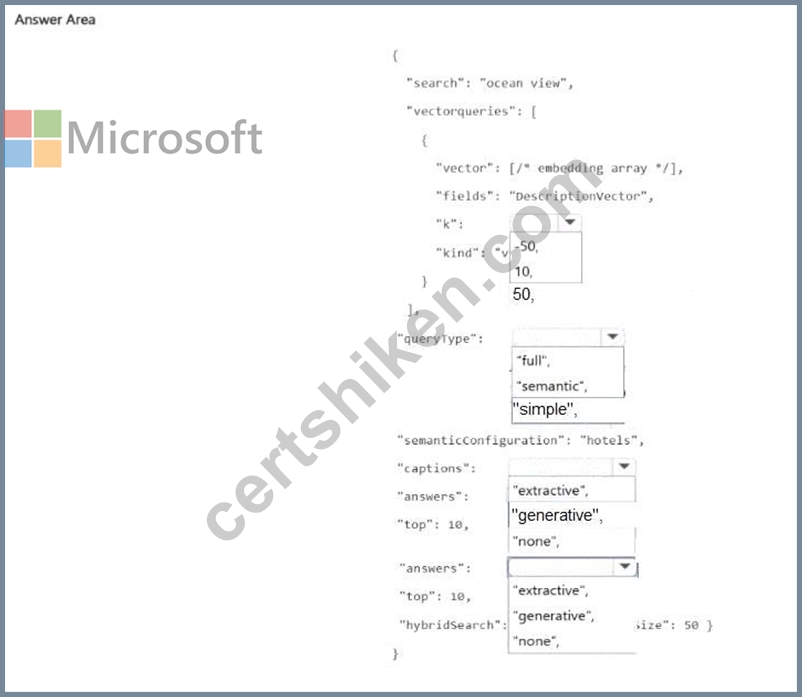
正解:
解説: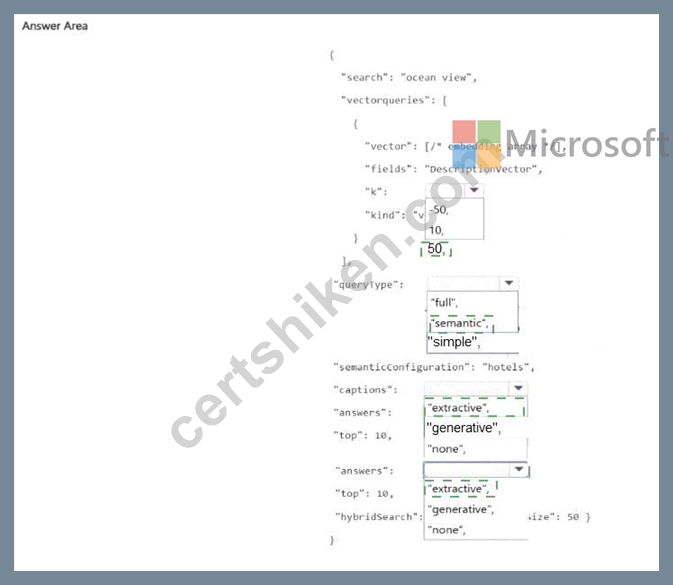
Explanation: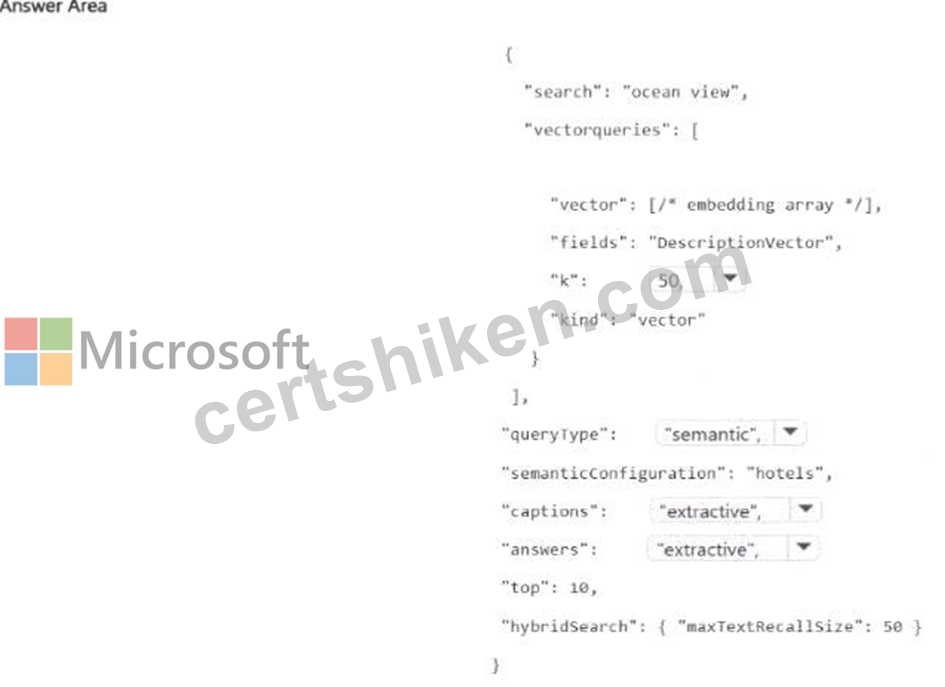
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
質問 # 72
You have an Azure SQL database that contains a table named Customer. Customer contains the following columns:
NationalIDNumber is unique per customer.
InvestigationNotes contains free-form text.
You have a stored procedure that performs point lookups by NationalIDNumber and returns InvestigationNotes in the query results without filtering on InvestigationNotes.
You need to encrypt both columns by using Always Encrypted and the highest security possible.
Which type of Always Encrypted encryption should you use for each column?
正解:A
質問 # 73
You have an Azure container app named app1-contoso-001 that hosts a Data API builder (DAB) container in front of an Azure SQL database.
You add an entity named Todo that uses a source named dbo.todos.
Which URL pattern should clients use to access the Todo REST endpoint?
正解:B
解説:
The correct answer is B because Data API builder exposes REST entities by default using the URL pattern:
https://{base_url}/api/{entity}
Microsoft's current DAB documentation states exactly that the default REST endpoint pattern is /api/{entity}
. For an entity named Todo , the REST route is therefore /api/Todo .
The other options are incorrect:
* A uses a GraphQL-style route and is not the REST endpoint.
* C uses /data-api/Todo , which is not the default REST path for a directly hosted DAB runtime.
* D adds an unnecessary /data-api prefix before /api/Todo .
Microsoft also shows examples such as:
GET https://localhost:5001/api/book
and documents collection reads as:
GET /api/{entity} .
So for the entity configuration:
* Entity name: Todo
* Source: dbo.todos
the REST endpoint path is:
/api/Todo
Therefore, among the supplied choices, Option B is the correct answer.
質問 # 74
Hotspot Question
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project. The repository contains the following GitHub Action workflow.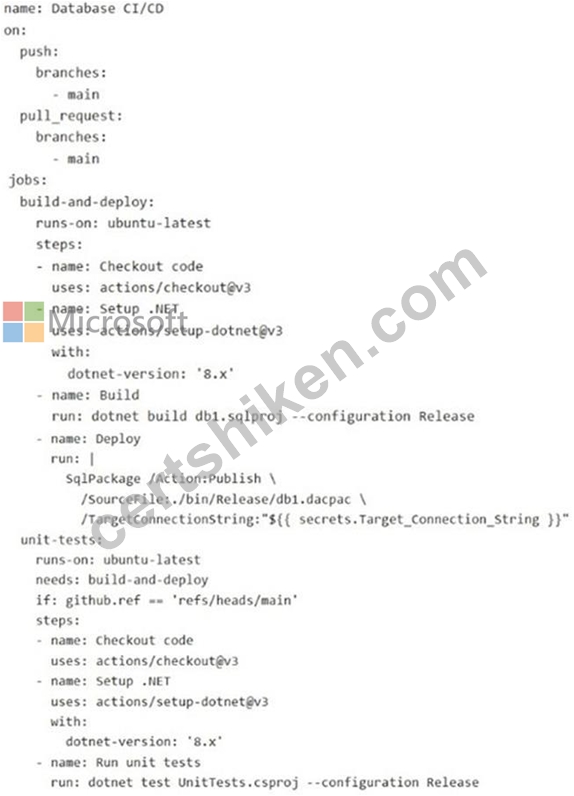
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.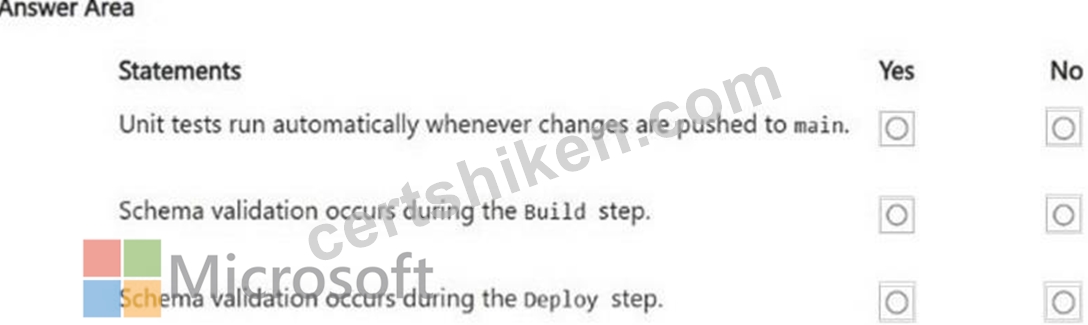
正解:
解説: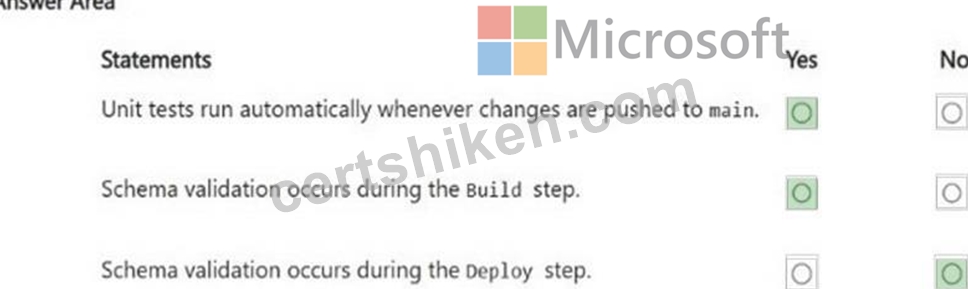
質問 # 75
......
DP-800日本語版テキスト内容: https://www.certshiken.com/DP-800-shiken.html