BTW, DOWNLOAD part of Pass4Test DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1laqNlGPmmQIPtGfd2dbDDwLBff4DUCBE
We strongly recommend using our DP-750 exam dumps to prepare for the Implementing Data Engineering Solutions Using Azure Databricks. It is the best way to ensure success. With our DP-750 practice questions, you can get the most out of your studying and maximize your chances of passing your DP-750 Exam. Pass4Test Implementing Data Engineering Solutions Using Azure Databricks is the answer if you want to score higher in the DP-750 exam and achieve your academic goals.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> Authorized DP-750 Exam Dumps <<
Pass4Test provides Microsoft DP-750 desktop-based practice software for you to test your knowledge and abilities. The DP-750 desktop-based practice software has an easy-to-use interface. You will become accustomed to and familiar with the free demo for Microsoft DP-750 Exam Questions. Exam self-evaluation techniques in our DP-750 desktop-based software include randomized questions and timed tests. These tools assist you in assessing your ability and identifying areas for improvement to pass the Microsoft certification exam.
NEW QUESTION # 67
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso ' s planned changes explicitly call for ' a clear execution order and dependencies ' and ' orchestrate multi-step ingestion and transformation workflows. ' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task ' s status independently, so if cleansing fails, ingestion doesn ' t re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn
' t address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
NEW QUESTION # 68
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
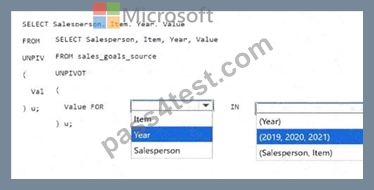
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Answer:
Explanation: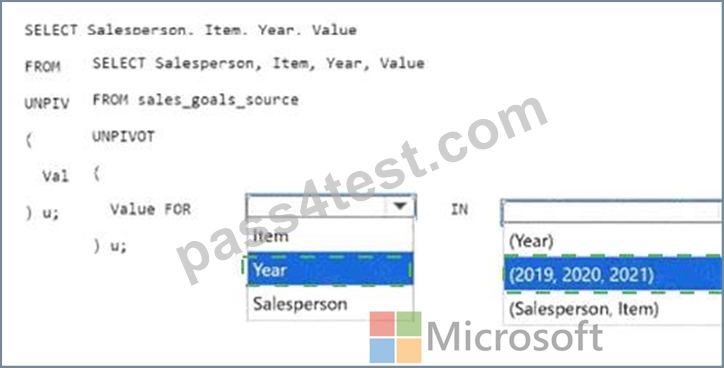
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
NEW QUESTION # 69
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have 500 GB of sales data stored as multiple CSV files in cloud storage.
You plan to load the data into a Delta table.
You need to ingest the bulk data by using a solution that meets the following requirements:
* Minimize how long it takes to implement the solution.
* Minimize the amount of custom code required.
What should you use?
Answer: B
Explanation:
COPY INTO provides a concise SQL-based mechanism for loading files from cloud storage directly into a Delta table. It requires substantially less custom code than constructing a Spark ingestion application and is suitable for a straightforward bulk load of multiple CSV files. COPY INTO is also retryable and idempotent:
it tracks files already loaded into the target table and skips them during later executions, helping prevent accidental duplication. Auto Loader is optimized primarily for incremental and continuously arriving files and normally requires a streaming or triggered pipeline. Apache Spark read APIs require additional code for reading, transforming, tracking, and writing the files. Manually uploading 500 GB would be inefficient and operationally unsuitable. Therefore, COPY INTO best satisfies both implementation-speed and minimal-code requirements. Microsoft Learn
NEW QUESTION # 70
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: D
Explanation:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
NEW QUESTION # 71
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.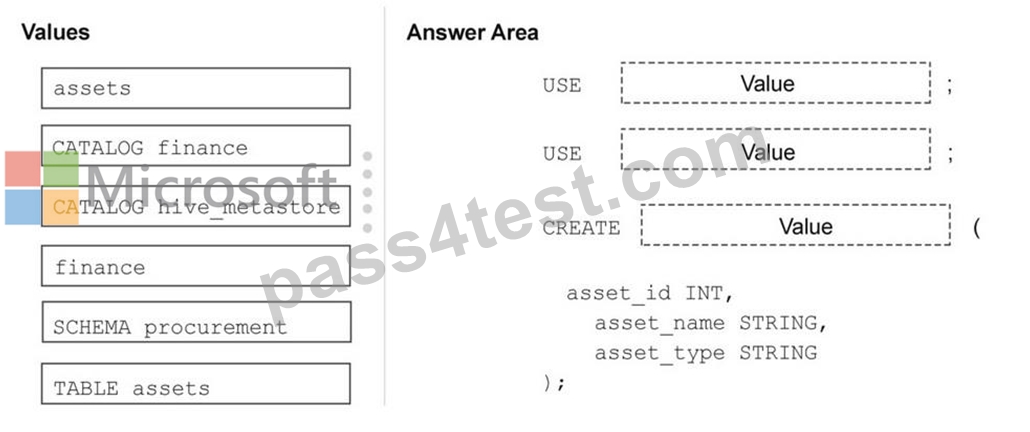
Answer:
Explanation: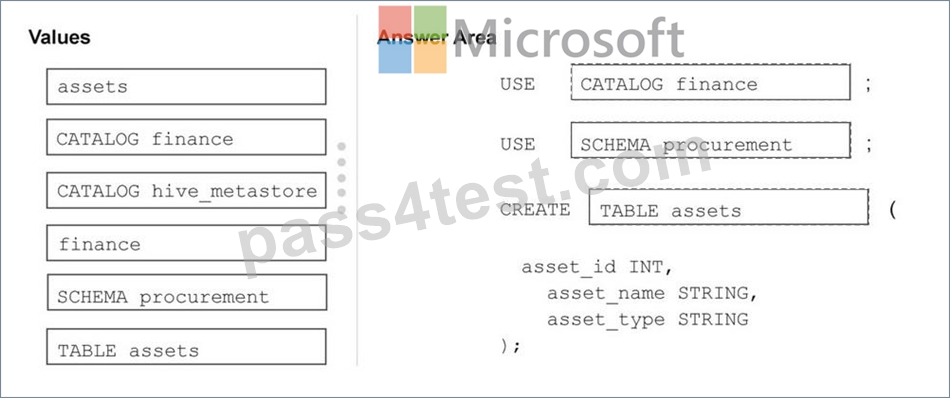
NEW QUESTION # 72
......
With passing rate more than 98 percent from exam candidates who chose our Microsoft DP-750 Study Guide, we have full confidence that your DP-750 actual test will be a piece of cake by them. Our Implementing Data Engineering Solutions Using Azure Databricks exam questions provide with the software which has a variety of self-study and self-assessment functions to detect learning results.
DP-750 Exam Blueprint: https://www.pass4test.com/DP-750.html
What's more, part of that Pass4Test DP-750 dumps now are free: https://drive.google.com/open?id=1laqNlGPmmQIPtGfd2dbDDwLBff4DUCBE