Because there are free trial services provided by our AI-200 preparation materials, by the free trial services you can get close contact with our products, learn about our AI-200 real test, and know how to choice the different versions before you buy our products. On the other hand, using free trial downloading before purchasing, I can promise that you will have a good command of the function of our AI-200 Test Prep. According to free trial downloading, you will know which version is more suitable for you.
| Section | Weight | Objectives |
|---|---|---|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
>> Valid Braindumps AI-200 Book <<
There are many businesses in the market who boast about the high quality of their test materials. However, we can pat on the chest confidently to say that the passing rate of students who use our AI-200 test torrent is between 98% and 99%. If you unfortunately fail to pass the AI-200 exam, upload your exam certificate and screenshots of the failed scores, and we will immediately give a full refund. Using our AI-200 Test Questions will not bring you any loss. In addition, the refund process is very simple and will not bring you any trouble. If you have any questions, you can always contact us online or email us. We will reply as soon as possible.
NEW QUESTION # 104
An AI application retrieves configuration values from App Configuration. The application uses static configuration.
You need to implement a solution that supports dynamic configuration updates and minimizes latency for application requests.
What should you do?
Answer: A
Explanation:
Use the Azure App Configuration provider ' s caching and dynamic refresh mechanism with a configured refresh interval . The application loads configuration into a local cache and periodically checks App Configuration for changes. When a registered key changes, the provider refreshes the cached configuration without requiring an application restart. Microsoft documents SetRefreshInterval and equivalent provider settings as the mechanism for controlling the minimum time between configuration-refresh checks.
This approach satisfies both requirements. The configuration is dynamic because updated values can be detected and reloaded at runtime, while request latency remains low because normal application requests read configuration from the local cached copy instead of making a remote App Configuration request every time.
For request-driven refresh, Microsoft notes that refresh occurs asynchronously and does not block the incoming request. Before the configured refresh interval expires, additional refresh calls effectively perform no remote operation.
Microsoft also recommends caching App Configuration values instead of loading them whenever they are used, both to reduce latency and to avoid excessive service requests, throttling, and unnecessary charges.
Environment variables remain static unless the application is restarted or redeployed. Retrieving configuration on every request increases latency and service load. Key Vault is primarily intended for secrets, not general dynamic application configuration.
Study Guide references: Azure App Configuration; dynamic configuration refresh; provider caching; refresh intervals; request-driven refresh; configuration resiliency.
NEW QUESTION # 105
You provisioned an Azure Cosmos DB for NoSQL account named account1 with the default consistency level.
You plan to configure the consistency level on a per request basis. You plan to request Consistent Prefix consistency on a per-request basis.
You need to identify the resulting consistency level for read and write operations.
Which levels result from this configuration? To answer, select the appropriate options in the answer a rea.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: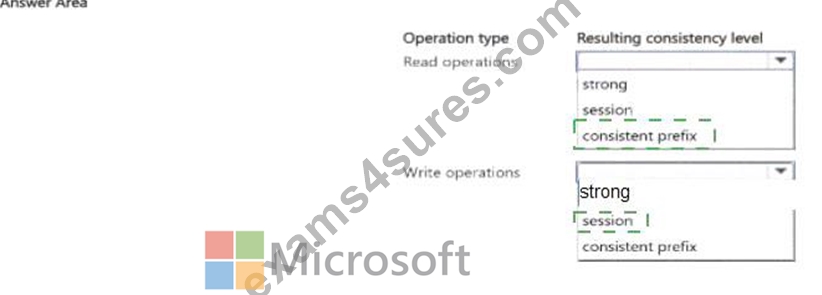
Explanation: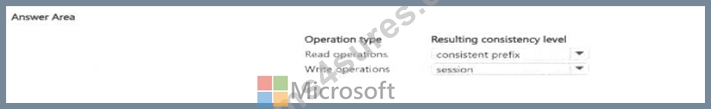
Verified Answer: Read operations: Consistent Prefix. Write operations: Session (the account default remains effective for writes).
Detailed Explanation: Azure Cosmos DB allows a client or request to override consistency for reads.
Microsoft explicitly notes that such an override applies only to reads; it does not change how writes are committed and replicated under the account's configured consistency. Because a new account uses Session consistency by default, requesting Consistent Prefix affects the reads while the account continues to use its Session consistency behavior for writes. This distinction is the key point tested by the hotspot.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Manage Cosmos DB consistency levels | Cosmos DB consistency level choices
NEW QUESTION # 106
Hotspot Question
You have an Azure Functions app using the Consumption hosting plan for a company. The app contains the following functions: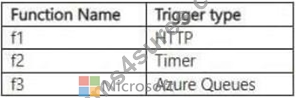
You plan to enable dynamic concurrency on the app. The company requires that each function has its concurrency level managed separately.
You need to configure the app for dynamic concurrency.
Which file or function names should you use? To answer, select the appropriate values in the answer area.
NOTE: Each correct selection is worth one point.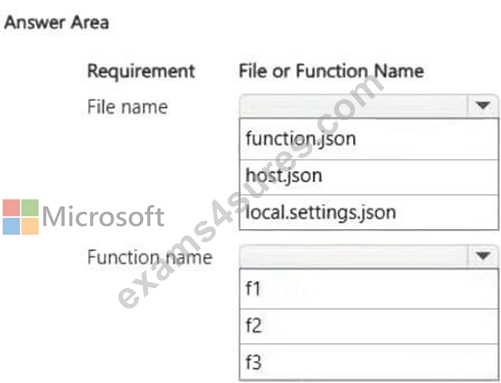
Answer:
Explanation: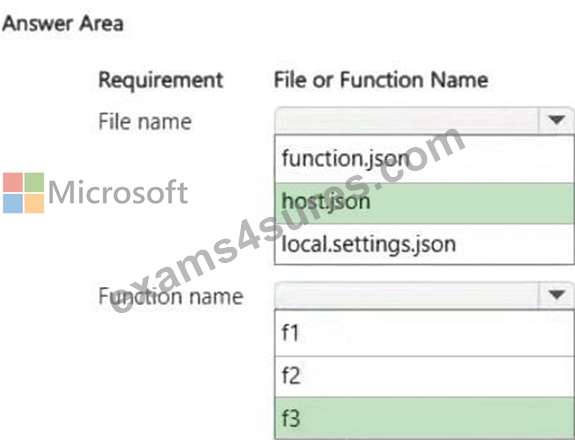
Explanation:
Box 1: host.json
To configure dynamic concurrency for the app, use the host.json configuration file.
host.json: Global metadata file where you enable the app-level dynamic concurrency setting ("dynamicConcurrencyEnabled": true) under the appropriate extension/extension lock configuration.
Box 2: f3
Apply the host.json file to the Azure Queue trigger function (f3), as dynamic concurrency is natively supported and managed per extension for runtime-driven storage and queue triggers rather than HTTP or timer triggers.
Azure Queue trigger function: Dynamic concurrency in Azure Functions specifically targets runtime-driven background bindings like Azure Queue, Blob, and Service Bus storage triggers, allowing individual management and automatic adjustments of processing limits per function.
Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-concurrency
NEW QUESTION # 107
You are designing a messaging solution by using Service Bus for AI document processing.
You need to ensure that a published message is delivered to multiple independent consumers.
Each consumer must receive their own copy of the message.
Which two Service Bus entities should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Topics and Subscriptions are the two Azure Service Bus entities that fit this scenario.
Topics: The publisher sends the document processing message to a single topic, which acts as the central distribution hub.
Subscriptions: Each independent consumer creates its own individual subscription under that topic. When a message arrives, a copy is forwarded to every independent subscription so each consumer can process their own copy safely and separately.
Reference:
https://learn.microsoft.com/en-us/azure/service-bus-messaging/service-bus-queues-topics-subscriptions
NEW QUESTION # 108
You must ensure an Azure OpenAI-powered application never exceeds a defined token-per-minute budget across all users to avoid runaway costs.
What should you configure?
Answer: A
Explanation:
Configure deployment-level Tokens-per-Minute (TPM) and Requests-per-Minute (RPM) rate limits for the Azure OpenAI model deployment. Azure OpenAI quota is allocated to individual model deployments in TPM units, and Microsoft documents that the TPM assigned to a deployment directly maps to the rate limit enforced for inference requests against that deployment. An associated RPM limit is also enforced according to the model ' s TPM-to-RPM ratio.
Because all application users invoke the same deployment, this enforcement occurs at the deployment boundary rather than independently for each end user. Once request traffic would exceed the configured capacity, Azure applies throttling rather than allowing unrestricted token consumption. Microsoft Foundry additionally supports explicit token-management controls through AI Gateway, where a TPM limit can be set for a model deployment; requests exceeding the limit receive HTTP 429 Too Many Requests responses.
Content filtering governs safety categories, not consumption. An Azure AI Search vector-index limit controls search storage rather than generated tokens. Temperature changes sampling randomness and has no enforcement role in rate or cost control.
Study Guide references: Azure OpenAI quota management; TPM/RPM rate limits; deployment capacity; throttling; Foundry AI Gateway token management.
NEW QUESTION # 109
......
We have prepared our Microsoft AI-200 Training Materials for you. They are professional practice material under warranty. Accompanied with acceptable prices for your reference, all our materials with three versions are compiled by professional experts in this area more than ten years long.
AI-200 Free Dump Download: https://www.exams4sures.com/Microsoft/AI-200-practice-exam-dumps.html