2026 Latest Pass4Leader Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1bynfYMMaD-bIaipJ3zhFxysNvKuXZ2zA
The Databricks Databricks-Generative-AI-Engineer-Associate PDF questions file of Pass4Leader has real Databricks Databricks-Generative-AI-Engineer-Associate exam questions with accurate answers. You can download Databricks PDF Questions file and revise Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate exam questions from any place at any time. We also offer desktop Databricks-Generative-AI-Engineer-Associate practice exam software which works after installation on Windows computers. The Databricks-Generative-AI-Engineer-Associate web-based practice test on the other hand needs no software installation or additional plugins. Chrome, Opera, Microsoft Edge, Internet Explorer, Firefox, and Safari support the web-based Databricks-Generative-AI-Engineer-Associate Practice Exam. You can access the Databricks Databricks-Generative-AI-Engineer-Associate web-based practice test via Mac, Linux, iOS, Android, and Windows. Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate practice test (desktop & web-based) allows you to design your mock test sessions.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Real Exam Qty: | 45-60 |
| Available Languages: | English |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Exam Duration: | 90 minutes |
| Exam Price: | USD 200 |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple choice, Multiple select |
| Recommended Training: | Databricks Academy - Generative AI Courses Mosaic AI Documentation |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Generative-AI-Engineer-Associate Latest Braindumps Ppt <<
If you want to walk into the test center with confidence, you should prepare well for Databricks-Generative-AI-Engineer-Associate certification. While, where to get the accurate and valid Databricks study pdf is another question puzzling you. Now, Databricks-Generative-AI-Engineer-Associate sure pass exam will help you step ahead in the real exam and assist you get your Databricks-Generative-AI-Engineer-Associate Certification easily. Our Databricks-Generative-AI-Engineer-Associate test questions answers will provide the best valid and accurate knowledge for you and give you right reference. You will successfully pass your actual test with the help of our high quality and high hit-rate Databricks-Generative-AI-Engineer-Associate study torrent.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 38
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.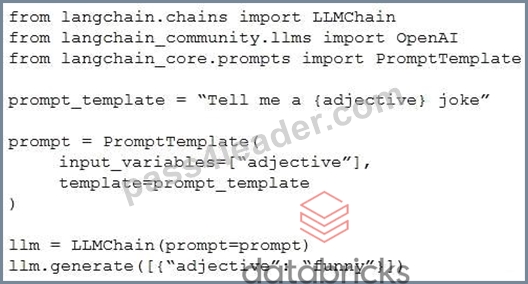
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
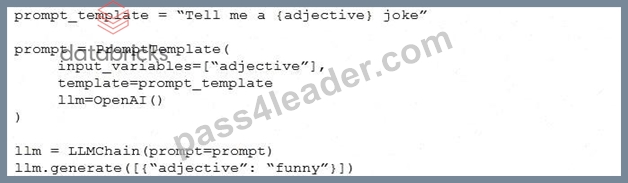
Answer: D
Explanation:
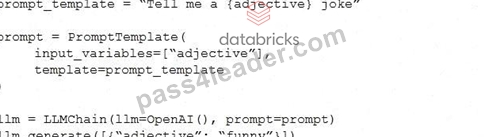
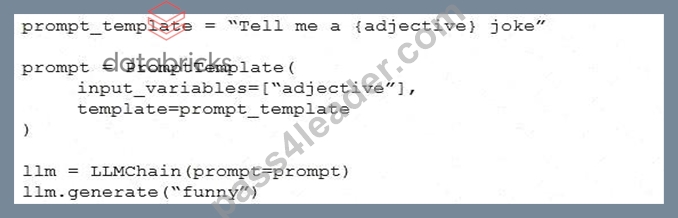
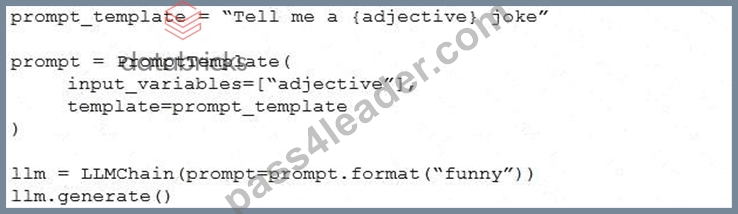
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here ' s a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization : In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods :
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A : Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B : Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D : Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain ' s architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 39
A Generative AI Engineer is building an interactive catalog for a company's inventory system that allows users to search for any item using a plain-text description. There are currently about 17,000 items, and new items are not frequently added. They need a solution that will be the most cost-effective and easy for the company to maintain.
Which solution should the engineer choose?
Answer: B
Explanation:
Option D best matches the small catalog, infrequent updates, and maintenance requirements. Databricks- managed embeddings remove the need to build and maintain a separate embedding-generation pipeline. A Delta Sync index connects the searchable content to its source Delta table. Triggered synchronization updates the index when explicitly invoked, making it suitable when inventory changes are occasional. Continuous synchronization maintains a running streaming pipeline and therefore introduces additional synchronization costs that this scenario does not justify. Self-managed embeddings add engineering responsibilities without a stated benefit. Storage-optimized endpoints primarily address much larger vector collections. Triggered synchronization reduces synchronization overhead; it does not eliminate the separate costs of serving the vector index or computing embeddings. Databricks documentation
NEW QUESTION # 40
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user's query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: C,E
Explanation:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here's why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
Define an evaluation metric: Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user's query and the expected response.
Recall measures the proportion of relevant information retrieved.
NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
Experiment with chunking strategies: Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user's query than others.
Evaluate performance: By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
Use the LLM as an evaluator: After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a "judge" function, where the LLM compares how well a given chunk answers previous user queries.
Optimize based on the LLM's judgment: By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
This metric could be a qualitative judgment on how closely the retrieved information matches the user's intent.
Tune chunking parameters: Based on the LLM's judgment, the engineer can adjust the chunk size or structure to better align with the LLM's responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
NEW QUESTION # 41
A Generative AI Engineer has been asked to design an LLM-based application that accomplishes the following business objective: answer employee HR questions using HR PDF documentation.
Which set of high level tasks should the Generative AI Engineer's system perform?
Answer: D
Explanation:
To design an LLM-based application that can answer employee HR questions using HR PDF documentation, the most effective approach is option D. Here's why:
* Chunking and Vector Store Embedding:HR documentation tends to be lengthy, so splitting it into smaller, manageable chunks helps optimize retrieval. These chunks are then embedded into avector store(a database that stores vector representations of text). Each chunk of text is transformed into an embeddingusing a transformer-based model, which allows for efficient similarity-based retrieval.
* Using Vector Search for Retrieval:When an employee asks a question, the system converts their query into an embedding as well. This embedding is then compared with the embeddings of the document chunks in the vector store. The most semantically similar chunks are retrieved, which ensures that the answer is based on the most relevant parts of the documentation.
* LLM to Generate a Response:Once the relevant chunks are retrieved, these chunks are passed into the LLM, which uses them as context to generate a coherent and accurate response to the employee's question.
* Why Other Options Are Less Suitable:
* A (Calculate Averaged Embeddings): Averaging embeddings might dilute important information. It doesn't provide enough granularity to focus on specific sections of documents.
* B (Summarize HR Documentation): Summarization loses the detail necessary for HR-related queries, which are often specific. It would likely miss the mark for more detailed inquiries.
* C (Interaction Matrix and ALS): This approach is better suited for recommendation systems and not for HR queries, as it's focused on collaborative filtering rather than text-based retrieval.
Thus, option D is the most effective solution for providing precise and contextual answers based on HR documentation.
NEW QUESTION # 42
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: D
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 43
......
Databricks-Generative-AI-Engineer-Associate Exam Cram: https://www.pass4leader.com/Databricks/Databricks-Generative-AI-Engineer-Associate-exam.html
BTW, DOWNLOAD part of Pass4Leader Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1bynfYMMaD-bIaipJ3zhFxysNvKuXZ2zA