弊社のNCP-BC-7.5問題集は大勢の専門家たちの努力で開発される成果です。初心者といい、数年IT仕事を従事した人といい、我々CertJukenのNutanix NCP-BC-7.5問題集は最良の選択であると考えられます。なぜならば、弊社は高品質かつ改革によってすぐに更新できるNCP-BC-7.5問題集を提供できるからです。
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Disaster Recovery Architecture | - Protection Domains - Replication Types (Sync/Async) - Nutanix Leap Overview |
| Topic 2: Recovery Operations | - Failover and Failback Procedures - Test Recovery Workflows - Recovery Plans and Orchestration |
| Topic 3: Prism Central Management | - Cluster and Site Management - DR Monitoring and Operations |
| Topic 4: Data Protection and Backup Integration | - Backup Solutions Integration - Snapshot Management |
| Topic 5: Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
Nutanix NCP-BC-7.5試験を難しく感じる人に「やってもいないのに、できないと言わないこと」を言いたいです。我々CertJukenへのNutanix NCP-BC-7.5試験問題集は専業化のチームが長時間で過去のデータから分析研究された成果で、あなたを試験に迅速的に合格できるのを助けます。依然躊躇うなら、弊社の無料のNutanix NCP-BC-7.5デモを参考しましょう。そうしたら、Nutanix NCP-BC-7.5試験はそんなに簡単なことだと知られます。
質問 # 32
Exhibit: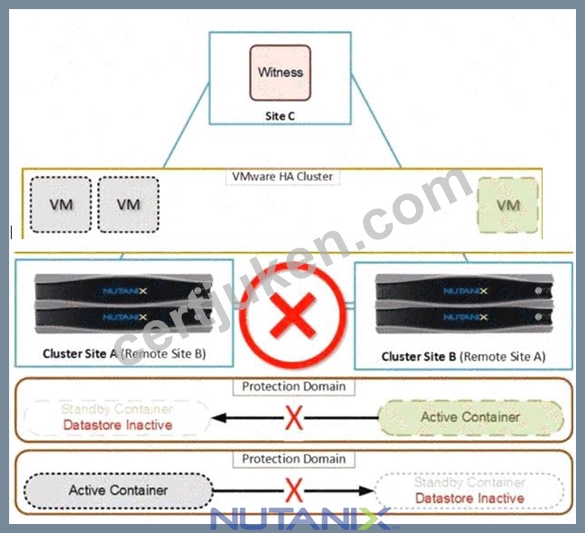
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
正解:B
解説:
Security hardening for BCDR is focused on protecting the integrity of recovery points against accidental deletion, administrative errors, or malicious intent such as ransomware. While infrastructure-level hardening like SSH keys (Option C) or host-level security (Option A) is important, they do not prevent a user with valid administrative credentials in Prism from deleting a snapshot. To address the specific requirement of ensuring only " authorized " and verified actions can modify or delete snapshots, the administrator should implement an " Approval Policy " .
An Approval Policy introduces a " four-eyes " principle for critical management tasks. When this policy is active, any attempt to delete or modify a recovery point does not execute immediately. Instead, it triggers a request in the Prism Central " Task " console and enters a " Pending Approval " state. A separate authorized user-an " Approver " -must then review the request and explicitly grant permission before the deletion can occur. This creates a vital procedural safeguard, ensuring that no single individual has the unilateral power to destroy the organization ' s backup data. By configuring this policy, the administrator hardens the DR environment against both internal threats and external actors who might gain access to a single set of admin credentials, providing a robust layer of defense for critical data assets.
質問 # 33
Recently, several new VMs were deployed as part of an application expansion. Within 24 hours, the administrator notices no recovery points are being created for the new VMs.
During investigation, the administrator observes:
* Existing VMs in the Protection Policy continue to replicate successfully.
* No replication task failures are reported.
* Network connectivity between clusters is healthy.
* Storage capacity at the remote site is sufficient.
* The Protection Policy uses category-based entity selection.
* The newly deployed VMs were provisioned by a separate team.
What is the most likely root cause of the issue?
正解:A
解説:
Nutanix Disaster Recovery (formerly Leap) utilizes a " policy-driven " approach where virtual machines are protected based on assigned " Categories " rather than individual VM names. This allows for automated protection: any VM tagged with a specific category (e.g., App:Web) is automatically picked up by the associated Protection Policy. When existing VMs are replicating fine but new ones are not, and there are no network or storage errors, the root cause is almost always an administrative oversight during provisioning.
If the separate team that deployed the VMs followed a checklist that didn ' t include category assignment, those VMs exist as " unprotected entities " in the eyes of Prism Central. The Protection Policy will ignore them because they do not match the entity selection criteria defined in the policy ' s configuration. To resolve this, the administrator must simply apply the correct category to the new VMs. Once tagged, the Cerebro service will identify the new members during its next scan and initiate the initial full seed replication to the recovery site. This scenario highlights the critical need for cross-team coordination and the use of automated deployment tools (like Nutanix Self-Service or Calm) to ensure that security and BCDR requirements are applied consistently during the VM lifecycle.
質問 # 34
An administrator is planning a scheduled maintenance window that will temporarily interrupt network connectivity between the primary and recovery sites. Several Tier 1 VMs are protected with a Synchronous replication Protection Policy. What must the administrator do before beginning the maintenance window to prevent these VMs from becoming unresponsive without making RPO changes?
正解:C
解説:
Synchronous replication is designed for zero data loss by requiring that every write be acknowledged at both the primary and recovery sites before the application can proceed. This creates a " hard " dependency on the network link between the two clusters . If the network connectivity is interrupted (e.g., during scheduled maintenance), the primary cluster will be unable to receive acknowledgments from the remote site.
By default, if the synchronous link is broken, the primary cluster may pause I/O to the protected VMs to prevent data inconsistency, which would cause the VMs to become unresponsive to users. To prevent this during planned maintenance while ensuring that the VMs stay online at the primary site, the administrator should temporarily transition the protection mode. Changing the Protection Policy from " Synchronous " to " Asynchronous " (Option C) removes the real-time write-mirroring requirement. This allows the VMs to continue serving local I/O independently of the remote site ' s status. While this technically increases the RPO during the maintenance window, it ensures application availability. Once the maintenance is complete and network connectivity is restored, the administrator can change the policy back to Synchronous. The system will then perform a catch-up sync and return to the Zero-RPO state once the data at both sites is identical again. This operational maneuver is a standard best practice for managing " stretched " cluster environments during infrastructure updates.
質問 # 35
An administrator notices that storage utilization continues to increase at both the primary and recovery sites after implementing a third-party backup solution that uses protection policies. Which configuration should be reviewed first?
正解:A
解説:
Storage consumption in a BCDR environment is directly governed by two factors: the frequency of recovery points (RPO) and the length of time those points are kept (Retention). When a third-party backup solution integrates with Nutanix Protection Policies, it often takes over the management of the snapshot lifecycle.
If storage utilization is increasing unexpectedly at both sites, the most likely cause is that recovery points are not being expired or purged at the expected rate. The administrator should first review the retention settings within the backup solution. If the retention period is set too long, or if the backup software is failing to send the " delete " command to Prism after its local catalog is updated, snapshots will accumulate on both the primary and recovery Nutanix clusters, leading to a steady growth in storage consumption. Other factors like network segmentation (Option C) or encryption (Option B) affect traffic paths and security but do not directly influence the quantity of data stored on the disks. Recovery validation (Option A) might use temporary storage but should not cause a continuous, long-term increase. Therefore, aligning the retention policy of the backup software with the available cluster capacity is the primary troubleshooting step.
質問 # 36
What must an administrator verify before starting a migration of entities from a protection domain to a protection policy?
正解:A
解説:
Migrating from legacy Protection Domain (PD) based management to the modern Prism Central (PC) based Protection Policies is a recommended best practice for scaling Nutanix Disaster Recovery. This migration involves moving VMs from a " Prism Element " centric management model to a centralized, category-based model in Prism Central.
To ensure that no data is lost during this transition, the most critical prerequisite is to verify that a successful, full replication (backup) of the Protection Domain has recently completed. This ensures that the recovery site already possesses a complete and consistent set of data for the VMs before they are unlinked from the old policy and attached to the new one. While adding VMs to a category (Option A) is a step in the process, it is not the first verification step required for data safety. If an administrator attempts to migrate while a replication is incomplete or failing, the transition to the new policy might leave the VMs unprotected for an extended period, or recovery points might be missing if a disaster occurs mid-migration. By completing a full backup of the PD first, the administrator creates a " safety net " of recovery points that can be used if the migration itself encounters issues. This ensures that the transition to modern DR is performed with minimal risk to the business ' s data protection objectives.
質問 # 37
......
NCP-BC-7.5学習教材は、当初の目標を達成し、仕事のキャリアをよりスムーズにし、家族の生活の質を向上させるのに役立ちます。 NCP-BC-7.5試験トレントを20〜30時間学習するだけで、NutanixのNCP-BC-7.5試験に自信を持って参加できると言っても過言ではありません。 そして、10年以上にわたってこのキャリアでプロフェッショナルであったため、あなたの成功を確実にすることができます。 そして、数千人の候補者が、優れたNCP-BC-7.5トレーニング資料の助けを借りて、Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5夢と野望を達成しました。
NCP-BC-7.5日本語関連対策: https://www.certjuken.com/NCP-BC-7.5-exam.html