Everything is changing so fast. So do not reject challenging new things. Our Certified-Data-Engineer-Professional study materials absolutely can add more pleasure to your life. You just need a chance to walk out. You can click to see the comments of the Certified-Data-Engineer-Professional exam braindumps and how we changed their life by helping them get the Certified-Data-Engineer-Professional Certification. And you can also see the pass rate of our Certified-Data-Engineer-Professional learning guide high as 98% to 100%, we can give you a promising future.
| Section | Weight | Objectives |
|---|---|---|
| Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
>> Online Certified-Data-Engineer-Professional Test <<
Free4Torrent Certified-Data-Engineer-Professional exam dumps are audited by our certified subject matter experts and published authors for development. Certified-Data-Engineer-Professional exam dumps are one of the highest quality Certified-Data-Engineer-Professional Q&AS in the world. It covers nearly 96% real questions and answers, including the entire testing scope. Free4Torrent guarantees you Pass Certified-Data-Engineer-Professional Exam at first attempt.
NEW QUESTION # 13
Which method can be used to determine the total wall-clock time it took to execute a query?
Answer: D
Explanation:
The Query Profiler in Databricks SQL and notebooks provides a detailed breakdown of query performance metrics. The "Total wall-clock duration" metric directly represents the total elapsed time from query start to completion, including all execution, planning, and waiting stages. In contrast, "Aggregated task time" reflects the cumulative duration across all parallel tasks, which does not equal the total elapsed wall time since tasks often run concurrently. Using job duration from Spark UI can underestimate or overestimate runtime when queries span multiple jobs.
Therefore, the Query Profiler's total wall-clock duration is the officially documented method to determine actual query execution time.
NEW QUESTION # 14
Which REST API call can be used to review the notebooks configured to run as tasks in a multi- task job?
Answer: C
Explanation:
https://docs.databricks.com/api/workspace/jobs/getresponses/settings/tasks/notebook_task/noteb ook_path
NEW QUESTION # 15
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query: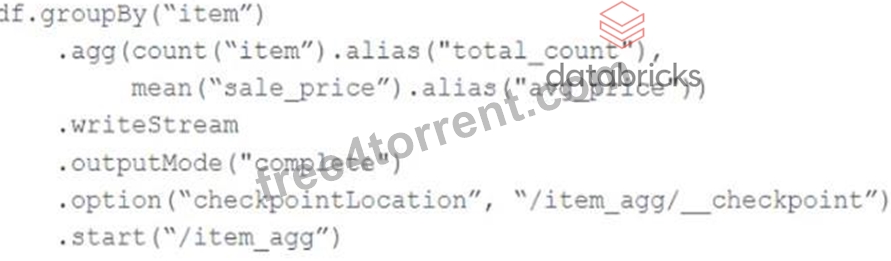
Proposed query: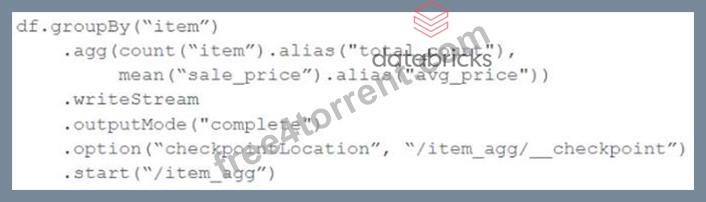
Which step must also be completed to put the proposed query into production?
Answer: A
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 16
Which statement regarding stream-static joins and static Delta tables is correct?
Answer: B
Explanation:
This is the correct answer because stream-static joins are supported by Structured Streaming when one of the tables is a static Delta table. A static Delta table is a Delta table that is not updated by any concurrent writes, such as appends or merges, during the execution of a streaming query. In this case, each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch, which means it will reflect any changes made to the static Delta table before the start of each microbatch.
NEW QUESTION # 17
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on task A.
If tasks A and B complete successfully but task C fails during a scheduled run, which statement describes the resulting state?
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The resulting state after running the second command is that an external table will be created in the storage container mounted to /mnt/finance_eda_bucket with the new name prod.sales_by_store. The command will not change any data or move any files in the storage container; it will only update the table reference in the metastore and create a new Delta transaction log for the renamed table.
NEW QUESTION # 18
......
High salary is everyone's dream. You salary is always based on your career competitive. In IT filed qualification is important. Our Certified-Data-Engineer-Professional questions and answers will help you hold opportunities and face difficulties bravely, then make a great achievement. Passing tests and get a certification is certainly a valid method that proves your competitions. Certified-Data-Engineer-Professional Questions and answers is surely helpful study guide for candidates all over the world.
Certified-Data-Engineer-Professional Valid Braindumps Files: https://www.free4torrent.com/Certified-Data-Engineer-Professional-braindumps-torrent.html