DOWNLOAD the newest Actual4Cert Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Gd4SfarNZbeTtV2C6_w0UoSPlkgAqM6z
The web-based Databricks-Certified-Data-Engineer-Associate practice test is accessible via any browser. This Databricks-Certified-Data-Engineer-Associate mock exam simulates the actual Databricks Databricks-Certified-Data-Engineer-Associate exam and does not require any software or plugins. Compatible with iOS, Mac, Android, and Windows operating systems, it provides all the features of the desktop-based Databricks-Certified-Data-Engineer-Associate Practice Exam software.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Engineer Associate Exam |
| Exam Number: | DE-A |
| Real Exam Qty: | 45 scored multiple-choice questions |
| Related Certifications: | Databricks Certified Data Engineer Professional |
| Exam Duration: | 90 minutes |
| Exam Price: | USD 200 |
| Available Languages: | English |
| Certificate Validity Period: | 2 years |
| Passing Score: | Approximately ~70% (not officially fixed/publicly guaranteed) |
| Exam Format: | Scenario-based questions, Proctored online or test center, Multiple-choice |
| Recommended Training: | Databricks Data Engineering Learning Path (Databricks Academy) Official Data Engineering with Databricks Course |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Data-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam or test center |
| Pre Condition: | No formal prerequisites required; recommended ~6 months hands-on experience with Databricks, Spark SQL, and PySpark. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-associate |
>> Databricks-Certified-Data-Engineer-Associate Exam Price <<
Our Databricks-Certified-Data-Engineer-Associate PDF format is also an effective format to do test preparation. In your spare time, you can easily use the Databricks-Certified-Data-Engineer-Associate dumps PDF file for study or revision. The PDF file of Databricks Databricks-Certified-Data-Engineer-Associate real questions is convenient and manageable. These Databricks Databricks-Certified-Data-Engineer-Associate Questions are also printable, giving you the option of paper study since some Databricks Databricks-Certified-Data-Engineer-Associate applicants prefer off-screen preparation rather than on a screen.
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) exam is a certification program designed for individuals who wish to demonstrate their expertise in designing and implementing big data solutions using Databricks. Databricks-Certified-Data-Engineer-Associate exam is intended for data engineers, data analysts, and big data architects who want to validate their skills in building and managing large-scale data processing systems using Databricks.
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) Certification Exam is designed for individuals who are interested in pursuing a career in data engineering. Databricks Certified Data Engineer Associate Exam certification exam is developed in collaboration with Databricks, a leading data and AI company that provides a unified analytics platform for data engineering, data science, and machine learning. The Databricks-Certified-Data-Engineer-Associate Exam Tests candidates on their knowledge of data engineering principles, practices, and tools.
NEW QUESTION # 230
A Delta Live Table pipeline includes two datasets defined using streaming live table. Three datasets are defined against Delta Lake table sources using live table.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
What is the expected outcome after clicking Start to update the pipeline assuming previously unprocessed data exists and all definitions are valid?
Answer: C
Explanation:
In Delta Live Tables (DLT), when configured to run in Continuous Pipeline Mode, particularly in a production environment, the system is designed to continuously process and update data as it becomes available. This mode keeps the compute resources active to handle ongoing data processing and automatically updates all datasets defined in the pipeline at predefined intervals. Once the pipeline is manually stopped, the compute resources are terminated to conserve resources and reduce costs. This mode is suitable for production environments where datasets need to be kept up-to-date with the latest data.
Reference:
Databricks documentation on Delta Live Tables: Delta Live Tables Guide
NEW QUESTION # 231
A data engineer has realized that the data files associated with a Delta table are incredibly small.
They want to compact the small files to form larger files to improve performance.
Which of the following keywords can be used to compact the small files?
Answer: D
NEW QUESTION # 232
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table: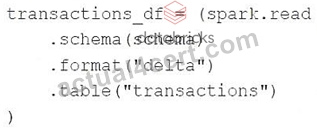
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
Answer: C
Explanation:
To read from a stream source, the data engineer needs to use the spark.readStream method instead of the spark.
read method. The spark.readStream method returns a DataStreamReader object that can be used to specify the details of the input source, such as the format, the schema, the path, and the options. The spark.read method is only suitable for batch processing, not streaming processing. The other changes are not necessary or correct for reading from a stream source. References: Structured Streaming Programming Guide, Read a stream, Databricks Data Sources
NEW QUESTION # 233
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also used by other processes. As a result, the files should be kept as is and will accumulate in the directory. The data engineer needs to identify which files are new since the previous run in the pipeline, and set up the pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
Answer: D
Explanation:
Auto Loader is a tool that can incrementally and efficiently process new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a Structured Streaming source called cloudFiles, which automatically detects and processes new files in a given input directory path on the cloud file storage.
Auto Loader also tracks the ingestion progress and ensures exactly-once semantics when writing data into Delta Lake. Auto Loader can ingest various file formats, such as JSON, CSV, XML, PARQUET, AVRO, ORC, TEXT, and BINARYFILE. Auto Loader has support for both Python and SQL in Delta Live Tables, which are a declarative way to build production-quality data pipelines with Databricks. References: What is Auto Loader?, Get started with Databricks Auto Loader, Auto Loader in Delta Live Tables
NEW QUESTION # 234
A data engineer has created a new database using the following command:
CREATE DATABASE IF NOT EXISTS customer360;
In which of the following locations will the customer360 database be located?
Answer: C
Explanation:
dbfs:/user/hive/warehouse Thereby showing "dbfs:/user/hive/warehouse/customer360.db The location of the customer360 database depends on the value of the spark.sql.warehouse.dir configuration property, which specifies the default location for managed databases and tables. If the property is not set, the default value is dbfs:/user/hive/warehouse. Therefore, the customer360 database will be located in dbfs:/user
/hive/warehouse/customer360.db. However, if the property is set to a different value, such as dbfs:/user/hive
/database, then the customer360 database will be located in dbfs:/user/hive/database/customer360.db. Thus, more information is needed to determine the correct response.
Option A is not correct, as dbfs:/user/hive/database/customer360 is not the default location for managed databases and tables, unless the spark.sql.warehouse.dir property is explicitly set to dbfs:/user/hive/database.
Option B is not correct, as dbfs:/user/hive/warehouse is the default location for the root directory of managed databases and tables, not for a specific database. The database name should be appended with .db to the directory path, such as dbfs:/user/hive/warehouse/customer360.db.
Option C is not correct, as dbfs:/user/hive/customer360 is not a valid location for a managed database, as it does not follow the directory structure specified by the spark.sql.warehouse.dir property.
Databases and Tables
[Databricks Data Engineer Professional Exam Guide]
NEW QUESTION # 235
......
Databricks-Certified-Data-Engineer-Associate Valid Exam Notes: https://www.actual4cert.com/Databricks-Certified-Data-Engineer-Associate-real-questions.html
P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by Actual4Cert: https://drive.google.com/open?id=1Gd4SfarNZbeTtV2C6_w0UoSPlkgAqM6z