참고: ExamPassdump에서 Google Drive로 공유하는 무료, 최신 Professional-Machine-Learning-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1d8QSUBqv2Bam_Tl4UGAXL9NLfd8RpuAW
ExamPassdump는 IT인증자격증시험에 대비한 덤프공부가이드를 제공해드리는 사이트인데 여러분의 자격증 취득의 꿈을 이루어드릴수 있습니다. Google인증 Professional-Machine-Learning-Engineer시험을 등록하신 분들은 바로ExamPassdump의Google인증 Professional-Machine-Learning-Engineer덤프를 데려가 주세요. 단기간에 시험패스의 기적을 가져다드리는것을 약속합니다.
| Section | Objectives |
|---|---|
| ML pipeline automation and orchestration | - Pipeline design
|
| Data preparation and processing | - Data ingestion and pipelines
|
| ML model development | - Evaluation
|
| Designing ML solutions | - Framing ML problems
|
| Deployment and operations | - Monitoring and maintenance
|
>> Professional-Machine-Learning-Engineer인증시험대비 공부문제 <<
퍼펙트한Google Professional-Machine-Learning-Engineer시험대비덤프자료는 ExamPassdump가 전문입니다. Google Professional-Machine-Learning-Engineer덤프를 다운받아 가장 쉬운 시험준비를 하여 한방에 패스가는것입니다. 다같이 Google Professional-Machine-Learning-Engineer덤프로 시험패스에 주문걸어 보아요. 마술처럼Google Professional-Machine-Learning-Engineer시험합격이 실현될것입니다.
질문 # 312
Your company manages an ecommerce platform and has a large dataset of customer reviews. Each review has a positive, negative, or neutral label. You need to quickly prototype a sentiment analysis model that accurately predicts the sentiment labels of new customer reviews while minimizing time and cost. What should you do?
정답:C
설명:
The keywords here are " quickly prototype " and " minimize time and cost. "
* Natural Language API: Google's pre-trained Natural Language API provides out-of-the-box sentiment analysis. It requires zero training time, zero infrastructure management, and no labeling effort. This is the fastest and most cost-effective way to get a baseline/prototype.
* Why other options are incorrect:
* Option A: Fine-tuning a BERT model is computationally expensive and requires significant engineering time.
* Option C: AutoML is a great secondary step if the API is not accurate enough, but it still requires time to train and evaluate, making it slower than the pre-trained API.
* Option D: Vectorizing text and training a regression model is unnecessarily complex for a standard sentiment classification task.
질문 # 313
You work for a company that provides an anti-spam service that flags and hides spam posts on social media platforms. Your company currently uses a list of 200,000 keywords to identify suspected spam posts. If a post contains more than a few of these keywords, the post is identified as spam. You want to start using machine learning to flag spam posts for human review. What is the main advantage of implementing machine learning for this business case?
정답:C
설명:
The main advantage of implementing machine learning for this business case is that new problematic phrases can be identified in spam posts. This is because machine learning can learn from the data and the feedback, and adapt to the changing patterns and trends of spam posts. Machine learning can also capture the semantic and contextual meaning of the posts, and not just rely on the presence or absence of keywords. By using machine learning, you can improve the accuracy and coverage of your anti-spam service, and detect new and emerging types of spam posts that may not be captured by the keyword list.
The other options are not advantages of implementing machine learning for this business case for the following reasons:
* A. Posts can be compared to the keyword list much more quickly is not an advantage, as it does not improve the quality or effectiveness of the anti-spam service. It only improves the efficiency of the service, which is not the primary objective. Moreover, machine learning may not necessarily be faster than the keyword list, depending on the complexity and size of the model and the data.
* C. A much longer keyword list can be used to flag spam posts is not an advantage, as it does not address the limitations or challenges of the keyword list approach. It only increases the size and complexity of the keyword list, which can make it harder to maintain and update. Moreover, a longer keyword list may not improve the accuracy or coverage of the anti-spam service, as it may introduce more false positives or false negatives, or miss new and emerging types of spam posts.
* D. Spam posts can be flagged using far fewer keywords is not an advantage, as it does not reflect the capabilities or benefits of machine learning. It only reduces the size and complexity of the keyword list, which can make it easier to maintain and update. However, using fewer keywords may not improve the accuracy or coverage of the anti-spam service, as it may lose some information or meaning of the posts, or miss some types of spam posts.
:
Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate Google Cloud l aunches machine learning engineer certification Machine Learning for Spam Detection Spam Detection Using Machine Learning
질문 # 314
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this:
A)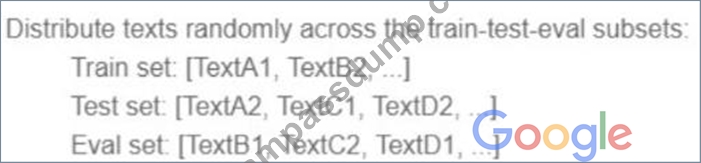
B)
C)
D)
정답:D
질문 # 315
You work for a large retailer and you need to build a model to predict customer churn. The company has a dataset of historical customer data, including customer demographics, purchase history, and website activity.
You need to create the model in BigQuery ML and thoroughly evaluate its performance. What should you do?
정답:A
설명:
Customer churn is a binary classification problem, where the target variable is whether a customer has churned or not. Therefore, a logistic regression model is more suitable than a linear regression model, which is used for regression problems. A logistic regression model can output the probability of a customer churning, which can be used to rank the customers by their churn risk and take appropriate actions 1 .
BigQuery ML is a service that allows you to create and execute machine learning models in BigQuery using standard SQL queries 2 . You can use BigQuery ML to create a logistic regression model for customer churn prediction by using the CREATE MODEL statement and specifying the LOGISTIC_REG model type 3
. You can use the historical customer data as the input table for the mo del, and specify the features and the label columns 3 .
Vertex AI Model Registry is a central repository where you can manage the lifecycle of your ML models 4
. You can import models from various sources, such as BigQuery ML, AutoML, or custom models, and assign them to different versions and aliases 4 . You can also deploy models to endpoints, which are resources that provide a service URL for online prediction.
By registering the BigQuery ML model in Vertex AI Model Registry, you can leverage the Vertex AI features to evaluate and monitor the model performance 4 . You can use Vertex AI Experiments to track and compare the metrics of different model versions, such as accuracy, precision, recall, and AUC. You can also use Vertex AI Explainable AI to generate feature attributions that show how much each input feature contributed to the model's prediction.
The other options are not suitable for your scenario, because they either use the wrong model type, such as linear regression, or they do not use Vertex AI to evaluate the model performance, which would limit the insights and actions you can take based on the model results.
:
Logistic Regression for Machine Learning
Introduction to BigQuery ML | Google Cloud
Creating a logistic regression model | BigQuery ML | Google Cloud
Introduction to Vertex AI Model Registry | Google Cloud
[Deploy a model to an endpoint | Vertex AI | Google Cloud]
[Vertex AI Experiments | Google Cloud]
질문 # 316
You recently used XGBoost to train a model in Python that will be used for online serving Your model prediction service will be called by a backend service implemented in Golang running on a Google Kubemetes Engine (GKE) cluster Your model requires pre and postprocessing steps You need to implement the processing steps so that they run at serving time You want to minimize code changes and infrastructure maintenance and deploy your model into production as quickly as possible. What should you do?
정답:D
설명:
The best option for implementing the processing steps so that they run at serving time, minimizing code changes and infrastructure maintenance, and deploying the model into production as quickly as possible, is to use the Predictor interface to implement a custom prediction routine. Build the custom container, upload the container to Vertex AI Model Registry, and deploy it to a Vertex AI endpoint. This option allows you to leverage the power and simplicity of Vertex AI to serve your XGBoost model with minimal effort and customization. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained XGBoost model to an online prediction endpoint, which can provide low-latency predictions for individual instances. A custom prediction routine (CPR) is a Python script that defines the logic for preprocessing the input data, running the prediction, and postprocessing the output data. A CPR can help you customize the prediction behavior of your model, and handle complex or non- standard data formats. A CPR can also help you minimize the code changes, as you only need to write a few functions to implement the prediction logic. A Predictor interface is a class that inherits from the base class aiplatform.Predictor , and implements the abstract methods predict() and preprocess() . A Predictor interface can help you create a CPR by defining the preprocessing and prediction logic for your model. A container image is a package that contains the model, the CPR, and the dependencies. A container image can help you standardize and simplify the deployment process, as you only need to upload the container image to Vertex AI Model Registry, and deploy it to Vertex AI Endpoints. By using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint, you can implement the processing st eps so that they run at serving time, minimize code changes and infrastructure maintenance, and deploy the model into production as quickly as possible 1 .
The other options are not as good as option C, for the following reasons:
* Option A: Using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, and deploying it on your organization's GKE cluster would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. FastAPI is a framework for building web applications and APIs in Python. FastAPI can help you implement an HTTP server that can handle prediction requests and responses, and perform data preprocessing and postprocessing. A Docker image is a package that contains the model, the HTTP server, and the dependencies. A Docker image can help you standardize and simplify the deployment process, as you only need to build and run the Docker image. GKE is a service that can create and manage Kubernetes clusters on Google Cloud. GKE can help you deploy and scale your Docker image on Google Cloud, and provide high availability and performance. However, using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, and deploying it on your organization's GKE cluster would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. You would need to write code, create and configure the HTTP server, build and test the Docker image, create and manage the GKE cluster, and deploy and monitor the Docker image. Moreover, this option would not leverage the power and simplicity of Vertex AI, which can provide online prediction natively integrated with Google Cloud services 2 .
* Option B: Using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, uploading the image to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. FastAPI is a framework for building web applications and APIs in Python. FastAPI can help you implement an HTTP server that can handle prediction requests and responses, and perform data preprocessing and postprocessing. A Docker image is a package that contains the model, the HTTP server, and the dependencies. A Docker image can help you standardize and simplify the deployment process, as you only need to build and run the Docker image. Vertex AI Model Registry is a service that can store and manage your machine learning models on Google Cloud. Vertex AI Model Registry can help you upload and organize your Docker image, and track the model versions and metadata. Vertex AI Endpoints is a service that can provide online prediction for your machine learning models on Google Cloud. Vertex AI Endpoints can help you deploy your Docker image to an online prediction endpoint, which can provide low-latency predictions for individual instances. However, using FastAPI to implement an HTTP server, creating a Docker image that runs your HTTP server, uploading the image to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint would require more skills and steps than using the Predictor interface to implement a CPR, building the custom container, uploading the container to Vertex AI Model Registry, and deploying it to a Vertex AI endpoint. You would need to write code, create and configure the HTTP server, build and test the Docker image, upload the Docker image to Vertex AI Model Registry, and deploy the Docker image to Vertex AI Endpoints. Moreover, this option would not leverage the power and simplicity of Vertex AI, which can provide online prediction natively integrated with Google Cloud services 2 .
* Option D: Using the XGBoost prebuilt serving container when importing the trained model into Vertex AI, deploying the model to a Vertex AI endpoint, working with the backend engineers to implement the pre- and postprocessing steps in the Golang backend service would not allow you to implement the processing steps so that they run at serving time, and could increase the code changes and infrastructure maintenance. A XGBoost prebuilt serving container is a container image that is provided by Google Cloud, and contains the XGBoost framework and the dependencies. A XGBoost prebuilt serving container can help you deploy a XGBoost model without writing any code, but it also limits your customization options. A XGBoost prebuilt serving container can only handle standard data formats, such as JSON or CSV, and cannot perform any preprocessing or postprocessing on the input or output data. If your input data requires any transformation or normalization before running the prediction, you cannot use a XGBoost prebuilt serving container. A Golang backend service is a service that is implemented in Golang, a programming language that can be used for web development and system programming. A Golang backend service can help you handle the prediction requests and responses from the frontend, and communicate with the Vertex AI endpoint. However, using the XGBoost prebuilt serving container when importing the trained model into Vertex AI, deploying the model to a Vertex AI endpoint, working with the backend engineers to implement the pre- and postprocessing steps in the Golang backend service would not allow you to implement the processing steps so that they run at serving time, and could increase the code changes and infrastructure maintenance. You would need to write code, import the trained model into Vertex AI, deploy the model to a Vertex AI endpoint, implement the pre- and postprocessing steps in the Golang backend service, and test and monitor the Golang backend service. Moreover, this option would not leverage the power and simplicity of Vertex AI, which can provide online prediction natively integrated with Google Cloud services 2 .
References:
Preparing for Google Cloud Certification: Machine Learning Engineer , Course 3: Production ML Systems, Week 2: Serving ML Predictions Google Cloud Professional Machine Learning Engineer Exam Guide , Section 3: Scaling ML models in production, 3.1 Deploying ML models to production Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6: Production ML Systems, Section 6.2: Serving ML Predictions Custom prediction routines Using pre-built containers for prediction Using custom containers for prediction
질문 # 317
......
Google Professional-Machine-Learning-Engineer인증덤프가 ExamPassdump전문가들의 끈임 없는 노력 하에 최고의 버전으로 출시되었습니다. 여러분의 꿈을 이루어드리려고 말이죠. IT업계에서 자기만의 자리를 잡고 싶다면Google Professional-Machine-Learning-Engineer인증시험이 아주 좋은 자격증입니다. 만약Google Professional-Machine-Learning-Engineer인증시험 자격증이 있다면 일에서도 많은 변화가 있을 것입니다, 연봉상승은 물론, 자기자신만의 공간도 넓어집니다.
Professional-Machine-Learning-Engineer최신버전 덤프공부: https://www.exampassdump.com/Professional-Machine-Learning-Engineer_valid-braindumps.html
그 외, ExamPassdump Professional-Machine-Learning-Engineer 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1d8QSUBqv2Bam_Tl4UGAXL9NLfd8RpuAW