Our company employs the first-rate expert team which is superior to others. Our experts team includes the experts who develop and research the Certified-Data-Engineer-Professional cram materials for many years and enjoy the great fame among the industry, the senior lecturers who boost plenty of experiences in the information about the exam and published authors who have done a deep research of the Certified-Data-Engineer-Professional Latest Exam file and whose articles are highly authorized. They provide strong backing to the compiling of the Certified-Data-Engineer-Professional exam questions and reliable exam materials resources. They can help you pass the Certified-Data-Engineer-Professional exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 2: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Topic 3: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 4: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Topic 5: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 6: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 7: Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures |
| Topic 8: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 9: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
>> Certified-Data-Engineer-Professional Valid Exam Sims <<
Are you trying to pass the Certified-Data-Engineer-Professional exam to get the longing Certified-Data-Engineer-Professional certification? As we know, there are a lot of the advantages of the certification, such as higher salaries, better job positions and so on. Perhaps at this moment, you need the help of our Certified-Data-Engineer-Professional Study Materials. As our company's flagship product, it has successfully helped countless candidates around the world to obtain the coveted Certified-Data-Engineer-Professional certification.
NEW QUESTION # 117
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer: D
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 118
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.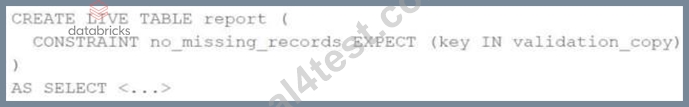
Which approach would allow using DLT expectations to validate all expected records are present in this table?
Answer: B
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 119
A security team wants to enforce data protection for a customer table containing customer PII data. To comply with local policies, sales team members should only see customers from their region, while non-admin users should have email addresses masked. Which implementation approach should be used when using Unity Catalog row filters and column masks?
Answer: B
Explanation:
Unity Catalog enforces fine-grained access control by applying SQL UDF-based row filters and column masks directly at the table level. Row filter UDFs can restrict visible rows based on the user's region, while column mask UDFs can dynamically mask sensitive fields like email addresses for non-admin users. Applying them with ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK ensures centralized, consistent enforcement of data protection policies across all access paths.
NEW QUESTION # 120
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.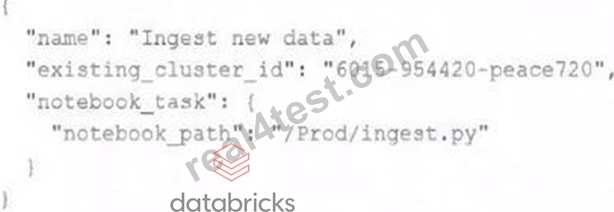
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: B
Explanation:
Databricks jobs create will create a new job with the same name each time it is run.
In order to overwrite the extsting job you need to run databricks jobs reset
NEW QUESTION # 121
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability. Which piece of information is critical to this decision?
Answer: A
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
NEW QUESTION # 122
......
One of the most effective ways to prepare for the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional exam is to take the latest Databricks Certified-Data-Engineer-Professional exam questions from Real4test. Many candidates get nervous because they don’t know what will happen in the final Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional exam. Taking Certified-Data-Engineer-Professional exam dumps from Real4test helps eliminate exam anxiety. Real4test has designed this set of real Databricks Certified-Data-Engineer-Professional PDF Questions in accordance with the Certified-Data-Engineer-Professional exam syllabus and pattern. You can gain essential knowledge and clear all concepts related to the final exam by using these Certified-Data-Engineer-Professional practice test questions.
Certified-Data-Engineer-Professional Sample Questions Pdf: https://www.real4test.com/Certified-Data-Engineer-Professional_real-exam.html