The ValidDumps is a leading platform that has been helping the Snowflake SPS-C01 exam aspirants for many years. Over this long time period, thousands of Snowflake SPS-C01 Exam candidates have passed their dream SPS-C01 certification exam and have become a member of Snowflake SPS-C01 certification exam community.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API and Development | 30% | - Python API fundamentals
|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Performance and Best Practices | 10% | - Optimization techniques
|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
>> Certificate SPS-C01 Exam <<
In light of the truth that different people have various learning habits, we launch three SPS-C01 training questions demos for your guidance: the PDF, Software and the APP online. Just come to our official website and click on the corresponding website link of the SPS-C01 Exam Materials, then seek the information you need, the test samples are easy to obtain. In addition, you can freely download those SPS-C01 learning materials for your consideration.
NEW QUESTION # 13
You are tasked with creating a series of Snowpark DataFrames for a data transformation pipeline. For debugging purposes, you want to materialize these DataFrames as tables within Snowflake, but only for the duration of your session. You also need to make sure that these tables are automatically cleaned up when your session ends. Which of the following approaches offer(s) the MOST efficient and appropriate way to achieve this?
Answer: C
Explanation:
Option E is the most efficient and appropriate because it leverages local temporary views. Local temporary views are automatically dropped at the end of the session without requiring explicit cleanup. Option A requires manual cleanup which is prone to errors. Option B involves writing physical tables, even if temporary, which is less efficient than views if you need to access data within the same session and are for debugging only. Option D uses a non-existent 'temporary' option, making it incorrect. Option C makes use of CTE's, but does not persist the data as local temporary tables.
NEW QUESTION # 14
You have a complex Snowpark Python UDF that aggregates data from various sources and returns a dictionary containing several metrics (e.g., '{'average price': 12.50, 'total sales': 1000, 'customer count': 50}'). You need to operationalize this UDF and ensure proper data type handling for each metric. Which of the following is the MOST appropriate way to define the return type using the registration API?
Answer: E
Explanation:
Using a 'StructType' with 'StructField' for each metric is the most appropriate way to define the return type. This allows you to explicitly define the data type for each metric (e.g., 'FloatType' for 'average_price', 'Integer Type' for 'customer_count'), ensuring type safety and efficient data processing. 'VariantType' (Option A) would store the dictionary as a semi-structured data type, but you'd lose the benefits of explicit type definitions for each metric. 'MapType' (Option B) is more appropriate for representing a map with keys and values, not a fixed set of named metrics. Serializing to JSON (Option D) adds overhead and loses type information. 'ArrayType' (Option E) is not suitable for dictionaries. 'StructType' enforces a schema upon the returned data.
NEW QUESTION # 15
You have a Snowpark DataFrame named 'products_df' with columns 'product_id' (INT), 'product_name' (VARCHAR), and 'price' (FLOAT). You want to create a new DataFrame called 'discounted_products df that includes all columns from 'products_df' plus a new column named 'discounted_price', which is calculated as the original price minus a discount percentage specified by the variable 'discount_rate' (e.g., 0.1 for 10%). The 'discount_rate' is stored in the database table named 'discount_table'. You want to load the rate to variable. Choose the correct ways to achieve this. (Select all that apply)





Answer: A,B,E
Explanation:
Options A, B and D provide valid ways to fetch 'discount_rate' as a single numerical value. And fetch the data and gets the first value from the first row. Similarly, gets the data and return the first row. However, Option C does not have LIMIT 1 and will not work. Option E fetches one row as one array, thus requires rate[0] to compute discounted_price.
NEW QUESTION # 16
You have a Snowpark DataFrame 'df' containing customer data with columns 'customer id', 'name', 'age', and 'city'. You want to filter the DataFrame to include only customers from 'New York' who are older than 30, then extract the 'customer id' and 'name' into a Rows object, and finally print the 'name' of the first row in the Rows object. Which of the following code snippets correctly achieves this using Snowpark Python?





Answer: B
Explanation:
The correct answer is C. The code first filters the DataFrame based on the specified conditions. Then, it selects the 'customer_id' and 'name' columns. The 'collect()' method retrieves the data as a list of Rows objects. Finally, correctly accesses the 'name' attribute of the first row in the list. A uses dictionary access which is incorrect for Row objects, B iterates the dataframe and does not get the first row correctly, D accesses the list by index (incorrect approach) and E is only required in scala
NEW QUESTION # 17
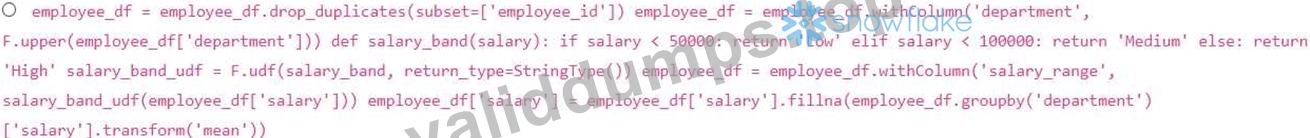
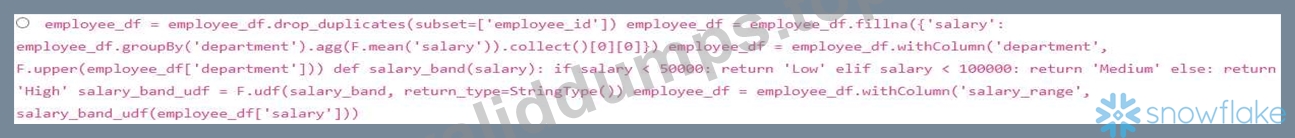
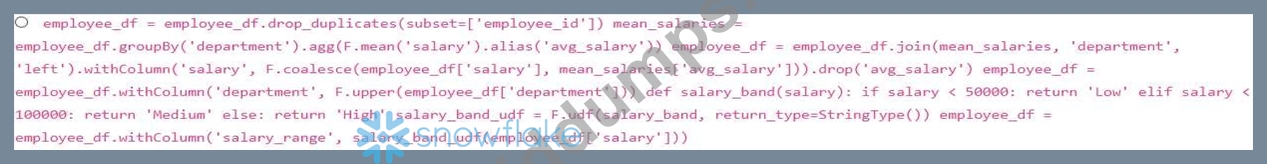
You are using Snowpark to process a DataFrame 'employee df containing employee data, including 'employee_id', 'name' , 'department' , and 'salary'. You need to implement a complex data cleaning and transformation pipeline that involves the following steps: 1. Remove duplicate rows based on 'employee id'. 2. Fill missing 'salary' values with the average salary for the employee's department. 3. Standardize department names by converting them to uppercase. 4. Create a new column 'salary_range' based on the salary. if Salary less than 50k 'Low', greater than 50k and less than 100k 'Medium', greater than 100k 'High'. Which of the following code snippets MOST effectively combines these transformations into a single, readable, and efficient Snowpark pipeline? Assume you have a session object available named 'session' and import necessary modules from 'snowflake.snowpark.functions as F'


Answer: C
Explanation:
Option E is the most efficient and recommended solution for the following reasons: Window Function for Filling Missing Salaries : It uses a window function ('Window.partitionBy('department')') to calculate the average salary for each department efficiently. This is more performant than joining with an aggregated DataFrame or collecting data to the client. No Client-Side Data Handling : All transformations are performed within Snowflake using Snowpark DataFrame operations. This avoids bringing data to the client, which is crucial for performance. Concise 'salary_range' Logic : It uses 'F.when' to define the 'salary_range' column in a concise and readable manner. The chained 'when' calls are a standard way to define conditional column values. Avoids UDF when not Necessary : It avoids using a UDF for calculating 'salary_range' , which generally has overhead compared to built-in functions. Option A computes the average salaries for each department and join again to the original dataframe, which requires more resources. Using UDF is also less performant when there is function available. Option B does not fill nulls before creating salary ranges. Option C collect data on Client side and is inefficient. Option D fillna method is not available and again, the UDF is less performant as it is not necessary.
NEW QUESTION # 18
......
As you see, all of the three versions of our SPS-C01 exam dumps are helpful for you to get the SPS-C01 certification. So there is another choice for you to purchase the comprehensive version which contains all the three formats. And no matter which format of SPS-C01 study engine you choose, we will give you 24/7 online service and one year's free updates. Moreover, we can assure you a 99% percent pass rate.
SPS-C01 Related Exams: https://www.validdumps.top/SPS-C01-exam-torrent.html