あなたの社会生活で成功し、高い社会的地位を所有するためには、あなたはいくつかの分野で十分な能力と十分な知識を所有しなければなりません。テストAI-500試験に合格すると、これらの目標を達成し、有能であることを証明できます。 AI-500模擬テストを購入すると、AI-500試験に流passに合格し、学習にかかる時間と労力が少なくて済みます。 AI-500テスト問題の質問と回答は入念に選択されており、重要な情報を簡素化して学習をリラックスして効率的にしています。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 3: Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Topic 4: Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
>> Microsoft AI-500日本語版サンプル <<
PassTestはIT試験問題集を提供するウエブダイトで、ここによく分かります。最もよくて最新で資料を提供いたします。こうして、君は安心で試験の準備を行ってください。弊社の資料を使って、100%に合格を保証いたします。もし合格しないと、われは全額で返金いたします。PassTestはずっと君のために最も正確なMicrosoftのAI-500「Designing and Implementing Multi-Agent AI Solutions」試験に関する資料を提供して、君が安心に選択することができます。君はオンラインで無料な練習問題をダウンロードできて、100%で試験に合格しましょう。
質問 # 24
You have a multi-agent solution hosted in an Azure App Service plan.
You use Azure App Configuration to store runtime settings.
A release adds a new planner agent and changes the prompt routing
You need to recommend a release plan that meets the following requirements:
* Slowly rolls out the release to users
* Uses end-user health alerts as rollout gates
* Increases exposure without redeploying the application
* Limits production exposure until the health metrics remain green
* Implements the solution without deploying a second environment
What should you recommend? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.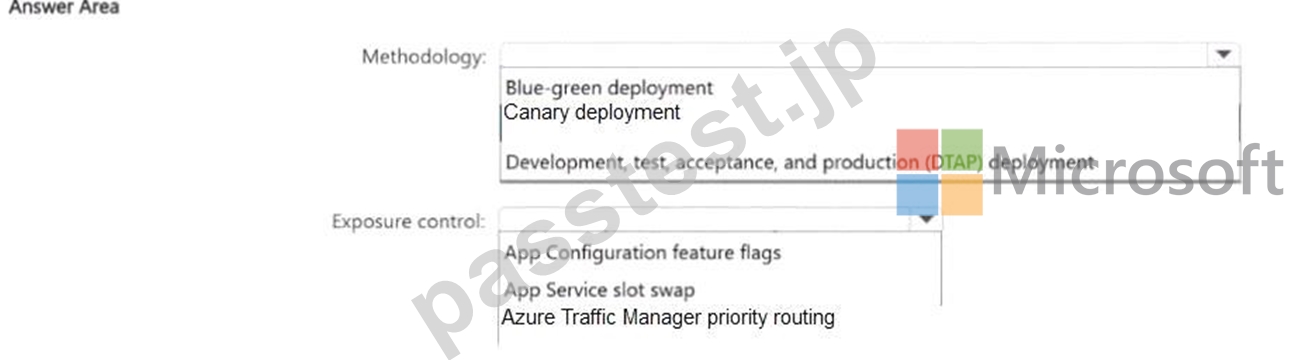
正解:
解説: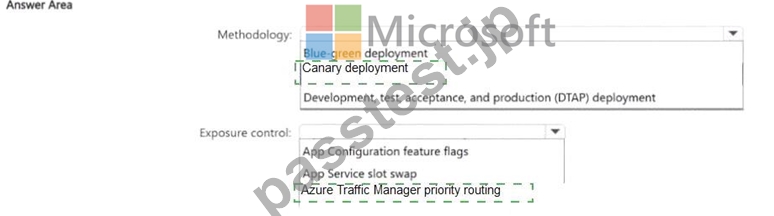
Explanation:
Methodology: Canary deployment; Exposure control: Azure App Configuration feature flags.
A canary release deliberately exposes a new behavior to a limited subset of users and expands that exposure only when operational health remains acceptable. That directly matches the requirement to use end-user health alerts as rollout gates. Azure App Configuration feature flags provide the runtime control needed to change the exposed percentage or audience without redeploying the application. Microsoft documents feature management as a way to decouple deployment from release, which is essential here because the application must stay in one environment while exposure changes. Blue/green deployment normally maintains a second production-like environment or slot, conflicting with the stated constraint. DTAP describes environment progression but not the requested gradual production exposure. Therefore canary plus App Configuration feature flags satisfies gradual rollout, health gating, dynamic exposure, and the no-second-environment requirement. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Azure App Configuration - feature management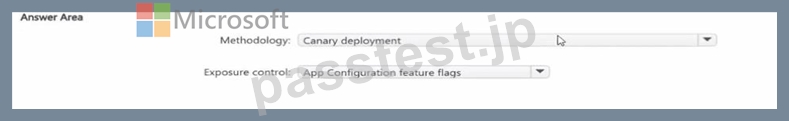
質問 # 25
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.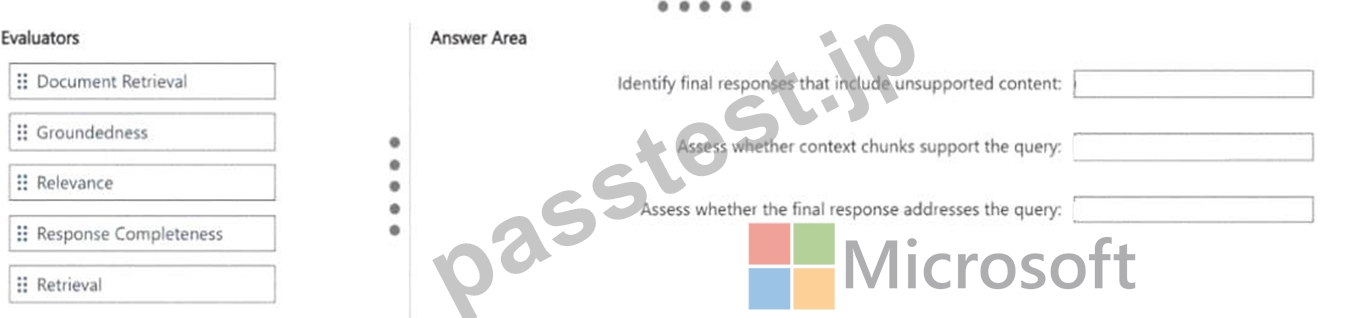
正解:
解説: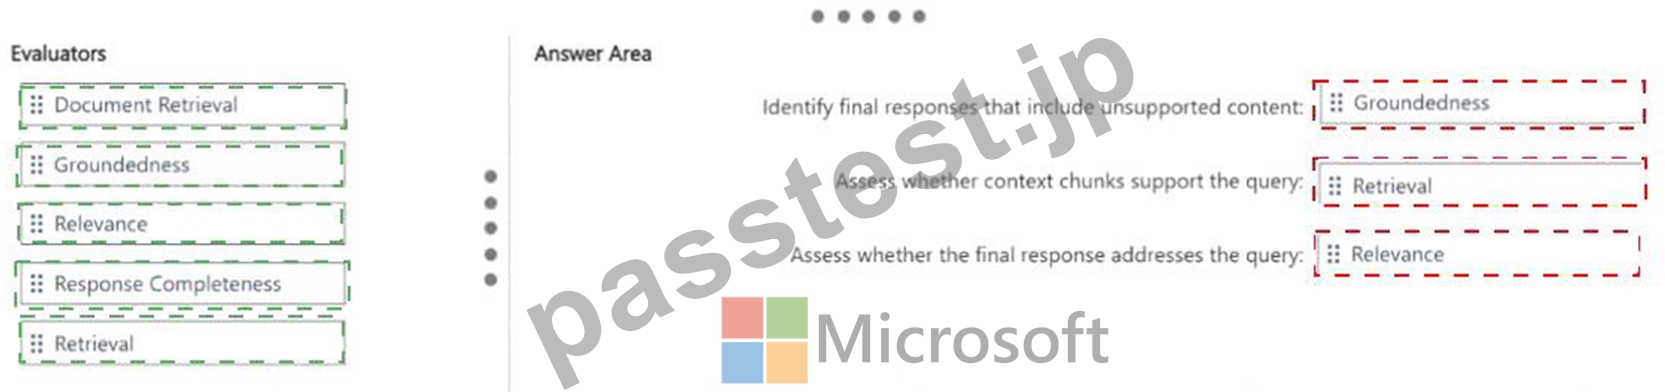
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators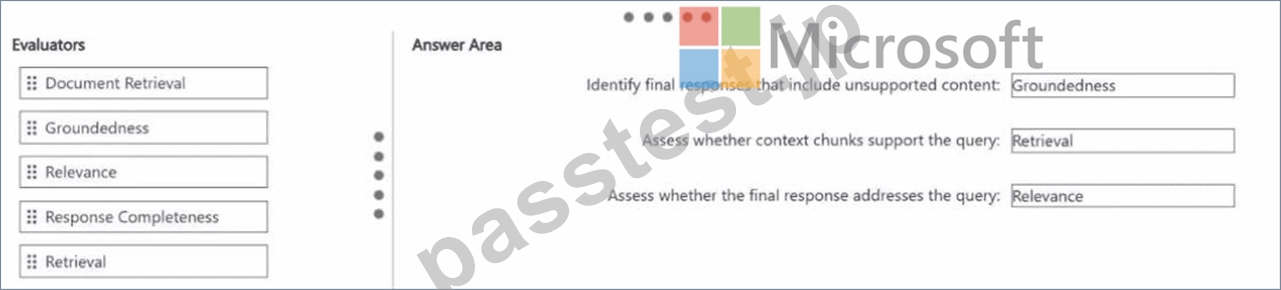
質問 # 26
You have a Microsoft Agent Framework solution for customer support that includes the following agents:
* A triage agent
* A refund specialist agent that runs in the same process as the triage agent
* A compliance review agent that is exposed by a partner team as a remote service You need to identify which integration components the triage agent will use to coordinate interactions with the other agents.
What should you identify for each agent? To answer, drag the appropriate components to the correct agents Each component may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.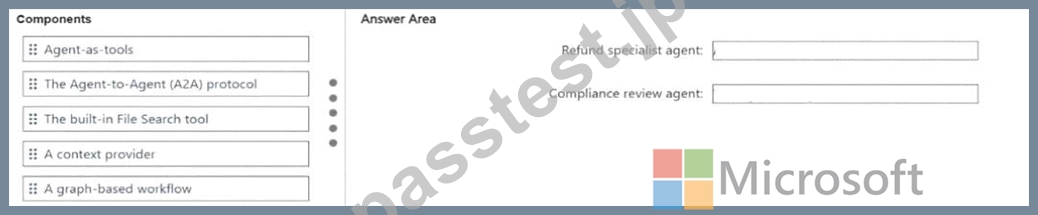
正解:
解説: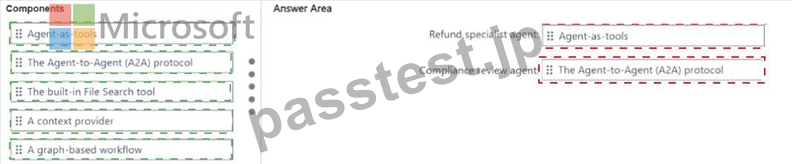
Explanation:
Refund specialist agent: Agent-as-tools; Compliance review agent: Agent-to-Agent (A2A) protocol.
The refund specialist runs in the same process as the triage agent, so exposing it as an agent-as-tool is the lightweight composition pattern. The outer triage agent can decide when to invoke the specialist while retaining overall task ownership. The compliance reviewer is different: it is a remote service owned by a partner team. Agent-to-Agent (A2A) is the interoperable protocol intended for independently hosted agents that may use a different runtime or framework. It supports capability discovery and remote task interaction without coupling the caller to the partner ' s implementation. Using A2A for the in-process specialist would add unnecessary network/protocol complexity, while treating the partner agent as an in-process tool would not match the deployment boundary. The two selections therefore reflect Microsoft ' s distinction between local agent composition and remote agent interoperability. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - agents as tools and A2A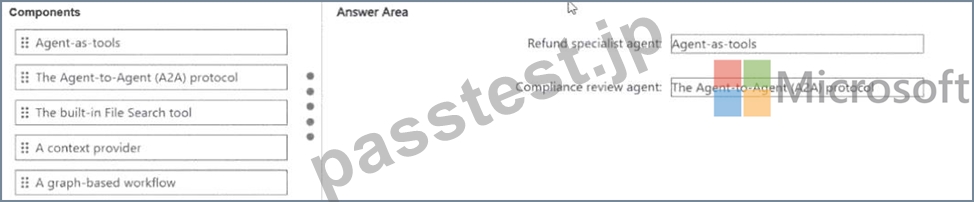
質問 # 27
You have a single-agent customer support copilot built by using Microsoft Foundry. The application that hosts the copilot runs on multiple stateless instances, and rolling upgrades restart the instances.
[Architect multi-agent solutions]
Customer investigations can last for several days. A user can have multiple unrelated investigations, and stable user preferences, such as a preferred contact method, must be available across sessions and devices Compliance reporting requires a one-year, queryable audit trail of thread messages and session metadata.
During long investigations, the model context window regularly approaches its limits. Temporary tool traces do NOT affect final outcomes after the run completes.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.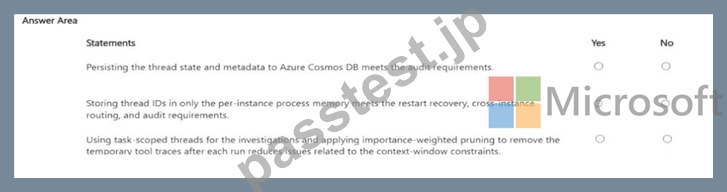
正解:
解説: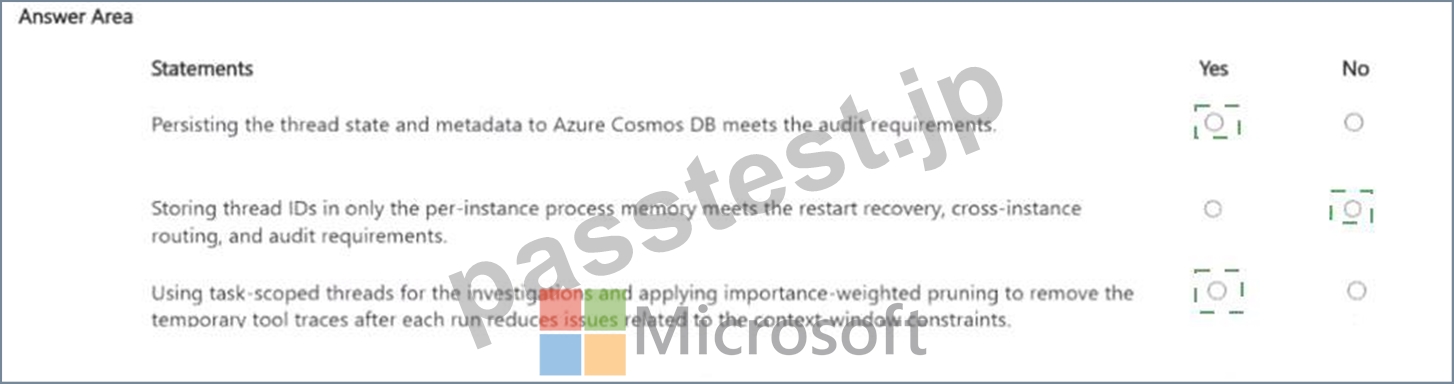
Explanation:
Yes / No / Yes
Persisting thread messages and session metadata in Azure Cosmos DB can satisfy the requirement for a durable, queryable audit trail when the appropriate retention and indexing policies are configured. Storing thread identifiers only in per-instance memory cannot survive rolling restarts and cannot support consistent routing across multiple stateless instances, so that statement is false. Separating unrelated investigations into task-scoped threads prevents one case from consuming the context budget of another. Removing temporary tool traces after the run when they no longer influence the outcome is also a valid compaction strategy for reducing context pressure. Current Agent Framework terminology commonly refers to this as compaction or tool-result eviction rather than "importance-weighted pruning," but the architectural effect described is sound.
Therefore the correct sequence is Yes, No, Yes. This choice also keeps the design composable as more agents are introduced. Clear interfaces, trust boundaries, and state ownership let a team change one domain without forcing unrelated agents to adopt the same permissions, context, or execution model.
Official Microsoft reference: Microsoft Foundry Agent Service - standard setup and durable state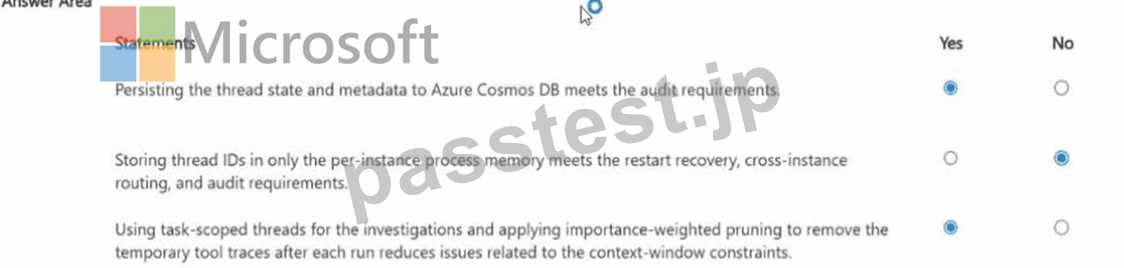
質問 # 28
You have a Microsoft Foundry multi-agent solution for loan applications. Each agent scores a full application independently and does NOT require output from other agents.
You need to recommend an orchestration pattern that meets the following requirements:
Produces one aggregated recommendation
Preserves independent scoring -
Minimizes end-to-end latency -
Minimize development effort -
What should you recommend?
正解:B
解説:
The scoring agents do not depend on each other ' s output, so their work should be fanned out in parallel and aggregated afterward. Microsoft Agent Framework concurrent orchestration is intended for independent participants that can process the same input simultaneously. That minimizes end-to-end latency because completion time approaches the slowest individual scorer instead of the sum of all scorers. The concurrent workflow also provides a fan-in stage that can aggregate the separate scores into one recommendation without requiring a complex custom conversation protocol. Sequential orchestration wastes time by serializing independent work. Group chat and Magentic-style collaboration introduce unnecessary coordination and planning overhead when the agents simply need independent scoring. Therefore D, concurrent, is the simplest and fastest orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
質問 # 29
......
AI-500認証試験はあなたのIT専門知識を検査する認証試験で、あなたの才能を生かすチャンスです。AI-500資格を取得したいなら、我々の資料はあなたの要求を満たすことができます。試験の前に、我々の提供する参考書を利用して、短時間であなたは大きな収穫を得られることができます。我々のAI-500参考書を速く入手しましょう。
AI-500専門知識: https://www.passtest.jp/Microsoft/AI-500-shiken.html