BONUS!!! Download part of BraindumpQuiz Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1mlGrrzy83ph-nw67pJB3QR1cnOfbwN1n
We all know that pass the Data-Engineer-Associate exam will bring us many benefits, but it is not easy for every candidate to achieve it. The Data-Engineer-Associate guide torrent is a tool that aimed to help every candidate to pass the exam. Our exam materials can installation and download set no limits for the amount of the computers and persons. We guarantee you that the Data-Engineer-Associate Study Materials we provide to you are useful and can help you pass the test. Once you buy the product you can use the convenient method to learn the Data-Engineer-Associate exam torrent at any time and place.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
| Topic 2: Data Ingestion and Transformation | 34% | - Perform data ingestion
|
| Topic 3: Data Store Management | 26% | - Understand data cataloging
|
| Topic 4: Data Security and Governance | 18% | - Apply authentication and authorization
|
>> Data-Engineer-Associate New Exam Braindumps <<
If you are quite worried about you exam and want to pass the exam successfully, you can choose us. Data-Engineer-Associate training materials is high quality and valid. They can help you prepare for and pass your exam easily. We have experienced experts compile Data-Engineer-Associate exam braindumps, therefore the quality can be guaranteed. Besides, Data-Engineer-Associate Training Materials cover most knowledge points for the exam, and you can master most knowledge for the exam. We provide you with free update for one year for Data-Engineer-Associate exam dumps, that is to say, you can obtain the latest information for the exam timely.
NEW QUESTION # 215
A company has a data processing pipeline that runs multiple SQL queries in sequence against an Amazon Redshift cluster. The company merges with a second company. The original company modifies a query that aggregates sales revenue data to join sales tables from both companies.
The sales table for the first company is named Table S1 and contains 10 billion records. The sales table for the second company is named Table S2 and contains 900 million records. The query becomes slow after the modification.
A data engineer must improve the query performance.
Which solutions will meet these requirements? (Select TWO)
Answer: D,E
Explanation:
Amazon Redshift query performance for large joins depends heavily on data distribution and query optimization. Using the KEY distribution style on both tables ensures that rows with the same join key are co-located on the same compute nodes, minimizing costly data redistribution during joins.
Selecting a high-cardinality column as the distribution key is critical to evenly distribute data across nodes and prevent data skew. Low-cardinality keys can cause hotspots where too much data resides on a small number of nodes, degrading performance.
Using EVEN distribution on the 10-billion-row table and ALL distribution on the 900-million-row table is inefficient because ALL distribution replicates the entire table to every node, which is not appropriate for large datasets. The Amazon Redshift query optimizer operates automatically and does not require manual selection.
Amazon Redshift Advisor analyzes workload patterns and provides actionable recommendations for distribution styles, sort keys, and query optimizations. Using Redshift Advisor allows the data engineer to apply proven optimizations based on actual cluster usage.
Therefore, combining KEY distribution with a high-cardinality join column and leveraging Amazon Redshift Advisor recommendations is the most effective solution to improve query performance.
NEW QUESTION # 216
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?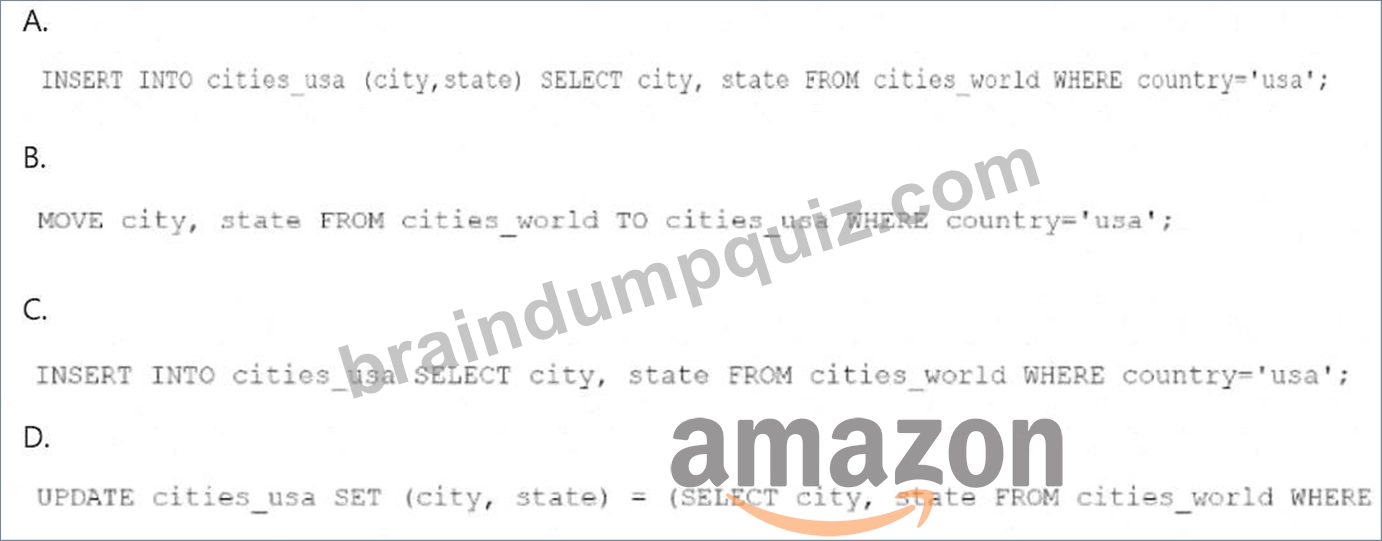
Answer: B
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 217
A company receives marketing campaign data from a vendor. The company ingests the data into an Amazon S3 bucket every 40 to 60 minutes. The data is in CSV format. File sizes are between 100 KB and 300 KB.
A data engineer needs to set-up an extract, transform, and load (ETL) pipeline to upload the content of each file to Amazon Redshift.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
NEW QUESTION # 218
A data engineer needs to use AWS Step Functions to design an orchestration workflow. The workflow must parallel process a large collection of data files and apply a specific transformation to each file.
Which Step Functions state should the data engineer use to meet these requirements?
Answer: D
Explanation:
Option C is the correct answer because the Map state is designed to process a collection of data in parallel by applying the same transformation to each element. The Map state can invoke a nested workflow for each element, which can be another state machine or a Lambda function. The Map state will wait until all the parallel executions are completed before moving to the next state.
Option A is incorrect because the Parallel state is used to execute multiple branches of logic concurrently, not to process a collection of data. The Parallel state can have different branches with different logic and states, whereas the Map state has only one branch that is applied to each element of the collection.
Option B is incorrect because the Choice state is used to make decisions based on a comparison of a value to a set of rules. The Choice state does not process any data or invoke any nested workflows.
Option D is incorrect because the Wait state is used to delay the state machine from continuing for a specified time. The Wait state does not process any data or invoke any nested workflows.
Reference:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 5: Data Orchestration, Section 5.3: AWS Step Functions, Pages 131-132 Building Batch Data Analytics Solutions on AWS, Module 5: Data Orchestration, Lesson 5.2: AWS Step Functions, Pages 9-10 AWS Documentation Overview, AWS Step Functions Developer Guide, Step Functions Concepts, State Types, Map State, Pages 1-3
NEW QUESTION # 219
A data engineer wants to optimize the runtime performance of an AWS Glue extract, transform, and load (ETL) job. The job processes large JSON files from Amazon S3. The job currently reads all fields from the source files but transforms only a subset of the fields.
Which solution will meet these requirements?
Answer: D
Explanation:
The correct answer is B because the performance issue is caused by reading unnecessary data. The best optimization is to reduce the amount of data and schema fields that the AWS Glue job reads before transformation. Pushdown-style filtering and selecting only required fields reduce scan and serialization overhead, especially when the job transforms only a subset of the JSON structure. Job bookmarks help track previously processed data, but they do not reduce the amount of data read within each file. Splitting the job into several smaller jobs increases orchestration and does not solve unnecessary field reads. An AWS Glue crawler catalogs metadata; it does not convert JSON files into Parquet. Therefore, restricting the source schema and pushing filtering closer to the source is the best available answer.
NEW QUESTION # 220
......
Exam candidates hold great purchasing desire for our Data-Engineer-Associate study questions which contribute to successful experience of former exam candidates with high quality and high efficiency. So our Data-Engineer-Associatepractice materials have great brand awareness in the market. They can offer systematic review of necessary knowledge and frequent-tested points of the Data-Engineer-Associate Learning Materials. You cam familiarize yourself with our Data-Engineer-Associate practice materials and their contents in a short time.
Data-Engineer-Associate Exam Cram Questions: https://www.braindumpquiz.com/Data-Engineer-Associate-exam-material.html
What's more, part of that BraindumpQuiz Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1mlGrrzy83ph-nw67pJB3QR1cnOfbwN1n