What's more, part of that PracticeMaterial SPS-C01 dumps now are free: https://drive.google.com/open?id=1G1PMhS1rEPiH2mgPw6HY4o9AMmm2ptD-
PracticeMaterial offers up to 1 year of free Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions updates. With our actual questions, you can prepare for the SPS-C01 exam without missing out on any point you need to know. These exam questions provide you with all the necessary knowledge that you will need to clear the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam with a high passing score.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 6: Data Engineering with Snowpark | - Pipeline development
|
We would like to benefit our customers from different countries who decide to choose our SPS-C01 study guide in the long run, so we cooperation with the leading experts in the field to renew and update our SPS-C01 study materials. We can assure you that you will get the latest version of our SPS-C01 Training Materials for free from our company in the whole year after payment. Do not miss the opportunity to buy the best SPS-C01 preparation questions in the international market which will also help you to advance with the times.
NEW QUESTION # 261
You have a Snowpark DataFrame with columns 'sale_date', 'product_id', and 'revenue'. You need to calculate the cumulative revenue for each product over time. Which of the following approaches will accomplish this in Snowpark using window functions?





Answer: D,E
Explanation:
Options A and E both achieve the desired result of calculating cumulative revenue for each product. Option A utilizes 'rowsBetween' specifying that the window frame should include all rows from the beginning ('Window.unboundedPreceding') up to the current row ('Window.currentRow'). This calculates a running sum of revenue for each product over time. Option E uses 'rangeBetween' , which is equivalent to when the order-by expression is of a numeric or date type. Option B does not partition by product_id, so the cumulative revenue is calculated over the entire dataset. Option C does not include frame specification 'rowsBetween()' or 'rangeBetween(Y , therefore defaults to 'RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW, which is valid for this question. While it's functionally correct, it's implicit, so 'A' is preferrable if one option is to be selected. Option D partitions incorrectly by sale_date.
NEW QUESTION # 262
You have a requirement to create Snowpark DataFrames from CSV files located in an AWS S3 external stage. Some CSV files have a header row, while others do not. The files also use different delimiters (comma, semicolon, or tab). You want to create a single function that can handle all these variations, without creating separate functions for each combination. The 'create_dataframe' function receives the stage path, the delimiter, and a boolean indicating whether a header is present. Which of the following code snippets, when implemented inside the function, BEST achieves this goal using the Snowpark Python API? Assume a Snowpark session 'session'.





Answer: B
Explanation:
Option D is the best approach. It correctly handles both delimiter and header options for CSV files using the correct option names ('field_delimiter' and 'skip_header'). The 'skip_header' option requires '0' or '1', not a boolean. Option A will throw exception as it uses incorrect option name. Option B will throw exception as hasHeader is expecting 0 or 1. Option C uses 'skip_header' but this option does not exist in snowpark DataFrameReader option E will throw exception as 'format' method should be called before 'options' method.
NEW QUESTION # 263
You are developing a Snowpark application that performs feature engineering on a dataset of customer transactions. This involves calculating several complex aggregate features such as rolling averages, medians, and custom ratios. You want to optimize the performance of this feature engineering process using a Snowpark-optimized warehouse. Which of the following strategies would be MOST effective in achieving optimal performance?
Answer: A,E
Explanation:
Using 'GROUP BY and window functions allows Snowflake to optimize the calculations within its engine. Leveraging UDTFs allows custom computations while still benefiting from Snowflake's optimization capabilities. Python UDFs are generally slower than equivalent SQL or Java/Scala UDTFs due to inter-process communication overhead. Materializing intermediate DataFrames can help in some scenarios but can also introduce overhead if not managed carefully. Java Stored procedures could be used, but UDTF would be more optimized way.
NEW QUESTION # 264
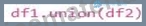
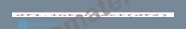
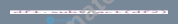
You have two Snowpark DataFrames, 'dfl' and 'df2, representing customer data'. 'dfl' contains columns 'CUSTOMER ID', 'NAME, and 'EMAIL', while 'df2 contains 'CUSTOMER ID' and 'PURCHASE AMOUNT'. You need to create a new DataFrame that combines the information from both DataFrames but only includes customers who exist in BOTH 'dfl ' and 'df2 and the resulting DataFrame should have columns from both. Which of the following Snowpark DataFrame operations should you use, and what is the correct way to call it?


Answer: A,E
Explanation:
To include only customers present in BOTH DataFrames and include columns from both, you need to perform an INNER JOIN. Options B, C and D are incorrect: intersect, union and subtract operations work at a row level. Also, intersect , union and subtract operations expects the number of columns and datatypes to match and is not relevant to the described scenario. Option A and E are valid way to use the join operation: (A) uses the explicit condition 'dfl .CUSTOMER_ID df2.CUSTOMER_lD while (E) is the short form which specifies the column name directly. Both achieves the same inner join behavior. You can choose E as a cleaner option when only joining on column name.
NEW QUESTION # 265
You have a Snowpark DataFrame named with columns 'category', , and You want to perform the following transformations using Snowpark:





Answer: C
Explanation:
Option E is correct, because the 'pivot' operation needs to be inside 'groupBy' . It first groups the data by 'category', then pivots the data based on the 'date' column, aggregating the 'value' column using the sum function. Options A,B,C, and D, will cause a Snowflake error.
NEW QUESTION # 266
......
If you feel that you always suffer from procrastination and cannot make full use of your spare time, maybe our SPS-C01 study materials can help you solve your problem. We are willing to recommend you to try the SPS-C01 study materials from our company. Our SPS-C01 training guide are high quality and efficiency test tools for all people. If you buy our SPS-C01 Preparation questions, we can promise that you can use our SPS-C01 study materials for study in anytime and anywhere. Because we have three version of SPS-C01 exam questions that can satisfy all needs of our customers.
Latest SPS-C01 Test Report: https://www.practicematerial.com/SPS-C01-exam-materials.html
DOWNLOAD the newest PracticeMaterial SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1G1PMhS1rEPiH2mgPw6HY4o9AMmm2ptD-