ちなみに、PassTest MLA-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1l_6BJAxUzY2brgKDpnlhmf6pIEy1WpwV
クライアントが当社のMLA-C01ガイド資料の習熟度を理解し、テストの準備を整えるために、テストプラクティスソフトウェアをクライアントに提供します。 MLA-C01実践ガイドのテスト実践ソフトウェアは、実際のテスト問題に基づいており、そのインターフェースは使いやすいです。テスト練習ソフトウェアは、実際のテストを刺激し、複数の練習モデル、MLA-C01トレーニング教材の練習の履歴記録、自己評価機能を高めるテストスキームを向上させます。
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Exam Duration: | 170 minutes |
| Exam Price: | 150 USD |
| Real Exam Qty: | 85 |
| Exam Format: | Multiple response, Multiple choice |
| Certificate Validity Period: | 3 years |
| Related Certifications: | AWS Certified Solutions Architect - Associate AWS Certified Developer - Associate AWS Certified Data Engineer - Associate |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Available Languages: | Japanese, Traditional Chinese, Korean, English, Simplified Chinese |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
競争がますます激しいIT業種では、AmazonのMLA-C01試験の認定は欠くことができない認証です。最も早い時間でAmazonのMLA-C01認定試験に合格したいなら、PassTestのAmazonのMLA-C01試験トレーニング資料を利用すればいいです。もしうちの学習教材を購入した後、試験に不合格になる場合は、私たちが全額返金することを保証いたします。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
質問 # 122
A company has implemented a data ingestion pipeline for sales transactions from its ecommerce website. The company uses Amazon Data Firehose to ingest data into Amazon OpenSearch Service. The buffer interval of the Firehose stream is set for 60 seconds. An OpenSearch linear model generates real-time sales forecasts based on the data and presents the data in an OpenSearch dashboard.
The company needs to optimize the data ingestion pipeline to support sub-second latency for the real-time dashboard.
Which change to the architecture will meet these requirements?
正解:D
解説:
The primary requirement in this scenario is achieving sub-second latency for a real-time analytics dashboard powered by Amazon OpenSearch Service. The current architecture uses Amazon Data Firehose, which buffers incoming records based on time or size before delivering them to the destination. A buffer interval of
60 seconds introduces unavoidable latency, making it unsuitable for near-real-time or sub-second use cases.
According to AWS documentation, reducing or eliminating buffering in Firehose is the correct approach when low-latency ingestion is required. Setting the Firehose buffer interval to zero seconds forces Firehose to deliver records as soon as they are received. Additionally, tuning the PutRecordBatch batch size allows efficient ingestion while minimizing delivery delay. This configuration is explicitly recommended for latency- sensitive analytics pipelines.
Option B is incorrect because AWS DataSync is designed for batch-oriented data transfers between storage systems, not real-time streaming. Enhanced fan-out consumers are a feature of Amazon Kinesis Data Streams, not DataSync, making this option invalid.
Option C directly contradicts the requirement. Increasing the buffer interval from 60 seconds to 120 seconds would further increase latency and degrade real-time performance.
Option D is also incorrect because Amazon SQS is a message queueing service, not a streaming ingestion service optimized for indexing data into OpenSearch with minimal latency. Using SQS would add additional processing layers and would not inherently provide sub-second ingestion into OpenSearch.
Therefore, using zero buffering in the Firehose stream and tuning the PutRecordBatch batch size is the only change that aligns with AWS best practices for achieving sub-second latency in real-time analytics pipelines.
質問 # 123
A company needs to perform feature engineering, aggregation, and data preparation. After the features are produced, the company must implement a solution on AWS to process and store the features. Which solution will meet these requirements?
正解:D
解説:
Amazon SageMaker Feature Processing (via processing jobs) is used to perform feature engineering and data preparation. The engineered features can then be ingested into SageMaker Feature Store, which is a purpose-built service to manage and store ML features for reuse across training and inference. This combination directly addresses the company's requirements.
質問 # 124
An ML engineer is training a simple neural network model. The ML engineer tracks the performance of the model over time on a validation dataset. The model's performance improves substantially at first and then degrades after a specific number of epochs.
Which solutions will mitigate this problem? (Choose two.)
正解:C、D
解説:
Early stopping halts training once the performance on the validation dataset stops improving. This prevents the model from overfitting, which is likely the cause of performance degradation after a certain number of epochs.
Dropout is a regularization technique that randomly deactivates neurons during training, reducing overfitting by forcing the model to generalize better. Increasing dropout can help mitigate the problem of performance degradation due to overfitting.
質問 # 125
An ML engineer wants to deploy an Amazon SageMaker AI model for inference. The payload sizes are less than 3 MB. Processing time does not exceed 45 seconds. The traffic patterns will be irregular or unpredictable.
Which inference option will meet these requirements MOST cost-effectively?
正解:D
解説:
Amazon SageMaker Serverless Inference is designed for irregular or unpredictable traffic patterns. It automatically provisions and scales compute resources based on request volume and scales down to zero when idle, making it the most cost-effective option.
Serverless inference supports payloads up to 6 MB and request durations up to 60 seconds, which comfortably meets the stated constraints. Customers are billed only for actual compute usage during inference execution, not for idle capacity.
Asynchronous inference is intended for long-running jobs (up to 1 hour) and large payloads (up to 1 GB).
Real-time inference requires always-on instances, increasing cost during idle periods. Batch transform is designed for offline processing.
Therefore, serverless inference is the optimal choice.
質問 # 126
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
* Random Cut Forest (RCF) algorithm
* Semantic segmentation algorithm
* Sequence-to-Sequence (seq2seq) algorithm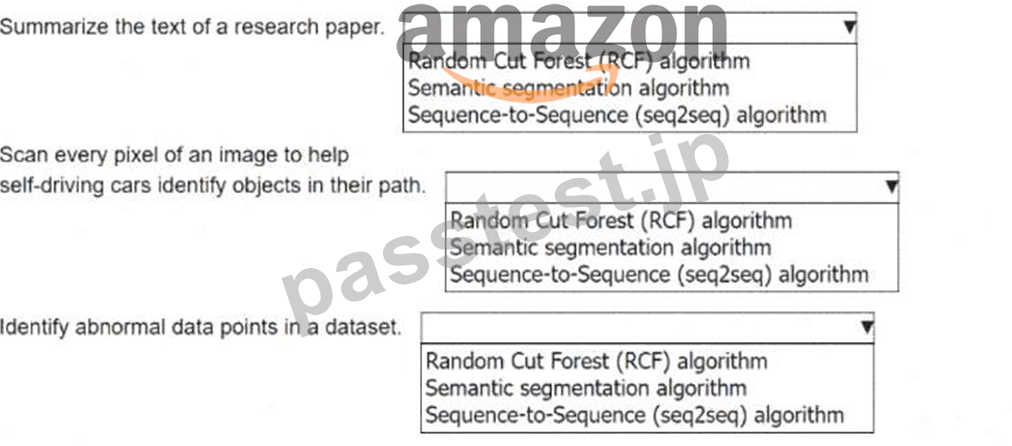
正解:
解説: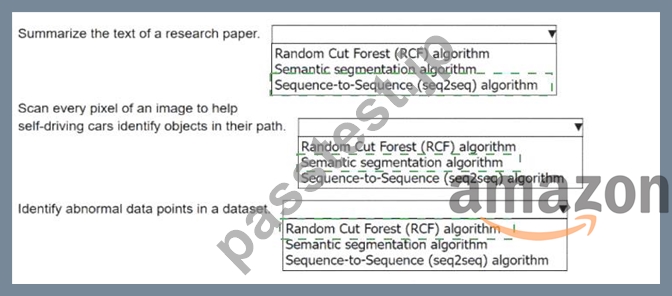
Explanation:
Use case 1:
Summarize the text of a research paper
## Sequence-to-Sequence (seq2seq) algorithm
Why:
Seq2seq models are designed for natural language generation tasks such as text summarization, translation, and paraphrasing. AWS documentation explicitly lists text summarization as a primary use case for the SageMaker seq2seq algorithm.
Use case 2:
Scan every pixel of an image to help self-driving cars identify objects in their path
## Semantic segmentation algorithm
Why:
Semantic segmentation performs pixel-level classification, assigning a class label to every pixel in an image.
This is exactly what is required for applications such as autonomous driving, road scene understanding, and object boundary detection.
Use case 3:
Identify abnormal data points in a dataset
## Random Cut Forest (RCF) algorithm
Why:
Random Cut Forest is an unsupervised anomaly detection algorithm. AWS SageMaker RCF is purpose-built to identify outliers, unusual patterns, and anomalies in numerical datasets, making it ideal for fraud detection, monitoring, and abnormal data point detection.
質問 # 127
......
MLA-C01日本語版: https://www.passtest.jp/Amazon/MLA-C01-shiken.html
P.S. PassTestがGoogle Driveで共有している無料かつ新しいMLA-C01ダンプ:https://drive.google.com/open?id=1l_6BJAxUzY2brgKDpnlhmf6pIEy1WpwV