P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by VCEPrep: https://drive.google.com/open?id=1D_VZv5XkH_L25StCttNkjEEi5b8n9e8y
Keep making progress is a very good thing for all people. If you try your best to improve yourself continuously, you will that you will harvest a lot, including money, happiness and a good job and so on. The DP-100 preparation exam from our company will help you keep making progress. Choosing our DP-100 Study Material, you will find that it will be very easy for you to overcome your shortcomings and become a persistent person. Just come and buy our DP-100 learning guide!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Train and deploy models | 25-30% | - Monitor and maintain models
|
| Topic 2: Explore data and run experiments | 20-25% | - Explore and visualize data
|
| Topic 3: Optimize language models for AI applications | 25-30% | - Evaluate and improve models
|
| Topic 4: Design and prepare a machine learning solution | 20-25% | - Manage data assets
|
As a IT worker sometime you may know you will take advantage of new technology more quickly by farming out computer operations, we prefer to strengthen own strong points. Our DP-100 test braindump materials is popular based on that too. As we all know the passing rate for IT exams is low, the wise choice for candidates will select valid DP-100 test braindump materials to make you pass exam surely and fast. Professional handles professional affairs.
NEW QUESTION # 434
You need to correct the model fit issue.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.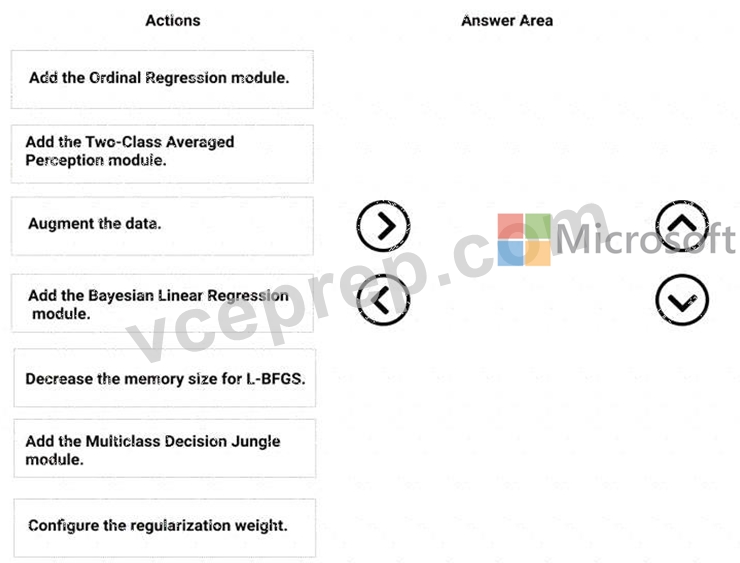
Answer:
Explanation: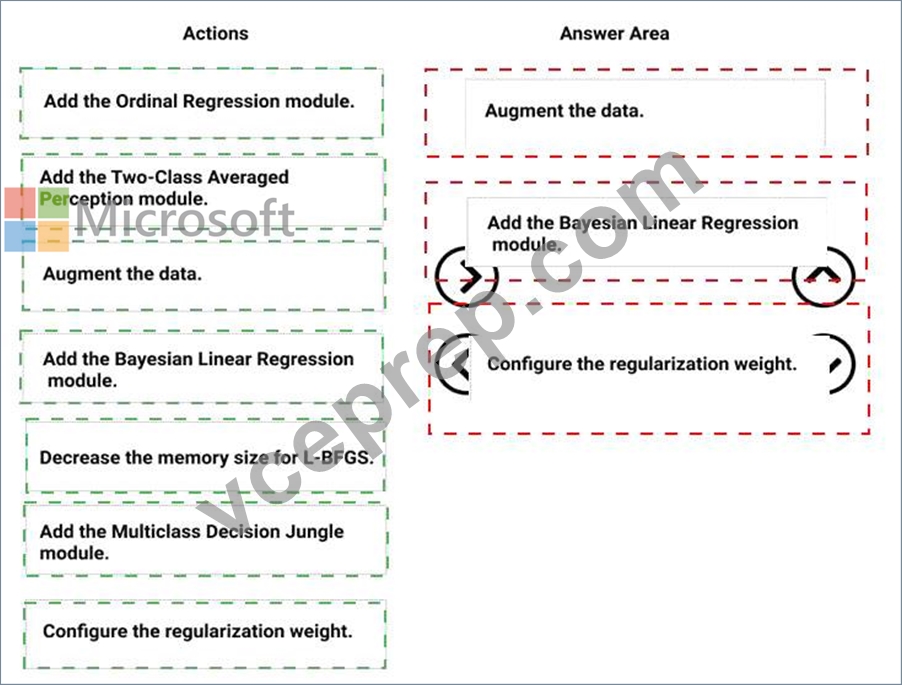
Explanation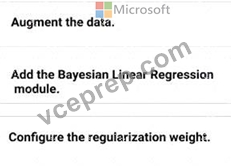
Step 1: Augment the data
Scenario: Columns in each dataset contain missing and null values. The datasets also contain many outliers.
Step 2: Add the Bayesian Linear Regression module.
Scenario: You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Step 3: Configure the regularization weight.
Regularization typically is used to avoid overfitting. For example, in L2 regularization weight, type the value to use as the weight for L2 regularization. We recommend that you use a non-zero value to avoid overfitting.
Scenario:
Model fit: The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
NEW QUESTION # 435
Hotspot Question
You create an Azure Machine Learning dataset containing automobile price data. The dataset includes 10,000 rows and 10 columns. You use the Azure Machine Learning designer to transform the dataset by using an Execute Python Script component and custom code.
The code must combine three columns to create a new column.
You need to configure the code function.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.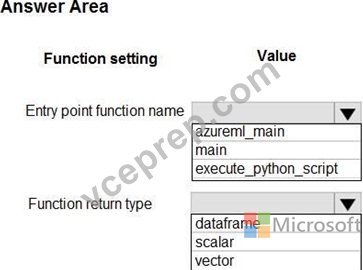
Answer:
Explanation: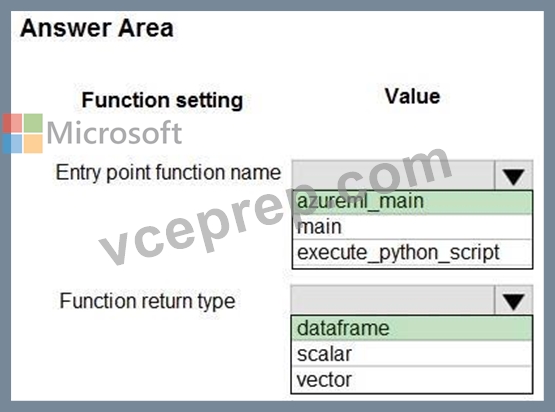
Explanation:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-designer-python#write-your- python-code
NEW QUESTION # 436
You use the Azure Machine Learning service to create a tabular dataset named training.dat a. You plan to use this dataset in a training script.
You create a variable that references the dataset using the following code:
training_ds = workspace.datasets.get("training_data")
You define an estimator to run the script.
You need to set the correct property of the estimator to ensure that your script can access the training.data dataset Which property should you set?
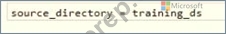



Answer: B
Explanation:
Example:
# Get the training dataset
diabetes_ds = ws.datasets.get("Diabetes Dataset")
# Create an estimator that uses the remote compute
hyper_estimator = SKLearn(source_directory=experiment_folder,
inputs=[diabetes_ds.as_named_input('diabetes')], # Pass the dataset as an input compute_target = cpu_cluster, conda_packages=['pandas','ipykernel','matplotlib'], pip_packages=['azureml-sdk','argparse','pyarrow'], entry_script='diabetes_training.py') Reference:
https://notebooks.azure.com/GraemeMalcolm/projects/azureml-primers/html/04%20-%20Optimizing%20Model%20Training.ipynb
NEW QUESTION # 437
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a model to predict the price of a student's artwork depending on the following variables: the student's length of education, degree type, and art form.
You start by creating a linear regression model.
You need to evaluate the linear regression model.
Solution: Use the following metrics: Accuracy, Precision, Recall, F1 score and AUC.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 438
Hotspot Question
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format.
You must configure an autoscaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.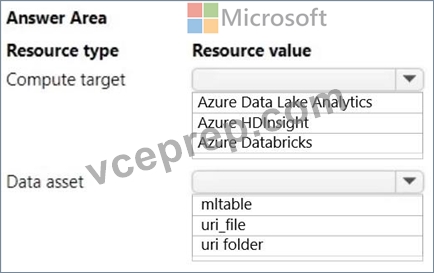
Answer:
Explanation: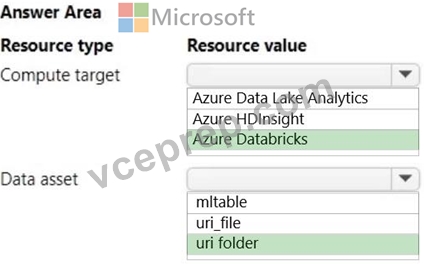
Explanation:
Compute target: Azure Databricks
This is because Azure Databricks supports autoscaling of workers required to run your job, which dynamically reallocates workers to match the computational demands of your job, thereby achieving high cluster utilization without the need for provisioning the cluster to match a specific workload.
Data asset: uri_folder
This option allows the machine learning job to access all the Parquet files stored in the specified directory. If you have multiple Parquet data files, you would use a URI that points to a folder containing all these files.
NEW QUESTION # 439
......
Do you want to pass exam 100% one-shot? Do you want to get certification fast? Microsoft DP-100 actual test question is a good way. If you study hard, 20-40 hours' preparation will help you pass exam. Once you clear DP-100 exam and obtain certification you will have a bright future. You have a great advantage over the other people. Microsoft DP-100 Actual Test questions have effective high-quality content and cover at least more than 88% of the real test questions. Looking for the best exam preparation, ours is the best.
Reliable DP-100 Test Sims: https://www.vceprep.com/DP-100-latest-vce-prep.html
P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by VCEPrep: https://drive.google.com/open?id=1D_VZv5XkH_L25StCttNkjEEi5b8n9e8y