What's more, part of that RealExamFree DP-100 dumps now are free: https://drive.google.com/open?id=1BmcIHxxX-lk8blkI2IJZkNZYr92rHhMy
Microsoft DP-100 can ensure your success. So here comes Microsoft, who provides you with the Microsoft DP-100 exam dumps to get your dream Microsoft DP-100 certification with no hassle. Microsoft DP-100 Certification will add up to your excellence in your field and leave no space for any doubts in the mind of the hiring team.
Microsoft DP-100 (Designing and Implementing a Data Science Solution on Azure) certification exam is designed for data professionals who use Azure technologies to build and implement data science solutions. DP-100 exam measures the candidate's ability to design and implement data storage solutions, data processing solutions, and data analysis solutions using Azure technologies. Candidates who pass the DP-100 exam will receive the Microsoft Certified: Azure Data Scientist Associate certification.
Microsoft DP-100 Certification Exam is a comprehensive exam that covers a wide range of topics related to data science solutions on Azure. DP-100 exam consists of multiple-choice questions and requires the candidate to demonstrate their knowledge and understanding of data science concepts and Azure data science solutions. DP-100 exam is designed to test the candidate’s ability to design and implement data science solutions on Azure.
>> DP-100 Exam Actual Tests <<
As you all know that practicing with the wrong preparation material will waste your valuable money and many precious study hours. So you need to choose the most proper and verified preparation material with caution. Preparation material for the Designing and Implementing a Data Science Solution on Azure (DP-100) exam questions from RealExamFree helps to break down the most difficult concepts into easy-to-understand examples. Also, you will find that all the included questions are based on the last and updated DP-100 exam dumps version.
The Microsoft DP-100 exam consists of approximately 40-60 multiple-choice questions and should be completed within 2 hours. DP-100 exam fee is $165 USD, and candidates can register for the exam through the Microsoft website. DP-100 Exam is available in English, Chinese, Korean, and Japanese, making it accessible to a global audience.
NEW QUESTION # 164
You create a datastore named training_data that references a blob container in an Azure Storage account. The blob container contains a folder named csv_files in which multiple comma-separated values (CSV) files are stored.
You have a script named train.py in a local folder named ./script that you plan to run as an experiment using an estimator. The script includes the following code to read data from the csv_files folder:
You have the following script.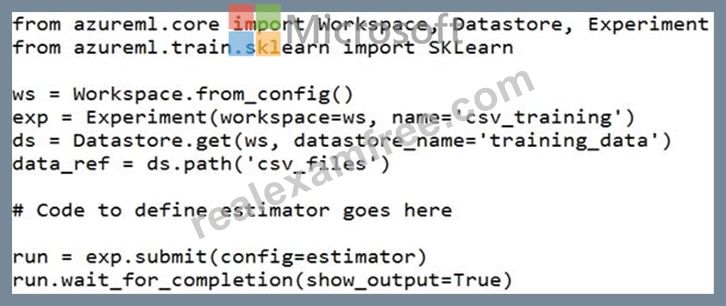
You need to configure the estimator for the experiment so that the script can read the data from a data reference named data_ref that references the csv_files folder in the training_data datastore.
Which code should you use to configure the estimator?
Answer: E
Explanation:
Besides passing the dataset through the inputs parameter in the estimator, you can also pass the dataset through script_params and get the data path (mounting point) in your training script via arguments. This way, you can keep your training script independent of azureml-sdk. In other words, you will be able use the same training script for local debugging and remote training on any cloud platform.
Example:
from azureml.train.sklearn import SKLearn
script_params = {
# mount the dataset on the remote compute and pass the mounted path as an argument to the training script
'--data-folder': mnist_ds.as_named_input('mnist').as_mount(),
'--regularization': 0.5
}
est = SKLearn(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script='train_mnist.py')
# Run the experiment
run = experiment.submit(est)
run.wait_for_completion(show_output=True)
Incorrect Answers:
A: Pandas DataFrame not used.
Reference:
https://docs.microsoft.com/es-es/azure/machine-learning/how-to-train-with-datasets
NEW QUESTION # 165
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code: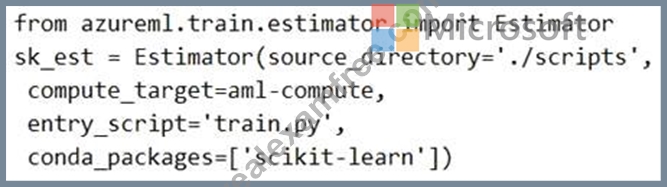
Does the solution meet the goal?
Answer: B
Explanation:
Explanation
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION # 166
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
An IT department creates the following Azure resource groups and resources: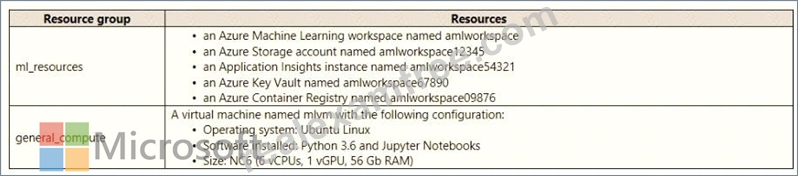
The IT department creates an Azure Kubernetes Service (AKS)-based inference compute target named aks-cluster in the Azure Machine Learning workspace.
You have a Microsoft Surface Book computer with a GPU. Python 3.6 and Visual Studio Code are installed.
You need to run a script that trains a deep neural network (DNN) model and logs the loss and accuracy metrics.
Solution: Attach the mlvm virtual machine as a compute target in the Azure Machine Learning workspace.
Install the Azure ML SDK on the Surface Book and run Python code to connect to the workspace. Run the training script as an experiment on the mlvm remote compute resource.
Answer: B
Explanation:
Explanation
Use the VM as a compute target.
Note: A compute target is a designated compute resource/environment where you run your training script or host your service deployment. This location may be your local machine or a cloud-based compute resource.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
NEW QUESTION # 167
You are using The Azure Machine Learning designer to transform a dataset containing the census data of all nations.
You must use the Split Data component to separate the dataset into two datasets. The first dataset must contain the census data of the United States. The second dataset must include the census data of the remaining nations.
You need to configure the component to create the datasets.
Which configuration values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: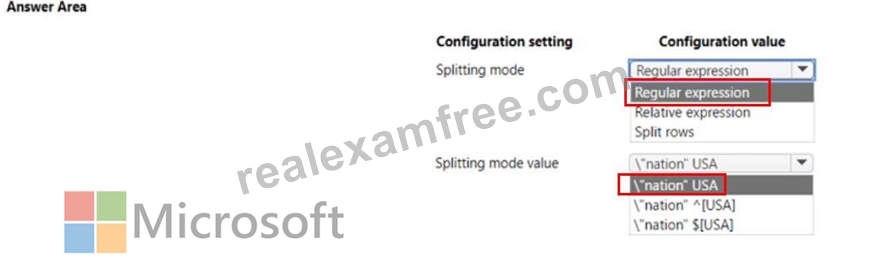
NEW QUESTION # 168
You manage an Azure Machine Learning workspace named workspace1 with a compute instance named compute1. You connect to compute! by using a terminal window from wofkspace1. You create a file named
"requirements.txt" containing Python dependencies to include Jupyler.
You need to add a new Jupyter kernel to compute1.
Which four commands should you use? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.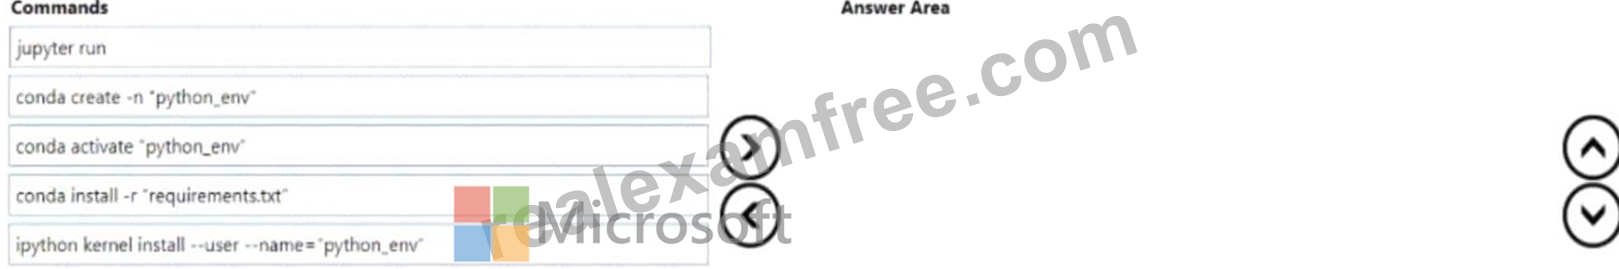
Answer:
Explanation:
Explanation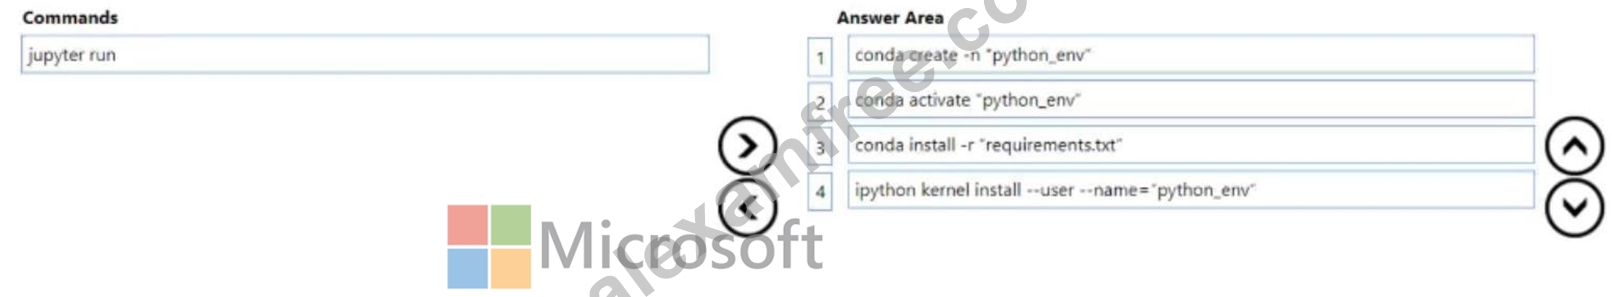
NEW QUESTION # 169
......
Certification DP-100 Torrent: https://www.realexamfree.com/DP-100-real-exam-dumps.html
DOWNLOAD the newest RealExamFree DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BmcIHxxX-lk8blkI2IJZkNZYr92rHhMy