For candidates who are going to pay for AI-300 test materials online, they may care more about the money safety. We apply the international recognition third party for payment, and if you pay for AI-300 exam materials, we can ensure the safety of your money and account. Besides, the third party will also protect your interests. The pass rate for AI-300 testing materials is 98.75%, and we can guarantee you that you can pass the exam just one time. We are pass guarantee and money back guarantee if you fail to pass the exam, and the refund will be returned to your payment account.
| Section | Objectives |
|---|---|
| Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows |
| Design and implement a GenAIOps infrastructure | - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Implement generative AI quality assurance and observability | - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding - Implement logging, tracing, and telemetry for GenAI applications - Conduct red teaming, adversarial testing, and content filtering |
| Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints |
| Optimize generative AI systems and model performance | - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases - Tune prompts, system messages, and grounding strategies - Optimize inference performance, caching, and throughput |
>> AI-300 Latest Test Sample <<
Our AI-300 test questions are compiled by domestic first-rate experts and senior lecturer and the contents of them contain all the important information about the test and all the possible answers of the questions which maybe appear in the test. Our AI-300 test practice guide' self-learning and self-evaluation functions, the statistics report function, the timing function and the function of stimulating the test could assist you to find your weak links and have a warming up for the Real AI-300 Exam. You will feel your choice to buy AI-300 reliable exam torrent is too right.
NEW QUESTION # 159
You manage a Retrieval-Augmented Generation (RAG) system that retrieves internal policy documents from a vector index.
Recent analysis shows that:
Retrieved results frequently include duplicated content from the same document.
Retrieved chunks sometimes span unrelated policy sections.
You review the following retrieval and ingestion configurations: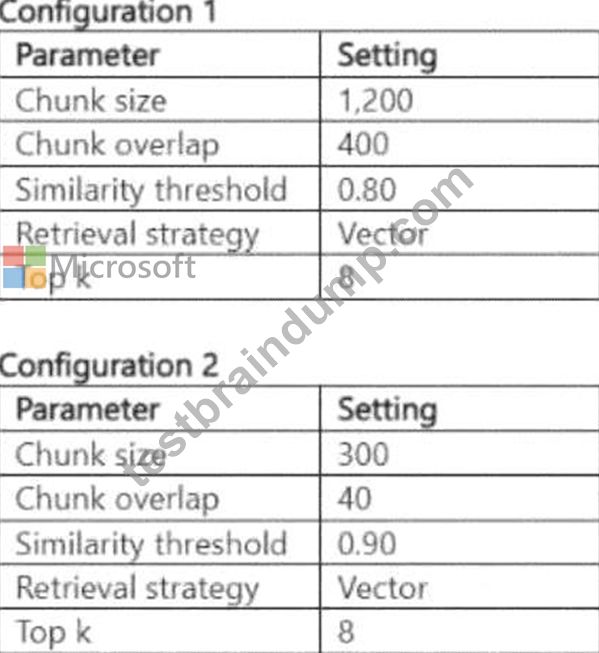
You need to reduce duplicated retrieval results and improve chunk relevance across policy sections.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.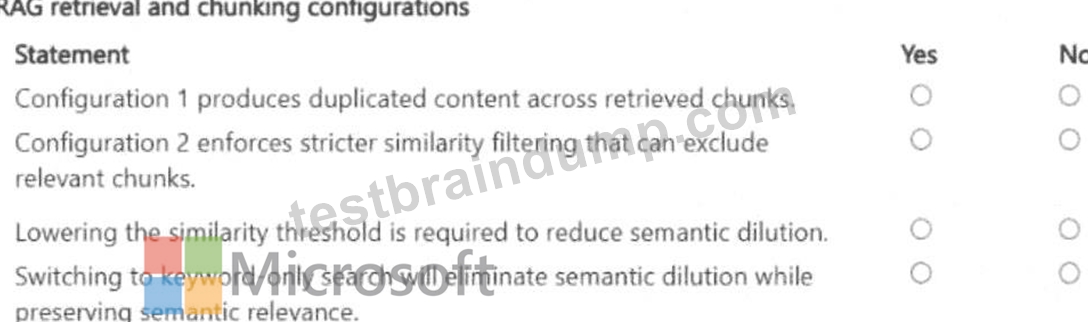
Answer:
Explanation: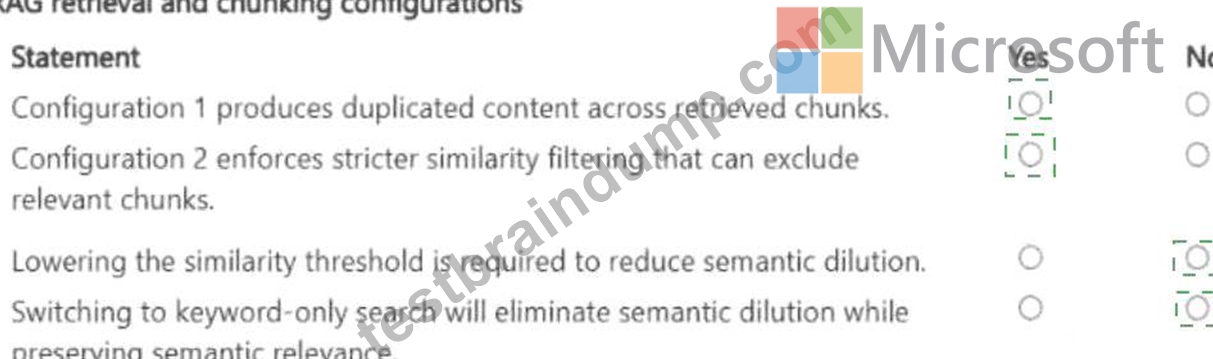
Explanation:
Two distinct RAG problems require two distinct solutions. When retrieved results frequently include duplicated content from the same document, the cause is overlapping chunks receiving similarly high similarity scores. The solution is Maximum Marginal Relevance reranking, which diversifies the result set by penalizing results that are semantically similar to already-selected results, reducing redundancy. When retrieved chunks sometimes span unrelated policy sections, the cause is fixed-size character chunking that splits content without regard for semantic boundaries. The solution is semantic chunking - splitting on natural sentence or section boundaries - ensuring each chunk is semantically coherent and does not straddle unrelated content. Both problems must be addressed together: reranking alone solves duplication but not relevance; semantic chunking alone solves relevance but not duplication.
Microsoft Learn Reference Topic: Optimize RAG retrieval in Azure AI Search - Chunking strategies and MMR reranking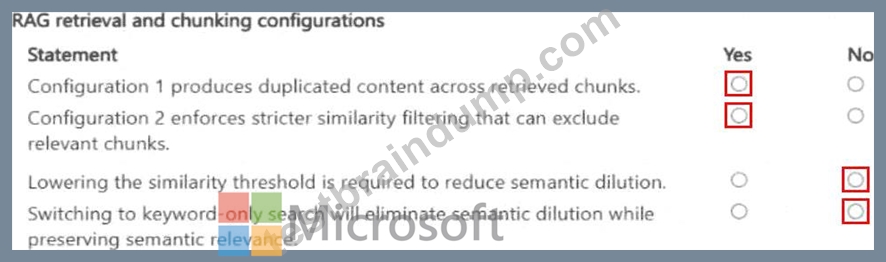
NEW QUESTION # 160
A data science team trains a classification model that predicts loan approval outcomes.
Before registering the model, the team must ensure the following:
Predictions must not disproportionately impact protected groups.
Prediction errors can be evaluated across different data segments.
You need to assess whether the model meets Responsible AI expectations.
Which two approaches should you use? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
Answer: B,C
Explanation:
A loan approval model must be assessed for both transparency and demographic fairness before registration.
Option D (feature importance) addresses prediction transparency - using SHAP or Azure ML ' s Responsible AI dashboard, the team can see which features drive individual predictions, revealing whether proxy variables for protected attributes are influencing decisions inappropriately. Option E (error rates across demographic cohorts) directly measures whether the model makes more mistakes for specific groups - a core fairness metric required under Responsible AI principles. Option A (global error rates) masks disparities since you need cohort-level analysis. Option B (endpoint latency) is a performance engineering concern. Option C (inference schema compatibility) is a technical integration check. The Azure ML Responsible AI dashboard combines both error analysis and feature importance in a unified interface designed for exactly this type of pre-deployment fairness assessment.
Microsoft Learn Reference Topic: Responsible AI dashboard in Azure Machine Learning - Error analysis and model interpretability
NEW QUESTION # 161
Hotspot Question
You train a model in Azure Machine Learning.
You plan to capture experiment details for later comparison. The training code must log parameters and metrics for each run.
You review the following training script.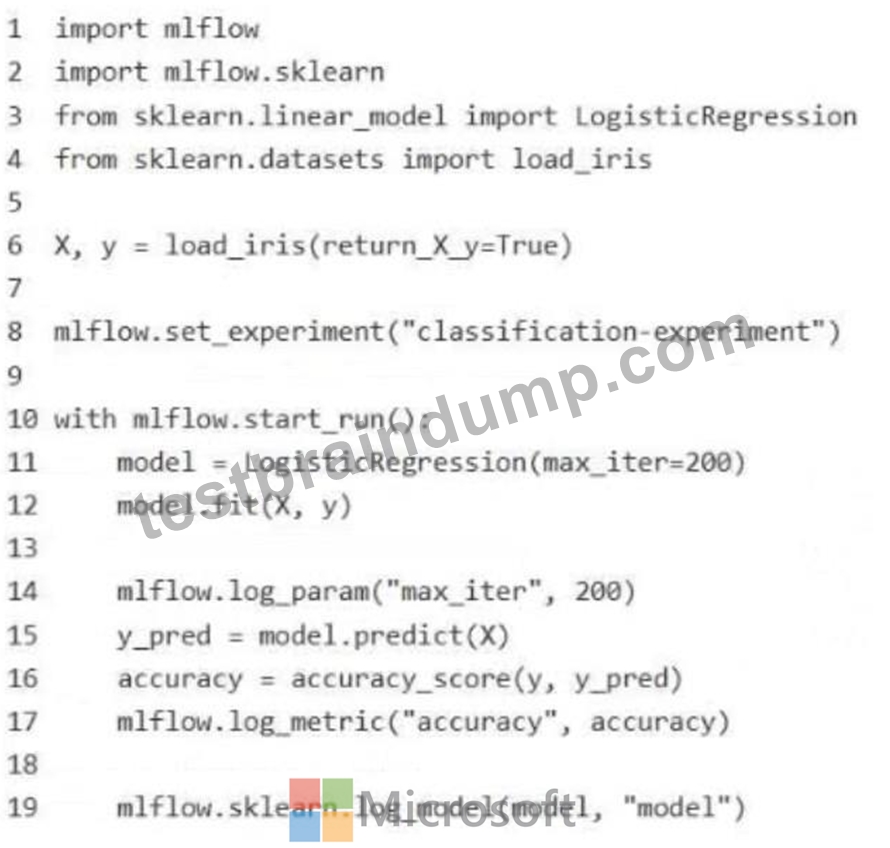
You need to verify whether the training script meets the experiment tracking requirement. For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.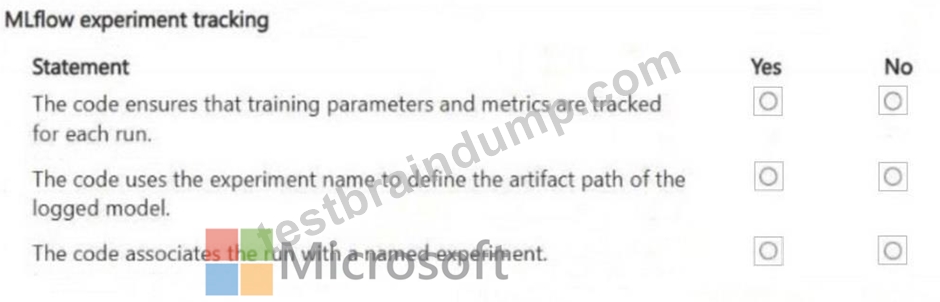
Answer:
Explanation: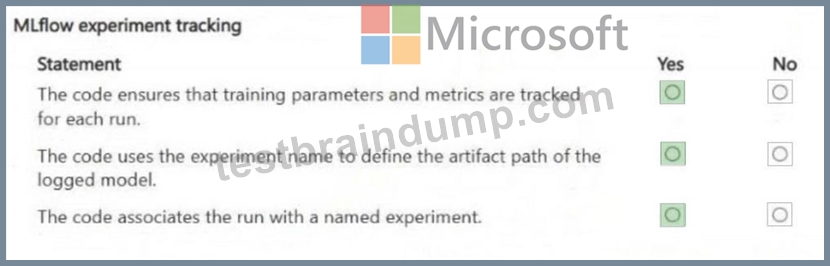
NEW QUESTION # 162
You use Azure Machine Learning to train models across multiple experiments by using the same workspace.
You must record training runs in a centralized location to compare results from different jobs.
During training, performance values must be captured so they appear in the experiment run history.
You need to configure experiment tracking.
What should you configure for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.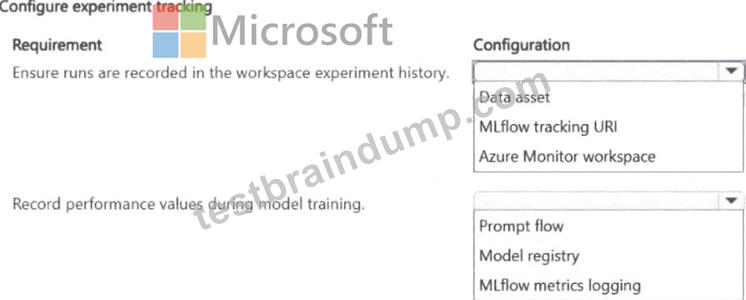
Answer:
Explanation: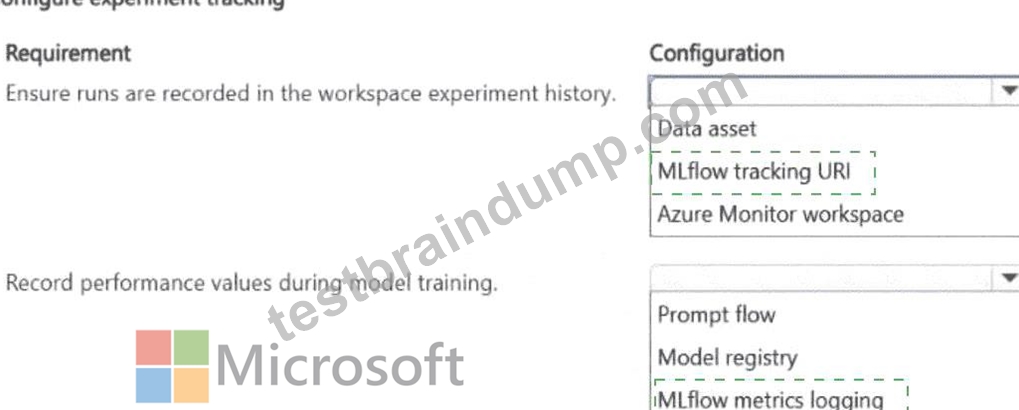
Explanation:
Azure Machine Learning ' s experiment tracking is built around two complementary concepts. First, experiments are named containers that group related runs. By calling mlflow.set_experiment with an experiment name at the start of your training code, all subsequent runs are grouped under that experiment name in the AML workspace, creating the centralized record required. Second, metrics are scalar values such as accuracy, loss, or AUC that represent model performance. Calling mlflow.log_metric with a metric name and value during training persists these values to the run ' s record in the experiment history. These values appear on the Azure ML Studio run detail page and can be compared across runs using the experiment comparison view. Without set_experiment, runs fall into a default experiment. Without log_metric, the run history has no performance data to display or compare.
Microsoft Learn Reference Topic: Track machine learning experiments with MLflow in Azure Machine Learning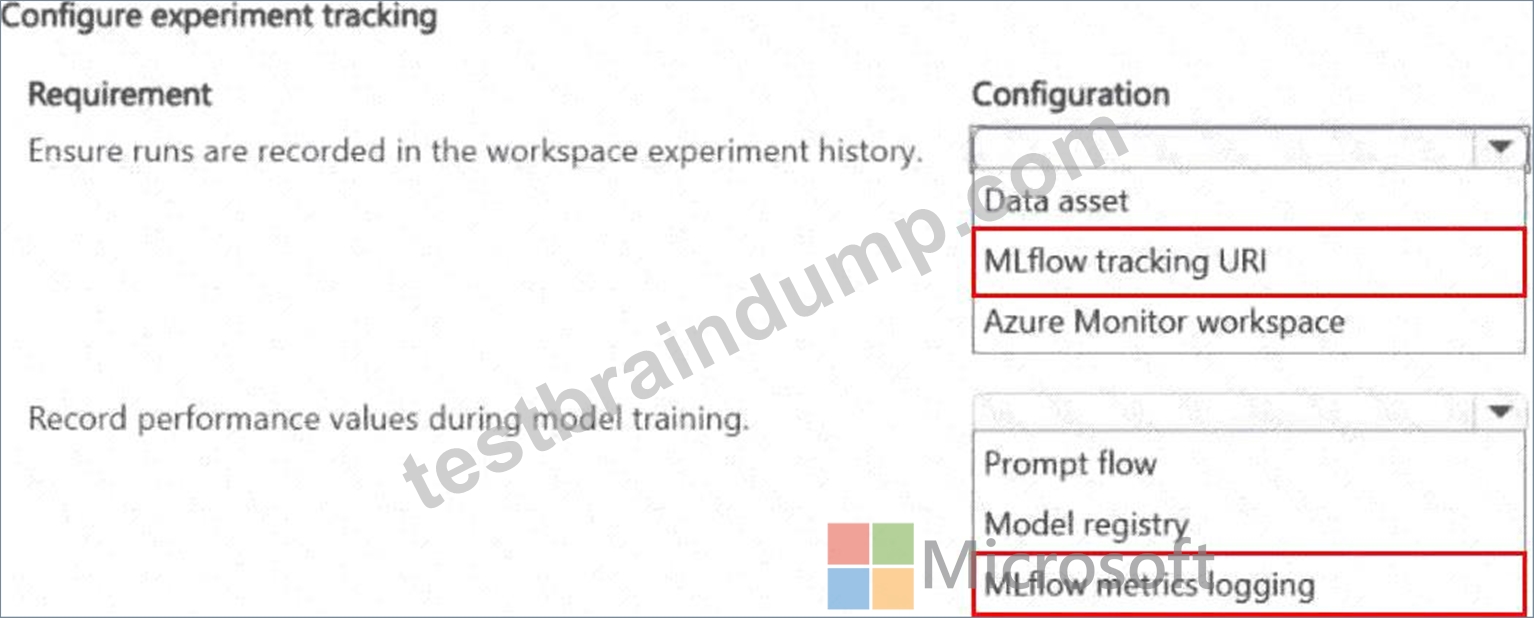
NEW QUESTION # 163
A product team is building a customer support assistant that must respond consistently across multiple channels.
Early testing shows that small wording changes in prompts cause large differences in tone and factual accuracy.
The team needs prompts that are reliable, reusable, and adaptable across multiple use cases without retraining the underlying model.
You need to design prompts that improve response quality while remaining flexible for future changes.
Which two actions should you perform? Each correct answer presents part of the solution. (Choose two.)
Answer: A,E
Explanation:
B and C provide the strongest architecture for reusable and predictable prompts. Separating persistent application instructions from dynamic user input establishes a clear instruction hierarchy . The stable portion of the prompt can define application behavior while channel-specific or request-specific content remains variable. This reduces coupling between user wording and the behavioral rules of the assistant and makes the prompt easier to reuse, version, test, and modify.
The system prompt should establish the model ' s role, behavioral boundaries, tone, communication style, response format, and other persistent rules. Microsoft specifically describes system messages as high-priority instructions used to define an assistant ' s role and boundaries and to set tone and communication style.
Fine-tuning for every conversational variation is unnecessarily expensive and contradicts the requirement to remain adaptable without retraining. Increasing temperature increases randomness and therefore works against consistent responses. Although repeating important instructions can sometimes mitigate recency effects, Microsoft treats this as an optional prompt-engineering technique to experiment with, not the primary architectural technique for producing reusable prompts.
Study Guide Reference: Design and implement a GenAIOps infrastructure - design and develop prompts, prompt management, prompt variants, system instructions, and reusable prompt structures.
NEW QUESTION # 164
......
Once the user has used our AI-300 learning material for a mock exercise, the product's system automatically remembers and analyzes all the user's actual operations. The user must complete the test within the time specified by the simulation system, and there is a timer on the right side of the screen, as long as the user begins the practice of AI-300 Learning Materials, the timer will run automatic and start counting.
AI-300 Question Explanations: https://www.testbraindump.com/AI-300-exam-prep.html