ちなみに、Jpshiken Professional-Machine-Learning-Engineerの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1woU8KeqNjzeWpiJjPg3SAwr9U6j4Qyvh
我々のJpshikenサイトは一番高質量のProfessional-Machine-Learning-Engineer試験資料と行き届いたアフタサービスを提供して協力します。Google Professional-Machine-Learning-Engineer問題集は試験の範囲を広くカバーして、試験の通過率は高いです。他のサイトと比較して、我が社のProfessional-Machine-Learning-Engineer試験問題集を購買すると決定します。商品の税金について、この問題を心配できません。顧客の利益を保証するために、税金は弊社の方で支払います。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Automate and orchestrate ML pipelines | 18% | - Use Vertex AI Pipelines, TFX, and other orchestration tools - Design end-to-end ML workflows - Automate retraining and model updates - Implement CI/CD for ML systems |
| Topic 2: Monitor and optimize AI solutions | 16% | - Troubleshoot and maintain production systems - Monitor model performance, fairness, and drift - Monitor data quality and pipeline health - Optimize cost, latency, and resource usage |
| Topic 3: Scale prototypes into AI models | 18% | - Select appropriate model architectures and frameworks - Work with foundation models and generative AI techniques - Optimize model performance and generalization - Design and run experiments |
| Topic 4: Architect low-code AI solutions | 12% | - Apply responsible AI principles to low-code designs - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Identify use cases for low-code/no-code AI tools |
| Topic 5: Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Organize and prepare enterprise data
|
| Topic 6: Train and deploy models | 20% | - Implement generative AI deployment patterns - Deploy models for online, batch, and streaming prediction - Configure training jobs and environments - Use Vertex AI deployment features and infrastructure |
>> Professional-Machine-Learning-Engineer日本語サンプル <<
Professional-Machine-Learning-Engineer認定を取得することは多くの人にとって簡単ではないことがわかっていますが、良いニュースをお伝えできることを嬉しく思います。当社の教材は、短時間でProfessional-Machine-Learning-Engineer認定を取得するのに役立ちます。 Professional-Machine-Learning-Engineer練習問題を詳細にご紹介します。貴重な時間を割いてProfessional-Machine-Learning-Engineer試験の質問をご覧ください。私たちはあなたを失望させないと信じてください。ウェブ上のProfessional-Machine-Learning-Engineerトレーニングガイドのデモを無料でダウンロードして、優れた品質を知ることができます。
質問 # 153
You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?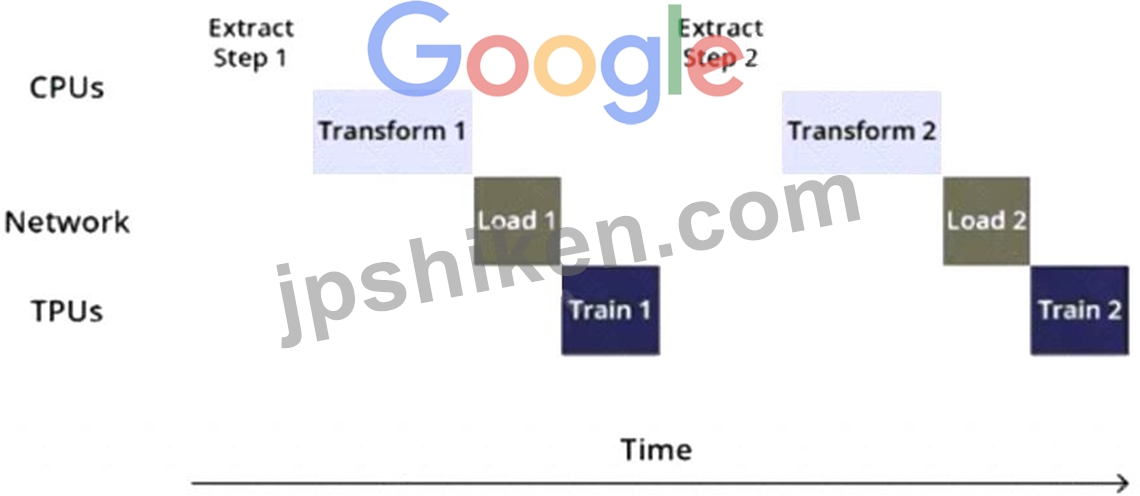
正解:A
解説:
The trace in the question shows that the training time is taking longer than expected. This is likely due to the input function not being optimized. To decrease training time in a cost-efficient way, the best option is to rewrite the input function using parallel reads, parallel processing, and prefetch. This will allow the model to process the data more efficiently and decrease training time. References:
* [Cloud TPU Performance Guide]
* [Data input pipeline performance guide]
質問 # 154
Machine Learning Specialist is training a model to identify the make and model of vehicles in images. The Specialist wants to use transfer learning and an existing model trained on images of general objects. The Specialist collated a large custom dataset of pictures containing different vehicle makes and models.
What should the Specialist do to initialize the model to re-train it with the custom data?
正解:A
解説:
Explanation/Reference:
質問 # 155
You recently created a new Google Cloud project. After testing that you can submit a Vertex AI Pipeline job from the Cloud Shell, you want to use a Vertex AI Workbench user-managed notebook instance to run your code from that instance. You created the instance and ran the code but this time the job fails with an insufficient permissions error. What should you do?
正解:D
質問 # 156
You need to use TensorFlow to train an image classification model. Your dataset is located in a Cloud Storage directory and contains millions of labeled images Before training the model, you need to prepare the dat a. You want the data preprocessing and model training workflow to be as efficient scalable, and low maintenance as possible. What should you do?
正解:B
質問 # 157
You have been asked to build a model using a dataset that is stored in a medium-sized (~10 GB) BigQuery table. You need to quickly determine whether this data is suitable for model development. You want to create a one-time report that includes both informative visualizations of data distributions and more sophisticated statistical analyses to share with other ML engineers on your team. You require maximum flexibility to create your report. What should you do?
正解:A
解説:
* Option A is correct because using Vertex AI Workbench user-managed notebooks to generate the report is the best way to quickly determine whether the data is suitable for model development, and to create a one-time report that includes both informative visualizations of data distributions and more sophisticated statistical analyses to share with other ML engineers on your team. Vertex AI Workbench is a service that allows you to create and use notebooks for ML development and experimentation. You can use Vertex AI Workbench to connect to your BigQuery table, query and analyze the data using SQL or Python, and create interactive charts and plots using libraries such as pandas, matplotlib, or seaborn.
You can also use Vertex AI Workbench to perform more advanced data analysis, such as outlier detection, feature engineering, or hypothesis testing, using libraries such as TensorFlow Data Validation, TensorFlow Transform, or SciPy. You can export your notebook as a PDF or HTML file, and share it with your team. Vertex AI Workbench provides maximum flexibility to create your report, as you can use any code or library that you want, and customize the report as you wish.
* Option B is incorrect because using Google Data Studio to create the report is not the most flexible way to quickly determine whether the data is suitable for model development, and to create a one-time report that includes both informative visualizations of data distributionsand more sophisticated statistical analyses to share with other ML engineers on your team. Google Data Studio is a service that allows you to create and share interactive dashboards and reports using data from various sources, such as BigQuery, Google Sheets, or Google Analytics. You can use Google Data Studio to connect to your BigQuery table, explore and visualize the data using charts, tables, or maps, and apply filters, calculations, or aggregations to the data. However, Google Data Studio does not support more
* sophisticated statistical analyses, such as outlier detection, feature engineering, or hypothesis testing, which may be useful for model development. Moreover, Google Data Studio is more suitable for creating recurring reports that need to be updated frequently, rather than one-time reports that are static.
* Option C is incorrect because using the output from TensorFlow Data Validation on Dataflow to generate the report is not the most efficient way to quickly determine whether the data is suitable for model development, and to create a one-time report that includes both informative visualizations of data distributions and more sophisticated statistical analyses to share with other ML engineers on your team.
TensorFlow Data Validation is a library that allows you to explore, validate, and monitor the quality of your data for ML. You can use TensorFlow Data Validation to compute descriptive statistics, detect anomalies, infer schemas, and generate data visualizations for your data. Dataflow is a service that allows you to create and run scalable data processing pipelines using Apache Beam. You can use Dataflow to run TensorFlow Data Validation on large datasets, such as those stored in BigQuery.
However, this option is not very efficient, as it involves moving the data from BigQuery to Dataflow, creating and running the pipeline, and exporting the results. Moreover, this option does not provide maximum flexibility to create your report, as you are limited by the functionalities of TensorFlow Data Validation, and you may not be able to customize the report as you wish.
* Option D is incorrect because using Dataprep to create the report is not the most flexible way to quickly determine whether the data is suitable for model development, and to create a one-time report that includes both informative visualizations of data distributions and more sophisticated statistical analyses to share with other ML engineers on your team. Dataprep is a service that allows you to explore, clean, and transform your data for analysis or ML. You can use Dataprep to connect to your BigQuery table, inspect and profile the data using histograms, charts, or summary statistics, and apply transformations, such as filtering, joining, splitting, or aggregating, to the data. However, Dataprep does not support more sophisticated statistical analyses, such as outlier detection, feature engineering, or hypothesis testing, which may be useful for model development. Moreover, Dataprep is more suitable for creating data preparation workflows that need to be executed repeatedly, rather than one-time reports that are static.
References:
* Vertex AI Workbench documentation
* Google Data Studio documentation
* TensorFlow Data Validation documentation
* Dataflow documentation
* Dataprep documentation
* [BigQuery documentation]
* [pandas documentation]
* [matplotlib documentation]
* [seaborn documentation]
* [TensorFlow Transform documentation]
* [SciPy documentation]
* [Apache Beam documentation]
質問 # 158
......
Google才能の新しい時代に次第に飽和して彼ら自身の利点を獲得し、あなたの能力をどのように反映しますか? おそらく最も直感的な方法は、テストProfessional-Machine-Learning-Engineer認定を取得して、Jpshiken対応する資格を取得することです。 ただし、Professional-Machine-Learning-Engineer認定試験はそれほど単純ではないため、レビューには多大な労力が必要です。 テスト認定を効果的に取得する方法について説明します。Professional-Machine-Learning-Engineer試験に短時間で合格することは空想ではないことを伝えるProfessional-Machine-Learning-Engineer学習教材です。 何万人もの受験者が99%の合格率でGoogle Professional Machine Learning Engineer試験に合格するのを支援しました。
Professional-Machine-Learning-Engineer関連受験参考書: https://www.jpshiken.com/Professional-Machine-Learning-Engineer_shiken.html
P.S. JpshikenがGoogle Driveで共有している無料かつ新しいProfessional-Machine-Learning-Engineerダンプ:https://drive.google.com/open?id=1woU8KeqNjzeWpiJjPg3SAwr9U6j4Qyvh