高品質-権威のあるNCP-AIO資格専門知識試験-試験の準備方法NCP-AIO試験問題集

2026年GoShikenの最新NCP-AIO PDFダンプおよびNCP-AIO試験エンジンの無料共有:https://drive.google.com/open?id=1BPC5VPKAC5Ae540JZm5Neryr5zHXKJBm
もし君はNVIDIAのNCP-AIO認定試験に合格するのを通じて、競争が激しいIT業種での地位を高めて、IT技能を増強するなら、GoShikenの NVIDIAのNCP-AIO試験トレーニング資料を選んだほうがいいです。長年の努力を通じて、GoShikenのNVIDIAのNCP-AIO認定試験の合格率が100パーセントになっていました。GoShikenを選ぶのは成功を選ぶのに等しいです。
NVIDIA NCP-AIO Exam Overview:
>> NCP-AIO資格専門知識 <<
検証するNCP-AIO|正確的なNCP-AIO資格専門知識試験|試験の準備方法NVIDIA AI Operations試験問題集
あなたのIT能力が権威的に認められるのがほしいですか。NVIDIAのNCP-AIO試験に合格するのは最良の方法の一です。我々GoShikenの開発するNVIDIAのNCP-AIOソフトはあなたに一番速い速度でNVIDIAのNCP-AIO試験のコツを把握させることができます。豊富な資料、便利なページ構成と購入した一年間の無料更新はあなたにNVIDIAのNCP-AIO試験に合格させる最高の支持です。
NVIDIA NCP-AIO 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| トピック 2 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| トピック 3 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| トピック 4 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
NVIDIA AI Operations 認定 NCP-AIO 試験問題 (Q37-Q42):
質問 # 37
You are setting up a Kubernetes cluster on NVIDIA DGX systems using BCM, and you need to initialize the control-plane nodes.
What is the most important step to take before initializing these nodes?
- A. Disable swap on all control-plane nodes before initializing them.
- B. Ensure that Docker is installed and running on all control-plane nodes.
- C. Set up a load balancer before initializing any control-plane node.
- D. Configure each control-plane node with its own external IP address.
正解:A
解説:
Comprehensive and Detailed Explanation From Exact Extract:
Disablingswapon all control-plane nodes is a critical prerequisite before initializing Kubernetes control-plane nodes. Kubernetes requires swap to be disabled to maintain performance and stability. Failure to disable swap can cause kubeadm initialization to fail or lead to unpredictable cluster behavior.
質問 # 38
A system administrator is troubleshooting a Docker container that crashes unexpectedly due to a segmentation fault. They want to generate and analyze core dumps to identify the root cause of the crash.
Why would generating core dumps be a critical step in troubleshooting this issue?
- A. Core dumps prevent future crashes by stopping any further execution of the faulty process.
- B. Core dumps restore the process to its previous state, often fixing the error-causing crash.
- C. Core dumps capture the memory state of the process at the time of the crash.
- D. Core dumps provide real-time logs that can be used to monitor ongoing application performance.
正解:C
解説:
Core dumps capture the memory state of a process at the time of its crash, providing a snapshot useful for post-mortem debugging. Analyzing core dumps helps identify the cause of segmentation faults or other critical errors by revealing what the process was doing at failure, including stack traces, variable states, and memory content.
質問 # 39
Consider the following Python code snippet used for reading data from a storage system for AI training:
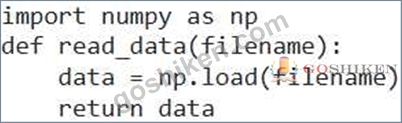
This code is used in an AI training loop. What storage considerations are most critical to optimize the performance of this code?
- A. Using a storage system that supports direct GPU memory access (e.g., GPUDirect Storage).
- B. Using a high-capacity HDD to store the data.
- C. Using a storage system with high sequential read throughput.
- D. Data compression for reducing storage space
- E. Using a storage system with low latency random access.
正解:A、C
解説:
NumPy's 'np.load' function typically reads the entire file sequentially into memory. Therefore, high sequential read throughput is crucial. GPUDirect Storage further optimizes performance by enabling direct memory access between the storage and the GPU, bypassing the CPU and system memory bottlenecks. Using a HDD will drastically reduce performance due to its low throughput and high latency.
質問 # 40
You are using 'nvsm' to manage your NVLink fabric. You want to verify the link speed and status between two specific GPUs. Which nvsm' command provides the MOST detailed information about individual NVLink connections?
- A. nvsm show devices'
- B. 'nvsm show configuration'
- C. 'nvsm show health'
- D. nvsm show links'
- E. 'nvsm show topology'
正解:D
解説:
'nvsm show links' provides detailed information about the individual NVLink connections, including their speed, status, and error counts. 'nvsm show topology' provides a high-level overview, while the other commands focus on different aspects of the system.
質問 # 41
You are deploying a PyTorch container from NGC that utilizes Tensor Cores. How can you verify that Tensor Cores are being effectively used during inference?
- A. Use the NVIDIA Nsight Systems profiler to analyze GPU kernel execution and identify Tensor Core operations.
- B. Use the 'nvidia-smi' command to monitor GPU utilization and check for high Tensor Core activity.
- C. Analyze the training loss curve; a steep decline indicates Tensor Core usage.
- D. Examine the CUDA code within the container to confirm explicit Tensor Core API calls.
- E. Check the container logs for messages indicating Tensor Core usage.
正解:A、B
解説:
B and E are correct. 'nvidia-smi' shows GPU utilization, including Tensor Core activity. Nsight Systems provides detailed profiling information, allowing you to identify specific Tensor Core operations. A is unreliable as log messages may not always be present. C refers to training, not inference. D is impractical without access to the container's source code.
質問 # 42
......
NCP-AIO試験問題集: https://www.goshiken.com/NVIDIA/NCP-AIO-mondaishu.html
- NCP-AIO専門知識 🍢 NCP-AIO日本語学習内容 🔈 NCP-AIO問題無料 🥿 ウェブサイト【 www.japancert.com 】を開き、“ NCP-AIO ”を検索して無料でダウンロードしてくださいNCP-AIO資格準備
- 有用的なNCP-AIO資格専門知識 - 資格試験におけるリーダーオファーs - 唯一無二なNCP-AIO: NVIDIA AI Operations 🌖 サイト☀ www.goshiken.com ️☀️で⏩ NCP-AIO ⏪問題集をダウンロードNCP-AIOテスト問題集
- NCP-AIO日本語学習内容 🍥 NCP-AIO最速合格 🙅 NCP-AIO専門知識 🐮 ▶ www.jptestking.com ◀には無料の⇛ NCP-AIO ⇚問題集がありますNCP-AIO専門試験
- NCP-AIO日本語問題集 🔷 NCP-AIO試験対策 🔽 NCP-AIO試験参考書 😴 ➥ www.goshiken.com 🡄を開いて“ NCP-AIO ”を検索し、試験資料を無料でダウンロードしてくださいNCP-AIO日本語学習内容
- 検証するNCP-AIO資格専門知識 - 合格スムーズNCP-AIO試験問題集 | 最新のNCP-AIO最速合格 🥩 ➤ www.xhs1991.com ⮘に移動し、▛ NCP-AIO ▟を検索して無料でダウンロードしてくださいNCP-AIO資格準備
- NCP-AIO日本語問題集 🐒 NCP-AIO問題無料 🏥 NCP-AIO試験対策 🍰 ✔ www.goshiken.com ️✔️サイトで[ NCP-AIO ]の最新問題が使えるNCP-AIO問題無料
- 真実的なNCP-AIO資格専門知識試験-試験の準備方法-権威のあるNCP-AIO試験問題集 📿 今すぐ{ www.passtest.jp }で▛ NCP-AIO ▟を検索して、無料でダウンロードしてくださいNCP-AIO専門試験
- 最高のNCP-AIO資格専門知識 - 合格スムーズNCP-AIO試験問題集 | 実用的なNCP-AIO最速合格 NVIDIA AI Operations 🔄 ▶ NCP-AIO ◀を無料でダウンロード➤ www.goshiken.com ⮘ウェブサイトを入力するだけNCP-AIO日本語学習内容
- 最高のNCP-AIO資格専門知識 - 合格スムーズNCP-AIO試験問題集 | 実用的なNCP-AIO最速合格 NVIDIA AI Operations 💏 《 www.mogiexam.com 》を入力して⇛ NCP-AIO ⇚を検索し、無料でダウンロードしてくださいNCP-AIO問題集
- 更新されたNCP-AIO資格専門知識 - すべてGoShiken 🛬 ➽ www.goshiken.com 🢪で☀ NCP-AIO ️☀️を検索して、無料で簡単にダウンロードできますNCP-AIO入門知識
- NCP-AIO認定試験トレーリング 💧 NCP-AIO問題無料 🐛 NCP-AIO関連合格問題 🌷 ⇛ NCP-AIO ⇚の試験問題は「 www.passtest.jp 」で無料配信中NCP-AIOトレーリングサンプル
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, fortunetelleroracle.com, hashnode.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026年GoShikenの最新NCP-AIO PDFダンプおよびNCP-AIO試験エンジンの無料共有:https://drive.google.com/open?id=1BPC5VPKAC5Ae540JZm5Neryr5zHXKJBm