P.S. Free & New DP-750 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1V34pks2MJzA1i5r4WdrpTbyvd6jnoT5E
Are you anxious about the upcoming DP-750 exam but has no idea about review? Don't give up and try DP-750 exam questions. Our DP-750 study material is strictly written by industry experts according to the exam outline. And our experts are so professional for they have beeen in this career for about ten years. With our DP-750 Learning Materials, you only need to spend 20-30 hours to review before the exam and will pass it for sure.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> Reliable Microsoft DP-750 Test Blueprint <<
“Quality First, Credibility First, and Service First” is our company’s purpose, we deeply hope our DP-750 Study Materials can bring benefits and profits for our customers. So we have been persisting in updating in order to help customers, who are willing to buy our test torrent, make good use of time and accumulate the knowledge. We will guarantee that you will have the opportunity to use the updating system for free.
NEW QUESTION # 32
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.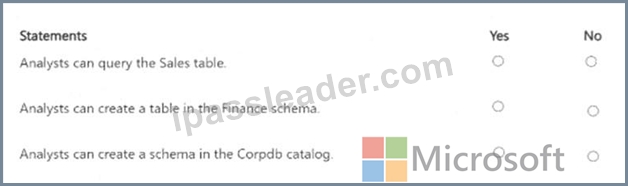
Answer:
Explanation: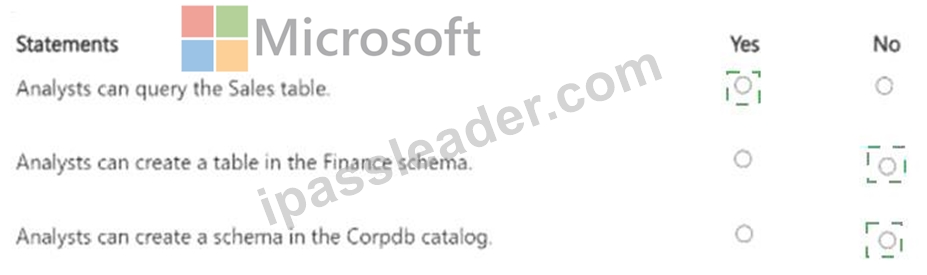
Explanation: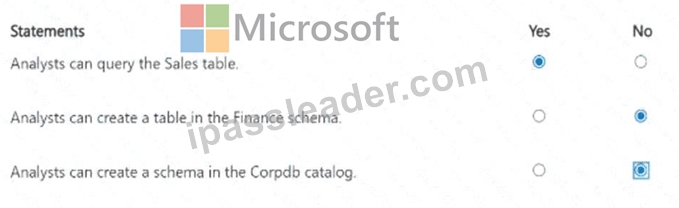
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 33
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: B
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 34
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
- New data must be available in near-real-time (NRT).
- The data must be stored in managed Delta tables.
- The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: A
Explanation:
You should use Auto Loader with Delta Live Tables (DLT) or a streaming readStream using the cloudFiles format to load data into Unity Catalog managed tables.
To achieve the absolute lowest maintenance and custom code, Delta Live Tables with Auto Loader is the recommended choice.
Configure Cloud FilesFormat option: Set the source format to cloudFiles in your Spark stream.File detection: Auto Loader automatically tracks new files arriving in Azure Data Lake Storage (ADLS) Gen2.Schema evolution: It infers and adapts to schema changes without code updates.
Reference:
https://docs.databricks.com/aws/en/ingestion/cloud-object-storage/auto-loader/unity-catalog
NEW QUESTION # 35
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: B
Explanation:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
NEW QUESTION # 36
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a table named Transactions. Transactions contains the following columns:
- transaction_id
- customer_name
- email_address
- credit_card_number
- transaction_amount
You need to ensure that business analysts can query all the rows in the Transactions table. The solution must meet the following requirements:
- Prevent the analysts from seeing the full values in the email_address and credit_card_number columns.
- Ensure that the analysts can see only the values after the @
character in each email address.
- Ensure that the analysts can see only the last four digits of each
credit card number.
- Enable the analysts to query the table without errors.
- Follow the principle of least privilege.
What should you do?
Answer: D
Explanation:
To protect sensitive customer information while allowing a specific group to run queries, use Unity Catalog's Dynamic Column Masking. This grants the group table access while applying User- Defined Functions (UDFs) to redact the email addresses and credit card numbers dynamically.
Here is the exact SQL implementation to apply:
1. Create the masking SQL UDFs
Define functions to apply the exact partial masking rules requested.
2. Apply the column masks to the tableAlter the transaction table to attach these UDFs to the respective columns.
3. Grant least privilege permissionsGrant the group the SELECT permission on the table, along with the foundational permissions to access the catalog and schema.
Reference:
https://docs.databricks.com/aws/en/data-governance/unity-catalog/filters-and-masks
NEW QUESTION # 37
......
If you want to find the best DP-750 study materials, the first thing you need to do is to find a bank of questions that suits you. Our DP-750 learning material is prepared by experts in strict accordance with the exam outline of the DP-750 certification exam, whose main purpose is to help students to pass the exam with the least amount of time and effort. We can claim that if you study with our DP-750 Practice Engine for 20 to 30 hours, then you will be sure to pass the exam.
DP-750 Test Discount: https://www.ipassleader.com/Microsoft/DP-750-practice-exam-dumps.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1V34pks2MJzA1i5r4WdrpTbyvd6jnoT5E