DOWNLOAD the newest Actual4dump DEA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1XAH2wwYhqZ2A518w63ZT0b1njKmz5rIh
The SnowPro Advanced: Data Engineer Certification Exam (DEA-C01) practice test software also shows changes and improvements done by the candidates on every step during the DEA-C01 exam. So this reduces your chance of failure in the actual DEA-C01 Exam. It requires no special plugins to function properly. So just start your journey with Actual4dump and prepare for the DEA-C01 exam instantly.
| Certification Vendor: | Snowflake |
|---|---|
| Exam Name: | SnowPro Advanced: Data Engineer Certification Exam |
| Exam Number: | DEA-C01 |
| Passing Score: | 750 / 1000 |
| Exam Price: | $375 USD |
| Available Languages: | English, Japanese |
| Related Certifications: | SnowPro Advanced: Administrator SnowPro Advanced: Security Engineer SnowPro Core SnowPro Advanced: Data Analyst SnowPro Advanced: Data Scientist SnowPro Advanced: Architect |
| Exam Duration: | 115 minutes |
| Real Exam Qty: | 65 |
| Exam Format: | Multiple select, Multiple choice |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Snowflake University Training Courses SnowPro Advanced: Data Engineer Exam Study Guide |
| Exam Registration: | Pearson VUE Registration Snowflake Certification Portal |
| Sample Questions: | Snowflake DEA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | Must hold active SnowPro Core Certification; recommended 2+ years hands-on data engineering experience |
| Official Syllabus URL: | https://learn.snowflake.com/en/certifications/snowpro-advanced-dataengineer/ |
In today's fast-paced world, having access to SnowPro Advanced: Data Engineer Certification Exam (DEA-C01) study material on the go is important. Actual4dump SnowPro Advanced: Data Engineer Certification Exam (DEA-C01) PDF questions are compatible with all smart devices, allowing you to study and prepare for the DEA-C01 Exam whenever and wherever you choose. Since you can access real Snowflake DEA-C01 dumps in PDF from your smartphone or tablet, you can easily fit DEA-C01 exam preparation into your busy schedule.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 337
When created, a stream logically takes an initial snapshot of every row in the source object and the contents of a stream change as DML statements execute on the source table.
A Data Engineer, Sophie Created a view that queries the table and returns the CURRENT_USER and CURRENT_TIMESTAMP values for the query transaction. A Stream has been created on views to capture CDC.
Tony, another user inserted the data e.g.
insert into <table> values (1),(2),(3);
Emily, another user also inserted the data e.g.
insert into <table> values (4),(5),(6);
What will happened when Different user queries the same stream after 1 hour?
Answer: A
Explanation:
Explanation
When User queries the stream, the stream returns the username for the user. The stream also returns the current timestamp for the query transaction in each row, NOT the timestamp when each row was inserted.
NEW QUESTION # 338
How can the following relational data be transformed into semi-structured data using the LEAST amount of operational overhead?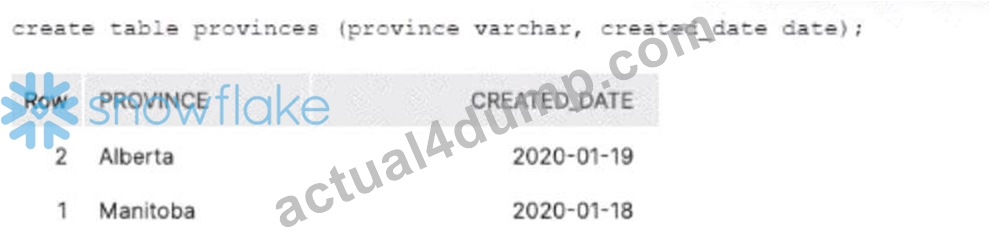
Answer: D
Explanation:
Explanation
This option is the best way to transform relational data into semi-structured data using the least amount of operational overhead. The OBJECT_CONSTRUCT function takes a variable number of key-value pairs as arguments and returns a Snowflake object, which is a variant type that can store JSON data. The function can be used to convert each row of relational data into a JSON object with the column names as keys and the column values as values.
NEW QUESTION # 339
A company has a data processing pipeline that runs multiple SQL queries in sequence against an Amazon Redshift cluster. The company merges with a second company. The original company modifies a query that aggregates sales revenue data to join sales tables from both companies.
The sales table for the first company is named Table S1. The sales table for the second company is named Table S2. Table S1 contains 10 billion records. Table S2 contains 900 million records.
The query becomes slow after the modification. A data engineer must improve the query performance.
Which solutions will meet these requirements? (Choose two.)
Answer: A,D
Explanation:
Choosing KEY distribution on both tables with a high-cardinality join column colocates matching rows across nodes and avoids data skew, improving join performance.
Redshift Advisor provides automated, actionable recommendations (e.g., distribution and sort keys, stats) to further optimize the slow query with minimal effort.
NEW QUESTION # 340
A Data Engineer needs to ingest invoice data in PDF format into Snowflake so that the data can be queried and used in a forecasting solution.
..... recommended way to ingest this data?
Answer: D
Explanation:
Explanation
The recommended way to ingest invoice data in PDF format into Snowflake is to create a Java User-Defined Function (UDF) that leverages Java-based PDF parser libraries to parse PDF data into structured data. This option allows for more flexibility and control over how the PDF data is extracted and transformed. The other options are not suitable for ingesting PDF data into Snowflake. Option A and B are incorrect because Snowpipe and COPY INTO commands can only ingest files that are in supported file formats, such as CSV, JSON, XML, etc. PDF files are not supported by Snowflake and will cause errors or unexpected results.
Option C is incorrect because external tables can only query files that are in supported file formats as well.
PDF files cannot be parsed by external tables and will cause errors or unexpected results.
NEW QUESTION # 341
A company runs an Apache Spark application every night in an Amazon EMR cluster. The company uses Amazon EC2 instances to supply compute capacity for the EMR cluster. The company deployed the Spark application in cluster mode.
An error occurs in the Spark application. A log for the error is stored in the application's Spark driver standard error logs. A data engineer needs to investigate the error.
Where can the data engineer find this error log?
Answer: B
Explanation:
In EMR cluster mode, the Spark driver runs inside the cluster and its standard error logs are captured as step logs. These logs are automatically archived to Amazon S3 and accessible from the Amazon EMR console under step logs. This is the correct location for investigating Spark driver errors.
NEW QUESTION # 342
......
Training DEA-C01 Material: https://www.actual4dump.com/Snowflake/DEA-C01-actualtests-dumps.html
BTW, DOWNLOAD part of Actual4dump DEA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1XAH2wwYhqZ2A518w63ZT0b1njKmz5rIh