P.S. Kostenlose und neue AIF-C01 Prüfungsfragen sind auf Google Drive freigegeben von EchteFrage verfügbar: https://drive.google.com/open?id=129WkUL_18UdBloyWJdzlM9P_USk32zxs
Um Ihre Zertifizierungsprüfungen reibungslos erfolgreich zu meistern, brauchen Sie nur unsere Prüfungsfragen und Antworten zu Amazon AIF-C01 (AWS Certified AI Practitioner)auswendigzulernen. Viel Erfolg!
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
| Thema 5 |
|
>> AIF-C01 Prüfungsinformationen <<
Die Amazon AIF-C01 Zertifizierungsprüfung stellt eine wichtige Position in der IT-Branche dar, worüber viele IT-Experten sich einig sind. Die Amazon AIF-C01 (AWS Certified AI Practitioner) Zertifizierungsprüfung zu bestehen ist jedoch nicht einfach. Es erfordert umfangreiche Fachkenntnisse und Erfahrungen, weil die Amazon AIF-C01 Zertifizierungsprüfung sowieso eine autoritäre Prüfung, die das Niveau der IT-Fachkenntnissen überprüft. Wenn Sie das Amazon AIF-C01 Zertifikat bekommen, wird Ihre Fähigkeit von den Firmen akzeptiert. Das bedeutet, dass die zielgerichteten Schulungsunterlagen von EchteFrage sehr wirksam ist. Mit unseren Prüfungsmaterialien können Sie 100% die Prüfung bestehen.
174. Frage
A company wants to use a large language model (LLM) on Amazon Bedrock for sentiment analysis. The company needs the LLM to produce more consistent responses to the same input prompt.
Which adjustment to an inference parameter should the company make to meet these requirements?
Antwort: B
Begründung:
The temperature parameter in a large language model (LLM) controls the randomness of the model's output.
A lower temperature value makes the output more deterministic and consistent, meaning that the model is less likely to produce different results for the same input prompt.
* Option A (Correct): "Decrease the temperature value": This is the correct answer because lowering the temperature reduces the randomness of the responses, leading to more consistent outputs for the same input.
* Option B: "Increase the temperature value" is incorrect because it would make the output more random and less consistent.
* Option C: "Decrease the length of output tokens" is incorrect as it does not directly affect the consistency of the responses.
* Option D: "Increase the maximum generation length" is incorrect because this adjustment affects the output length, not the consistency of the model's responses.
AWS AI Practitioner References:
* Understanding Temperature in Generative AI Models: AWS documentation explains that adjusting the temperature parameter affects the model's output randomness, with lower values providing more consistent outputs.
175. Frage
A company wants to use Amazon Bedrock. The company needs to review which security aspects the company is responsible for when using Amazon Bedrock.
Antwort: B
Begründung:
* With Amazon Bedrock, AWS handles infrastructure security and patching (shared responsibility model).
* Customers are responsible for securing their data (encryption, IAM, policies) both in transit and at rest.
* Provisioning infrastructure (D) and platform patching (A, B) are AWS responsibilities.
# Reference:
AWS Shared Responsibility Model
176. Frage
A hospital is developing an AI system to assist doctors in diagnosing diseases based on patient records and medical images. To comply with regulations, the sensitive patient data must not leave the country the data is located in.
Which data governance strategy will ensure compliance and protect patient privacy?
Antwort: B
Begründung:
Data residency is the principle and practice of ensuring that data remains within a specific geographic location or jurisdiction, often to comply with local regulations and privacy laws (such as HIPAA, GDPR, or national healthcare laws). Data residency policies prevent sensitive data (such as patient records) from being transferred or accessed outside the designated country, thus protecting privacy and ensuring regulatory compliance.
A is correct:
"Data residency refers to where data is stored geographically, and often organizations need to ensure that certain data does not leave a particular country or region to comply with legal or regulatory requirements." (Reference: AWS Data Residency Whitepaper, AWS Responsible AI & Data Privacy)
"Data residency refers to where data is stored geographically, and often organizations need to ensure that certain data does not leave a particular country or region to comply with legal or regulatory requirements." (Reference: AWS Data Residency Whitepaper, AWS Responsible AI & Data Privacy) B (data quality) refers to the accuracy and reliability of data, not its location.
C (data discoverability) is about being able to find and access data, not restricting its movement.
D (data enrichment) is about enhancing data with additional information.
"Maintaining data residency is critical in healthcare and regulated industries to ensure data does not leave the prescribed jurisdiction." (Reference: AWS Data Residency)
"Maintaining data residency is critical in healthcare and regulated industries to ensure data does not leave the prescribed jurisdiction." (Reference: AWS Data Residency)
177. Frage
Sated and order the steps from the following bat to correctly describe the ML Lifecycle for a new custom modal Select each step one time. (Select and order FOUR.)
* Define the business objective.
* Deploy the modal.
* Develop and tram the model.
* Process the data.
Antwort:
Begründung: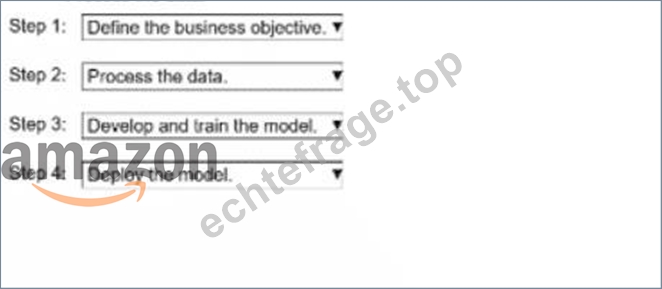
Step 1: Define the business objective.
Step 2: Process the data.
Step 3: Develop and train the model.
Step 4: Deploy the model.
The correct order represents the machine learning lifecycle as defined by AWS in the Amazon SageMaker documentation and AWS Certified Machine Learning Specialty Study Guide. The lifecycle describes the sequence of tasks required to build, train, and deploy a custom ML model effectively.
From AWS documentation:
"The machine learning process begins with defining the business problem, followed by collecting and processing data, developing and training models, and finally deploying them into production for inference." Step 1 - Define the business objective:
This step involves clearly identifying the business problem to be solved and determining the measurable outcomes expected from the ML model. This ensures alignment between business goals and ML outputs.
Step 2 - Process the data:
Data is collected, cleaned, transformed, and prepared for training. This includes handling missing values, normalizing data, and performing feature engineering - a crucial phase that influences model performance.
Step 3 - Develop and train the model:
The model is built and trained on the processed data using algorithms appropriate to the problem (e.g., regression, classification, clustering). Hyperparameters are tuned to optimize model accuracy.
Step 4 - Deploy the model:
Once validated, the model is deployed to a production environment (e.g., Amazon SageMaker endpoint) to make predictions on new data. Continuous monitoring and retraining ensure the model remains effective.
Referenced AWS AI/ML Documents and Study Guides:
Amazon SageMaker Developer Guide - Machine Learning Lifecycle
AWS Certified Machine Learning Specialty Study Guide - Model Development Lifecycle AWS ML Best Practices Whitepaper - End-to-End ML Workflow
178. Frage
A company has a generative AI application that uses a pre-trained foundation model (FM) on Amazon Bedrock. The company wants the FM to include more context by using company information.
Which solution meets these requirements MOST cost-effectively?
Antwort: C
Begründung:
Amazon Bedrock Knowledge Bases enable Retrieval Augmented Generation (RAG) by letting you connect external company data sources to your foundation model in a serverless, cost-effective manner-without retraining or fine-tuning. This allows the model to answer questions and generate content grounded in your own documents or data.
* A is correct:
"Knowledge Bases for Amazon Bedrock enable generative AI applications to retrieve and include your company's information for more contextual responses, without the need for expensive retraining or custom models." (Reference: Amazon Bedrock Knowledge Bases)
* B is not cost-effective or guaranteed to add your company's context.
* C (Agents) are for orchestrating workflows, not specifically RAG/context.
* D (Custom model deployment) is costly and unnecessary for just adding context.
179. Frage
......
Viele meiner Freude im IT-Bereich haben viel Zeit und Energie für die Amazon AIF-C01 Zertifizierungsprüfung verwendet. Aber sie haben sich nicht am Kurs oder Training im Internet beteiligt. Für sie ist es schwer, die Amazon AIF-C01 Prüfung zu bestehen. Und die Erfolgsquote ist auch sehr niedrig. Glünklicherweise bietet EchteFrage die zuverlässigen Amazon AIF-C01 Prüfungsmaterialien. Die Schulungsunterlagen von EchteFrage beinhalten die Simulationssoftware und die Prüfungsfragen-und antworten. Wir würden die besten Prüfungsfragen und Antworten zur AIF-C01 Zertifizierungsprüfung bieten, um Ihre Bedürfnisse abzudecken.
AIF-C01 Dumps: https://www.echtefrage.top/AIF-C01-deutsch-pruefungen.html
Außerdem sind jetzt einige Teile dieser EchteFrage AIF-C01 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=129WkUL_18UdBloyWJdzlM9P_USk32zxs