BONUS!!! Download part of ActualTestsQuiz DAA-C01 dumps for free: https://drive.google.com/open?id=1bBAY7CItCuhhxkjVCTeeXQtEKDO1eeXT
Without doubt, our DAA-C01 practice dumps keep up with the latest information and contain the most valued key points that will show up in the real DAA-C01 exam. Meanwhile, we can give you accurate and instant suggestion for our customer services know every detail of our DAA-C01 Exam Questions. And they are pleased to give guide for 24 hours online. You can get assistant by them as long as you made your inquire.
| Section | Objectives |
|---|---|
| Topic 1: Security, Governance, and Data Sharing | - Access control and security
|
| Topic 2: Data Transformation and Analysis | - Analytical workloads
|
| Topic 3: Data Modeling and Performance Optimization | - Modeling approaches in Snowflake
|
| Topic 4: Snowflake Architecture and Data Platform Fundamentals | - Snowflake architecture concepts
|
| Topic 5: Data Loading and Unloading | - Data export
|
>> Pass4sure DAA-C01 Pass Guide <<
Our DAA-C01 exam questions are valuable and useful and if you buy our product will provide first-rate service to you to make you satisfied. We provide not only the free download and try out of the DAA-C01 study guide but also the immediate refund if you fail in the test. To see whether our DAA-C01 Study Materials are worthy to buy you can have a look at the introduction of our product on the website and free download the demos to check the questions and answers.
NEW QUESTION # 55
You're developing a data quality process in Snowflake that relies on identifying duplicate records within a large table named 'TRANSACTIONS. You need to generate a hash value for each row based on several key columns ('transaction_id', 'customer_id' , amount', to efficiently compare rows and detect duplicates. However, some of these columns may contain NULL values, which you want to handle consistently during the hash generation. Which of the following approaches, utilizing Snowflake's system functions, will MOST reliably generate a consistent hash value for duplicate rows, even when some of the key columns contain NULLs? (Select TWO)
Answer: B,C
Explanation:
Options B and E are the most reliable. Option B concatenates the value of the columns as a string to create a seed for SHA2, ensuring to convert the NULL to empty string, which is necessary so that SHA2 does not return NULL in the face of NULL column values. Option E also uses SHA2 to encrypt after concatenating all the column values but it casts all those columns to varchar, which is necessary for the data preparation and data ingestion as they might be of different datatype. The first option is wrong because Snowflake's HASH function automatically returns NULL if any of the input are NULL. Option C uses the 'II' operator to concatenate values and Snowflake will return NULL in case any value is null. Option D concatenates strings with a separator, handling NULLs implicitly by skipping them in concatenation, leading to inconsistencies
NEW QUESTION # 56
You are building a data pipeline to ingest customer data into Snowflake. You have identified a need to dynamically determine the data load timestamp during the ingestion process itself, without relying on external systems or pre-defined variables. Which system function(s) would be the MOST appropriate and efficient choice to accomplish this?

Answer: C
Explanation:
The function returns the current timestamp at the start of the statement. 'SYSDATE()' and 'GETDATE()' functions does not exists in Snowflake. is a synonym for CURRENT TIMESTAMP(). However, is not a standard documented function.
NEW QUESTION # 57
A Data Analyst created a model called modelX using SNOWFLAKE.ML.FORECAST. The Analyst needs to predict the next few values and save the result directly into tableX. What step does the Analyst need to take after calling the modelX!FORECAST function?
Answer: C
Explanation:
Snowflake Cortex ML functions, such as FORECAST, return a tabular result set when called using the instance method syntax (e.g., CALL modelX!FORECAST(...)). While this output is visible in the Snowsight results pane, the CALL statement itself cannot be used directly as a subquery within a standard INSERT INTO or CREATE TABLE AS SELECT (CTAS) statement.
To persist the results of a model's prediction into a permanent table (tableX), the Data Analyst must utilize the RESULT_SCAN table function. Snowflake stores the results of every query and function call in a temporary cache for 24 hours. The RESULT_SCAN function allows you to treat that cache as a queryable table.
The standard workflow is:
* Execute the forecast: CALL modelX!FORECAST(FORECASTING_PERIODS => 12);
* Immediately after, use the LAST_QUERY_ID() function to identify the query that generated the forecast results.
* Create the table by querying that result set: CREATE TABLE tableX AS SELECT * FROM TABLE (RESULT_SCAN(LAST_QUERY_ID())); Evaluating the Options:
* Option A is incorrect because the CALL syntax does not support a direct INTO clause for table creation.
* Option B is incorrect because passing a table as an argument is part of the training or input phase, not the output persistence phase.
* Option D is overly complex and contains non-standard terminology ("List the cache content").
* Option C is the 100% correct answer. It reflects the required "post-processing" step in the Snowflake Data Cloud to bridge the gap between procedural model calls and relational table storage.
NEW QUESTION # 58
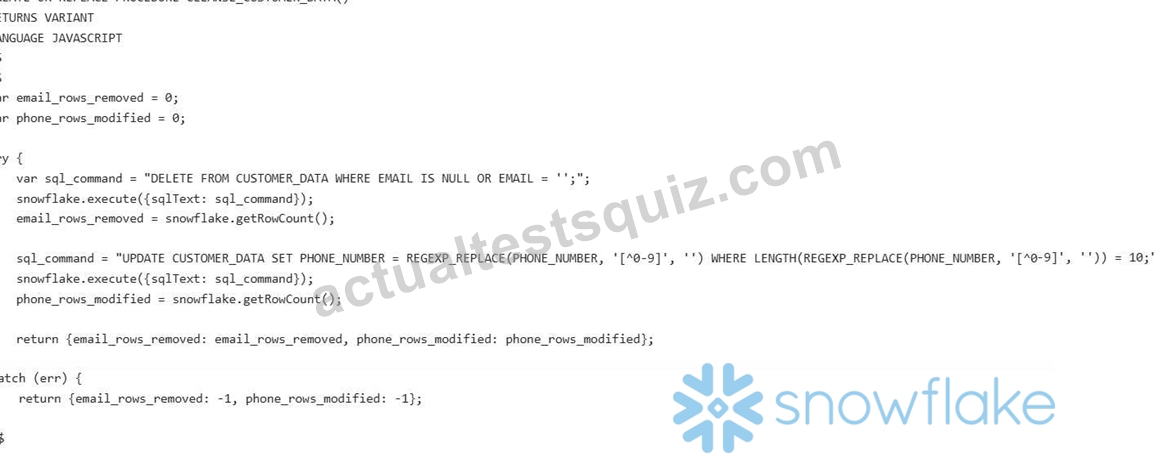
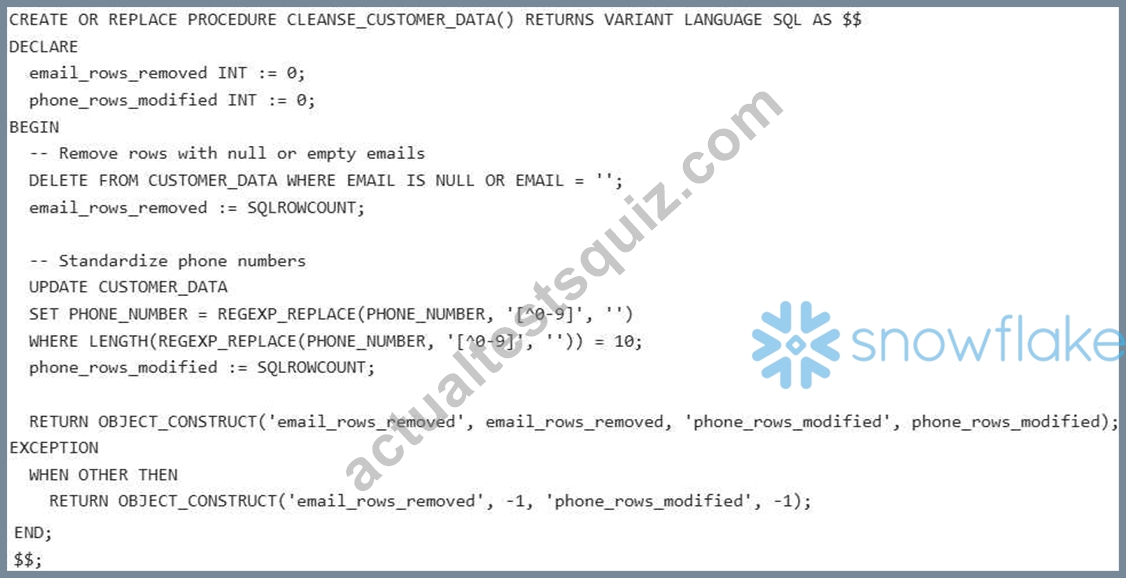
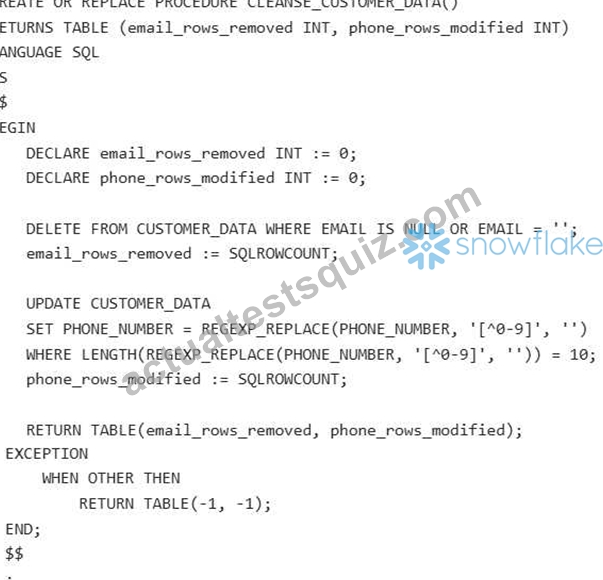
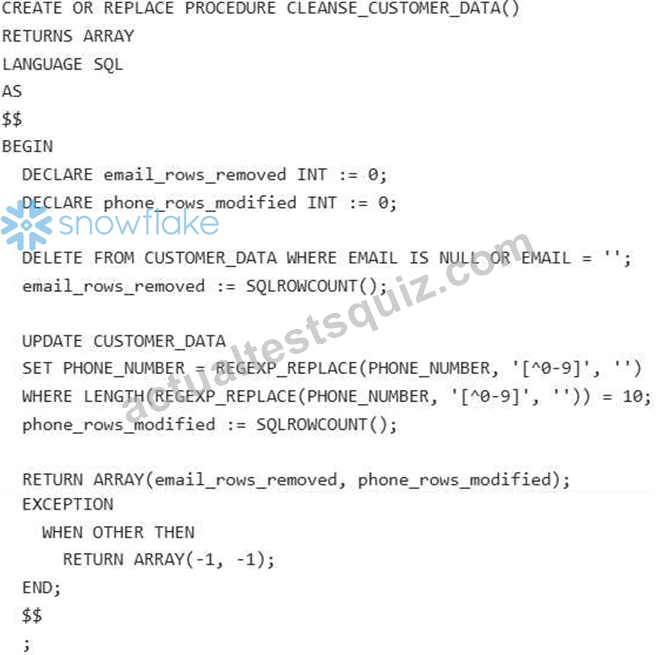
You are tasked with creating a stored procedure in Snowflake to perform data cleansing on a table named 'CUSTOMER DATA'. The procedure should: 1) Remove rows where the 'EMAIL' column is NULL or empty. 2) Standardize the 'PHONE NUMBER' column by removing all non-numeric characters and ensuring it's exactly 10 digits long. 3) Return the number of rows removed due to invalid emails and the number of rows modified due to phone number standardization. Assume the table already exists and contains columns 'CUSTOMER (INT), (VARCHAR), and 'PHONE NUMBER (VARCHAR). Which of the following code snippets correctly implements this stored procedure? The procedure should use exception handling to gracefully handle errors, returning -1 for both counts if any error occurs.
Answer: B
Explanation:
Option A is correct because it uses SQL to perform the data cleansing tasks, correctly utilizes 'SQLROWCOUNT' to capture the number of affected rows, and returns the results as a VARIANT OBJECT. It also includes proper exception handling. Options B, C, and D have errors in syntax or logic regarding return types, variable declaration, or how to retrieve row counts. Specifically, using Javascript or returning an ARRAY/TABLE when VARIANT is more flexible in this scenario.
NEW QUESTION # 59
When manipulating data in Snowflake, what distinguishes aggregate functions from analytic functions?
Answer: C
Explanation:
Analytic functions perform calculations on individual rows within a partition, while aggregate functions operate on entire datasets, making them distinct in their functionality.
NEW QUESTION # 60
......
You can set time to test your study efficiency, so that you can accomplish your test within the given time when you are in the real DAA-C01 exam. Moreover, you can adjust yourself to the exam speed and stay alert according to the time-keeper that we set on our DAA-C01 training materials. Therefore, you can trust on our DAA-C01 Study Guide for this effective simulation function will eventually improve your efficiency and assist you to succeed in the DAA-C01 exam. Just have a try on our free demo of DAA-C01 exam questions!
Exam DAA-C01 Papers: https://www.actualtestsquiz.com/DAA-C01-test-torrent.html
BONUS!!! Download part of ActualTestsQuiz DAA-C01 dumps for free: https://drive.google.com/open?id=1bBAY7CItCuhhxkjVCTeeXQtEKDO1eeXT