BONUS!!! JPNTest Databricks-Certified-Data-Engineer-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1wz2CrLAell4ZUa58MszMVQfGTiNkQhXH
当社Databricksでは、多くの分野の専門家を雇用してDatabricks-Certified-Data-Engineer-Associate学習ガイドを作成しているため、学習教材の品質を安心してご利用いただけます。 さらに、Databricks-Certified-Data-Engineer-Associate試験問題のガイダンスに基づいて試験の準備をすることで、JPNTest近い将来昇進する機会を増やし、給与を引き上げることができます。 したがって、Databricks Certified Data Engineer Associate Exam試験を受ける準備ができたら、Databricks-Certified-Data-Engineer-Associate学習教材を利用できます。 次の受益者になりたい場合、何を待っていますか? Databricks-Certified-Data-Engineer-Associate学習教材を購入してください。
GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) 試験は、Databricks を使用したデータエンジニアリングの熟練度を検証したいプロフェッショナル向けに設計された認定試験です。この試験は、データ変換、ETL プロセス、データモデリング、データウェアハウスなど、Databricks のさまざまな側面をカバーしています。この認定は、グローバルに認められ、候補者の Databricks データエンジニアリングにおける専門知識を示します。
Databricks認定データエンジニアアソシエイト資格は、ITおよびビジネスプロフェッショナル向けのプロフェッショナル認定を提供するリーディングプロバイダーであるGAQMによって提供されています。 GAQMは、世界中の雇用主や専門家に認められた高品質の認定試験を提供することで評判があります。Databricks認定データエンジニアアソシエイト資格も例外ではありません。
>> Databricks Databricks-Certified-Data-Engineer-Associate資格準備 <<
Databricks Databricks-Certified-Data-Engineer-Associate試験を目前に控えて、不安なのですか。我々社のDatabricks Databricks-Certified-Data-Engineer-Associate問題集のソフト版を購買するに値するかまだ疑問がありますか。こうしたら、我々JPNTestのDatabricks-Certified-Data-Engineer-Associate問題集デーモを無料にダウンロードして行動してみよう。我々提供するDatabricks-Certified-Data-Engineer-Associate試験資料はあなたの需要を満足できると知られています。我々にとって、Databricks Databricks-Certified-Data-Engineer-Associate試験に参加する圧力を減らして備考効率を高めるのは大変名誉のことです。
GAQMのDatabricks-Certified-Data-Engineer-Associate(Databricks認定データエンジニアアソシエイト)試験は、Databricksを使用してビッグデータソリューションを設計および実装する専門知識を証明したい個人を対象とした認定プログラムです。この試験は、Databricksを使用して大規模なデータ処理システムを構築および管理するスキルを検証したいデータエンジニア、データアナリスト、ビッグデータアーキテクトを対象としています。
質問 # 146
A data engineer has realized that the data files associated with a Delta table are incredibly small. They want to compact the small files to form larger files to improve performance.
Which of the following keywords can be used to compact the small files?
正解:B
解説:
The keyword that can be used to compact the small files associated with a Delta table is OPTIMIZE. The OPTIMIZE command performs file compaction on a Delta table by rewriting a set of small files into a set of larger files1. This can improve the performance of queries that scan the table by reducing the number of files that need to be read and the amount of metadata that needs to be processed1. The OPTIMIZE command can also optionally sort the data within each file by a given set of columns, which can further improve the query performance by enabling data skipping and predicate pushdown1. The OPTIMIZE command can be applied to the whole table or to a specific partition of the table1.
The other keywords are not suitable for compacting the small files associated with a Delta table. REDUCE is a keyword used in the SQL syntax for aggregating data using a user-defined function2. COMPACTION is not a valid keyword in SQL or Python. REPARTITION is a keyword used in the Python syntax for changing the number of partitions of a DataFrame or an RDD3. VACUUM is a keyword used to remove files that are no longer referenced by a Delta table and are older than a retention threshold4.
Reference:
1: OPTIMIZE | Databricks on AWS
2: REDUCE | Databricks on AWS
3: repartition | Databricks on AWS
4: VACUUM | Databricks on AWS
質問 # 147
A data engineer is developing an ETL process based on Spark SQL. The execution fails. The data engineer checks the Spark Ul and can see the ERRORS as follows:
Which two corrective actions should the data engineer perform to resolve this issue?
Choose 2 answers - (Q) Narrow the filters in order to collect less data in the query
正解:B、C
質問 # 148
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also used by other processes. As a result, the files should be kept as is and will accumulate in the directory.
The data engineer needs to identify which files are new since the previous run in the pipeline, and set up the pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
正解:A
解説:
Auto Loader is a tool that can incrementally and efficiently process new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a Structured Streaming source called cloudFiles, which automatically detects and processes new files in a given input directory path on the cloud file storage.
Auto Loader also tracks the ingestion progress and ensures exactly-once semantics when writing data into Delta Lake. Auto Loader can ingest various file formats, such as JSON, CSV, XML, PARQUET, AVRO, ORC, TEXT, and BINARYFILE. Auto Loader has support for both Python and SQL in Delta Live Tables, which are a declarative way to build production-quality data pipelines with Databricks. References: What is Auto Loader?, Get started with Databricks Auto Loader, Auto Loader in Delta Live Tables
質問 # 149
A data engineer is working with two tables. Each of these tables is displayed below in its entirety.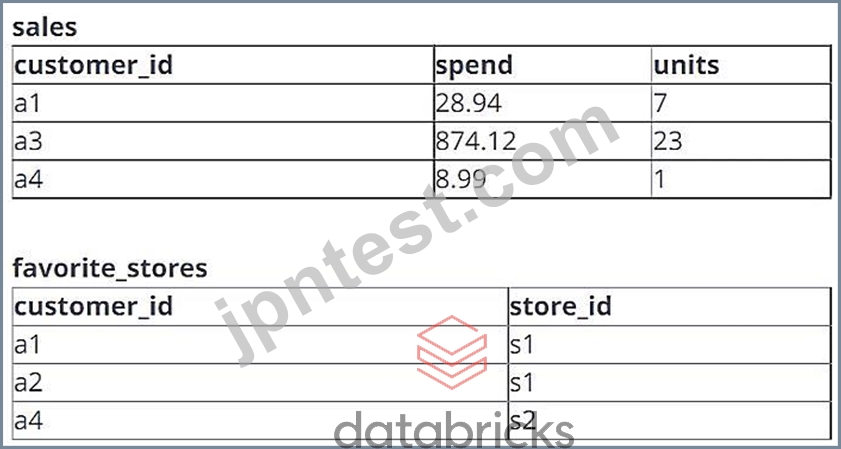
The data engineer runs the following query to join these tables together: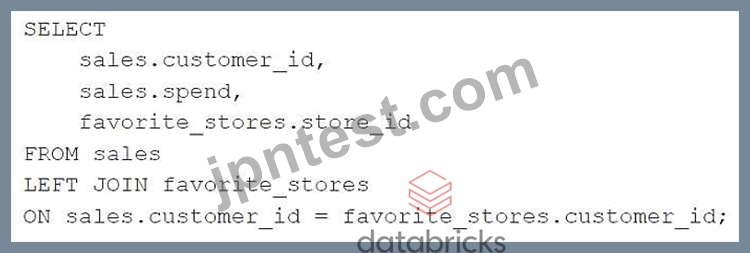
Which of the following will be returned by the above query?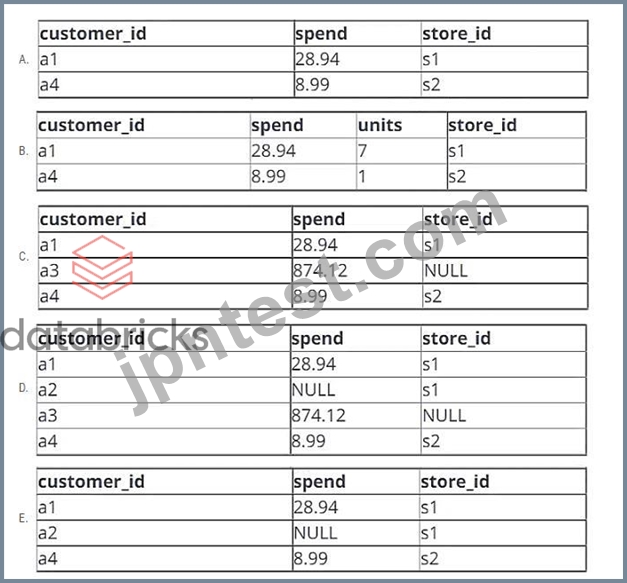
正解:D
解説:
Option A is the correct answer because it shows the result of an INNER JOIN between the two tables. An INNER JOIN returns only the rows that have matching values in both tables based on the join condition. In this case, the join condition is ON a.customer_id = c.customer_id, which means that only the rows that have the same customer ID in both tables will be included in the output. The output will have four columns:
customer_id, name, account_id, and overdraft_amt. The output will have four rows, corresponding to the four customers who have accounts in the account table.
The use of INNER JOIN can be referenced from Databricks documentation on SQL JOIN or from other sources like W3Schools or GeeksforGeeks.
質問 # 150
Which of the following describes when to use the CREATE STREAMING LIVE TABLE (formerly CREATE INCREMENTAL LIVE TABLE) syntax over the CREATE LIVE TABLE syntax when creating Delta Live Tables (DLT) tables using SQL?
正解:C
解説:
A streaming live table or view processes data that has been added only since the last pipeline update.
Streaming tables and views are stateful; if the defining query changes, new data will be processed based on the new query and existing data is not recomputed. This is useful when data needs to be processed incrementally, such as when ingesting streaming data sources or performing incremental loads from batch data sources. A live table or view, on the other hand, may be entirely computed when possible to optimize computation resources and time. This is suitable when data needs to be processed in full, such as when performing complex transformations or aggregations that require scanning all the data. References: Difference between LIVE TABLE and STREAMING LIVE TABLE, CREATE STREAMING TABLE, Load data using streaming tables in Databricks SQL.
質問 # 151
......
Databricks-Certified-Data-Engineer-Associateテストサンプル問題: https://www.jpntest.com/shiken/Databricks-Certified-Data-Engineer-Associate-mondaishu
無料でクラウドストレージから最新のJPNTest Databricks-Certified-Data-Engineer-Associate PDFダンプをダウンロードする:https://drive.google.com/open?id=1wz2CrLAell4ZUa58MszMVQfGTiNkQhXH