P.S. Free & New NCP-BC-7.5 dumps are available on Google Drive shared by CramPDF: https://drive.google.com/open?id=1m7A8kKt9vB-uX1VQP9e4PVn6nQnekmK0
In today's society, our pressure grows as the industry recovers and competition for the best talents increases. By this way the NCP-BC-7.5 exam is playing an increasingly important role to assess candidates. Considered many of our customers are too busy to study, the NCP-BC-7.5 real study dumps designed by our company were according to the real exam content, which would help you cope with the NCP-BC-7.5 Exam with great ease. With about ten years’ research and development we still keep updating our NCP-BC-7.5 prep guide, in order to grasp knowledge points in accordance with the exam, thus your study process would targeted and efficient.
| Section | Weight | Objectives |
|---|---|---|
| Test BCDR Solutions | 25% | - Perform disaster recovery validation procedures - Verify site connectivity and replication throughput - Validate recovery plan execution and outcomes - Execute planned, unplanned, and test failovers |
| Interpret and Configure BCDR Requirements | 30% | - Translate business requirements into RPO/RTO objectives - Create and configure recovery plans - Determine prerequisites for BCDR configuration - Configure network and storage for BCDR - Select replication types: Async, NearSync, Synchronous, Metro - Configure snapshot policies and retention - Design secure BCDR environments: segmentation, RBAC, approval policies |
| Troubleshoot BCDR Failures | 20% | - Resolve storage and snapshot errors - Diagnose network-related replication failures - Troubleshoot replication and protection policy issues - Resolve misconfigurations in DR environments - Fix third-party backup integration problems |
| Perform BCDR Operational Tasks | 25% | - Snapshot-based VM and volume recovery - Self-service restore operations - Execute failover and failback workflows - Migrate legacy protection domains to modern policies - Post-failover cleanup and re-protection |
Under the tremendous stress of fast pace in modern life, sticking to learn for a NCP-BC-7.5 certificate becomes a necessity to prove yourself as a competitive man. Our NCP-BC-7.5 practice questions have been commonly known as the most helpful examination support materials and are available from global internet storefront. After years of unremitting efforts, our NCP-BC-7.5 Exam Materials and services have received recognition and praises by the vast number of customers. An increasing number of candidates choose our NCP-BC-7.5 study materials as their exam plan utility.
NEW QUESTION # 29
An administrator configures a protection policy that replicates workloads to two different recovery AZs (multisite deployment). Replication to both recovery AZs is successful. However, when attempting to perform failover to the second recovery AZ, the administrator cannot select it as a failover target.
Which setup step was most likely missed?
Answer: C
Explanation:
A multisite deployment in Nutanix Disaster Recovery allows a single primary cluster to replicate its workloads to multiple destination availability zones (AZs) for increased resilience. While a single " Protection Policy " can define the replication schedules to both recovery sites, the " Recovery Plan " is the separate object responsible for the actual orchestration of the failover.
A Recovery Plan is fundamentally a point-to-point object; it defines how to move workloads from Site A to Site B. If an administrator wants the ability to failover to either of two different recovery AZs, they must create two distinct Recovery Plans: one for AZ1 and another for AZ2. Each plan will contain the site-specific network mappings, boot sequences, and IP mappings relevant to that specific destination. If the administrator has only created a recovery plan for the first AZ, they will be able to see recovery points at both locations but will only have a " target " defined for the first site. The second AZ will not appear as a valid destination in the failover menu until its specific Recovery Plan is built and validated. This modular design ensures that each DR site can have its own customized networking and application orchestration logic.
NEW QUESTION # 30
Refer to Exhibit: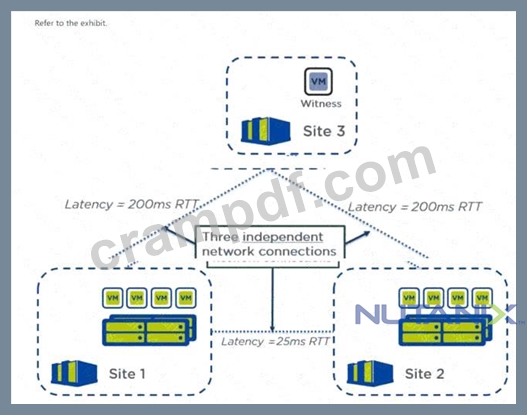
An administrator is configuring Metro Availability in their environment, as shown in the diagram. What issue in the configuration will prevent Metro from working correctly?
Answer: B
Explanation:
Nutanix Metro Availability and Synchronous Replication have very strict networking requirements to ensure that real-time data mirroring does not introduce unacceptable application latency. The industry-standard requirement for Nutanix synchronous operations is a maximum Round Trip Time (RTT) latency of 5ms between the two primary clusters (Site 1 and Site 2). According to the diagram provided in the question, the latency between Site 1 and Site 2 is 25ms RTT. This latency is significantly higher than the 5ms threshold and will prevent the Metro Availability configuration from functioning correctly. While the latency to the Witness VM (200ms RTT) is perfectly acceptable (Option D), and having a Witness at a third site (Option A) is a best practice, the " data path " between the storage clusters is the bottleneck here. If an administrator attempts to enable Metro with 25ms of latency, the guest VMs would experience severe performance degradation because every write would be delayed by the 25ms it takes to receive an acknowledgment from the remote site.
Therefore, the high latency between the data-serving sites is the primary configuration issue that must be resolved, typically by moving the clusters closer together or upgrading the inter-site fiber connection.
NEW QUESTION # 31
An administrator plans to migrate guest VMs from a legacy Protection Domain-based DR plan to the Prism Central-based Disaster Recovery solution. What should be done first before removing the legacy protection domains?
Answer: D
Explanation:
Modern Nutanix Disaster Recovery utilizes Prism Central-based Protection Policies and Recovery Plans, which offer more advanced orchestration and automation than legacy Prism Element-based Protection Domains. When an organization decides to upgrade its DR management, a careful migration path must be followed to ensure that VMs do not lose protection during the transition.
The first and most critical step is to migrate the virtual machines from the legacy Protection Domain to a new PC-based Protection Policy. This process involves adding the VMs to the correct Categories in Prism Central, which then associates them with the new policy. Once the VMs are " claimed " by the Protection Policy, the system will begin managing their snapshots and replication schedules according to the new logic. Only after the VMs are successfully protected under the new system is it safe to " unprotect " them and remove the legacy Protection Domains (and their associated snapshots) to reclaim storage. Attempting to delete snapshots first (Option A) or perform a failover (Option D) before the management handoff is complete could leave the business without a valid recovery point if an outage occurs during the migration window.
NEW QUESTION # 32
A VM is configured with a 5-minute Nearsync RPO. After several hours, replication transitions back to hourly RPO. Alerts indicate the minute schedule cannot be maintained. What is the most likely root cause?
Answer: D
Explanation:
Nutanix NearSync replication uses Lightweight Snapshots (LWS) to achieve RPOs as low as 1 minute. To maintain this aggressive schedule, the system must be able to replicate all the " delta " changes (the data that has changed since the last snapshot) within the RPO window. If the data change rate (churn) of the VM increases, or if the available network bandwidth decreases, the system may find that it cannot complete the replication of one LWS before the next one is due.
When the Nutanix Cerebro service detects that it is consistently missing its NearSync target, it will automatically " downshift " the replication to a standard Asynchronous schedule (typically hourly) to ensure that the VM remains protected at a manageable frequency. This is a self-healing mechanism designed to prevent replication jobs from stacking up and causing cluster instability. Insufficient bandwidth (Option D) is the most common cause for this downshift, as the " Snapshot-on-wire " cannot be moved fast enough to satisfy the 5-minute requirement. While high RTT (Option A) is a requirement for Synchronous replication, NearSync is designed to handle higher latencies (up to 80ms or more), making bandwidth the primary bottleneck in these troubleshooting scenarios.
NEW QUESTION # 33
An organization is finalizing its Disaster Recovery (DR) plan. The primary objective is to balance cost- efficiency with a target RTO of under 15 minutes. Data currently resides in Object Storage, but the team is debating between a Zero Compute approach and a Pilot Light approach. Why would a Pilot Light infrastructure be selected over a Zero Compute model despite the higher " Moderate " cost?
Answer: A
Explanation:
When designing disaster recovery to a cloud environment (such as NC2 on AWS or Azure), organizations must choose a compute model that aligns with their Recovery Time Objective (RTO). The " Zero Compute " model is the most cost-efficient because it stores only the data (snapshots) in low-cost Object Storage (S3 or Blob) and does not maintain a running cluster. However, the RTO for Zero Compute is high because, in a disaster, the organization must first deploy a new Nutanix cluster, configure it, and then begin the process of hydrating data from the Object Storage.
In contrast, the " Pilot Light " model involves keeping a minimal, active Nutanix cluster (e.g., 3 nodes) running at the recovery site. While this carries a moderate ongoing cost, it significantly reduces the RTO.
Because the cluster already exists, the management plane (Prism Central), the storage containers, and all metadata are already active. When a failover is triggered, the system only needs to power on the VMs or perform a small amount of data hydration. This allows the organization to meet aggressive RTO targets of under 15 minutes, which is generally impossible with the Zero Compute model. Pilot Light provides the " ready-to-go " infrastructure needed for mission-critical applications that cannot afford the multiple hours required to provision a fresh cluster from scratch during an emergency.
NEW QUESTION # 34
......
CramPDF assists people in better understanding, studying, and passing more difficult certification exams. We take pride in successfully servicing industry experts by always delivering safe and dependable exam preparation materials. You will need authentic Nutanix NCP-BC-7.5 Exam Preparation material if you want to take the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 exam to expand your career opportunities.
Latest NCP-BC-7.5 Practice Materials: https://www.crampdf.com/NCP-BC-7.5-exam-prep-dumps.html
P.S. Free 2026 Nutanix NCP-BC-7.5 dumps are available on Google Drive shared by CramPDF: https://drive.google.com/open?id=1m7A8kKt9vB-uX1VQP9e4PVn6nQnekmK0