Sie können im Internet teilweise die Fragenkatalogen zur Nutanix NCP-BC-7.5 Zertifizierungsprüfung von ITZert kostenlos herunterladen. Dann werden Sie mehr Vertrauen in unsere Produkte haben. Sie können sich dann gut auf Ihre Nutanix NCP-BC-7.5 Zertifizierungsprüfung vorbereiten. Schicken bitte schnell die Produkte von ITZert in den Warenkorb.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Perform BCDR Operational Tasks | 25% | - Execute failover and failback workflows - Snapshot-based VM and volume recovery - Self-service restore operations - Migrate legacy protection domains to modern policies - Post-failover cleanup and re-protection |
| Topic 2: Test BCDR Solutions | 25% | - Perform disaster recovery validation procedures - Execute planned, unplanned, and test failovers - Validate recovery plan execution and outcomes - Verify site connectivity and replication throughput |
| Topic 3: Interpret and Configure BCDR Requirements | 30% | - Configure snapshot policies and retention - Select replication types: Async, NearSync, Synchronous, Metro - Create and configure recovery plans - Translate business requirements into RPO/RTO objectives - Configure network and storage for BCDR - Design secure BCDR environments: segmentation, RBAC, approval policies - Determine prerequisites for BCDR configuration |
| Topic 4: Troubleshoot BCDR Failures | 20% | - Troubleshoot replication and protection policy issues - Resolve storage and snapshot errors - Resolve misconfigurations in DR environments - Fix third-party backup integration problems - Diagnose network-related replication failures |
>> Nutanix NCP-BC-7.5 Online Test <<
Wir bemühen uns nun darum, den Kandidaten rechtzeitigen und effizieten Service zu bieten, um Ihre wertvolle Zeit zu ersparen. ITZert bietet Ihnen zahlreiche Lerntipps, Fragen und Antworten zur Nutanix NCP-BC-7.5 Zertifizierungsprüfung. Einige Websites bieten Ihnen auch Lernmaterialien zur NCP-BC-7.5 Zertifizierungsprüfung, die von guter Qualität ist und mit dem Zeit Schritt halten. Aber ITZert ist die einzige Website, die beste Schulungsunterlagen zur NCP-BC-7.5 Zertifizierungsprüfung bietet. Mit Hilfe der Lernmaterialien und der Anleitung von ITZert können Sie die Nutanix NCP-BC-7.5 Zertifizierungsprüfung einmalig bestehen.
29. Frage
An administrator recently expanded a Nutanix cluster by adding several new nodes. Shortly after, multiple backup jobs began failing. The following error is consistently reported: " Failed to perform backup: Cannot complete process ' iscsiadm --mode discovery --type sendtargets --portal X.X.X.X ' within timeout " . What is the most likely cause of the failure?
Antwort: A
Begründung:
Nutanix storage is often accessed by external backup solutions (like Veeam, Commvault, or HYCU) using the iSCSI protocol. This allows the backup server to mount snapshots and read data directly from the storage tier.
The error message " iscsiadm... discovery... timeout " specifically indicates that the backup server ' s iSCSI initiator is unable to communicate with the Nutanix Data Services IP or the Controller VMs (CVMs) over the network.
When a Nutanix cluster is expanded, it is essential that all networking and firewall configurations applied to the existing nodes are also applied to the new nodes. The iSCSI protocol relies on specific TCP ports: port
3260 is the standard port for iSCSI traffic, and port 3205 is often used for iSCSI discovery and metadata operations within Nutanix. If these ports are not open in the physical firewall or the host-based security rules for the newly added nodes, the backup server will be unable to discover the targets on those specific nodes, leading to the timeout errors . This highlights a common " Day 2 " operational trap: cluster expansion requires careful auditing of network security groups and firewall whitelists to ensure that external integrations- especially BCDR and backup services-continue to have uninterrupted access to the expanded storage fabric.
Verifying and opening ports 3205 and 3260 for the new node IPs is the first step to resolving this timeout issue.
30. Frage
Exhibit: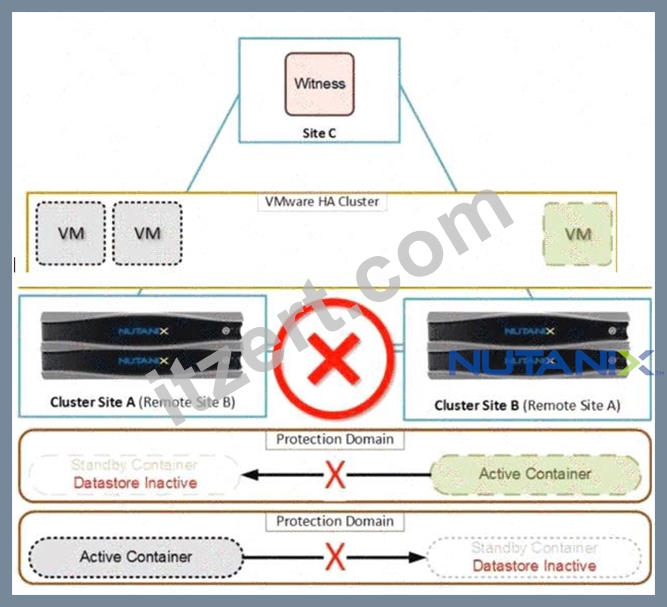
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
Antwort: B
Begründung:
Security hardening for BCDR is focused on protecting the integrity of recovery points against accidental deletion, administrative errors, or malicious intent such as ransomware. While infrastructure-level hardening like SSH keys (Option C) or host-level security (Option A) is important, they do not prevent a user with valid administrative credentials in Prism from deleting a snapshot. To address the specific requirement of ensuring only " authorized " and verified actions can modify or delete snapshots, the administrator should implement an " Approval Policy " .
An Approval Policy introduces a " four-eyes " principle for critical management tasks. When this policy is active, any attempt to delete or modify a recovery point does not execute immediately. Instead, it triggers a request in the Prism Central " Task " console and enters a " Pending Approval " state. A separate authorized user-an " Approver " -must then review the request and explicitly grant permission before the deletion can occur. This creates a vital procedural safeguard, ensuring that no single individual has the unilateral power to destroy the organization ' s backup data. By configuring this policy, the administrator hardens the DR environment against both internal threats and external actors who might gain access to a single set of admin credentials, providing a robust layer of defense for critical data assets.
31. Frage
An administrator plans on performing a failover of a VM from a source cluster to a DR cluster. The administrator needs the VM ' s IP address preserved after failover. In what scenario is the VM ' s IP address preserved?
Antwort: C
Begründung:
Preserving IP addresses during a failover is a common requirement for applications with hardcoded IP references or complex inter-service dependencies. In a standard multi-site DR setup, the source and destination sites reside on different Layer 3 subnets, meaning a VM would naturally require a new IP address to be routable at the recovery site. To achieve " IP Preservation, " the underlying network infrastructure must support Layer 2 (L2) stretching.
L2 stretching (often implemented via VXLAN or specialized VPN tunnels like Nutanix Flow Virtual Networking) allows a single logical subnet to span multiple physical locations. When a VM fails over to a cluster on a stretched subnet, it effectively stays on the same network broadcast domain. As a result, its IP address, default gateway, and subnet mask remain valid and unchanged. If the subnets are not stretched, the administrator must rely on the Recovery Plan ' s " IP Mapping " feature to assign a new, valid IP at the destination-which does not " preserve " the original address. While preserving IPs simplifies application recovery, it requires more complex network engineering to ensure that traffic is correctly routed to the active site during a disaster, highlighting the trade-off between application simplicity and infrastructure complexity in BCDR design.
32. Frage
An administrator has recently completed the initial configuration of Nutanix Disaster Recovery for a production environment. Protection Policies and Recovery Plans have been configured and validated by the senior infrastructure team.
The administrator has confirmed that the expected categories are correctly associated with both the Protection Policies and Recovery Plans. During a scheduled test failover, the administrator notices that several VMs are missing from the recovery.
The administrator reviews the environment and notes the following:
* The Protection Summary tab does not show any warnings or errors
* No replication tasks are currently ongoing
* The missing VMs were all deployed within the last two weeks as part of a new application rollout
* The missing VMs are running on the same cluster as other VMs that recovered successfully during the test failover
* The application team followed the standard VM deployment checklist but did not coordinate with the infrastructure team during provisioning Given this information, what is the most likely cause of the missing VMs?
Antwort: A
Begründung:
Modern Nutanix Disaster Recovery (Leap) relies on " Categories " to automate the inclusion of virtual machines into Protection Policies and Recovery Plans. When a Protection Policy is created, it is typically applied to a category (e.g., AppType:SQL) rather than individual VM names.
In this scenario, the newly deployed VMs were missed during a test failover despite other VMs on the same cluster recovering successfully. The most likely root cause is that the application team, working independently, failed to assign the required categories to the new VMs during the provisioning process.
Because the VMs lacked the correct category tags, the Nutanix Protection Policy did not " see " them, and consequently, no recovery points were ever created for them. This is a common operational failure in environments where " infrastructure as code " or strict provisioning standards are not enforced. Recovery Plans (Option A) do not need manual re-synchronization for new VMs if the categories are correctly mapped.
While an initial sync is required (Option D), it would typically show a task or progress rather than just leaving the VMs " missing " from the entire protection summary. Therefore, verifying category assignment is the primary troubleshooting step.
33. Frage
An administrator plans to configure Cross Hypervisor Disaster Recovery (CHDR) to replicate VMs from an ESXi cluster to an AHV cluster using an Asynchronous replication schedule. Which component must be installed on the VMs to ensure successful migration and driver configuration during recovery?
Antwort: B
Begründung:
Cross-Hypervisor Disaster Recovery (CHDR) allows for the seamless replication and failover of workloads between different hypervisor platforms, such as moving from VMware ESXi to Nutanix AHV. The primary technical challenge in CHDR is ensuring that the virtual machine has the correct storage and network drivers to boot on the new hypervisor. For instance, a VM running on ESXi uses VMware-specific drivers, while AHV requires Nutanix VirtIO drivers.
Nutanix Guest Tools (NGT) is the mandatory component that handles this translation process automatically.
When NGT is installed on a VM running on ESXi, it includes the necessary Nutanix drivers in a dormant state. During a failover to an AHV cluster, the Nutanix orchestration engine uses the NGT hooks to inject and activate these drivers, ensuring the VM can successfully recognize its virtual disks and network adapters upon power-on at the recovery site. Without NGT, the VM would likely suffer a " Blue Screen of Death " (BSOD) on Windows or a kernel panic on Linux due to the missing boot drivers. While manual VirtIO installation (Option A) is possible, NGT provides the integrated orchestration required for a reliable, automated BCDR workflow, making it the essential component for CHDR success.
34. Frage
......
Wenn wir am Anfang die Fragenkataloge zur Nutanix NCP-BC-7.5 Zertifizierungsprüfung bieteten, haben wir niemals geträumt, dass wir so einen guten Ruf bekommen können. Wir geben Ihnen die unglaubliche Garantie. Wenn Sie die Produkte von ITZert für Ihre Nutanix NCP-BC-7.5 Zertifizierungsprüfung benutzen, versprechen wir Ihnen, die Prüfung 100% zu bestehen.
NCP-BC-7.5 Exam Fragen: https://www.itzert.com/NCP-BC-7.5_valid-braindumps.html