Use Desktop CompTIA DY0-001 Practice Test Software To Identify Gaps In Knowledge

BTW, DOWNLOAD part of Actual4Dumps DY0-001 dumps from Cloud Storage: https://drive.google.com/open?id=1eSlGvt6-ePzIc1C_QKj52sysnbzZwhPQ
They are committed to assisting you in CompTIA DY0-001 exam preparation and boosting the DY0-001 exam candidate's confidence to pass it. The CompTIA DataAI Certification Exam (DY0-001) exam questions are designed and verified by CompTIA exam trainers. They check and ensure each DY0-001 Practice Questions are real, updated, and accurate. So rest assured that with the CompTIA DataAI Certification Exam (DY0-001) practice exams you can get success in challenging the DY0-001 exam easily.
CompTIA DY0-001 Exam Overview:
| Certification Vendor: | CompTIA |
|---|
| Exam Name: | CompTIA DataAI Certification Exam |
|---|
| Exam Number: | DY0-001 |
|---|
| Available Languages: | Japanese, English |
|---|
| Exam Duration: | 165 minutes |
|---|
| Exam Format: | Multiple Choice, Performance-Based |
|---|
| Exam Price: | $529 USD |
|---|
| Passing Score: | Pass/Fail (No scaled score) |
|---|
| Related Certifications: | CompTIA DataAI (formerly DataX) |
|---|
| Real Exam Qty: | Up to 90 |
|---|
| Certificate Validity Period: | Usually 3 years |
|---|
| Sample Questions: | CompTIA DY0-001 Sample Questions |
|---|
| Exam Way: | Available at Pearson VUE testing centers or via online proctoring (OnVUE). |
|---|
| Pre Condition: | 5+ years of experience in data science or a similar role recommended. |
|---|
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai |
|---|
>> Exam DY0-001 Passing Score <<
CompTIA DY0-001 Practice Tests | Reliable DY0-001 Exam Answers
There may be a lot of people feel that the preparation process for DY0-001 exams is hard and boring, and hard work does not necessarily mean good results, which is an important reason why many people are afraid of examinations. Today, our DY0-001 Exam Materials will radically change this. High question hit rate makes you no longer aimless when preparing for the exam, so you just should review according to the content of our DY0-001 study guide prepared for you.
| Topic | Details |
|---|
| Topic 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 2 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| Topic 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| Topic 4 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 5 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
CompTIA DataAI Certification Exam Sample Questions (Q67-Q72):
NEW QUESTION # 67
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
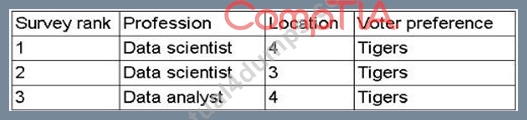
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. Extrapolated data
- B. Out-of-sample data
- C. Interpolated data
- D. In-sample data
Answer: A
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 68
Which of the following measures would a data scientist most likely use to calculate the similarity of two text strings?
- A. String indexing
- B. k-nearest neighbors
- C. Edit distance
- D. Word cloud
Answer: C
Explanation:
# Edit distance (also known as Levenshtein distance) measures how many single-character edits (insertions, deletions, or substitutions) are needed to transform one string into another. It's a common metric for assessing string similarity, especially in natural language processing (NLP) tasks.
Why the other options are incorrect:
* A: Word clouds visualize word frequency, not similarity.
* C: String indexing is a method for referencing string positions, not comparison.
* D: k-NN is a classification algorithm, not a string similarity measure.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 6.3:"Edit distance is a key similarity metric in text comparison tasks, particularly in cleaning or matching string records."
-
NEW QUESTION # 69
Which of the following belong in a presentation to the senior management team and/or C-suite executives? (Choose two.)
- A. High-level results
- B. Detailed explanations of statistical tests
- C. Final recommendations
- D. Security keys and login information
- E. Code snippets
- F. Full literature reviews
Answer: C
Explanation:
Senior leaders need actionable insights and the overarching outcomes, not the implementation details, so you present your key recommendations alongside a summary of results at a high level.
NEW QUESTION # 70
A data scientist is standardizing a large data set that contains website addresses. A specific string inside some of the web addresses needs to be extracted. Which of the following is the best method for extracting the desired string from the text data?
- A. Named-entity recognition
- B. Regular expressions
- C. Large language model
- D. Find and replace
Answer: B
NEW QUESTION # 71
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. Out-of-sample data
- B. Interpolated data
- C. Extrapolated data
- D. In-sample data
Answer: A
Explanation:
The aggregated feedback covers only 80% of respondents, mostly from a few professions and locations, so the model hasn't "seen" the remaining 20% (and those underrepresented groups). Its performance on those unseen subsets (out-of-sample data) is therefore the primary concern for how well it will predict the actual vote.
NEW QUESTION # 72
......
DY0-001 Practice Tests: https://www.actual4dumps.com/DY0-001-study-material.html
- DY0-001 PDF Cram Exam 🐗 DY0-001 Valid Test Forum 🍈 New DY0-001 Test Pattern 🌀 Search for ▶ DY0-001 ◀ and easily obtain a free download on ▷ www.prepawayete.com ◁ 🗳DY0-001 New Dumps Pdf
- 100% Pass DY0-001 CompTIA DataAI Certification Exam Marvelous Exam Passing Score 🍵 Search for 【 DY0-001 】 on ⏩ www.pdfvce.com ⏪ immediately to obtain a free download 🔁DY0-001 Reliable Exam Labs
- DY0-001 certification training: CompTIA DataAI Certification Exam - DY0-001 study guide 🎐 Search for “ DY0-001 ” on ⏩ www.pass4test.com ⏪ immediately to obtain a free download 🕙Practice DY0-001 Exam
- New DY0-001 Test Book 🐬 DY0-001 Reliable Exam Labs 🦍 Certification DY0-001 Test Answers 🚖 Search for “ DY0-001 ” and download it for free on 【 www.pdfvce.com 】 website 😳Free DY0-001 Practice Exams
- DY0-001 certification training: CompTIA DataAI Certification Exam - DY0-001 study guide 🚉 Enter ➤ www.examcollectionpass.com ⮘ and search for ( DY0-001 ) to download for free 😨DY0-001 Valid Test Forum
- CompTIA DY0-001 Exam Questions in Convenient PDF Format 🤟 Download 《 DY0-001 》 for free by simply entering ➽ www.pdfvce.com 🢪 website 🦰DY0-001 Exam Vce Format
- DY0-001 Exam Vce Format ❤️ DY0-001 Latest Braindumps Book 🏃 DY0-001 Pdf Pass Leader 🐣 Open ➥ www.examcollectionpass.com 🡄 enter ➡ DY0-001 ️⬅️ and obtain a free download 🕵Free DY0-001 Practice Exams
- DY0-001 Exam Flashcards 🐨 DY0-001 Valid Exam Papers ⚜ Exam DY0-001 Guide 💇 Open ➤ www.pdfvce.com ⮘ and search for ➠ DY0-001 🠰 to download exam materials for free 💋DY0-001 Valid Test Vce Free
- DY0-001 certification training: CompTIA DataAI Certification Exam - DY0-001 study guide ✏ ▶ www.troytecdumps.com ◀ is best website to obtain ➡ DY0-001 ️⬅️ for free download 📑DY0-001 New Dumps Pdf
- CompTIA DY0-001 Study Material in Different Formats 💬 Easily obtain free download of ▶ DY0-001 ◀ by searching on ▛ www.pdfvce.com ▟ 🥝DY0-001 Valid Test Vce Free
- Exam DY0-001 Guide 🛑 Dumps DY0-001 Cost 🥥 DY0-001 Official Cert Guide 🤘 Search for ➡ DY0-001 ️⬅️ on 【 www.prepawaypdf.com 】 immediately to obtain a free download 📊Free DY0-001 Practice Exams
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, divisionmidway.org, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest Actual4Dumps DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1eSlGvt6-ePzIc1C_QKj52sysnbzZwhPQ