Topexamは、お客様に学習のためのさまざまな種類のMicrosoftのAI-500練習トレントを提供し、知識を蓄積し、試験に合格し、期待されるスコアを取得する能力を高めるための信頼できる学習プラットフォームです。 AI-500スタディガイドには、オンラインでPDF、ソフトウェア、APPの3つの異なるバージョンがあります。 顧客の信頼を確立するために、購入前にダウンロードできる関連するDesigning and Implementing Multi-Agent AI Solutions無料デモを提供しています。 AI-500試験の質問で、AI-500試験で勝つ自信があります。
| Section | Weight | Objectives |
|---|---|---|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
| Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
現在、多くの外資系会社はMicrosoftのAI-500試験認定を持つ職員に奨励を与えます。それに、AI-500試験に合格しない人々は大変なことであるでしょうか?我々のMicrosoftのAI-500問題集は試験に準備する受験生にヘルプを与えます。もしあなたはMicrosoftのAI-500試験に準備しているなら、弊社TopexamのAI-500問題集を使ってください。
質問 # 26
You have a Microsoft Foundry helpdesk triage agent. Employees sign in to the agent by using Microsoft Entra. The agent can invoke the following tools:
* A ticket search tool that enforces the existing per employee authorization model
* A knowledge article tool that writes to a separate production article repository You need to recommend an identity-based access configuration for the following execution contexts:
* Ensure that interactive ticket searches enforce per employee authorization.
* Constrain approved article updates to the production article repository The solution must meet the following requirements:
* Prevent the use of embedded secrets.
* Follow the principle of least privilege
Which access configurations should you recommend? To answer, drag the appropriate configurations to the correct execution contexts. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.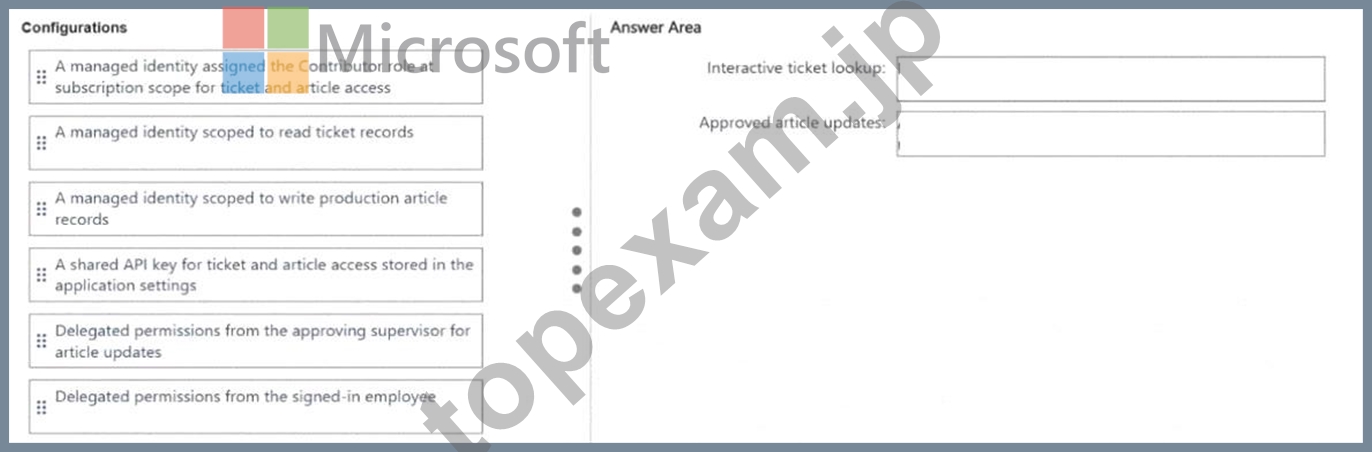
正解:
解説: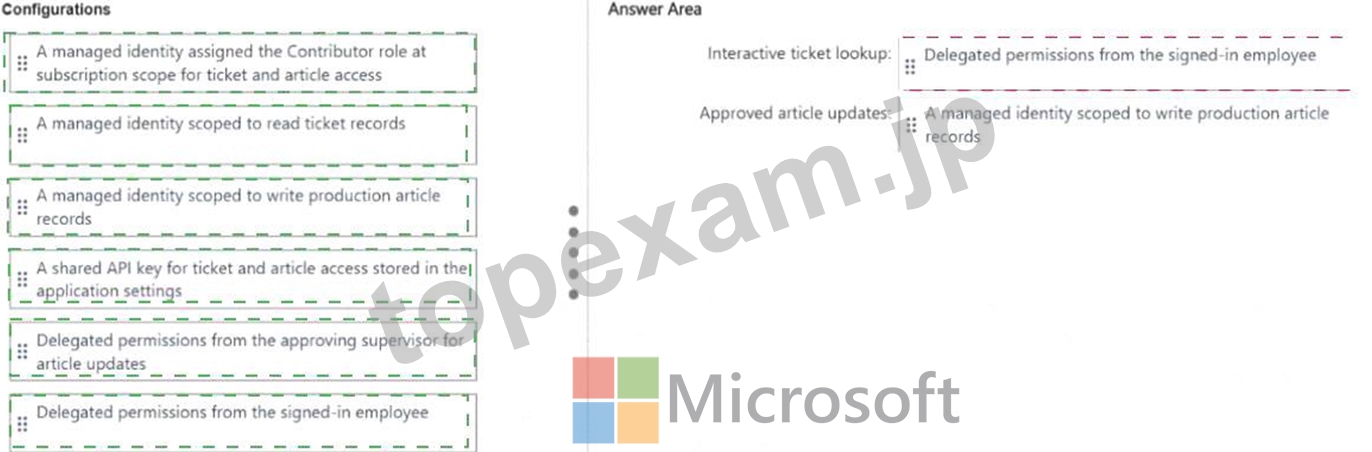
Explanation:
Interactive ticket lookup: Delegated permissions from the signed-in employee; Approved article updates: A managed identity scoped to write production article records.
Ticket search must preserve the existing per-employee authorization model, so the downstream operation should execute in the signed-in employee ' s delegated identity context. That allows the ticket service to enforce the same user-level permissions it already uses. The knowledge-article update is an application- controlled write to one production repository, so a managed workload identity with only the required write permission is the least-privilege choice. Microsoft identity guidance distinguishes delegated/on-behalf-of access for user-context operations from managed or agent identities for service-to-service work. Both approaches also eliminate embedded secrets when configured with Microsoft Entra authentication. A broad Contributor assignment or shared API key would unnecessarily expand the blast radius and weaken audit attribution. Therefore the mixed model in the answer is intentional: delegated permissions for per-user reads, and a narrowly scoped managed identity for controlled production writes. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry agent identity
質問 # 27
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
正解:C
質問 # 28
You have a Microsoft Foundry Agent Service solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and configure a static agent scope value for each memory search tool.
Does this meet the goal?
正解:A
解説:
A separate memory store for each agent correctly isolates the two agent domains, but a static scope shared by every user inside each store does not isolate end users. Multiple users ' memories would be written and searched within the same logical scope. Microsoft Foundry Memory explicitly recommends a user-derived scope such as `{{$userId}}` when per-user isolation is required. Scope-based deletion is also how one user ' s memory can be removed without deleting other users ' memories. With a single static scope, that deletion boundary does not exist. The proposed design therefore solves only the domain part of the problem and fails both user isolation and safe per-user deletion. Since all requirements must be satisfied, the correct answer is B, No. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Create and use memory in Foundry Agent Service
質問 # 29
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.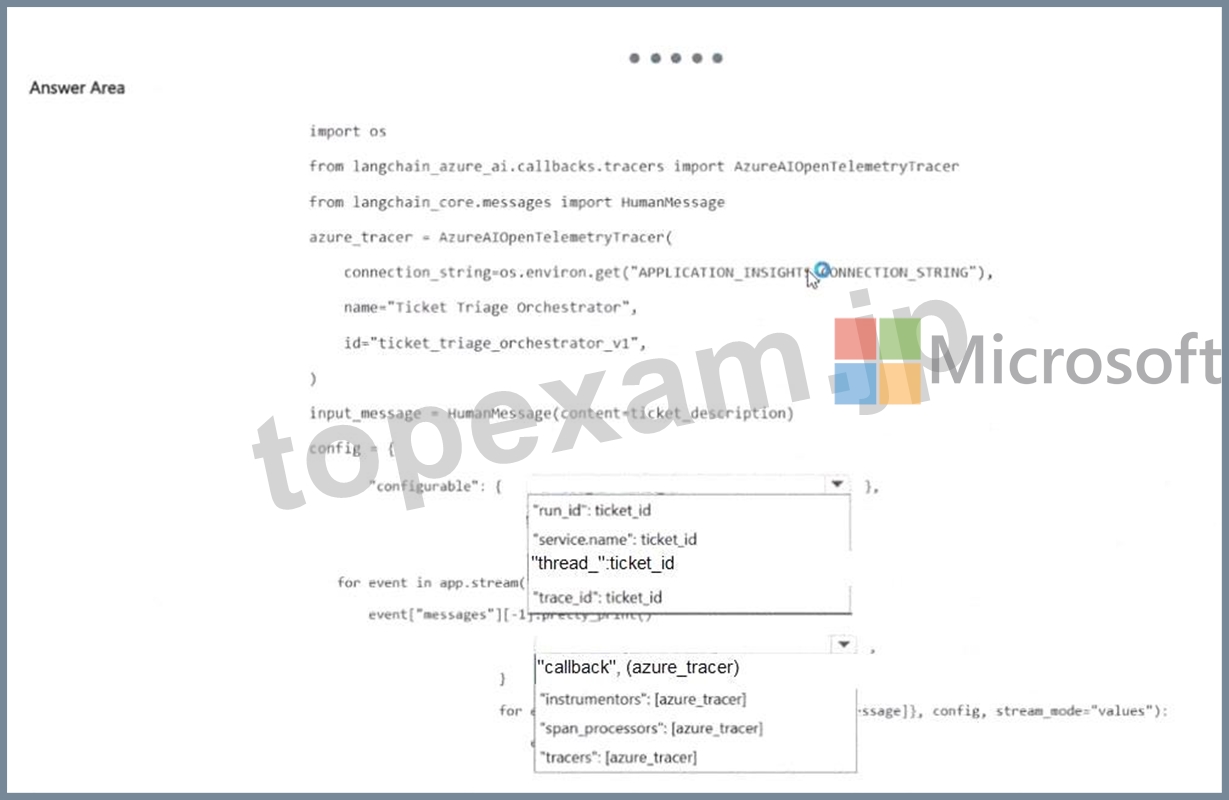
正解:
解説: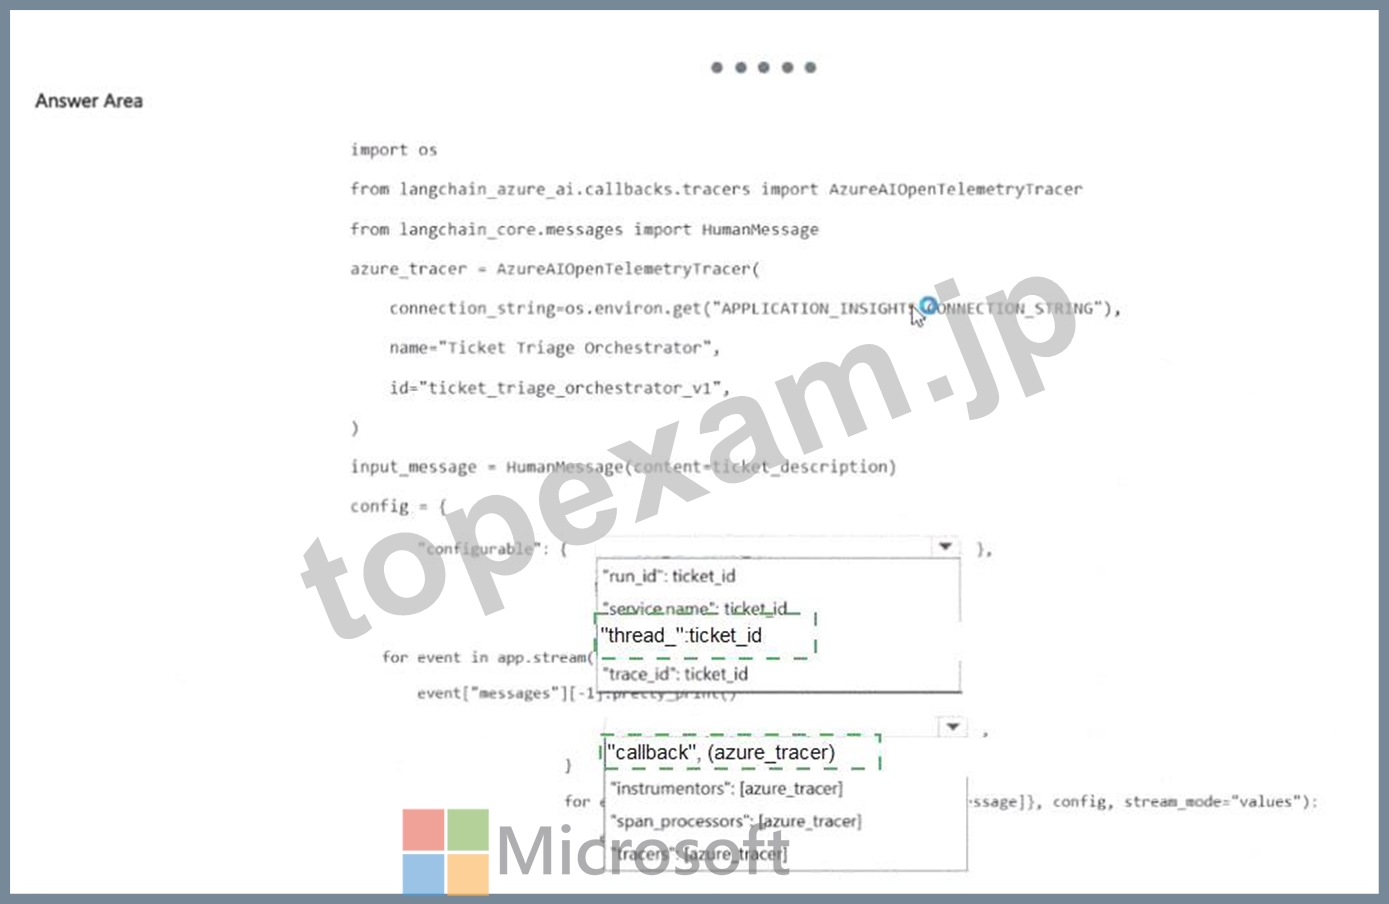
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents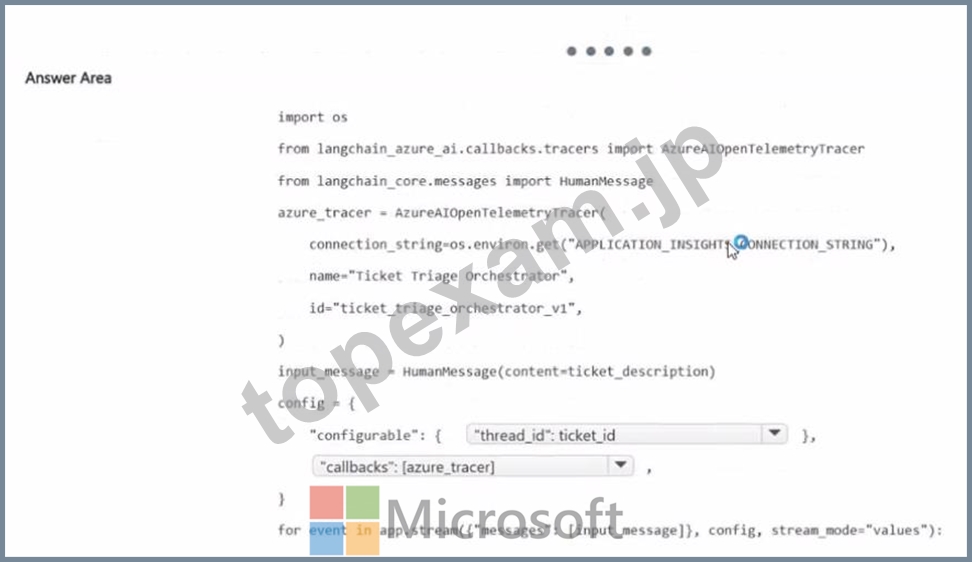
質問 # 30
You need to recommend changes to decrease the Claim Approval duration without breaking any existing functionality.
What should you recommend?
正解:A
解説:
Fraud-check, Policy-eligibility, and Document-summary are independent specialist activities, so running them concurrently reduces wall-clock time without changing their outputs. The Decision agent is different because the case study states that it depends on the results of those three agents. It therefore must execute only after the independent work completes. Microsoft Agent Framework ' s concurrent orchestration pattern is designed for independent participants whose results can be fanned in later, while dependency-driven work should remain ordered. Running all four agents concurrently would violate the Decision agent ' s data dependency.
Running all four sequentially would preserve correctness but add unnecessary latency. Disabling memory would also change functionality unrelated to the performance bottleneck. The optimal graph is therefore a parallel fan-out of the three independent specialists followed by a fan-in and Decision step, which preserves behavior while minimizing end-to-end claim-approval duration. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
質問 # 31
......
クライアントがAI-500試験トレントの料金を支払うと、5〜10分でシステムから送信されたメールを受け取ります。その後、クライアントはリンクをたたいてダウンロードすることができ、Microsoftその後、AI-500質問トレントを使用して学習できます。試験の準備をする人にとって時間は非常に重要であるため、クライアントは支払い後すぐにダウンロードできるため、AI-500ガイド急流の大きな利点です。したがって、クライアントがAI-500試験問題を使用して学習することは非常に便利です。
AI-500専門知識: https://www.topexam.jp/AI-500_shiken.html