Databricks-Certified-Professional-Data-Engineer practice tests
Our Databricks Certified Professional Data Engineer Exam exam questions are curated and crafted by experts. We have put in a lot of efforts to create amazing guides for our customers. Passing Databricks-Certified-Professional-Data-Engineer can be hard, and you won’t find such exam Databricks-Certified-Professional-Data-Engineer Brain Dumps anywhere. With Databricks-Certified-Professional-Data-Engineer sample questions exam dumps, you can secure high marks in the Databricks-Certified-Professional-Data-Engineer. We provide 100% money back guarantee on exam Databricks-Certified-Professional-Data-Engineer practice exam products.
| Section | Objectives |
|---|
| Topic 1: Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance
- Build and manage workflows using Databricks Jobs
- Automate ETL pipelines and scheduling
|
| Topic 2: Data Ingestion and Transformation | - Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
- Transform and clean datasets using Spark SQL and DataFrame APIs
|
| Topic 3: Data Modeling and Storage | - Design scalable data lakehouse architectures
- Schema evolution and data partitioning strategies
- Delta Lake table design and optimization
|
| Topic 4: Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads
- Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
|
>> Passing Databricks-Certified-Professional-Data-Engineer Score <<
Reliable Test Databricks-Certified-Professional-Data-Engineer Test & Databricks-Certified-Professional-Data-Engineer Latest Exam Pdf
For easy use, ExamsTorrent provides you with different version Databricks-Certified-Professional-Data-Engineer exam dumps. PDF version dumps are easy to read and reproduce the real exam. SOFT version dumps is a test engine which can measure what your preparations for the exam. If you want to know whether you prepare well for the Databricks-Certified-Professional-Data-Engineer test, you can take advantage of the SOFT version dumps to measure your ability. So you can quickly know your weaknesses and shortcomings, which is helpful to your further study.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q47-Q52):
NEW QUESTION # 47
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
Which kind of the test does the above line exemplify?
- A. Manual
- B. Integration
- C. Unit
- D. functional
Answer: C
Explanation:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function.
Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
:
Software Testing Fundamentals: Unit Testing
NEW QUESTION # 48
The data engineering team maintains the following code:
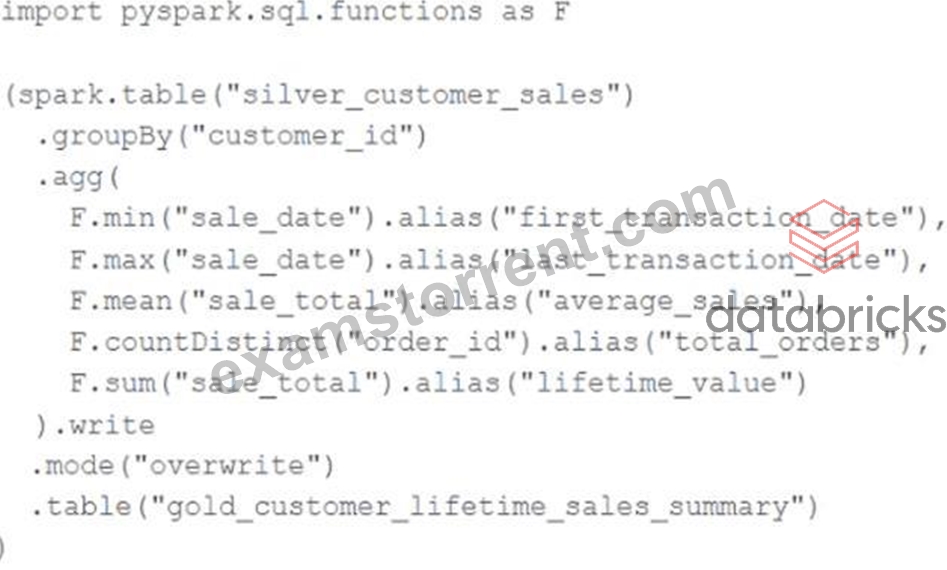
Assuming that this code produces logically correct results and the data in the source table has been de- duplicated and validated, which statement describes what will occur when this code is executed?
- A. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
- B. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- C. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- D. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- E. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
Answer: B
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References :
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 49
A data analyst has noticed that their Databricks SQL queries are running too slowly. They claim that this issue
is affecting all of their sequentially run queries. They ask the data engineering team for help. The data
engineering team notices that each of the queries uses the same SQL endpoint, but the SQL endpoint is not
used by any other user.
Which of the following approaches can the data engineering team use to improve the latency of the data
analyst's queries?
- A. They can turn on the Serverless feature for the SQL endpoint
- B. They can increase the cluster size of the SQL endpoint
- C. They can turn on the Auto Stop feature for the SQL endpoint
- D. They can increase the maximum bound of the SQL endpoint's scaling range
- E. They can turn on the Serverless feature for the SQL endpoint and change the Spot In-stance Policy to
"Reliability Optimized"
Answer: B
NEW QUESTION # 50
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. C++
- B. pyspsark.ml.feature
- C. Scala Datasets
- D. Julia
- E. Regex
Answer: E
Explanation:
Explanation
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks. References:
https://docs.databricks.com/notebooks/notebooks-use.html#use-regular-expressions
https://docs.databricks.com/spark/latest/spark-sql/udf-scala.html#using-regular-expressions-in-udfs
https://docs.databricks.com/spark/latest/sparkr/functions/regexp_extract.html
https://docs.databricks.com/spark/latest/sparkr/functions/regexp_replace.html
NEW QUESTION # 51
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. to_interval("event_time", "5 minutes").alias("time")
- B. "event_time"
- C. window("event_time", "10 minutes").alias("time")
- D. window("event_time", "5 minutes").alias("time")
- E. lag("event_time", "10 minutes").alias("time")
Answer: D
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "WINDOW" section.
https://www.databricks.com/blog/2017/05/08/event-time-aggregation-watermarking-apache-sparks-structured-str
NEW QUESTION # 52
......
One of the key factors for passing the exam is practice. Candidates must use Databricks-Certified-Professional-Data-Engineer practice test material to be able to perform at their best on the real exam. This is why ExamsTorrent has developed three formats to assist candidates in their Databricks-Certified-Professional-Data-Engineer Preparation. These formats include desktop-based Databricks-Certified-Professional-Data-Engineer practice test software, web-based practice test, and a PDF format.
Reliable Test Databricks-Certified-Professional-Data-Engineer Test: https://www.examstorrent.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps-torrent.html
- Key Databricks-Certified-Professional-Data-Engineer Concepts 🧦 Databricks-Certified-Professional-Data-Engineer Instant Download 🧅 New Study Databricks-Certified-Professional-Data-Engineer Questions 🏀 Search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 on ➠ www.examcollectionpass.com 🠰 immediately to obtain a free download 🌈Test Databricks-Certified-Professional-Data-Engineer Tutorials
- HOT Passing Databricks-Certified-Professional-Data-Engineer Score: Databricks Certified Professional Data Engineer Exam - High Pass-Rate Databricks Reliable Test Databricks-Certified-Professional-Data-Engineer Test 🥣 Open ▛ www.pdfvce.com ▟ enter ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download 🏎Relevant Databricks-Certified-Professional-Data-Engineer Questions
- Correct Passing Databricks-Certified-Professional-Data-Engineer Score - Pass-Sure Databricks Certification Training - Verified Databricks Databricks Certified Professional Data Engineer Exam 🎋 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and obtain a free download on [ www.dumpsmaterials.com ] 🍱Databricks-Certified-Professional-Data-Engineer Sample Questions Answers
- Real Databricks Databricks-Certified-Professional-Data-Engineer Questions Formats - Prepare Better For Exam 🧄 Download [ Databricks-Certified-Professional-Data-Engineer ] for free by simply searching on ➡ www.pdfvce.com ️⬅️ 🤿Test Databricks-Certified-Professional-Data-Engineer Tutorials
- Real Databricks Databricks-Certified-Professional-Data-Engineer Questions Formats - Prepare Better For Exam 😇 Download 「 Databricks-Certified-Professional-Data-Engineer 」 for free by simply entering ☀ www.validtorrent.com ️☀️ website 🏹Databricks-Certified-Professional-Data-Engineer Sample Questions Answers
- Real Databricks Databricks-Certified-Professional-Data-Engineer Questions Formats - Prepare Better For Exam 🤺 Enter 「 www.pdfvce.com 」 and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download for free 🖼New Databricks-Certified-Professional-Data-Engineer Cram Materials
- New Databricks-Certified-Professional-Data-Engineer Exam Sample 🥦 Databricks-Certified-Professional-Data-Engineer Dumps Discount 🍬 Databricks-Certified-Professional-Data-Engineer Test Testking 🐚 Go to website [ www.practicevce.com ] open and search for 《 Databricks-Certified-Professional-Data-Engineer 》 to download for free ☔Databricks-Certified-Professional-Data-Engineer Dumps Discount
- Databricks-Certified-Professional-Data-Engineer Latest Test Simulator 📅 Passing Databricks-Certified-Professional-Data-Engineer Score 🥵 Test Databricks-Certified-Professional-Data-Engineer Tutorials ➖ Simply search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ for free download on ⇛ www.pdfvce.com ⇚ 🎊Reliable Databricks-Certified-Professional-Data-Engineer Exam Practice
- New Databricks-Certified-Professional-Data-Engineer Exam Sample 🏛 New Study Databricks-Certified-Professional-Data-Engineer Questions 🦎 Databricks-Certified-Professional-Data-Engineer Latest Test Simulator 🕝 Open website { www.examdiscuss.com } and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free download 🧾Databricks-Certified-Professional-Data-Engineer Instant Download
- Key Databricks-Certified-Professional-Data-Engineer Concepts 🧑 Databricks-Certified-Professional-Data-Engineer Instant Download 🤑 Relevant Databricks-Certified-Professional-Data-Engineer Questions 📀 Search on ⇛ www.pdfvce.com ⇚ for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to obtain exam materials for free download 🐁Passing Databricks-Certified-Professional-Data-Engineer Score
- Pass Guaranteed Updated Databricks-Certified-Professional-Data-Engineer - Passing Databricks Certified Professional Data Engineer Exam Score 🍳 Search for ( Databricks-Certified-Professional-Data-Engineer ) and download it for free on ☀ www.troytecdumps.com ️☀️ website 🐡Valid Test Databricks-Certified-Professional-Data-Engineer Bootcamp
- customerscomm.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, gifyu.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes