DOWNLOAD the newest DumpsActual ARA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=17ma2YP8SUcAAKSY7PT_NmDa5LTyjmdkr
Our website offer you the latest ARA-C01 dumps torrent in pdf version and test engine version, which selected according to your study habit. You can print our ARA-C01 practice questions out and share the materials with your classmates and friends. The test engine version is a way of exam simulation that helps you get used to the atmosphere of ARA-C01 Real Exam and solve the problems with great confidence.
Snowflake ARA-C01 Certification Exam is composed of two parts, the first being a multiple-choice exam that tests fundamental knowledge of Snowflake architecture and features. The second part of the exam is a hands-on lab where candidates are given a set of requirements and need to implement a Snowflake solution to meet those requirements. The lab is designed to test the candidate's ability to apply their knowledge in real-world scenarios.
>> ARA-C01 Test Engine Version <<
To provide our users with the SnowPro Advanced Architect Certification (ARA-C01) latest questions based on the sections of the actual exam quesions, we regularly update our ARA-C01 study material. Also, DumpsActual provides free updates of Snowflake ARA-C01 Exam Questions for up to 365 days. For customers who don't crack the Snowflake ARA-C01 test after using our product, DumpsActual will provides them a refund guarantee according to terms and conditions.
In order to prepare for the SnowPro Advanced Architect Certification exam, candidates can take advantage of various resources provided by Snowflake, such as training courses, study guides, and practice exams. Additionally, candidates can also benefit from hands-on experience working with Snowflake's cloud data platform, as well as collaborating with other Snowflake experts and architects.
NEW QUESTION # 176
A user who has SELECT privilege on a view does not also need SELECT privilege on the tables that the view uses
Answer: B
NEW QUESTION # 177
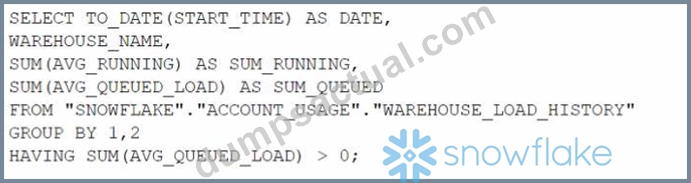
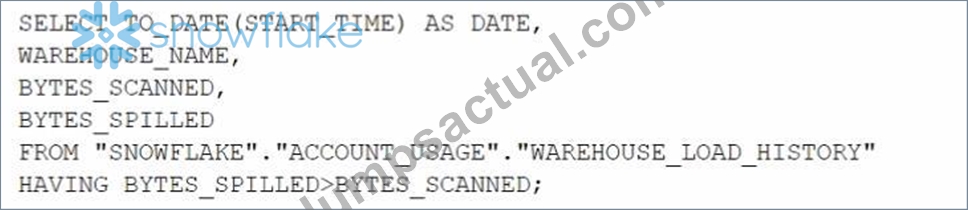
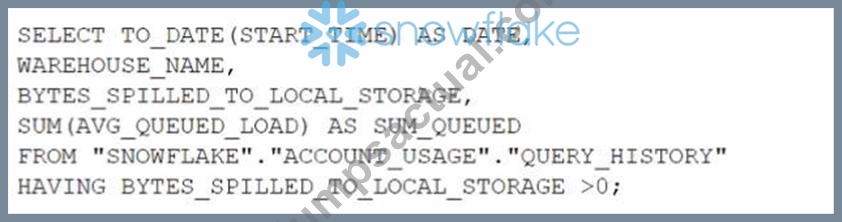
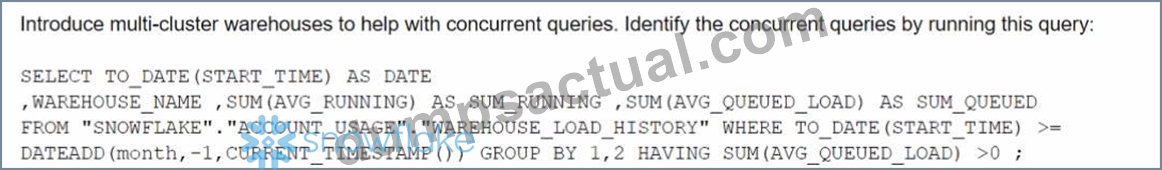
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
Answer: A
Explanation:
The correct answer is option B. This query is designed to assess the need for a multi-cluster warehouse by examining the queuing time (AVG_QUEUED_LOAD) on different days and virtual warehouses. When theAVG_QUEUED_LOADis greater than zero, it suggests that queries are waiting for resources, which can be an indicator that performance might be improved by using a multi-cluster warehouse to handle the workload more efficiently. By grouping by date and warehouse name and filtering on the sum of the average queued load being greater than zero, the query identifies specific days and warehouses where the workload exceeded the available compute resources. This information is valuable when considering scaling out warehouses to multi-cluster configurations for improved performance.
NEW QUESTION # 178
A large manufacturing company runs a dozen individual Snowflake accounts across its business divisions. The company wants to increase the level of data sharing to support supply chain optimizations and increase its purchasing leverage with multiple vendors.
The company's Snowflake Architects need to design a solution that would allow the business divisions to decide what to share, while minimizing the level of effort spent on configuration and management. Most of the company divisions use Snowflake accounts in the same cloud deployments with a few exceptions for European-based divisions.
According to Snowflake recommended best practice, how should these requirements be met?
Answer: A
Explanation:
Explanation
According to Snowflake recommended best practice, the requirements of the large manufacturing company should be met by deploying a Private Data Exchange in combination with data shares for the European accounts. A Private Data Exchange is a feature of the Snowflake Data Cloud platform that enables secure and governed sharing of data between organizations. It allows Snowflake customers to create their own data hub and invite other parts of their organization or external partners to access and contribute data sets. A Private Data Exchange provides centralized management, granular access control, and data usage metrics for the data shared in the exchange1. A data share is a secure and direct way of sharing data between Snowflake accounts without having to copy or move the data. A data share allows the data provider to grant privileges on selected objects in their account to one or more data consumers in other accounts2. By using a Private Data Exchange in combination with data shares, the company can achieve the following benefits:
* The business divisions can decide what data to share and publish it to the Private Data Exchange, where it can be discovered and accessed by other members of the exchange. This reduces the effort and complexity of managing multiple data sharing relationships and configurations.
* The company can leverage the existing Snowflake accounts in the same cloud deployments to create the Private Data Exchange and invite the members to join. This minimizes the migration and setup costs and leverages the existing Snowflake features and security.
* The company can use data shares to share data with the European accounts that are in different regions or cloud platforms. This allows the company to comply with the regional and regulatory requirements for data sovereignty and privacy, while still enabling data collaboration across the organization.
* The company can use the Snowflake Data Cloud platform to perform data analysis and transformation on the shared data, as well as integrate with other data sources and applications. This enables the company to optimize its supply chain and increase its purchasing leverage with multiple vendors.
The other options are incorrect because they do not meet the requirements or follow the best practices. Option A is incorrect because migrating the European accounts to the global region may violate the data sovereignty and privacy regulations, and deploying a Data Exchange may not provide the level of control and management that the company needs. Option C is incorrect because deploying to the Snowflake Marketplace may expose the company's data to unwanted consumers, and using invoker_share() in secure views may not provide the desired level of security and governance. Option D is incorrect because using replication to allow European data shares in the Exchange may incur additional costs and complexity, and may not be necessary if data shares can be used instead. References: Private Data Exchange | Snowflake Documentation, Introduction to Secure Data Sharing | Snowflake Documentation
NEW QUESTION # 179
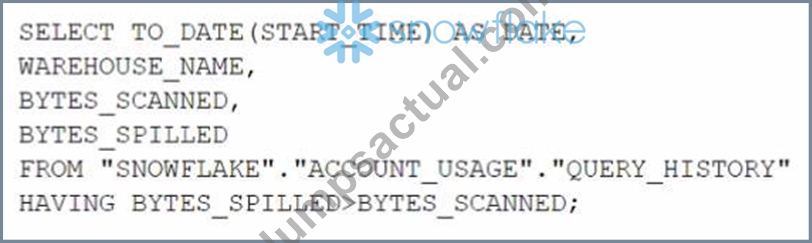
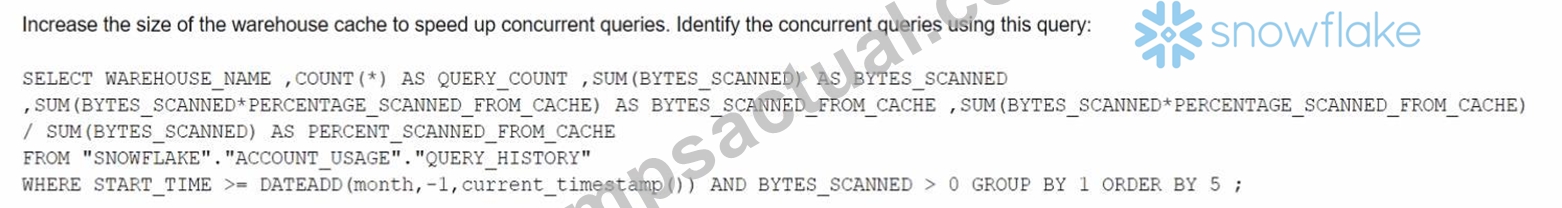
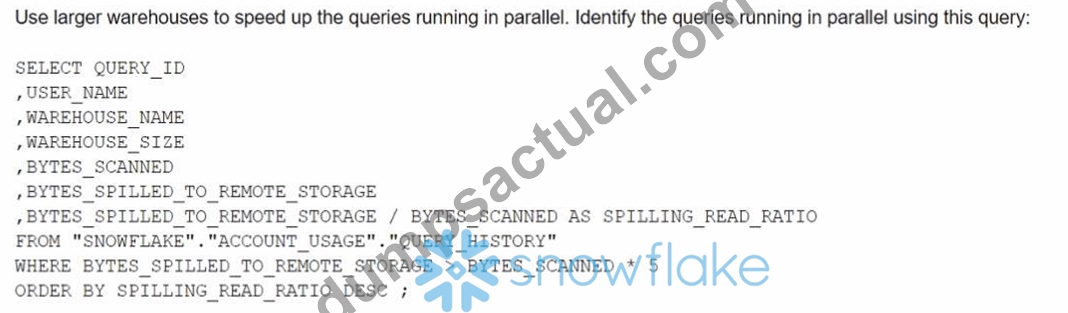
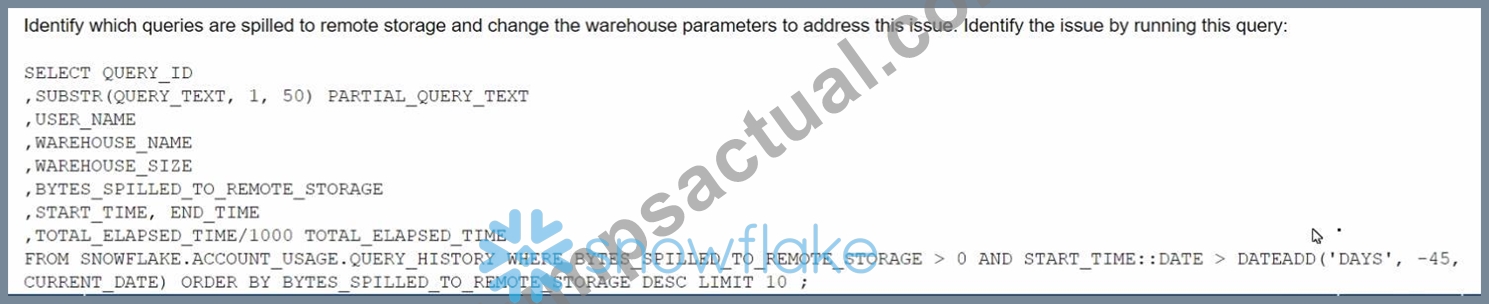
The Business Intelligence team reports that when some team members run queries for their dashboards in parallel with others, the query response time is getting significantly slower What can a Snowflake Architect do to identify what is occurring and troubleshoot this issue?
Answer: C
Explanation:
The image shows a SQL query that can be used to identify which queries are spilled to remote storage and suggests changing the warehouse parameters to address this issue. Spilling to remote storage occurs when the memory allocated to a warehouse is insufficient to process a query, and Snowflake uses disk or cloud storage as a temporary cache. This can significantly slow down the query performance and increase the cost. To troubleshoot this issue, a Snowflake Architect can run the query shown in the image to find out which queries are spilling, how much data they are spilling, and which warehouses they are using. Then, the architect can adjust the warehouse size, type, or scaling policy to provide enough memory for the queries and avoid spilling12. References:
Recognizing Disk Spilling
Managing the Kafka Connector
NEW QUESTION # 180
A table contains five columns and it has millions of records. The cardinality distribution of the columns is shown below: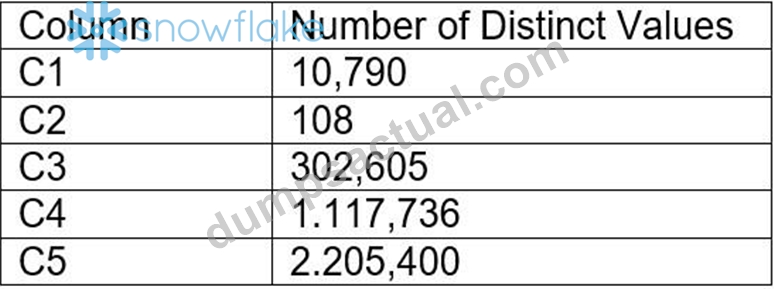
Column C4 and C5 are mostly used by SELECT queries in the GROUP BY and ORDER BY clauses. Whereas columns C1, C2 and C3 are heavily used in filter and join conditions of SELECT queries.
The Architect must design a clustering key for this table to improve the query performance.
Based on Snowflake recommendations, how should the clustering key columns be ordered while defining the multi-column clustering key?
Answer: B
Explanation:
According to the Snowflake documentation, the following are some considerations for choosing clustering for a table1:
Clustering is optimal when either:
You require the fastest possible response times, regardless of cost.
Your improved query performance offsets the credits required to cluster and maintain the table.
Clustering is most effective when the clustering key is used in the following types of query predicates:
Filter predicates (e.g. WHERE clauses)
Join predicates (e.g. ON clauses)
Grouping predicates (e.g. GROUP BY clauses)
Sorting predicates (e.g. ORDER BY clauses)
Clustering is less effective when the clustering key is not used in any of the above query predicates, or when the clustering key is used in a predicate that requires a function or expression to be applied to the key (e.g. DATE_TRUNC, TO_CHAR, etc.).
For most tables, Snowflake recommends a maximum of 3 or 4 columns (or expressions) per key. Adding more than 3-4 columns tends to increase costs more than benefits.
Based on these considerations, the best option for the clustering key columns is C. C1, C3, C2, because:
These columns are heavily used in filter and join conditions of SELECT queries, which are the most effective types of predicates for clustering.
These columns have high cardinality, which means they have many distinct values and can help reduce the clustering skew and improve the compression ratio.
These columns are likely to be correlated with each other, which means they can help co-locate similar rows in the same micro-partitions and improve the scan efficiency.
These columns do not require any functions or expressions to be applied to them, which means they can be directly used in the predicates without affecting the clustering.
NEW QUESTION # 181
......
ARA-C01 Guaranteed Questions Answers: https://www.dumpsactual.com/ARA-C01-actualtests-dumps.html
BONUS!!! Download part of DumpsActual ARA-C01 dumps for free: https://drive.google.com/open?id=17ma2YP8SUcAAKSY7PT_NmDa5LTyjmdkr