Die Anthropic CCAR-P Prüfungsfragen von ZertFragen sind in Übereinstimmung mit dem neuesten Lehrplan und der echten Anthropic CCAR-P Zertifizierungsprüfung. Wir aktualisieren auch ständig unsere Schulungsunterlagen. Alle Produkte erhalten Sie mit einjährigen kostenlosen Updates. Sie können auch das Abozeit verlängern, so dass Sie mehr Zeit bekommen, um sich besser auf die Prüfung vorzubereiten. Wenn Sie zögert sind oder nicht dafür entscheiden können, ob Sie die Anthropic CCAR-P Schulungsunterlagen von ZertFragen kaufen oder nicht. Dann können Sie die Demo umsonst auf der ZertFragen website herunterladen. Wenn es Ihnen passt, dann gehen Sie zum Kaufen ohne Bereuung.
| Section | Weight | Objectives |
|---|---|---|
| Solution Design & Architecture | 17% | - Architectural patterns
- Translating business problems into Claude-based AI solutions - Alignment with business value, cost, performance, and SLAs - End-to-end architecture design - Decomposition techniques for complex problem solving |
| Developer Productivity & Operational Enablement | 7% | - Developer enablement - Debugging and operational issue resolution - AI-assisted developer workflows - Claude tooling configuration for teams |
| Claude Models, Prompting & Context Engineering | 13% | - System prompts and prompt templates - Context window optimization - Guardrails - Claude model selection and trade-offs - Prompt reuse and context engineering strategies |
| Stakeholder Communication & Lifecycle Management | 14% | - Architecture documentation - Discovery and requirements gathering - Service-level agreements - Solution lifecycle management - Communicating architectural decisions - Stakeholder management |
| Governance, Safety & Risk Management | 14% | - AI safety and guardrails - Ethical AI considerations - Human-in-the-loop validation - Security and risk management - Regulatory and compliance requirements |
| Integration | 19% | - Claude integration mechanisms
- RAG pipeline design
|
| Evaluation, Testing & Optimization | 16% | - System issue diagnosis - Cost and performance optimization - Production monitoring and optimization - Evaluation metrics and datasets - Evaluation framework design - A/B testing |
Nachdem Sie die Demo unserer Anthropic CCAR-P probiert haben, werden Sie sicherlich getrost sein. Sie brauchen nicht mehr Sorge darum machen, wie die Prüfungsunterlagen der Anthropic CCAR-P nachzusuchen. Außerdem brauchen Sie nicht bei der Vorbereitung darum sorgen, dass die Unterlagen veraltet sind, weil wir Ihnen einjährigen Aktualisierungsdienst gratis anbieten. Sofort nach der Aktualisierung der Anthropic CCAR-P Prüfungssoftware geben wir Ihnen Bescheid. Deshalb können Sie immer die neuesten Prüfungsunterlagen benutzen. Sie dürfen sich ohne Sorge auf die Prüfung konzentriert vorbereiten.
95. Frage
A business sponsor has requested an AI solution to "improve customer experience." The sponsor cannot articulate which customer journey is failing, which metric reflects the failure, or which decisions the AI should support. The sponsor is asking you to begin design work next week.
Which delegation-competency action should you take first?
Antwort: C
Begründung:
The request is not yet design-ready because it lacks a defined failure, affected user journey, supported decision, target population, and measurable outcome. The architect should therefore facilitate structured discovery rather than prematurely selecting an AI pattern or model.
Discovery should identify where the current customer journey breaks down, who experiences the problem, what decision or task requires assistance, what data is available, and which metric would demonstrate improvement. The team can then establish baseline performance, target thresholds, operational constraints, risks, and explicit non-goals. Anthropic's evaluation guidance states that an LLM application should begin with clearly defined success criteria and a method for measuring them. Define Success Criteria and Build Evaluations Option A abandons the sponsor instead of helping translate a business concern into an actionable problem.
Option B risks producing a generic demonstration unrelated to a validated customer need. Option C substitutes the architect's assumptions for stakeholder evidence and may commit the organization to the wrong scope.
Competent delegation begins by defining the decision, intended outcome, authority boundaries, and target metric before determining which responsibilities should be assigned to Claude, conventional software, or human reviewers.
Study Guide references/topics: Structured discovery; delegation competency; problem definition; target metrics; decision support; measurable business outcomes.
96. Frage
You are classifying chunking strategies by the corpus type each is best suited to.
For each chunking strategy, select the appropriate corpus type: "Long Structured Documents,"
"Heterogeneous Short Records," or "Code or Hierarchical Specifications."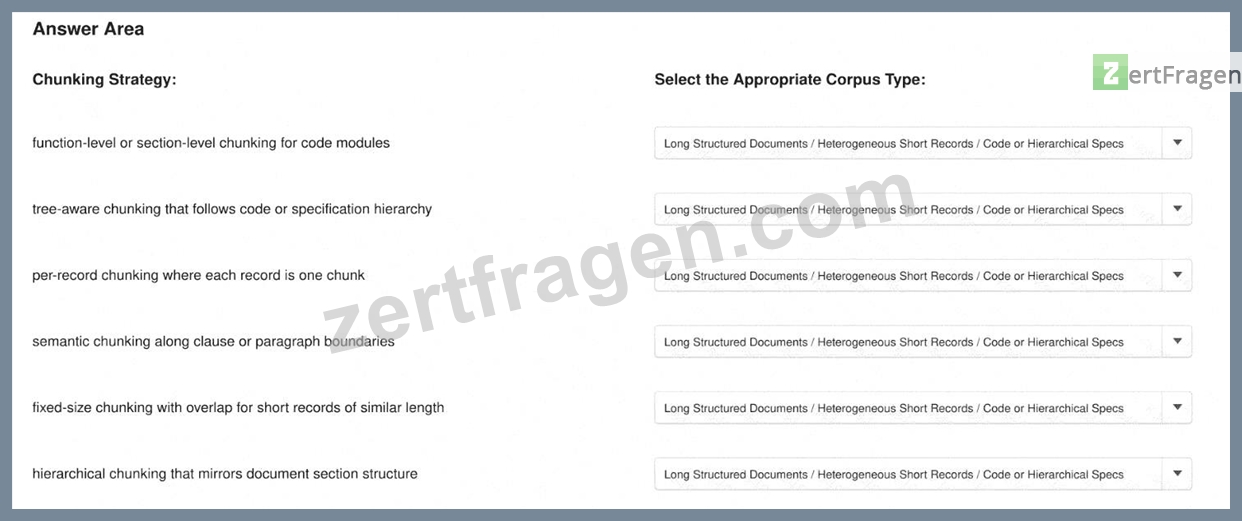
Antwort:
Begründung: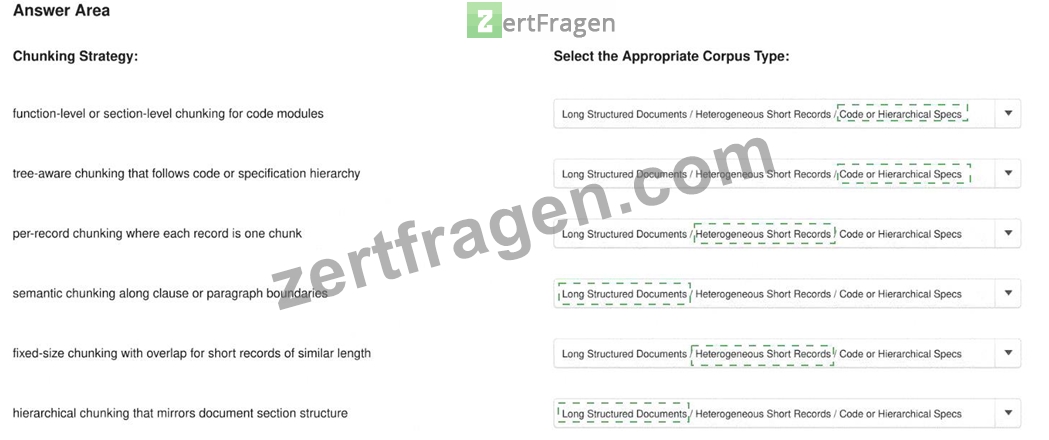
Explanation:
Function-level or section-level chunking for code modules - Code or Hierarchical Specifications Tree-aware chunking that follows code or specification hierarchy - Code or Hierarchical Specifications Per-record chunking where each record is one chunk - Heterogeneous Short Records Semantic chunking along clause or paragraph boundaries - Long Structured Documents Fixed-size chunking with overlap for short records of similar length - Heterogeneous Short Records Hierarchical chunking that mirrors document section structure - Long Structured Documents Chunking must preserve the structural unit that carries meaning in the source corpus. Code and hierarchical specifications are best divided at function, module, class, or tree boundaries because arbitrary token cuts can separate definitions from their implementation or parent context. Heterogeneous short-record collections should generally preserve each record as an independent chunk. Fixed-size overlapping chunks are also effective when records have broadly similar lengths and lack meaningful internal hierarchy. Long structured documents benefit from semantic boundaries such as clauses and paragraphs, while hierarchical chunking preserves relationships among sections, subsections, and parent headings. Anthropic notes that chunk size, boundaries, and overlap materially affect retrieval performance; therefore, one universal chunking method is inappropriate. Anthropic Contextual Retrieval
97. Frage
You are auditing a procurement-assistant agent whose defined responsibility is to draft purchase requests for review.
For each tool currently configured on the agent, select yes if the tool should remain after a least-privilege audit. Otherwise, select no if it should be removed.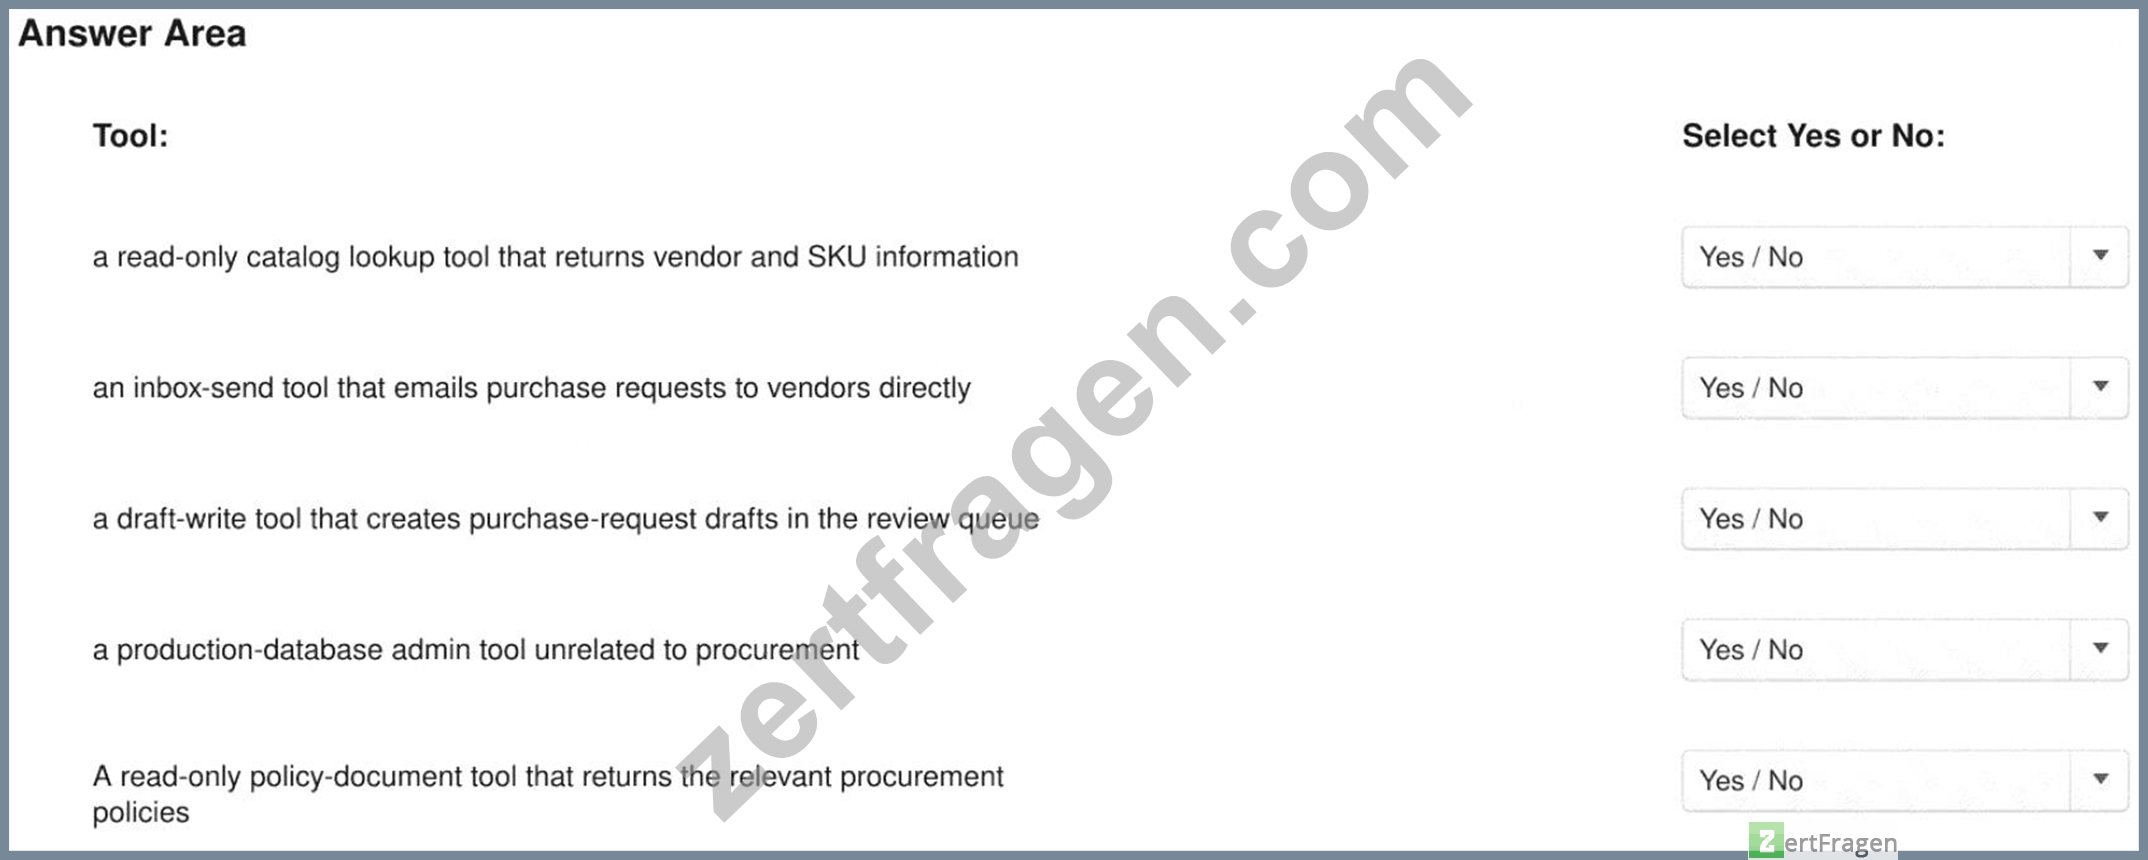
Antwort:
Begründung: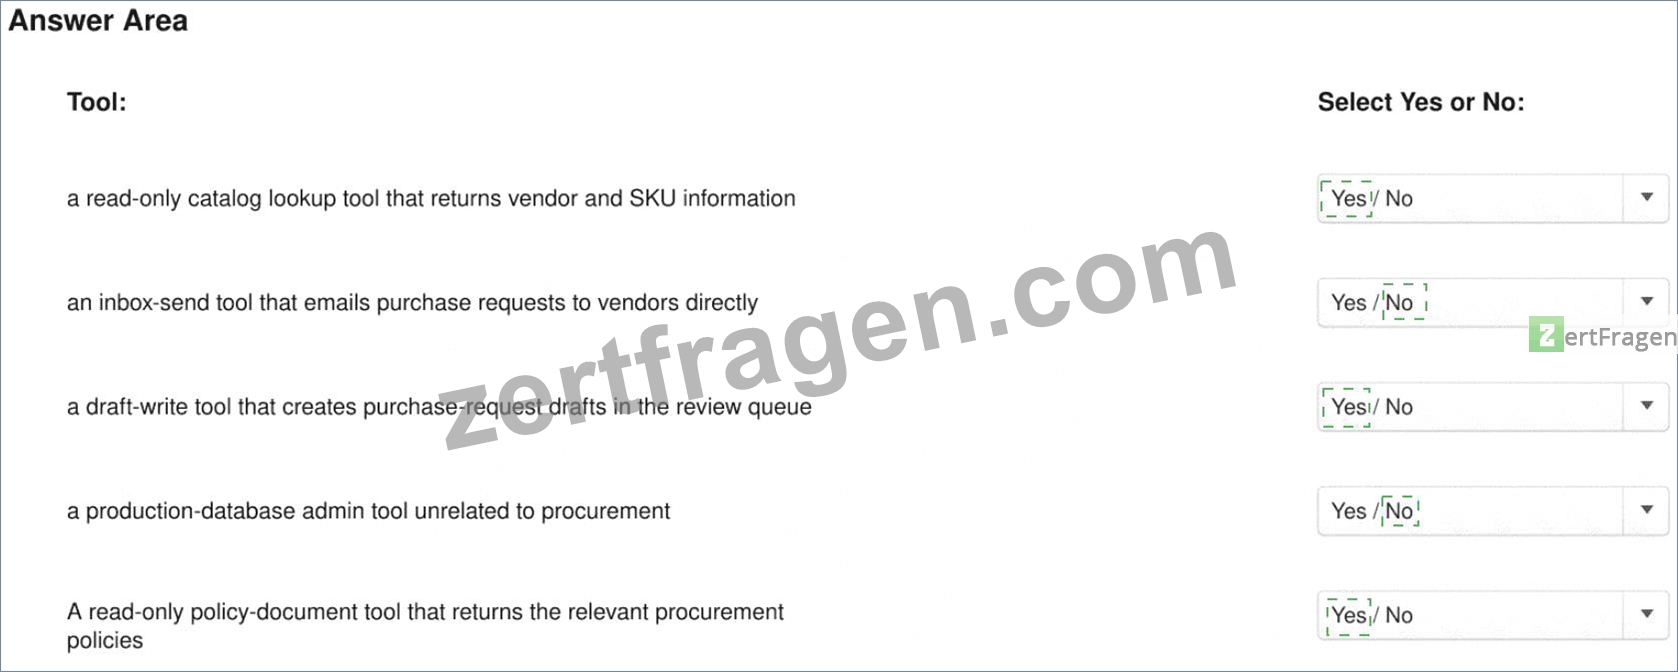
Explanation:
Yes, No, Yes, No, Yes
Least privilege requires each retained tool to be necessary for the agent's assigned responsibility and restricted to the minimum action level needed. Catalog lookup is appropriate because vendor and SKU information is needed to prepare an accurate request. The policy-document tool is similarly justified because the agent must ground the draft in applicable procurement rules. The draft-write tool is also aligned because it writes only to a review queue, preserving the required human approval boundary.
The inbox-send tool exceeds the stated responsibility. Sending a request directly to a vendor converts a drafting assistant into an externally acting purchasing agent and bypasses the review stage. The production- database administrator tool is unrelated to procurement and introduces unnecessary destructive capability, privilege-escalation exposure, and potential data-access risk.
Anthropic's prompt-injection guidance recommends limiting access to sensitive data and actions and applying least privilege so that a compromised agent can cause minimal damage. Claude Code also supports tool- specific allow, ask, and deny rules that are enforced outside the model. Prompt-Injection Mitigation, Claude Code Permissions Study Guide references/topics: Capability-bloat auditing; least privilege; tool scoping; human review gates; separation of drafting and execution authority.
98. Frage
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."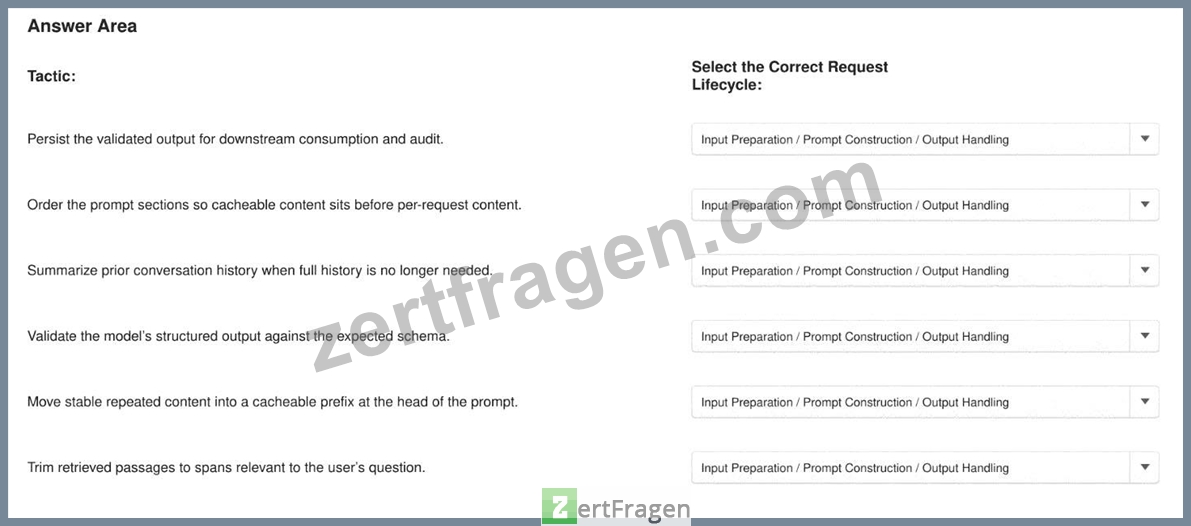
Antwort:
Begründung: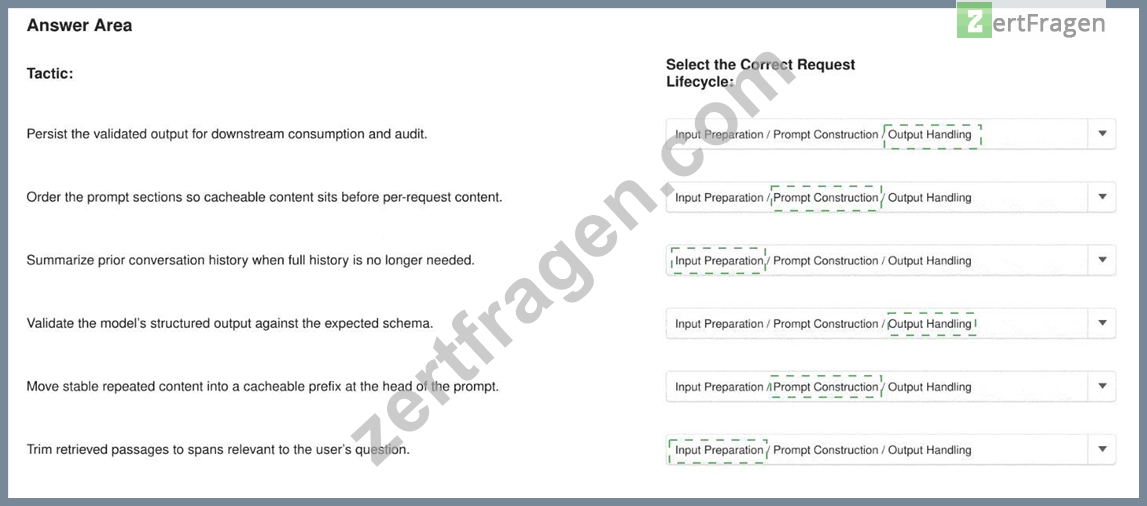
Explanation:
* Persist the validated output for downstream consumption and audit - Output Handling
* Order prompt sections so cacheable content appears before per-request content - Prompt Construction
* Summarize prior conversation history when full history is no longer needed - Input Preparation
* Validate the model's structured output against the expected schema - Output Handling
* Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction
* Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows; prompt caching
99. Frage
You are diagnosing a Claude Code session whose subagent uses 50,000 tokens of context before the engineer types a single message.
Which root cause is most likely?
Antwort: C
Begründung:
Claude Code constructs the model context before the first user message. That initial context can include the system prompt, project instructions, subagent configuration, MCP server instructions, and tool definitions expressed as JSON schemas. When numerous MCP servers expose many tools and Tool Search is disabled, those schemas must be loaded upfront. A large collection of verbose tool descriptions and parameter schemas can therefore consume tens of thousands of tokens before the engineer enters any text.
Tool Search is specifically designed to prevent this form of context inflation. With Tool Search enabled, Claude initially receives only server instructions and compact tool-identification information; full tool schemas are deferred until a relevant tool is discovered and required. Anthropic consequently describes Tool Search as the mechanism for keeping MCP context consumption low as integrations scale.
Keyboard layouts, font rendering, and display scaling operate outside the language-model context and cannot generate API input tokens. Likewise, model behavior does not silently reserve 50,000 tokens for personal preferences. The diagnostic action is to inspect configured MCP servers and tool counts, determine whether Tool Search has been disabled, and remove or defer unnecessary definitions.
Study Guide references/topics: [MCP Tool Search and context scaling](https://docs.anthropic.com/en/docs
/claude-code/mcp); MCP server configuration; subagent context budgeting; tool-schema optimization.
100. Frage
......
Wünschen Sie nicht großen Erfolg in Ihrem Arbeitsleben machen? Wenn ja, sollen Sie jetzt sich verbessern. Und wie kann Ihre selbe Fähigkeit in IT-Industrie sich verbessern? Es ist eine gute Weise, die Anthropic CCAR-P Zertifizierungsprüfung abzulegen. Die Anthropic Zeritizierungsprüfung ist eine sehr wichtige Zertifizierung, deshalb gibt es immer mehr Anthropic Prüfungskandidaten.
CCAR-P PDF: https://www.zertfragen.com/CCAR-P_prufung.html