PDFExamDumps Databricks-Certified-Data-Engineer-Professional最新考題 -立即獲取

P.S. PDFExamDumps在Google Drive上分享了免費的2026 Databricks Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=13SIw7NPYZz-IIIaWa0qbTw9i15koETRd
你已經報名參加了Databricks-Certified-Data-Engineer-Professional認證考試嗎?是不是面對一大堆的復習資料和習題感到頭痛呢?PDFExamDumps可以幫您解決這一問題,它絕對是你可以信賴的網站!只要你選擇使用PDFExamDumps網站提供的資料,絕對可以輕鬆通過考試,與其花費時間在不知道是否有用的復習資料上,不如趕緊來體驗PDFExamDumps帶給您的服務,還在等什麼趕緊行動吧。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Production Pipelines and Orchestration | - Databricks Workflows
- Job scheduling and monitoring
- Error handling and recovery strategies
|
| Topic 2: Data Modeling and Transformation | - Performance optimization techniques
- Dimensional modeling concepts
- Spark SQL transformations
|
| Topic 3: Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
| Topic 4: Data Ingestion and Processing | - ETL pipeline design patterns
- Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
|
| Topic 5: Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
|
>> Databricks-Certified-Data-Engineer-Professional最新考題 <<
Databricks-Certified-Data-Engineer-Professional證照資訊 & Databricks-Certified-Data-Engineer-Professional權威考題
PDFExamDumps的專家團隊為了滿足以大部分IT人士的需求,他們利用自己的經驗和知識努力地研究過去的幾年的Databricks Databricks-Certified-Data-Engineer-Professional 認證考試題目,如此,PDFExamDumps的最新的Databricks Databricks-Certified-Data-Engineer-Professional 的模擬測試題和答案就問世了。 我們的Databricks Databricks-Certified-Data-Engineer-Professional 模擬測試題及答案和真實考試的題目及答案有95%的相似性,通過PDFExamDumps提供的測試題你可以100%通過考試。如果你沒有通過考試,PDFExamDumps會全額退款給你。你也可以先在網上免費下載PDFExamDumps提供的部分關於Databricks Databricks-Certified-Data-Engineer-Professional 認證考試的練習題和答案作為嘗試,在你瞭解了我們的可靠性後,快將我們PDFExamDumps提供的產品加入您的購物車吧。PDFExamDumps將成就你的夢想。
最新的 Databricks Certification Databricks-Certified-Data-Engineer-Professional 免費考試真題 (Q212-Q217):
問題 #212
Which statement describes the default execution mode for Databricks Auto Loader?
- A. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- B. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
- D. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- E. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
答案:A
解題說明:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
問題 #213
The data governance team has instituted a requirement that the "user" table containing Personal Identifiable Information (PII) must have the appropriate masking on the SSN column. This means that anyone outside of the HRAdminGroup should see masked social security numbers as ***-**-
****.
The team created a masking function:

What does the data governance team need to do next to achieve this goal?
- A. CREATE TABLE users
(name STRING);
ALTER TABLE users CREATE COLUMN ssn CREATE MASK ssn_mask; - B. CREATE TABLE users
(name STRING, ssn STRING);
ALTER TABLE users ALTER COLUMN ssn SET MASK ssn_mask; - C. CREATE TABLE users
(name STRING, int STRING);
ALTER TABLE users ALTER COLUMN ssn CREATE MASK if is_member('HRAdminGroup'); - D. CREATE TABLE users
(name STRING, ssn INT MASKED ssn_mask);
答案:B
解題說明:
In Databricks, after creating a masking function, you apply it to a column using ALTER TABLE
<table> ALTER COLUMN <column> SET MASK <mask_function>. The table must already include the column (here, ssn as STRING). This ensures that only users in the HRAdminGroup see the unmasked SSN, while all others see the masked value.
問題 #214
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- B. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- C. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- D. Stop the existing pipeline; use the returned settings in a reset command
答案:B
解題說明:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
問題 #215
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- B. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
- C. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
- D. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- E. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
答案:B
解題說明:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees.
Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs.
問題 #216
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
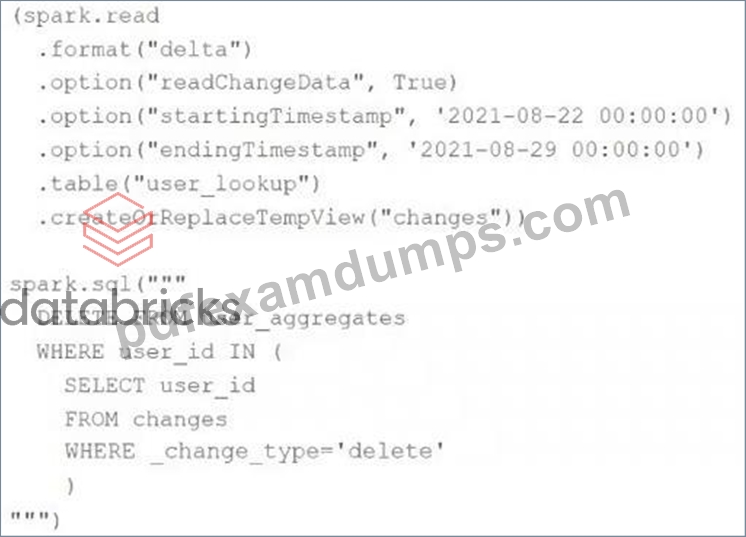
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- B. No; the change data feed only tracks inserts and updates not deleted records.
- C. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- D. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- E. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
答案:A
解題說明:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
問題 #217
......
PDFExamDumps有很好的的售後服務。如果你選擇購買PDFExamDumps的產品,PDFExamDumps將為你提供每天24小時的線上客戶服務和提供一年的免費更新服務,及時的通知顧客最新的考試資訊讓客戶有充分準備。我們可以讓你花費少量的時間和金錢就可以通過IT認證考試。選擇PDFExamDumps的產品幫助你的第一次參加的Databricks Databricks-Certified-Data-Engineer-Professional 認證考試是很划算的。
Databricks-Certified-Data-Engineer-Professional證照資訊: https://www.pdfexamdumps.com/Databricks-Certified-Data-Engineer-Professional_valid-braindumps.html
- 獲取更新Databricks-Certified-Data-Engineer-Professional最新考題 - 全部在www.newdumpspdf.com 😩 立即到⇛ www.newdumpspdf.com ⇚上搜索( Databricks-Certified-Data-Engineer-Professional )以獲取免費下載Databricks-Certified-Data-Engineer-Professional在線題庫
- 最新Databricks-Certified-Data-Engineer-Professional題庫 🧙 Databricks-Certified-Data-Engineer-Professional考古題介紹 🚏 Databricks-Certified-Data-Engineer-Professional考題資訊 💟 在《 www.newdumpspdf.com 》搜索最新的➤ Databricks-Certified-Data-Engineer-Professional ⮘題庫Databricks-Certified-Data-Engineer-Professional認證考試解析
- Databricks-Certified-Data-Engineer-Professional真題材料 🍖 Databricks-Certified-Data-Engineer-Professional認證考試解析 🎽 Databricks-Certified-Data-Engineer-Professional認證考試解析 🚴 打開網站⮆ tw.fast2test.com ⮄搜索“ Databricks-Certified-Data-Engineer-Professional ”免費下載Databricks-Certified-Data-Engineer-Professional考古題更新
- 最新的Databricks Databricks-Certified-Data-Engineer-Professional考古題 ⏫ 立即在⏩ www.newdumpspdf.com ⏪上搜尋➥ Databricks-Certified-Data-Engineer-Professional 🡄並免費下載Databricks-Certified-Data-Engineer-Professional證照考試
- Databricks-Certified-Data-Engineer-Professional認證考試解析 😐 Databricks-Certified-Data-Engineer-Professional題庫下載 🕡 Databricks-Certified-Data-Engineer-Professional資料 🦹 到⮆ www.kaoguti.com ⮄搜索➥ Databricks-Certified-Data-Engineer-Professional 🡄輕鬆取得免費下載Databricks-Certified-Data-Engineer-Professional認證考試解析
- 使用完美的Databricks Databricks-Certified-Data-Engineer-Professional最新考題輕松地通過您的Databricks Databricks-Certified-Data-Engineer-Professional考試 👹 在➡ www.newdumpspdf.com ️⬅️網站上免費搜索「 Databricks-Certified-Data-Engineer-Professional 」題庫Databricks-Certified-Data-Engineer-Professional考古題介紹
- Databricks-Certified-Data-Engineer-Professional真題材料 🍻 最新Databricks-Certified-Data-Engineer-Professional題庫 🥨 Databricks-Certified-Data-Engineer-Professional考題資訊 🔔 在✔ www.vcesoft.com ️✔️網站上免費搜索➡ Databricks-Certified-Data-Engineer-Professional ️⬅️題庫Databricks-Certified-Data-Engineer-Professional考古題更新
- Databricks-Certified-Data-Engineer-Professional資料 🦏 Databricks-Certified-Data-Engineer-Professional熱門題庫 📭 Databricks-Certified-Data-Engineer-Professional題庫下載 🧙 ▷ www.newdumpspdf.com ◁是獲取▷ Databricks-Certified-Data-Engineer-Professional ◁免費下載的最佳網站Databricks-Certified-Data-Engineer-Professional考試題庫
- 有效的考試資料Databricks-Certified-Data-Engineer-Professional最新考題保證助您輕松通過Databricks Databricks-Certified-Data-Engineer-Professional考試無憂 🌮 ▶ www.vcesoft.com ◀最新《 Databricks-Certified-Data-Engineer-Professional 》問題集合Databricks-Certified-Data-Engineer-Professional學習筆記
- Databricks-Certified-Data-Engineer-Professional最新考古題 📻 Databricks-Certified-Data-Engineer-Professional真題材料 ✊ Databricks-Certified-Data-Engineer-Professional題庫下載 👵 到【 www.newdumpspdf.com 】搜索➥ Databricks-Certified-Data-Engineer-Professional 🡄輕鬆取得免費下載最新Databricks-Certified-Data-Engineer-Professional題庫
- Databricks-Certified-Data-Engineer-Professional考試題庫 ⌨ Databricks-Certified-Data-Engineer-Professional權威考題 🚂 Databricks-Certified-Data-Engineer-Professional認證考試 ⏩ ▷ www.newdumpspdf.com ◁是獲取☀ Databricks-Certified-Data-Engineer-Professional ️☀️免費下載的最佳網站Databricks-Certified-Data-Engineer-Professional考試題庫
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. PDFExamDumps在Google Drive上分享了免費的2026 Databricks Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=13SIw7NPYZz-IIIaWa0qbTw9i15koETRd