TorrentExam Microsoft DP-800 test answers are the most effective and we guarantee your success in the first attempt. If you do not pass Microsoft DP-800 exam, we will give you a FULL REFUND of your purchasing fee. Failure in exam will not affect your finance. On request we can provide you with another exam of your choice absolutely free of cost. Think you! What do you have to lose? Microsoft DP-800 Test Answers are the latest and 100% guarantee to pass your DP-800 exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Our DP-800 exam questions are authoritatively certified. Our goal is to help you successfully pass relevant exam in an efficient learning style. Due to the quality and reasonable prices of our DP-800 training materials, our competitiveness has always been a leader in the world. Our DP-800 Learning Materials have a higher pass rate than other DP-800 training materials, so we are confident to allow you to gain full results.
NEW QUESTION # 48
You have an Azure SQL database that supports a customer-facing API. The API calls a stored procedure named dbo.GetCustomerOrders thousands of times per hour.
After a deployment that updated indexes and statistics, users report that the API endpoint backed by dbo.GetCustomerOrders is slower. In Query Store, the same query now has two persisted execution plans. During the last hour, the newer plan had a significantly higher average duration and CPU time than the older plan.
You need to restore the previous performance quickly, without changing the API code.
Which Transact-SQL command should you run?
Answer: D
Explanation:
We have encountered plan regression. This often happens after maintenance (like updating statistics) because the query optimizer generates a new execution plan that it thinks is better based on the new data distribution, but it ends up being less efficient in practice.
Since you've already identified the Plan ID for the faster plan and the Query ID from Query Store, you can force the "good" plan immediately using:
EXEC sp_query_store_force_plan @query_id = [YourQueryID], @plan_id = [YourFastPlanID]; Use code with caution.
This tells Azure SQL to ignore the new, slower plan and stick to the one that worked, providing an almost instant fix for your API's performance without requiring a code deployment.
Reference:
https://daxsws.com/blog/real-world-dynamics-365-performance-tuning-scenarios-and-fixes
NEW QUESTION # 49
You have an Azure SQL database that contains the following tables and columns.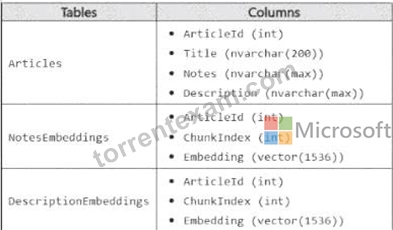
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.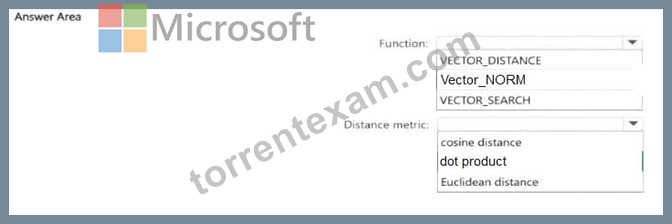
Answer:
Explanation: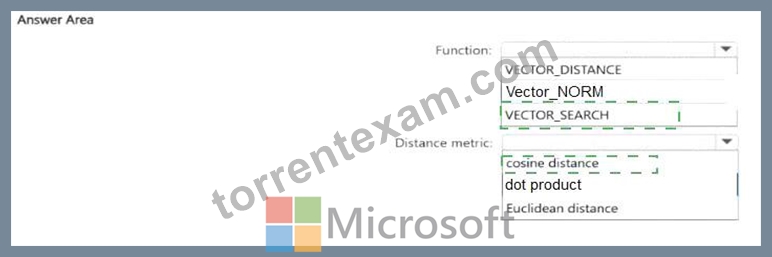
Explanation: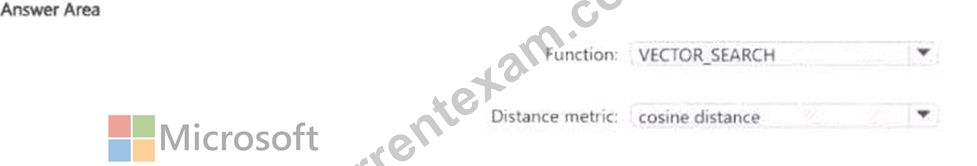
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 50
You have a SQL database in Microsoft Fabric that contains a table named WebSite. Logs. WebSite.Logs stores application telemetry data. Website.Logs contains a nvarehar(iMx) column named log that stores JSON documents You have a daily report that filters by the $.severity JSON property and returns Logld. LogDateTime, and log.
The report frequently causes full table scans.
You need to modify Website. Logs to support efficient filtering by $. severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.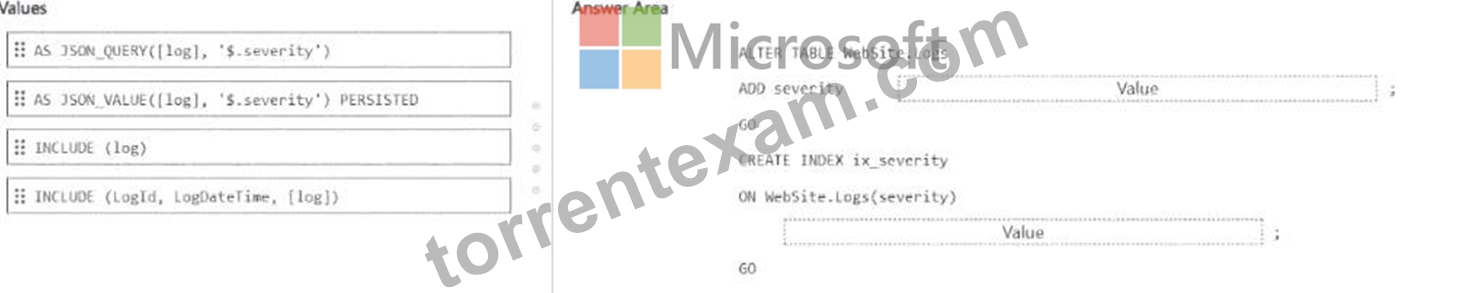
Answer:
Explanation: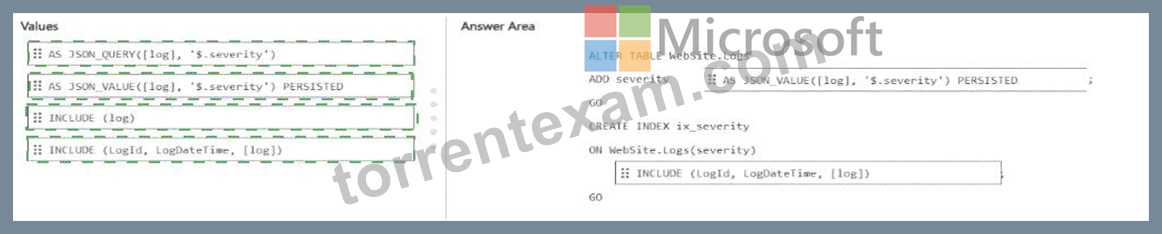
Explanation: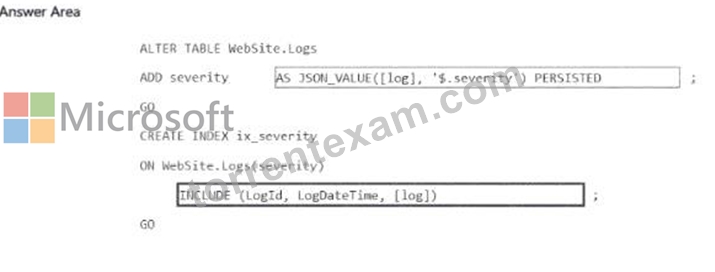
The correct way to avoid full table scans here is to add a computed column that extracts the JSON scalar property with JSON_VALUE , and then create a nonclustered index on that computed column with the report's returned columns in the INCLUDE list. Microsoft's JSON indexing guidance specifically recommends creating a computed column that exposes the JSON property you filter on, using the same expression as in the query, and then indexing that computed column.
So the computed column must be:
AS JSON_VALUE([log], ' $.severity ' ) PERSISTED
This is correct because $.severity is a scalar JSON value, so JSON_VALUE is the proper function.
JSON_QUERY would be for extracting an object or array, not a scalar property. Microsoft also notes that persisted computed columns can improve access speed for JSON-derived values.
The index should then include:
INCLUDE (LogId, LogDateTime, [log])
That is the right covering strategy because the report filters by severity but returns LogId, LogDateTime, and log. Microsoft's guidance on included columns explains that nonkey included columns let a nonclustered index cover more queries and reduce extra lookups to the base table.
So the completed code is:
ALTER TABLE WebSite.Logs
ADD severity AS JSON_VALUE([log], ' $.severity ' ) PERSISTED;
GO
CREATE INDEX ix_severity
ON WebSite.Logs(severity)
INCLUDE (LogId, LogDateTime, [log]);
GO
NEW QUESTION # 51
Your company has an ecommerce catalog in a Microsoft SQL Server 202b database named SalesDB SalesDB contains a table named products, products contains the following columns:
* product.id (int)
* product_name (nvarchar(200))
* description (nvarchar(max))
* category (nvarchar(50))
* brand (nvarchar(W))
* price (decimal)
* sku (nvarchar(40))
The description fields ate updated dairy by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price. You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC=' cosine ' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.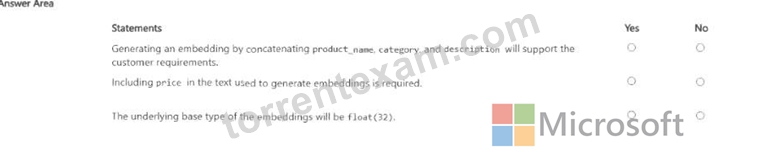
Answer:
Explanation: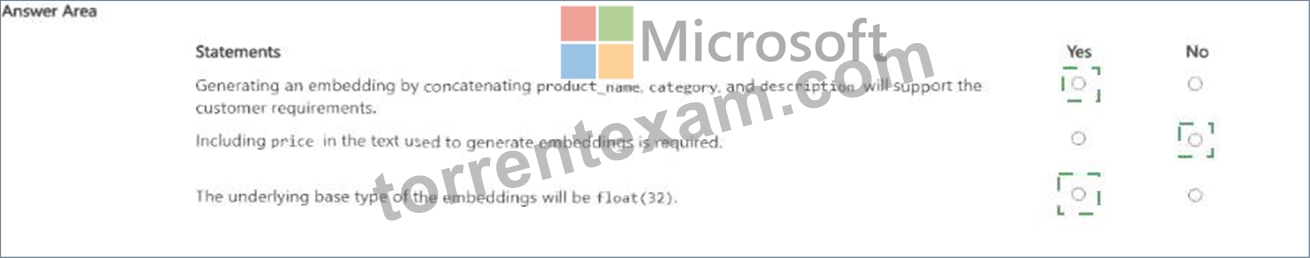
Explanation: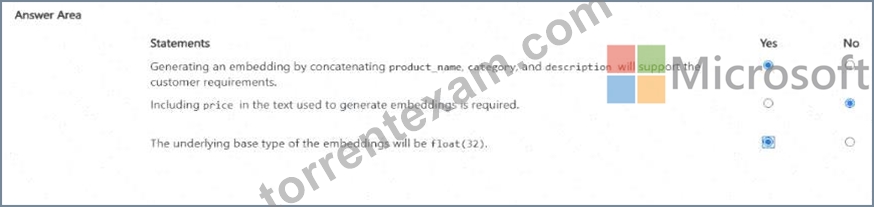
The first statement is Yes . Embeddings are used to represent the semantic meaning of content, and vector search is for conceptually similar matches over that content. Here, the semantically meaningful fields are product_name, category, and description. Using those together supports natural-language search, while brand and price can be handled as structured filters outside the embedding itself. This is an inference from Microsoft's guidance that vector search works over embeddings representing content meaning, while filters remain part of the nonvector query pipeline.
The second statement is No . price changes multiple times per day and is a structured numeric attribute, not stable semantic content. Since the requirement already says customers can apply structured filters for brand and price , price does not need to be embedded into the text. Embedding volatile numeric values would also make embeddings stale faster without improving the semantic-search objective. This is again an inference grounded in Microsoft's distinction between vector similarity over content and filtering/sorting over nonvector fields.
The third statement is Yes . In SQL Server's vector type, the default underlying base type is float32 unless float16 is specified explicitly.
NEW QUESTION # 52
You have an SDK-style SQL database project named MyDatabaseProject.sqlproj stored in a private GitHub repository. The repository contains the following GitHub Actions workflow:
YAML
name: Build and Deploy SQL Project
on:
push:
branches:
- main
workflow_dispatch:
jobs:
build-and-deploy:
runs-on: ubuntu-latest
permissions:
id-token: write
contents: read
steps:
- uses: actions/checkout@v4
- name: Build SQL project
run: dotnet build MyDatabaseProject.sqlproj
- name: Publish DACPAC
uses: azure/sql-action@v2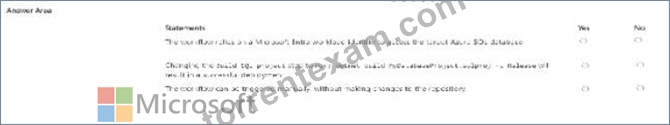
Answer:
Explanation: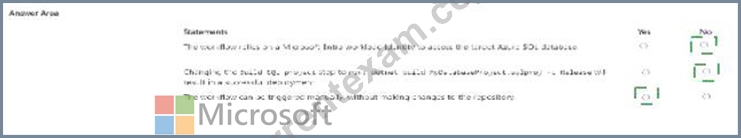
Explanation: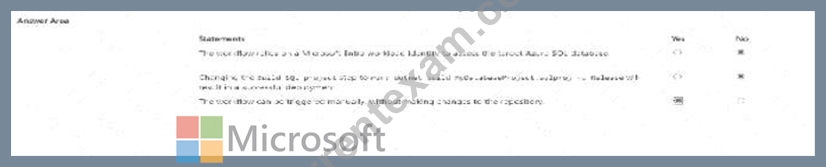
NEW QUESTION # 53
......
Thus, we come forward to assist them in cracking the Microsoft DP-800 examination. Don't postpone purchasing Microsoft DP-800 exam dumps to pass the crucial examination. TorrentExam study material is available in three versions: Microsoft DP-800 Pdf Dumps, desktop practice exam software, and a web-based Microsoft DP-800 practice test.
Latest DP-800 Study Materials: https://www.torrentexam.com/DP-800-exam-latest-torrent.html